mirror of
https://github.com/nerfstudio-project/nerfstudio.git
synced 2026-11-12 19:04:03 +08:00
Merge branch 'main' into AdamRashid96/main
This commit is contained in:
 Ethan Weber committed
commit
f115dc784e
67 files changed
+1474
-527
No files matched your search
+13
-9
@@ -1,11 +1,13 @@
|
||||
ARG CUDA_VERSION=11.8.0
|
||||
ARG OS_VERSION=22.04
|
||||
# Define base image.
|
||||
FROM nvidia/cuda:11.8.0-devel-ubuntu22.04
|
||||
FROM nvidia/cuda:${CUDA_VERSION}-devel-ubuntu${OS_VERSION}
|
||||
|
||||
# metainformation
|
||||
LABEL org.opencontainers.image.version = "0.1.18"
|
||||
LABEL org.opencontainers.image.source = "https://github.com/nerfstudio-project/nerfstudio"
|
||||
LABEL org.opencontainers.image.licenses = "Apache License 2.0"
|
||||
LABEL org.opencontainers.image.base.name="docker.io/library/nvidia/cuda:11.8.0-devel-ubuntu22.04"
|
||||
LABEL org.opencontainers.image.base.name="docker.io/library/nvidia/cuda:${CUDA_VERSION}-devel-ubuntu${OS_VERSION}"
|
||||
|
||||
# Variables used at build time.
|
||||
## CUDA architectures, required by Colmap and tiny-cuda-nn.
|
||||
@@ -115,32 +117,34 @@ SHELL ["/bin/bash", "-c"]
|
||||
# Upgrade pip and install packages.
|
||||
RUN python3.10 -m pip install --upgrade pip setuptools pathtools promise pybind11
|
||||
# Install pytorch and submodules
|
||||
RUN python3.10 -m pip install torch==2.0.1+cu118 torchvision==0.15.2+cu118 --extra-index-url https://download.pytorch.org/whl/cu118
|
||||
RUN CUDA_VER=${CUDA_VERSION%.*} && CUDA_VER=${CUDA_VER//./} && python3.10 -m pip install \
|
||||
torch==2.0.1+cu${CUDA_VER} \
|
||||
torchvision==0.15.2+cu${CUDA_VER} \
|
||||
--extra-index-url https://download.pytorch.org/whl/cu${CUDA_VER}
|
||||
# Install tynyCUDNN (we need to set the target architectures as environment variable first).
|
||||
ENV TCNN_CUDA_ARCHITECTURES=${CUDA_ARCHITECTURES}
|
||||
RUN python3.10 -m pip install git+https://github.com/NVlabs/tiny-cuda-nn.git@v1.6#subdirectory=bindings/torch
|
||||
|
||||
# Install pycolmap 0.3.0, required by hloc.
|
||||
# TODO(https://github.com/colmap/pycolmap/issues/111) use wheel when available for Python 3.10
|
||||
RUN git clone --branch v0.3.0 --recursive https://github.com/colmap/pycolmap.git && \
|
||||
# Install pycolmap, required by hloc.
|
||||
RUN git clone --branch v0.4.0 --recursive https://github.com/colmap/pycolmap.git && \
|
||||
cd pycolmap && \
|
||||
python3.10 -m pip install . && \
|
||||
cd ..
|
||||
|
||||
# Install hloc master (last release (1.3) is too old) as alternative feature detector and matcher option for nerfstudio.
|
||||
RUN git clone --branch master --recursive https://github.com/cvg/Hierarchical-Localization && \
|
||||
RUN git clone --branch master --recursive https://github.com/cvg/Hierarchical-Localization.git && \
|
||||
cd Hierarchical-Localization && \
|
||||
python3.10 -m pip install -e . && \
|
||||
cd ..
|
||||
|
||||
# Install pyceres from source
|
||||
RUN git clone --branch main --recursive https://github.com/cvg/pyceres.git && \
|
||||
RUN git clone --branch v1.0 --recursive https://github.com/cvg/pyceres.git && \
|
||||
cd pyceres && \
|
||||
python3.10 -m pip install -e . && \
|
||||
cd ..
|
||||
|
||||
# Install pixel perfect sfm.
|
||||
RUN git clone --branch main --recursive https://github.com/cvg/pixel-perfect-sfm && \
|
||||
RUN git clone --branch v1.0 --recursive https://github.com/cvg/pixel-perfect-sfm.git && \
|
||||
cd pixel-perfect-sfm && \
|
||||
python3.10 -m pip install -e . && \
|
||||
cd ..
|
||||
|
||||
@@ -6,7 +6,7 @@
|
||||
|
||||
## Overview
|
||||
|
||||
This Blender add-on allows for compositing with a Nerfstudio render as a background layer by generating a camera path JSON file from the Blender camera path, as well as a way to import Nerfstudio JSON files as a Blender camera baked with the Nerfstudio camera path. This add-on also allows compositing multiple NeRF objects into a NeRF scene. This is achieved by importing a mesh or point-cloud representation of the NeRF scene from Nerfstudio into Blender and getting the camera coordinates relative to the transformations of the NeRF representation. Dynamic FOV from the Blender camera is supported and will match the Nerfstudio render. Perspective and equirectangular cameras are supported.
|
||||
This Blender add-on allows for compositing with a Nerfstudio render as a background layer by generating a camera path JSON file from the Blender camera path, as well as a way to import Nerfstudio JSON files as a Blender camera baked with the Nerfstudio camera path. This add-on also allows compositing multiple NeRF objects into a NeRF scene. This is achieved by importing a mesh or point-cloud representation of the NeRF scene from Nerfstudio into Blender and getting the camera coordinates relative to the transformations of the NeRF representation. Dynamic FOV from the Blender camera is supported and will match the Nerfstudio render. Perspective, equirectangular, VR180, and omnidirectional stereo (VR 360) cameras are supported.
|
||||
|
||||
<center>
|
||||
<img width="800" alt="image" src="https://user-images.githubusercontent.com/9502341/211442247-99d1ebc7-3ef9-46f7-9bcc-0e18553f19b7.PNG">
|
||||
@@ -89,7 +89,7 @@ This Blender add-on allows for compositing with a Nerfstudio render as a backgro
|
||||
- The generated JSON camera path follows the user specified frame start, end, and step fields in the Output Properties in Blender. The JSON file specifies the user specified x and y render resolutions at the given % in the Output Properties.
|
||||
- The add-on computes the camera coordinates based on the active camera in the scene.
|
||||
- FOV animated changes of the camera will be matched with the NeRF render.
|
||||
- Perspective and equirectangular cameras are supported and can be selected within Blender.
|
||||
- Perspective, equirectangular, VR180, and omnidirectional stereo cameras are supported and can be configured within Blender.
|
||||
- The generated JSON file can be imported into Nerfstudio. Each keyframe of the camera transform in the frame sequence in Blender will be a keyframe in Nerfstudio. The exported JSON camera path is baked, where each frame in the sequence is a keyframe. This is to ensure that frame interpolation across Nerfstudio and Blender do not differ.
|
||||
<center>
|
||||
<img width="800" alt="image" src="https://user-images.githubusercontent.com/9502341/211245108-587a97f7-d48d-4515-b09a-5644fd966298.png">
|
||||
@@ -101,6 +101,13 @@ This Blender add-on allows for compositing with a Nerfstudio render as a backgro
|
||||
- It is recommended to export a high fidelity mesh as the NeRF representation from Nerfstudio. However if that is not possible or the scene is too large, a point cloud representation also works.
|
||||
- For compositing, it is recommended to convert the video render into image frames to ensure the Blender and NeRF renders are in sync.
|
||||
- Currently, dynamic camera focus is not supported.
|
||||
- Compositing with Blender Objects and VR180 or ODS Renders
|
||||
- Configure the Blender camera to be panoramic equirectangular and enable stereoscopy in the Output Properties. For the VR180 Blender camera, set the panoramic longitude min and max to -90 and 90.
|
||||
- Under the Stereoscopy panel the Blender camera settings, change the mode to "Parallel", set the Interocular Distance to 0.064 m, and checkmark "Spherical Stereo".
|
||||
|
||||
<center>
|
||||
<img width="300" alt="image" src="https://github-production-user-asset-6210df.s3.amazonaws.com/9502341/253217833-fd607601-2b81-48ab-ac5d-e55514a588da.png">
|
||||
</center>
|
||||
- Fisheye and orthographic cameras are not supported.
|
||||
- A walkthrough of this section is included in the tutorial video.
|
||||
|
||||
|
||||
@@ -114,6 +114,7 @@ This documentation is organized into 3 parts:
|
||||
- [Instruct-NeRF2NeRF](nerfology/methods/in2n.md): Editing 3D Scenes with Instructions
|
||||
- [K-Planes](nerfology/methods/kplanes.md): Unified 3D and 4D Radiance Fields
|
||||
- [LERF](nerfology/methods/lerf.md): Language Embedded Radiance Fields
|
||||
- [Nerfbusters](nerfology/methods/nerfbusters.md): Removing Ghostly Artifacts from Casually Captured NeRFs
|
||||
- [NeRFPlayer](nerfology/methods/nerfplayer.md): 4D Radiance Fields by Streaming Feature Channels
|
||||
- [Tetra-NeRF](nerfology/methods/tetranerf.md): Representing Neural Radiance Fields Using Tetrahedra
|
||||
|
||||
|
||||
@@ -38,7 +38,7 @@ Specify which diffusion model to use with the diffusion_model flag:
|
||||
ns-train generfacto --pipeline.model.diffusion_model ["stablediffusion", "deepfloyd"]
|
||||
```
|
||||
|
||||
# Example Results
|
||||
## Example Results
|
||||
|
||||
The following videos are renders of NeRFs generated from Generfacto. Each model was trained 30k steps, which took around 1 hour with DeepFloyd
|
||||
and around 4 hours with Stable Diffusion.
|
||||
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 43 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 273 KiB |
@@ -33,6 +33,7 @@ The following methods are supported in nerfstudio:
|
||||
Mip-NeRF<mipnerf.md>
|
||||
NeRF<nerf.md>
|
||||
Nerfacto<nerfacto.md>
|
||||
Nerfbusters<nerfbusters.md>
|
||||
NeRFPlayer<nerfplayer.md>
|
||||
Tetra-NeRF<tetranerf.md>
|
||||
TensoRF<tensorf.md>
|
||||
|
||||
@@ -10,11 +10,12 @@ ns-train nerfacto --help
|
||||
|
||||
We provide a few additional variants:
|
||||
|
||||
| Method | Description | Memory | Speed |
|
||||
| ---------------- | --------------------- | ------ | ------ |
|
||||
| `nerfacto` | Default Model | ~6GB | Fast |
|
||||
| `nerfacto-big` | Larger higher quality | ~12GB | Slower |
|
||||
| `depth-nerfacto` | Supervise on depth | ~6GB | Fast |
|
||||
| Method | Description | Memory | Speed |
|
||||
| ---------------- | ------------------------------ | ------ | ------- |
|
||||
| `nerfacto` | Default Model | ~6GB | Fast |
|
||||
| `nerfacto-big` | Larger higher quality | ~12GB | Slower |
|
||||
| `nerfacto-huge` | Even larger and higher quality | ~24GB | Slowest |
|
||||
| `depth-nerfacto` | Supervise on depth | ~6GB | Fast |
|
||||
|
||||
## Method
|
||||
|
||||
|
||||
@@ -0,0 +1,66 @@
|
||||
# Nerfbusters
|
||||
|
||||
<h4>Removing Ghostly Artifacts from Casually Captured NeRFs 👻 </h4>
|
||||
|
||||
```{button-link} https://ethanweber.me/nerfbusters
|
||||
:color: primary
|
||||
:outline:
|
||||
Paper Website
|
||||
```
|
||||
|
||||
```{button-link} https://github.com/ethanweber/nerfbusters
|
||||
:color: primary
|
||||
:outline:
|
||||
Code and Data
|
||||
```
|
||||
|
||||
**TLDR: We present a method that uses a 3D diffusion prior to clean NeRFs and an evaluation procedure for in-the-wild NeRFs**
|
||||
|
||||
<video id="teaser" muted autoplay playsinline loop controls width="100%">
|
||||
<source id="mp4" src="https://ethanweber.me/nerfbusters/media/nerf-comparisons/car-sq.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
## Installation
|
||||
|
||||
First install nerfstudio dependencies. Then run:
|
||||
|
||||
```bash
|
||||
pip install git+https://github.com/ethanweber/nerfbusters
|
||||
nerfbusters-setup
|
||||
ns-train nerfbusters --help
|
||||
```
|
||||
|
||||
For more details, see the [installation instructions](https://github.com/ethanweber/nerfbusters).
|
||||
|
||||
### Running the Method
|
||||
|
||||
Please checkout the readme for the [Nerfbusters repository](https://github.com/ethanweber/nerfbusters)
|
||||
|
||||
## Abstract
|
||||
|
||||
Casually captured Neural Radiance Fields (NeRFs) suffer from artifacts such as floaters or flawed geometry when rendered outside the path of the training views. However, common practice is still to evaluate on every 8th frame, which does not measure rendering quality away from training views, hindering progress in volume rendering. We propose a new dataset and evaluation procedure, where two camera trajectories are recorded of the scene, one used for training, and the other for evaluation. We find that existing hand-crafted regularizers do not remove floaters nor improve scene geometry in this more challenging in-the-wild setting. To this end, we propose a learned, local 3D diffusion prior and a novel density score distillation sampling loss. We show that this learned prior removes floaters and improves scene geometry for casual captures.
|
||||
|
||||
## NeRF evaluation for casually captured videos
|
||||
|
||||
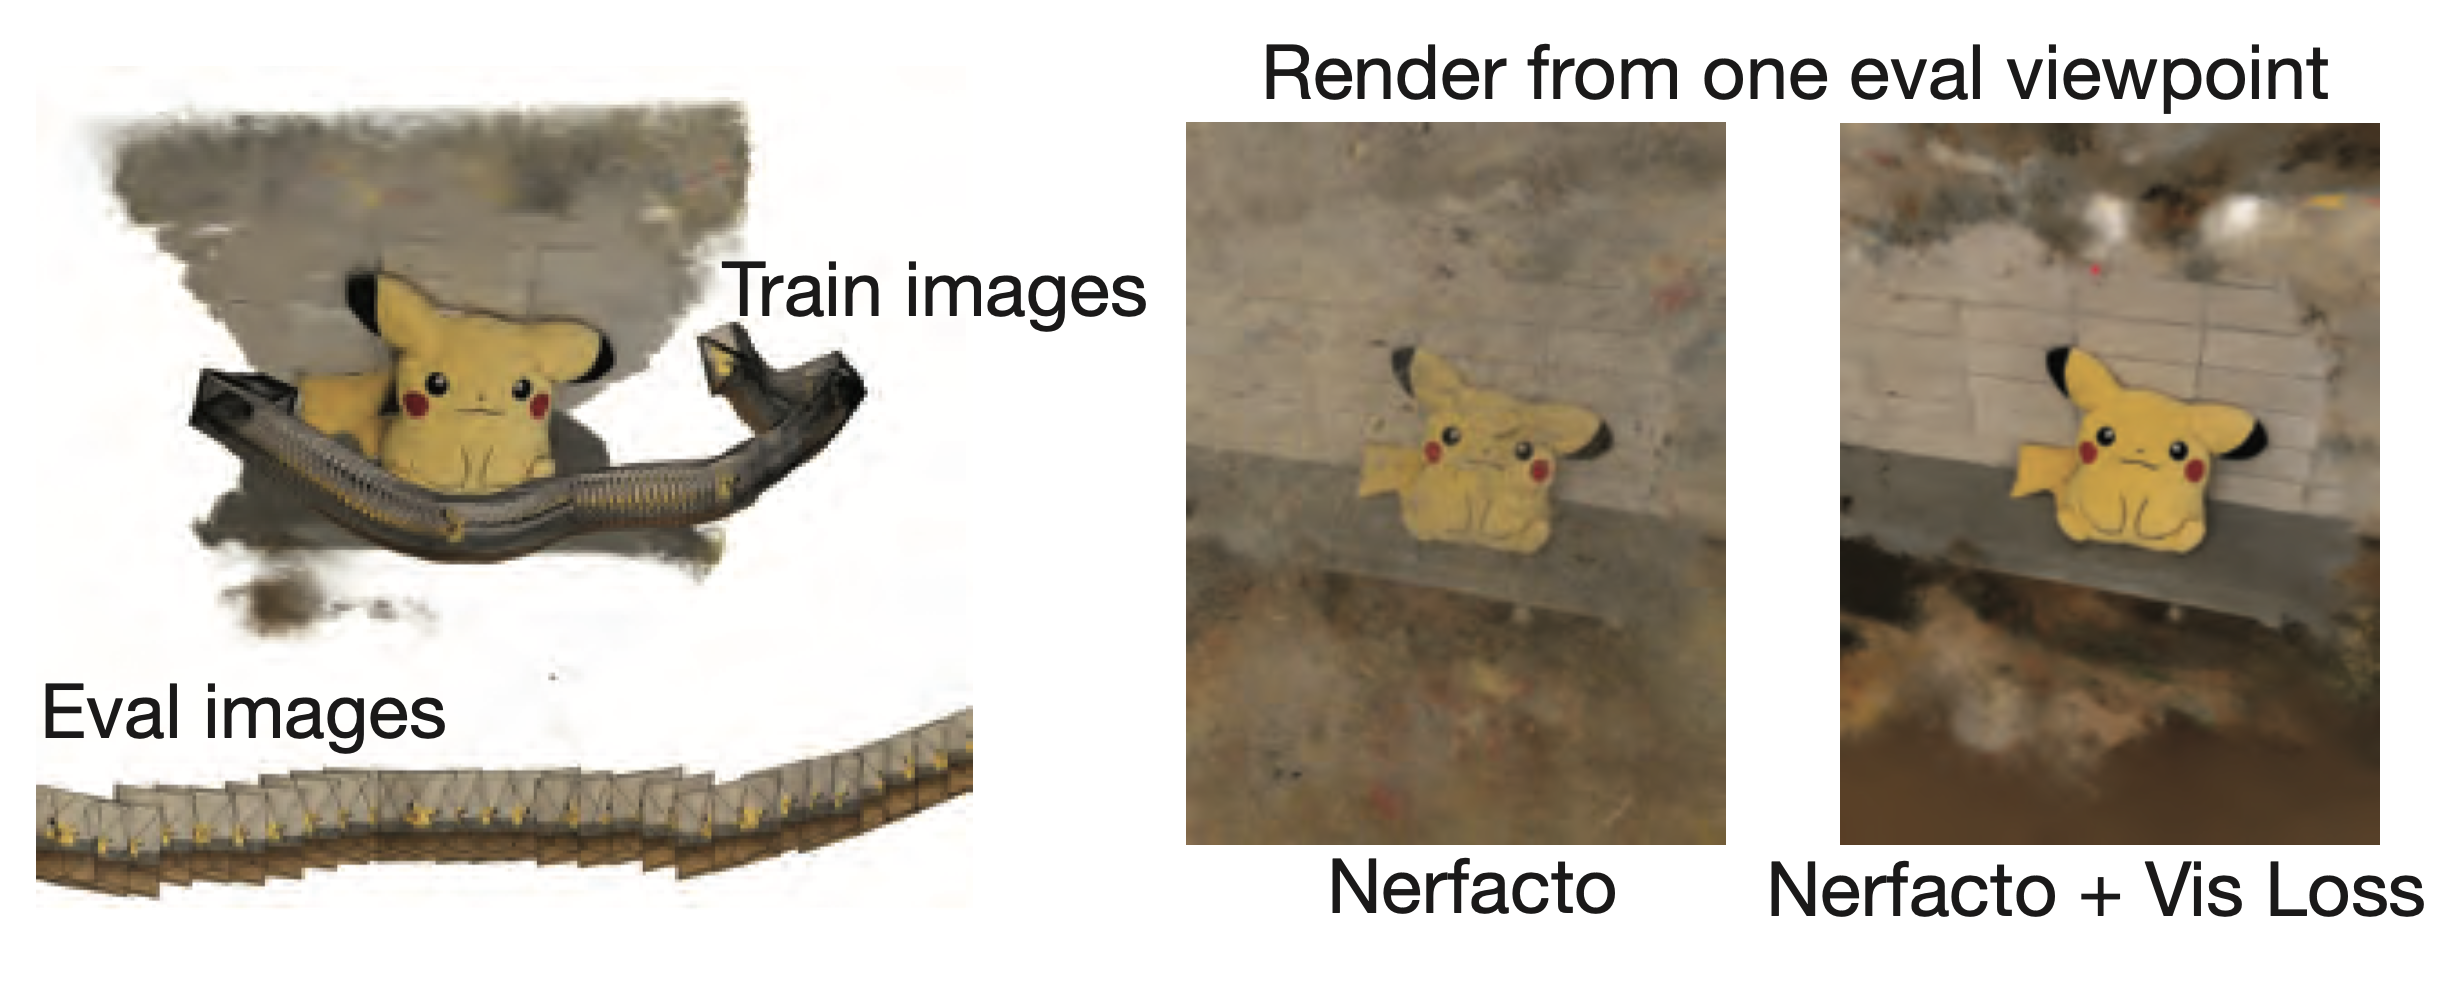
We train on a single camera trajectory and evaluate on a second camera trajectory. Both methods succeed on the training trajectory, but only our method succeeds on the evaluation trajectory.
|
||||
|
||||
<video id="teaser" muted autoplay playsinline loop no-controls width="100%">
|
||||
<source id="mp4" src="https://ethanweber.me/nerfbusters/media/teaser-animated.m4v" type="video/mp4">
|
||||
</video>
|
||||
|
||||
### Model Overview
|
||||
|
||||
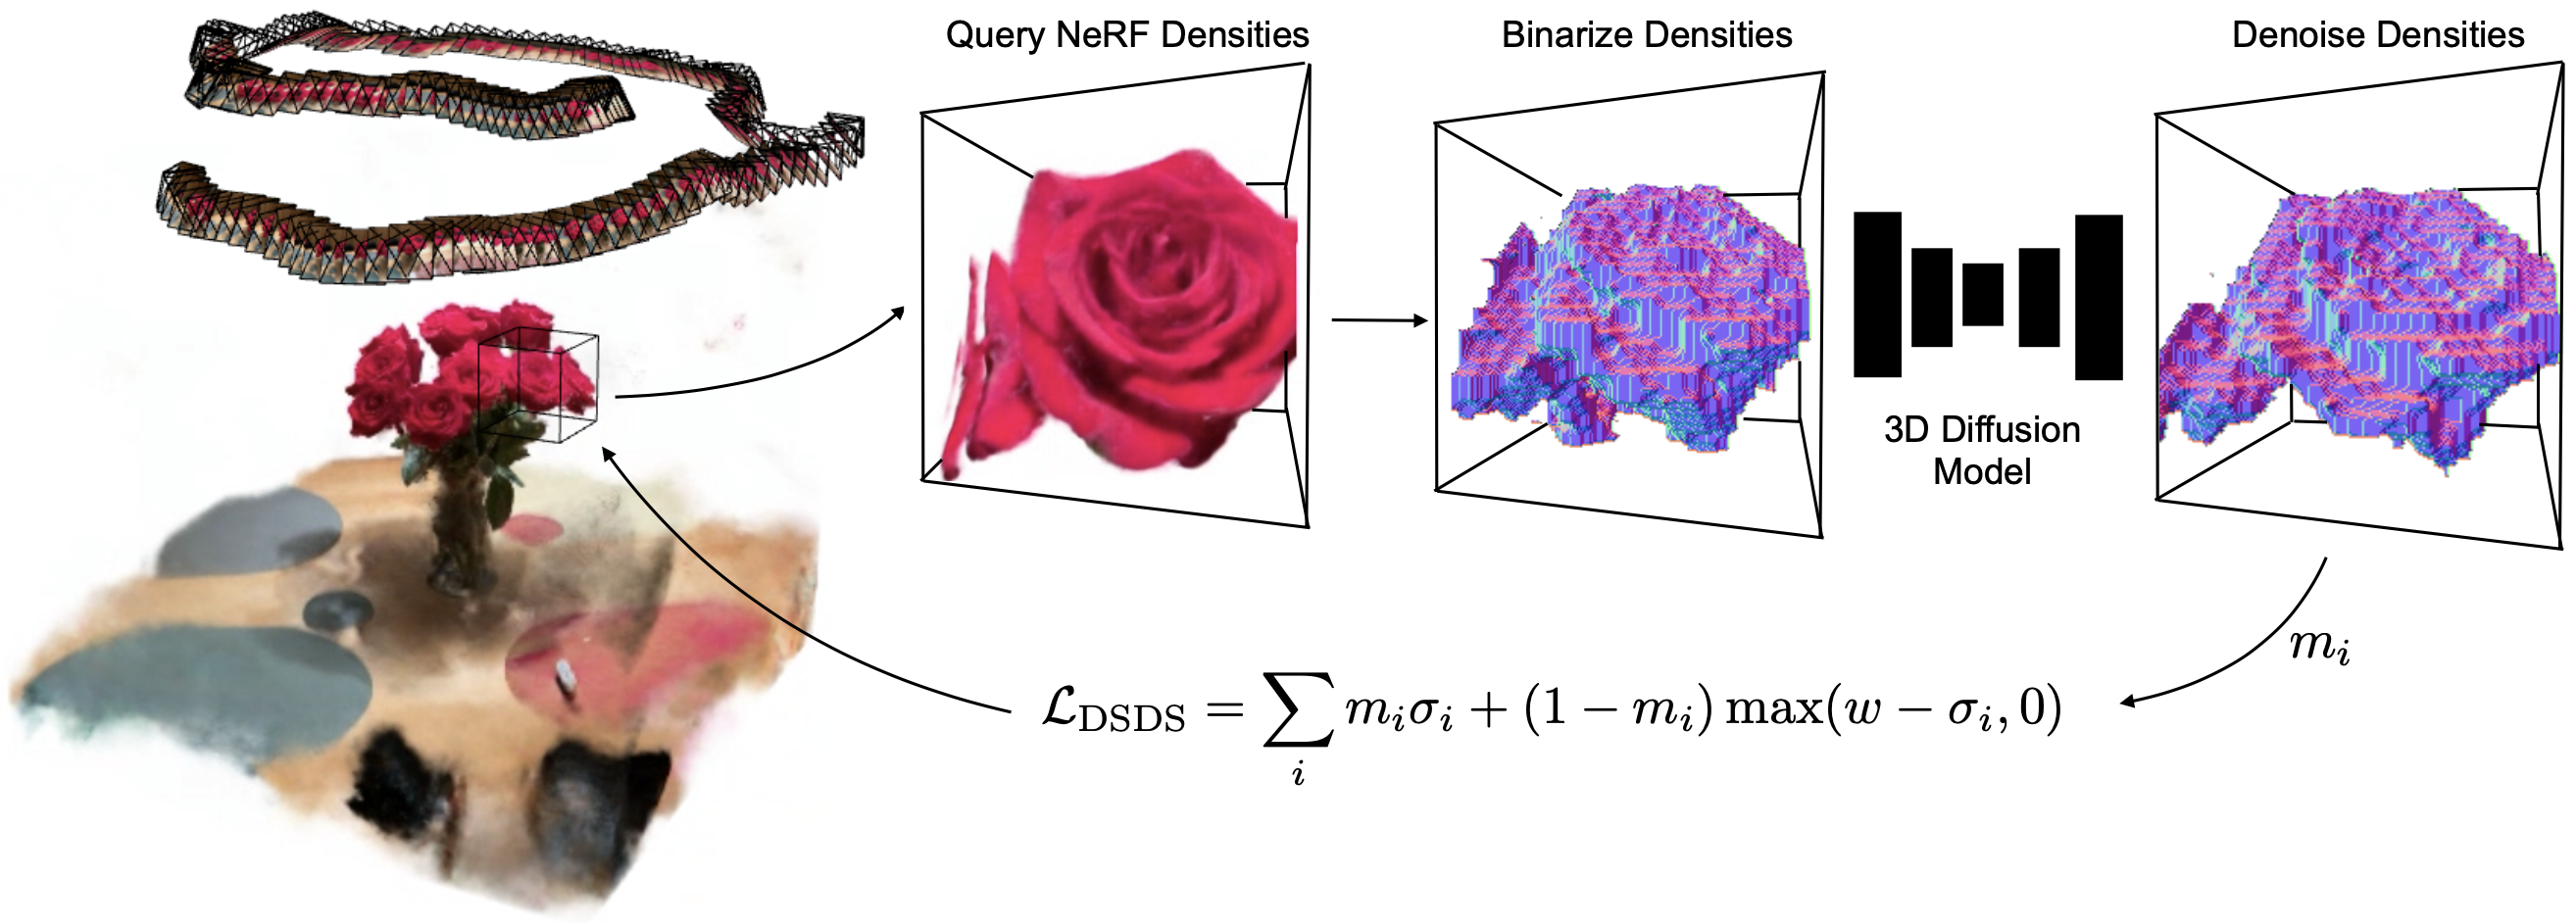
We learn a local 3D prior with a diffusion model that regularizes the 3D geometry of NeRFs. We use importance sampling to query a cube with NeRF densities. We binarize these densities and perform one single denoising step using a pre-trained 3D diffusion model. With these denoised densities, we compute a density score distillation sampling (DSDS) that penalizes NeRF densities where the diffusion model predicts empty voxels and pushes the NeRF densities above the target w where the diffusion model predicts occupied voxels.
|
||||
|
||||
|
||||
|
||||
|
||||
### Visibiltiy Loss
|
||||
|
||||
Our visibility loss enables stepping behind or outside the training camera frustums. We accomplish this by supervising densities to be low when not seen by at least one training view. Other solutions would be to store an occupancy grid or compute ray-frustum intersection tests during rendering. Our solution is easy to implement and applicable to any NeRF.
|
||||
|
||||
|
||||
|
||||
### Results and dataset preview
|
||||
|
||||
For results and a dataset preview, view the [project page](https://ethanweber.me/nerfbusters)!
|
||||
@@ -8,6 +8,10 @@
|
||||
Paper Website
|
||||
```
|
||||
|
||||
<video id="teaser" muted autoplay playsinline loop controls width="100%">
|
||||
<source id="mp4" src="https://apchenstu.github.io/TensoRF/video/train_process.mp4" type="video/mp4">
|
||||
</video>
|
||||
|
||||
### Running Model
|
||||
|
||||
```bash
|
||||
@@ -16,4 +20,14 @@ ns-train tensorf
|
||||
|
||||
## Overview
|
||||
|
||||
🚧 Guide under construction 🚧
|
||||
```{image} imgs/tensorf/models_tensorf_pipeline.png
|
||||
:align: center
|
||||
```
|
||||
|
||||
TensoRF models the radiance field of a scene as a 4D tensor, which represents a 3D voxel grid with per-voxel multi-channel features. TensoRF factorizes the 4D scene tensor into multiple compact low-rank tensor components using CP or VM modes. CP decomposition factorizes tensors into rank-one components with compact vectors. Vector-Matrix (VM) decomposition factorizes tensors into compact vector and matrix factors.
|
||||
|
||||
```{image} imgs/tensorf/models_tensorf_factorization.png
|
||||
:align: center
|
||||
```
|
||||
|
||||
TensoRF with CP(left) and VM(right) decompositions results in a significantly reduced memory footprint compared to previous and concurrent works that directly optimize per-voxel features, such as [Plenoxels](https://alexyu.net/plenoxels/) and [PlenOctrees](https://alexyu.net/plenoctrees/). In experiments, TensoRF with CP decomposition achieves fast reconstruction with improved rendering quality and a smaller model size compared to NeRF. Furthermore, TensoRF with VM decomposition enhances rendering quality even further, while reducing reconstruction time and maintaining a compact model size.
|
||||
@@ -106,8 +106,8 @@ cd vcpkg
|
||||
```bash
|
||||
git clone https://github.com/microsoft/vcpkg
|
||||
cd vcpkg
|
||||
./bootstrap-vcpkg.bat
|
||||
./vcpkg install colmap[cuda]:x64-windows
|
||||
.\bootstrap-vcpkg.bat
|
||||
.\vcpkg install colmap[cuda]:x64-windows
|
||||
```
|
||||
|
||||
:::
|
||||
@@ -116,8 +116,8 @@ cd vcpkg
|
||||
```bash
|
||||
git clone https://github.com/microsoft/vcpkg
|
||||
cd vcpkg
|
||||
./bootstrap-vcpkg.sh
|
||||
./vcpkg install colmap:x64-windows
|
||||
.\bootstrap-vcpkg.sh
|
||||
.\vcpkg install colmap:x64-windows
|
||||
```
|
||||
|
||||
:::
|
||||
@@ -347,48 +347,77 @@ The pixels representing the distorted hand and head are obviously not useful in
|
||||
|
||||
If cropping only needs to be done from the bottom, you can use the `--crop-bottom [num]` argument which would be the same as doing `--crop-factor 0.0 [num] 0.0 0.0`
|
||||
|
||||
## 🥽 Render Omni-directional Stereo (360 VR)
|
||||
## 🥽 Render VR Video
|
||||
|
||||
Stereo equirectangular rendering for VR video is supported as omni-directional stereo video and image rendering. This outputs two equirectangular renders vertically stacked, one for each eye. Omni-directional stereo (ODS) is a method to render VR 3D 360 videos, and may introduce slight depth distortions for close objects. For additional information on how ODS works, refer to this [writeup](https://developers.google.com/vr/jump/rendering-ods-content.pdf).
|
||||
Stereo equirectangular rendering for VR video is supported as VR180 and omni-directional stereo (360 VR) Nerfstudio camera types for video and image rendering.
|
||||
|
||||
### Omni-directional Stereo (360 VR)
|
||||
This outputs two equirectangular renders vertically stacked, one for each eye. Omni-directional stereo (ODS) is a method to render VR 3D 360 videos, and may introduce slight depth distortions for close objects. For additional information on how ODS works, refer to this [writeup](https://developers.google.com/vr/jump/rendering-ods-content.pdf).
|
||||
|
||||
<center>
|
||||
<img img width="300" src="https://github-production-user-asset-6210df.s3.amazonaws.com/9502341/240530353-5c05d12b-6e42-42bb-8ff5-f54aa30ca262.jpg">
|
||||
<img img width="300" src="https://github-production-user-asset-6210df.s3.amazonaws.com/9502341/255423390-ff0710f1-29ce-47b2-85f9-922084cab297.jpg">
|
||||
</center>
|
||||
|
||||
To render in ODS it is essential to adjust the NeRF to have an approximately true-to-life real world scale (adjustable in the camera path) to ensure that the scene depth and IPD (distance between the eyes) is appropriate for the render to be viewable in VR. You can adjust the scene scale with the [Blender Add-on](https://docs.nerf.studio/en/latest/extensions/blender_addon.html) by appropriately scaling a point cloud representation of the NeRF.
|
||||
|
||||
### VR180
|
||||
This outputs two 180 deg equirectangular renders horizontally stacked, one for each eye. VR180 is a video format for VR 3D 180 videos. Unlike in omnidirectional stereo, VR180 content only displays front facing content.
|
||||
|
||||
<center>
|
||||
<img img width="375" src="https://github-production-user-asset-6210df.s3.amazonaws.com/9502341/255379444-b90f5b3c-5021-4659-8732-17725669914e.jpeg">
|
||||
</center>
|
||||
|
||||
### Setup instructions
|
||||
To render for VR video it is essential to adjust the NeRF to have an approximately true-to-life real world scale (adjustable in the camera path) to ensure that the scene depth and IPD (distance between the eyes) is appropriate for the render to be viewable in VR. You can adjust the scene scale with the [Nerfstudio Blender Add-on](https://docs.nerf.studio/en/latest/extensions/blender_addon.html) by appropriately scaling a point cloud representation of the NeRF.
|
||||
Results may be unviewable if the scale is not set appropriately. The IPD is set at 64mm by default but only is accurate when the NeRF scene is true to scale.
|
||||
|
||||
For good quality renders, it is recommended to render at 4096x2048 per eye, or 2048x1024 per eye. Render resolutions must be specified in the camera path in a 2:1 aspect ratio. The final stacked render output will automatically be constructed as 1:1.
|
||||
For good quality renders, it is recommended to render at high resolutions (For ODS: 4096x2048 per eye, or 2048x1024 per eye. For VR180: 4096x4096 per eye or 2048x2048 per eye). Render resolutions for a single eye are specified in the camera path. For VR180, resolutions must be in a 1:1 aspect ratio. For ODS, resolutions must be in a 2:1 aspect ratio. The final stacked render output will automatically be constructed (with aspect ratios for VR180 as 2:1 and ODS as 1:1).
|
||||
|
||||
:::{admonition} Note
|
||||
:class: info
|
||||
If you are rendering an image sequence, it is recommended to render as png instead of jpeg, since the png will appear clearer. However, file sizes can be significantly larger with png.
|
||||
:::
|
||||
|
||||
To render with the ODS camera:
|
||||
1. Use the Nerfstudio Blender Add-on to set the scale of the NeRF scene and create the camera path
|
||||
To render with the VR videos camera:
|
||||
1. Use the [Nerfstudio Blender Add-on](https://docs.nerf.studio/en/latest/extensions/blender_addon.html) to set the scale of the NeRF scene and create the camera path
|
||||
- Export a point cloud representation of the NeRF
|
||||
- Import the point cloud representation in Blender and enable the Blender Add-on
|
||||
- Import the point cloud representation in Blender and enable the Nerfstudio Blender Add-on
|
||||
- Create a reference object such as a cube which may be 1x1x1 meter. You could also create a cylinder and scale it to an appropriate height of a viewer.
|
||||
- Now scale the point cloud representation accordingly to match the reference object. This is to ensure that the NeRF scene is scaled as close to real life.
|
||||
- To place the camera at the correct height from the ground in the scene, you create a cylinder representing the viewer vertically scaled to the viewer’s height, and place the camera at eye level.
|
||||
- To place the camera at the correct height from the ground in the scene, you can create a cylinder representing the viewer vertically scaled to the viewer’s height, and place the camera at eye level.
|
||||
- Animate the camera movement as needed
|
||||
- Create the camera path JSON file with the Nerfstudio Blender Add-on
|
||||
|
||||
2. Edit the JSON camera path file
|
||||
- Open the camera path JSON file and specify the `camera_type` as `omnidirectional`
|
||||
- Specify the `render_height` and `render_width` to the resolution of a single eye. The width:height aspect ratio must be 2:1. Recommended resolutions are 4096x2048 or 2048x1024.
|
||||
|
||||
**Omni-directional Stereo (360 VR)**
|
||||
- Open the camera path JSON file and specify the `camera_type` as `omnidirectional`
|
||||
- Specify the `render_height` and `render_width` to the resolution of a single eye. The width:height aspect ratio must be 2:1. Recommended resolutions are 4096x2048 or 2048x1024.
|
||||
<center>
|
||||
<img img width="250" src="https://github-production-user-asset-6210df.s3.amazonaws.com/9502341/240530527-22d14276-ac2c-46a5-a4b0-4785b7413241.png">
|
||||
</center>
|
||||
|
||||
|
||||
**VR180**
|
||||
- Open the camera path JSON file and specify the `camera_type` as `vr180`
|
||||
- Specify the `render_height` and `render_width` to the resolution of a single eye. The width:height aspect ratio must be 1:1. Recommended resolutions are 4096x4096 or 2048x2048.
|
||||
<center>
|
||||
<img img width="190" src="https://github-production-user-asset-6210df.s3.amazonaws.com/9502341/255379889-83b7fd09-ce8f-4868-8838-7be9b63f01b4.png">
|
||||
</center>
|
||||
|
||||
- Save the camera path and render the NeRF
|
||||
<center>
|
||||
<img img width="300" src="https://github-production-user-asset-6210df.s3.amazonaws.com/9502341/240530527-22d14276-ac2c-46a5-a4b0-4785b7413241.png">
|
||||
</center>
|
||||
|
||||
|
||||
:::{admonition} Note
|
||||
:class: info
|
||||
If the depth of the scene is unviewable and looks too close or expanded when viewing the render in VR, the scale of the NeRF may be set too small. If there is almost no discernible depth, the scale of the NeRF may be too large. Getting the right scale may take some experimentation, so it is recommended to either render at a much lower resolution or just one frame to ensure the depth and render is viewable in the VR headset.
|
||||
:::
|
||||
|
||||
### Additional Notes
|
||||
- Rendering with ODS can take significantly longer than traditional renders due to higher resolutions and needing to render a left and right eye view for each frame. Render times may grow exponentially with larger resolutions.
|
||||
- When rendering ODS content, Nerfstudio will first render the left eye, then the right eye, and finally vertically stack the renders. During this process, Nerfstudio will create a temporary folder to store the left and right eye renders and delete this folder once the final renders are stacked.
|
||||
#### Additional Notes
|
||||
- Rendering with VR180 or ODS can take significantly longer than traditional renders due to higher resolutions and needing to render a left and right eye view for each frame. Render times may grow exponentially with larger resolutions.
|
||||
- When rendering VR180 or ODS content, Nerfstudio will first render the left eye, then the right eye, and finally vertically stack the renders. During this process, Nerfstudio will create a temporary folder to store the left and right eye renders and delete this folder once the final renders are stacked.
|
||||
- If rendering content where the camera is stationary for many frames, it is recommended to only render once at that position and extend the time in a video editor since ODS renders can take a lot of time to render.
|
||||
- It is recommended to render a preliminary render at a much lower resolution or frame rate to test and ensure that the depth and camera position look accurate in VR.
|
||||
- The IPD can be modified in the `cameras.py` script as the variable `vr_ipd` (default is 64 mm).
|
||||
- Compositing with Blender Objects and VR180 or ODS Renders
|
||||
- Configure the Blender camera as panoramic and equirectangular. For the VR180 Blender camera, set the panoramic longitude min and max to -90 and 90.
|
||||
- Change the Stereoscopy mode to "Parallel" set the Interocular Distance to 0.064 m.
|
||||
@@ -144,7 +144,12 @@ build arg and look up [the compute capability for your GPU](https://developer.nv
|
||||
For example, here's how to build with support for GeForce 30xx series GPUs:
|
||||
|
||||
```bash
|
||||
docker build --build-arg CUDA_ARCHITECTURES=86 --tag nerfstudio-86 -f Dockerfile .
|
||||
docker build \
|
||||
--build-arg CUDA_VERSION=11.8.0 \
|
||||
--build-arg CUDA_ARCHITECTURES=86 \
|
||||
--build-arg OS_VERSION=22.04 \
|
||||
--tag nerfstudio-86 \
|
||||
--file Dockerfile .
|
||||
```
|
||||
|
||||
### Using an interactive container
|
||||
|
||||
@@ -10,10 +10,45 @@ Base
|
||||
:members:
|
||||
:show-inheritance:
|
||||
|
||||
Instant NGP
|
||||
Density
|
||||
----------------
|
||||
|
||||
.. automodule:: nerfstudio.fields.instant_ngp_field
|
||||
.. automodule:: nerfstudio.fields.density_fields
|
||||
:members:
|
||||
:show-inheritance:
|
||||
|
||||
Nerfacto
|
||||
----------------
|
||||
|
||||
.. automodule:: nerfstudio.fields.nerfacto_field
|
||||
:members:
|
||||
:show-inheritance:
|
||||
|
||||
Nerf-W
|
||||
----------------
|
||||
|
||||
.. automodule:: nerfstudio.fields.nerfw_field
|
||||
:members:
|
||||
:show-inheritance:
|
||||
|
||||
SDF
|
||||
----------------
|
||||
|
||||
.. automodule:: nerfstudio.fields.sdf_field
|
||||
:members:
|
||||
:show-inheritance:
|
||||
|
||||
Semantic NeRF
|
||||
----------------
|
||||
|
||||
.. automodule:: nerfstudio.fields.semantic_nerf_field
|
||||
:members:
|
||||
:show-inheritance:
|
||||
|
||||
TensoRF
|
||||
----------------
|
||||
|
||||
.. automodule:: nerfstudio.fields.tensorf_field
|
||||
:members:
|
||||
:show-inheritance:
|
||||
|
||||
|
||||
@@ -141,6 +141,8 @@ def get_path_from_json(camera_path: Dict[str, Any]) -> Cameras:
|
||||
camera_type = CameraType.EQUIRECTANGULAR
|
||||
elif camera_path["camera_type"].lower() == "omnidirectional":
|
||||
camera_type = CameraType.OMNIDIRECTIONALSTEREO_L
|
||||
elif camera_path["camera_type"].lower() == "vr180":
|
||||
camera_type = CameraType.VR180_L
|
||||
else:
|
||||
camera_type = CameraType.PERSPECTIVE
|
||||
|
||||
@@ -151,11 +153,13 @@ def get_path_from_json(camera_path: Dict[str, Any]) -> Cameras:
|
||||
# pose
|
||||
c2w = torch.tensor(camera["camera_to_world"]).view(4, 4)[:3]
|
||||
c2ws.append(c2w)
|
||||
if (
|
||||
camera_type == CameraType.EQUIRECTANGULAR
|
||||
or camera_type == CameraType.OMNIDIRECTIONALSTEREO_L
|
||||
or camera_type == CameraType.OMNIDIRECTIONALSTEREO_R
|
||||
):
|
||||
if camera_type in [
|
||||
CameraType.EQUIRECTANGULAR,
|
||||
CameraType.OMNIDIRECTIONALSTEREO_L,
|
||||
CameraType.OMNIDIRECTIONALSTEREO_R,
|
||||
CameraType.VR180_L,
|
||||
CameraType.VR180_R,
|
||||
]:
|
||||
fxs.append(image_width / 2)
|
||||
fys.append(image_height)
|
||||
else:
|
||||
|
||||
@@ -46,6 +46,8 @@ class CameraType(Enum):
|
||||
EQUIRECTANGULAR = auto()
|
||||
OMNIDIRECTIONALSTEREO_L = auto()
|
||||
OMNIDIRECTIONALSTEREO_R = auto()
|
||||
VR180_L = auto()
|
||||
VR180_R = auto()
|
||||
|
||||
|
||||
CAMERA_MODEL_TO_TYPE = {
|
||||
@@ -58,6 +60,8 @@ CAMERA_MODEL_TO_TYPE = {
|
||||
"EQUIRECTANGULAR": CameraType.EQUIRECTANGULAR,
|
||||
"OMNIDIRECTIONALSTEREO_L": CameraType.OMNIDIRECTIONALSTEREO_L,
|
||||
"OMNIDIRECTIONALSTEREO_R": CameraType.OMNIDIRECTIONALSTEREO_R,
|
||||
"VR180_L": CameraType.VR180_L,
|
||||
"VR180_R": CameraType.VR180_R,
|
||||
}
|
||||
|
||||
|
||||
@@ -694,8 +698,7 @@ class Cameras(TensorDataclass):
|
||||
|
||||
# circle of ODS ray origins
|
||||
ods_origins_circle = (
|
||||
ods_cam_position
|
||||
+ isRightEye * (vr_ipd / 2.0) * (ods_x_axis.repeat(c2w.shape[1], 1)) * (torch.cos(ods_theta))[:, None]
|
||||
isRightEye * (vr_ipd / 2.0) * (ods_x_axis.repeat(c2w.shape[1], 1)) * (torch.cos(ods_theta))[:, None]
|
||||
+ isRightEye * (vr_ipd / 2.0) * (ods_z_axis.repeat(c2w.shape[1], 1)) * (torch.sin(ods_theta))[:, None]
|
||||
)
|
||||
|
||||
@@ -709,6 +712,60 @@ class Cameras(TensorDataclass):
|
||||
|
||||
return ods_origins_circle, directions_stack
|
||||
|
||||
def _compute_rays_for_vr180(
|
||||
eye: Literal["left", "right"]
|
||||
) -> Tuple[Float[Tensor, "num_rays_shape 3"], Float[Tensor, "3 num_rays_shape 3"]]:
|
||||
"""Compute the rays for a VR180 camera
|
||||
|
||||
Args:
|
||||
eye: Which eye to compute rays for.
|
||||
|
||||
Returns:
|
||||
A tuple containing the origins and the directions of the rays.
|
||||
"""
|
||||
# Directions calculated similarly to equirectangular
|
||||
vr180_cam_type = CameraType.VR180_R.value if eye == "right" else CameraType.VR180_L.value
|
||||
mask = (self.camera_type[true_indices] == vr180_cam_type).squeeze(-1)
|
||||
mask = torch.stack([mask, mask, mask], dim=0)
|
||||
|
||||
# adjusting theta range to +/-90 deg
|
||||
theta = -torch.pi * ((x - cx) / (fx * 2))[0]
|
||||
phi = torch.pi * (0.5 - coord_stack[..., 1])
|
||||
|
||||
directions_stack[..., 0][mask] = torch.masked_select(-torch.sin(theta) * torch.sin(phi), mask).float()
|
||||
directions_stack[..., 1][mask] = torch.masked_select(torch.cos(phi), mask).float()
|
||||
directions_stack[..., 2][mask] = torch.masked_select(-torch.cos(theta) * torch.sin(phi), mask).float()
|
||||
|
||||
vr_ipd = 0.064 # IPD in meters (note: scale of NeRF must be true to life and can be adjusted with the Blender add-on)
|
||||
isRightEye = 1 if eye == "right" else -1
|
||||
|
||||
# find VR180 camera position
|
||||
c2w = self.camera_to_worlds[true_indices]
|
||||
assert c2w.shape == num_rays_shape + (3, 4)
|
||||
transposedC2W = c2w[0][0].t()
|
||||
vr180_cam_position = transposedC2W[3].repeat(c2w.shape[1], 1)
|
||||
|
||||
rotation = c2w[..., :3, :3]
|
||||
|
||||
-torch.pi * ((x - cx) / fx)[0]
|
||||
|
||||
# interocular axis of the VR180 camera
|
||||
vr180_x_axis = torch.tensor([1, 0, 0], device=c2w.device)
|
||||
|
||||
# VR180 ray origins of horizontal offset
|
||||
vr180_origins = isRightEye * (vr_ipd / 2.0) * (vr180_x_axis.repeat(c2w.shape[1], 1))
|
||||
|
||||
# rotate origins to match the camera rotation
|
||||
for i in range(vr180_origins.shape[0]):
|
||||
vr180_origins[i] = rotation[0][0] @ vr180_origins[i] + vr180_cam_position[0]
|
||||
|
||||
vr180_origins = vr180_origins.unsqueeze(0).repeat(c2w.shape[0], 1, 1)
|
||||
|
||||
# assign final camera origins
|
||||
c2w[..., :3, 3] = vr180_origins
|
||||
|
||||
return vr180_origins, directions_stack
|
||||
|
||||
for cam in cam_types:
|
||||
if CameraType.PERSPECTIVE.value in cam_types:
|
||||
mask = (self.camera_type[true_indices] == CameraType.PERSPECTIVE.value).squeeze(-1) # (num_rays)
|
||||
@@ -756,6 +813,17 @@ class Cameras(TensorDataclass):
|
||||
ods_origins_circle, directions_stack = _compute_rays_for_omnidirectional_stereo("right")
|
||||
# assign final camera origins
|
||||
c2w[..., :3, 3] = ods_origins_circle
|
||||
|
||||
elif CameraType.VR180_L.value in cam_types:
|
||||
vr180_origins, directions_stack = _compute_rays_for_vr180("left")
|
||||
# assign final camera origins
|
||||
c2w[..., :3, 3] = vr180_origins
|
||||
|
||||
elif CameraType.VR180_R.value in cam_types:
|
||||
vr180_origins, directions_stack = _compute_rays_for_vr180("right")
|
||||
# assign final camera origins
|
||||
c2w[..., :3, 3] = vr180_origins
|
||||
|
||||
else:
|
||||
raise ValueError(f"Camera type {cam} not supported.")
|
||||
|
||||
|
||||
@@ -17,7 +17,6 @@
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import warnings
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
from typing import Any, List, Literal, Optional, Tuple, Type
|
||||
@@ -25,8 +24,6 @@ from typing import Any, List, Literal, Optional, Tuple, Type
|
||||
# model instances
|
||||
from nerfstudio.utils import writer
|
||||
|
||||
warnings.filterwarnings("ignore", module="torchvision")
|
||||
|
||||
|
||||
# Pretty printing class
|
||||
class PrintableConfig:
|
||||
|
||||
@@ -20,23 +20,18 @@ from typing import TYPE_CHECKING
|
||||
|
||||
import tyro
|
||||
|
||||
from nerfstudio.data.dataparsers.arkitscenes_dataparser import (
|
||||
ARKitScenesDataParserConfig,
|
||||
)
|
||||
from nerfstudio.data.dataparsers.arkitscenes_dataparser import ARKitScenesDataParserConfig
|
||||
from nerfstudio.data.dataparsers.base_dataparser import DataParserConfig
|
||||
from nerfstudio.data.dataparsers.blender_dataparser import BlenderDataParserConfig
|
||||
from nerfstudio.data.dataparsers.colmap_dataparser import ColmapDataParserConfig
|
||||
from nerfstudio.data.dataparsers.dnerf_dataparser import DNeRFDataParserConfig
|
||||
from nerfstudio.data.dataparsers.dycheck_dataparser import DycheckDataParserConfig
|
||||
from nerfstudio.data.dataparsers.instant_ngp_dataparser import (
|
||||
InstantNGPDataParserConfig,
|
||||
)
|
||||
from nerfstudio.data.dataparsers.instant_ngp_dataparser import InstantNGPDataParserConfig
|
||||
from nerfstudio.data.dataparsers.minimal_dataparser import MinimalDataParserConfig
|
||||
from nerfstudio.data.dataparsers.nerfosr_dataparser import NeRFOSRDataParserConfig
|
||||
from nerfstudio.data.dataparsers.nerfstudio_dataparser import NerfstudioDataParserConfig
|
||||
from nerfstudio.data.dataparsers.nuscenes_dataparser import NuScenesDataParserConfig
|
||||
from nerfstudio.data.dataparsers.phototourism_dataparser import (
|
||||
PhototourismDataParserConfig,
|
||||
)
|
||||
from nerfstudio.data.dataparsers.phototourism_dataparser import PhototourismDataParserConfig
|
||||
from nerfstudio.data.dataparsers.scannet_dataparser import ScanNetDataParserConfig
|
||||
from nerfstudio.data.dataparsers.sdfstudio_dataparser import SDFStudioDataParserConfig
|
||||
from nerfstudio.data.dataparsers.sitcoms3d_dataparser import Sitcoms3DDataParserConfig
|
||||
@@ -56,6 +51,7 @@ dataparsers = {
|
||||
"sdfstudio-data": SDFStudioDataParserConfig(),
|
||||
"nerfosr-data": NeRFOSRDataParserConfig(),
|
||||
"sitcoms3d-data": Sitcoms3DDataParserConfig(),
|
||||
"colmap": ColmapDataParserConfig(),
|
||||
}
|
||||
|
||||
external_dataparsers = discover_dataparsers()
|
||||
|
||||
@@ -76,6 +76,8 @@ class ExperimentConfig(InstantiateConfig):
|
||||
"""Alias for --pipeline.model.prompt"""
|
||||
relative_model_dir: Path = Path("nerfstudio_models/")
|
||||
"""Relative path to save all checkpoints."""
|
||||
load_scheduler: bool = True
|
||||
"""Whether to load the scheduler state_dict to resume training, if exists"""
|
||||
|
||||
def is_viewer_enabled(self) -> bool:
|
||||
"""Checks if a viewer is enabled."""
|
||||
|
||||
@@ -137,7 +137,6 @@ method_configs["nerfacto-big"] = TrainerConfig(
|
||||
hidden_dim=128,
|
||||
hidden_dim_color=128,
|
||||
appearance_embed_dim=128,
|
||||
base_res=32,
|
||||
max_res=4096,
|
||||
proposal_weights_anneal_max_num_iters=5000,
|
||||
log2_hashmap_size=21,
|
||||
@@ -184,8 +183,6 @@ method_configs["nerfacto-huge"] = TrainerConfig(
|
||||
hidden_dim=256,
|
||||
hidden_dim_color=256,
|
||||
appearance_embed_dim=32,
|
||||
features_per_level=4,
|
||||
base_res=32,
|
||||
max_res=8192,
|
||||
proposal_weights_anneal_max_num_iters=5000,
|
||||
log2_hashmap_size=21,
|
||||
|
||||
@@ -18,11 +18,11 @@ Datamanager.
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import functools
|
||||
from abc import abstractmethod
|
||||
from collections import defaultdict
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from functools import cached_property
|
||||
from typing import (
|
||||
Any,
|
||||
Callable,
|
||||
@@ -35,6 +35,9 @@ from typing import (
|
||||
Type,
|
||||
Union,
|
||||
cast,
|
||||
ForwardRef,
|
||||
get_origin,
|
||||
get_args,
|
||||
)
|
||||
|
||||
import torch
|
||||
@@ -65,6 +68,7 @@ from nerfstudio.engine.callbacks import TrainingCallback, TrainingCallbackAttrib
|
||||
from nerfstudio.model_components.ray_generators import RayGenerator
|
||||
from nerfstudio.utils.misc import IterableWrapper
|
||||
from nerfstudio.utils.rich_utils import CONSOLE
|
||||
from nerfstudio.utils.misc import get_orig_class
|
||||
|
||||
|
||||
def variable_res_collate(batch: List[Dict]) -> Dict:
|
||||
@@ -375,7 +379,6 @@ class VanillaDataManager(DataManager, Generic[TDataset]):
|
||||
local_rank: int = 0,
|
||||
**kwargs,
|
||||
):
|
||||
self.dataset_type: Type[TDataset] = kwargs.get("_dataset_type", getattr(TDataset, "__default__"))
|
||||
self.config = config
|
||||
self.device = device
|
||||
self.world_size = world_size
|
||||
@@ -408,15 +411,32 @@ class VanillaDataManager(DataManager, Generic[TDataset]):
|
||||
CONSOLE.print("Variable resolution, using variable_res_collate")
|
||||
self.config.collate_fn = variable_res_collate
|
||||
break
|
||||
|
||||
super().__init__()
|
||||
|
||||
def __class_getitem__(cls, item):
|
||||
return type(
|
||||
cls.__name__,
|
||||
(cls,),
|
||||
{"__module__": cls.__module__, "__init__": functools.partialmethod(cls.__init__, _dataset_type=item)},
|
||||
)
|
||||
@cached_property
|
||||
def dataset_type(self) -> Type[TDataset]:
|
||||
"""Returns the dataset type passed as the generic argument"""
|
||||
default: Type[TDataset] = cast(TDataset, TDataset.__default__) # type: ignore
|
||||
orig_class: Type[VanillaDataManager] = get_orig_class(self, default=None) # type: ignore
|
||||
if type(self) is VanillaDataManager and orig_class is None:
|
||||
return default
|
||||
if orig_class is not None and get_origin(orig_class) is VanillaDataManager:
|
||||
return get_args(orig_class)[0]
|
||||
|
||||
# For inherited classes, we need to find the correct type to instantiate
|
||||
for base in getattr(self, "__orig_bases__", []):
|
||||
if get_origin(base) is VanillaDataManager:
|
||||
for value in get_args(base):
|
||||
if isinstance(value, ForwardRef):
|
||||
if value.__forward_evaluated__:
|
||||
value = value.__forward_value__
|
||||
elif value.__forward_module__ is None:
|
||||
value.__forward_module__ = type(self).__module__
|
||||
value = getattr(value, "_evaluate")(None, None, set())
|
||||
assert isinstance(value, type)
|
||||
if issubclass(value, InputDataset):
|
||||
return cast(Type[TDataset], value)
|
||||
return default
|
||||
|
||||
def create_train_dataset(self) -> TDataset:
|
||||
"""Sets up the data loaders for training"""
|
||||
|
||||
@@ -0,0 +1,402 @@
|
||||
# Copyright 2022 the Regents of the University of California, Nerfstudio Team and contributors. All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" Data parser for nerfstudio datasets. """
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
import sys
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from typing import List, Literal, Optional, Type
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
from rich.prompt import Confirm
|
||||
|
||||
from nerfstudio.cameras import camera_utils
|
||||
from nerfstudio.cameras.cameras import CAMERA_MODEL_TO_TYPE, Cameras
|
||||
from nerfstudio.data.dataparsers.base_dataparser import DataParser, DataParserConfig, DataparserOutputs
|
||||
from nerfstudio.data.scene_box import SceneBox
|
||||
from nerfstudio.data.utils import colmap_parsing_utils as colmap_utils
|
||||
from nerfstudio.process_data.colmap_utils import parse_colmap_camera_params
|
||||
from nerfstudio.process_data.process_data_utils import downscale_images
|
||||
from nerfstudio.utils.rich_utils import CONSOLE
|
||||
|
||||
MAX_AUTO_RESOLUTION = 1600
|
||||
|
||||
|
||||
@dataclass
|
||||
class ColmapDataParserConfig(DataParserConfig):
|
||||
"""Nerfstudio dataset config"""
|
||||
|
||||
_target: Type = field(default_factory=lambda: ColmapDataParser)
|
||||
"""target class to instantiate"""
|
||||
data: Path = Path()
|
||||
"""Directory or explicit json file path specifying location of data."""
|
||||
scale_factor: float = 1.0
|
||||
"""How much to scale the camera origins by."""
|
||||
downscale_factor: Optional[int] = None
|
||||
"""How much to downscale images. If not set, images are chosen such that the max dimension is <1600px."""
|
||||
scene_scale: float = 1.0
|
||||
"""How much to scale the region of interest by."""
|
||||
orientation_method: Literal["pca", "up", "vertical", "none"] = "up"
|
||||
"""The method to use for orientation."""
|
||||
center_method: Literal["poses", "focus", "none"] = "poses"
|
||||
"""The method to use to center the poses."""
|
||||
auto_scale_poses: bool = True
|
||||
"""Whether to automatically scale the poses to fit in +/- 1 bounding box."""
|
||||
train_split_fraction: float = 0.9
|
||||
"""The fraction of images to use for training. The remaining images are for eval."""
|
||||
depth_unit_scale_factor: float = 1e-3
|
||||
"""Scales the depth values to meters. Default value is 0.001 for a millimeter to meter conversion."""
|
||||
|
||||
images_path: Path = Path("images")
|
||||
"""Path to images directory relative to the data path."""
|
||||
masks_path: Optional[Path] = None
|
||||
"""Path to masks directory. If not set, masks are not loaded."""
|
||||
depths_path: Optional[Path] = None
|
||||
"""Path to depth maps directory. If not set, depths are not loaded."""
|
||||
colmap_path: Path = Path("sparse/0")
|
||||
"""Path to the colmap reconstruction directory relative to the data path."""
|
||||
|
||||
|
||||
class ColmapDataParser(DataParser):
|
||||
"""COLMAP DatasetParser.
|
||||
Expects a folder with the following structure:
|
||||
images/ # folder containing images used to create the COLMAP model
|
||||
sparse/0 # folder containing the COLMAP reconstruction (either TEXT or BINARY format)
|
||||
masks/ # (OPTIONAL) folder containing masks for each image
|
||||
depths/ # (OPTIONAL) folder containing depth maps for each image
|
||||
The paths can be different and can be specified in the config. (e.g., sparse/0 -> sparse)
|
||||
Currently, most COLMAP camera models are supported except for the FULL_OPENCV and THIN_PRISM_FISHEYE models.
|
||||
|
||||
The dataparser loads the downscaled images from folders with `_{downscale_factor}` suffix.
|
||||
If these folders do not exist, the user can choose to automatically downscale the images and
|
||||
create these folders.
|
||||
|
||||
The loader is compatible with the datasets processed using the ns-process-data script and
|
||||
can be used as a drop-in replacement. It further supports datasets like Mip-NeRF 360 (although
|
||||
in the case of Mip-NeRF 360 the downsampled images may have a different resolution because they
|
||||
use different rounding when computing the image resolution).
|
||||
"""
|
||||
|
||||
config: ColmapDataParserConfig
|
||||
|
||||
def __init__(self, config: ColmapDataParserConfig):
|
||||
super().__init__(config)
|
||||
self.config = config
|
||||
self._downscale_factor = None
|
||||
|
||||
def _get_all_images_and_cameras(self, recon_dir: Path):
|
||||
if (recon_dir / "cameras.txt").exists():
|
||||
cam_id_to_camera = colmap_utils.read_cameras_text(recon_dir / "cameras.txt")
|
||||
im_id_to_image = colmap_utils.read_images_text(recon_dir / "images.txt")
|
||||
elif (recon_dir / "cameras.bin").exists():
|
||||
cam_id_to_camera = colmap_utils.read_cameras_binary(recon_dir / "cameras.bin")
|
||||
im_id_to_image = colmap_utils.read_images_binary(recon_dir / "images.bin")
|
||||
else:
|
||||
raise ValueError(f"Could not find cameras.txt or cameras.bin in {recon_dir}")
|
||||
|
||||
cameras = {}
|
||||
frames = []
|
||||
camera_model = None
|
||||
|
||||
# Parse cameras
|
||||
for cam_id, cam_data in cam_id_to_camera.items():
|
||||
cameras[cam_id] = parse_colmap_camera_params(cam_data)
|
||||
|
||||
# Parse frames
|
||||
for im_id, im_data in im_id_to_image.items():
|
||||
# NB: COLMAP uses Eigen / scalar-first quaternions
|
||||
# * https://colmap.github.io/format.html
|
||||
# * https://github.com/colmap/colmap/blob/bf3e19140f491c3042bfd85b7192ef7d249808ec/src/base/pose.cc#L75
|
||||
# the `rotation_matrix()` handles that format for us.
|
||||
rotation = colmap_utils.qvec2rotmat(im_data.qvec)
|
||||
translation = im_data.tvec.reshape(3, 1)
|
||||
w2c = np.concatenate([rotation, translation], 1)
|
||||
w2c = np.concatenate([w2c, np.array([[0, 0, 0, 1]])], 0)
|
||||
c2w = np.linalg.inv(w2c)
|
||||
# Convert from COLMAP's camera coordinate system (OpenCV) to ours (OpenGL)
|
||||
c2w[0:3, 1:3] *= -1
|
||||
c2w = c2w[np.array([1, 0, 2, 3]), :]
|
||||
c2w[2, :] *= -1
|
||||
|
||||
frame = {
|
||||
"file_path": (self.config.images_path / im_data.name).as_posix(),
|
||||
"transform_matrix": c2w,
|
||||
"colmap_im_id": im_id,
|
||||
}
|
||||
frame.update(cameras[im_data.camera_id])
|
||||
if self.config.masks_path is not None:
|
||||
frame["mask_path"] = ((self.config.masks_path / im_data.name).with_suffix(".png").as_posix(),)
|
||||
if self.config.depths_path is not None:
|
||||
frame["depth_path"] = ((self.config.depths_path / im_data.name).with_suffix(".png").as_posix(),)
|
||||
frames.append(frame)
|
||||
if camera_model is not None:
|
||||
assert camera_model == frame["camera_model"], "Multiple camera models are not supported"
|
||||
else:
|
||||
camera_model = frame["camera_model"]
|
||||
|
||||
out = {}
|
||||
out["frames"] = frames
|
||||
applied_transform = np.eye(4)[:3, :]
|
||||
applied_transform = applied_transform[np.array([1, 0, 2]), :]
|
||||
applied_transform[2, :] *= -1
|
||||
out["applied_transform"] = applied_transform.tolist()
|
||||
out["camera_model"] = camera_model
|
||||
assert len(frames) > 0, "No images found in the colmap model"
|
||||
return out
|
||||
|
||||
def _get_image_indices(self, image_filenames, split):
|
||||
has_split_files_spec = (
|
||||
(self.config.data / "train_list.txt").exists()
|
||||
or (self.config.data / "test_list.txt").exists()
|
||||
or (self.config.data / "validation_list.txt").exists()
|
||||
)
|
||||
if (self.config.data / f"{split}_list.txt").exists():
|
||||
CONSOLE.log(f"Using {split}_list.txt to get indices for split {split}.")
|
||||
with (self.config.data / f"{split}_list.txt").open("r", encoding="utf8") as f:
|
||||
filenames = f.read().splitlines()
|
||||
# Validate split first
|
||||
split_filenames = set(self.config.images_path / x for x in filenames)
|
||||
unmatched_filenames = split_filenames.difference(image_filenames)
|
||||
if unmatched_filenames:
|
||||
raise RuntimeError(
|
||||
f"Some filenames for split {split} were not found: {set(map(str, unmatched_filenames))}."
|
||||
)
|
||||
|
||||
indices = [i for i, path in enumerate(image_filenames) if path in split_filenames]
|
||||
CONSOLE.log(f"[yellow] Dataset is overriding {split}_indices to {indices}")
|
||||
indices = np.array(indices, dtype=np.int32)
|
||||
elif has_split_files_spec:
|
||||
raise RuntimeError(f"The dataset's list of filenames for split {split} is missing.")
|
||||
else:
|
||||
# filter image_filenames and poses based on train/eval split percentage
|
||||
num_images = len(image_filenames)
|
||||
num_train_images = math.ceil(num_images * self.config.train_split_fraction)
|
||||
num_eval_images = num_images - num_train_images
|
||||
i_all = np.arange(num_images)
|
||||
i_train = np.linspace(
|
||||
0, num_images - 1, num_train_images, dtype=int
|
||||
) # equally spaced training images starting and ending at 0 and num_images-1
|
||||
i_eval = np.setdiff1d(i_all, i_train) # eval images are the remaining images
|
||||
assert len(i_eval) == num_eval_images
|
||||
if split == "train":
|
||||
indices = i_train
|
||||
elif split in ["val", "test"]:
|
||||
indices = i_eval
|
||||
else:
|
||||
raise ValueError(f"Unknown dataparser split {split}")
|
||||
return indices
|
||||
|
||||
def _generate_dataparser_outputs(self, split: str = "train"):
|
||||
assert self.config.data.exists(), f"Data directory {self.config.data} does not exist."
|
||||
colmap_path = self.config.data / self.config.colmap_path
|
||||
assert colmap_path.exists(), f"Colmap path {colmap_path} does not exist."
|
||||
|
||||
meta = self._get_all_images_and_cameras(colmap_path)
|
||||
camera_type = CAMERA_MODEL_TO_TYPE[meta["camera_model"]]
|
||||
|
||||
image_filenames = []
|
||||
mask_filenames = []
|
||||
depth_filenames = []
|
||||
poses = []
|
||||
|
||||
fx = []
|
||||
fy = []
|
||||
cx = []
|
||||
cy = []
|
||||
height = []
|
||||
width = []
|
||||
distort = []
|
||||
|
||||
for frame in meta["frames"]:
|
||||
fx.append(float(frame["fl_x"]))
|
||||
fy.append(float(frame["fl_y"]))
|
||||
cx.append(float(frame["cx"]))
|
||||
cy.append(float(frame["cy"]))
|
||||
height.append(int(frame["h"]))
|
||||
width.append(int(frame["w"]))
|
||||
distort.append(
|
||||
camera_utils.get_distortion_params(
|
||||
k1=float(frame["k1"]) if "k1" in frame else 0.0,
|
||||
k2=float(frame["k2"]) if "k2" in frame else 0.0,
|
||||
k3=float(frame["k3"]) if "k3" in frame else 0.0,
|
||||
k4=float(frame["k4"]) if "k4" in frame else 0.0,
|
||||
p1=float(frame["p1"]) if "p1" in frame else 0.0,
|
||||
p2=float(frame["p2"]) if "p2" in frame else 0.0,
|
||||
)
|
||||
)
|
||||
|
||||
image_filenames.append(Path(frame["file_path"]))
|
||||
poses.append(frame["transform_matrix"])
|
||||
if "mask_path" in frame:
|
||||
mask_filenames.append(Path(frame["mask_path"]))
|
||||
if "depth_path" in frame:
|
||||
depth_filenames.append(Path(frame["depth_path"]))
|
||||
|
||||
assert len(mask_filenames) == 0 or (
|
||||
len(mask_filenames) == len(image_filenames)
|
||||
), """
|
||||
Different number of image and mask filenames.
|
||||
You should check that mask_path is specified for every frame (or zero frames) in transforms.json.
|
||||
"""
|
||||
assert len(depth_filenames) == 0 or (
|
||||
len(depth_filenames) == len(image_filenames)
|
||||
), """
|
||||
Different number of image and depth filenames.
|
||||
You should check that depth_file_path is specified for every frame (or zero frames) in transforms.json.
|
||||
"""
|
||||
poses = torch.from_numpy(np.array(poses).astype(np.float32))
|
||||
poses, transform_matrix = camera_utils.auto_orient_and_center_poses(
|
||||
poses,
|
||||
method=self.config.orientation_method,
|
||||
center_method=self.config.center_method,
|
||||
)
|
||||
|
||||
# Scale poses
|
||||
scale_factor = 1.0
|
||||
if self.config.auto_scale_poses:
|
||||
scale_factor /= float(torch.max(torch.abs(poses[:, :3, 3])))
|
||||
scale_factor *= self.config.scale_factor
|
||||
|
||||
poses[:, :3, 3] *= scale_factor
|
||||
|
||||
# Choose image_filenames and poses based on split, but after auto orient and scaling the poses.
|
||||
indices = self._get_image_indices(image_filenames, split)
|
||||
image_filenames, mask_filenames, depth_filenames, downscale_factor = self._setup_downscale_factor(
|
||||
image_filenames, mask_filenames, depth_filenames
|
||||
)
|
||||
|
||||
image_filenames = [image_filenames[i] for i in indices]
|
||||
mask_filenames = [mask_filenames[i] for i in indices] if len(mask_filenames) > 0 else []
|
||||
depth_filenames = [depth_filenames[i] for i in indices] if len(depth_filenames) > 0 else []
|
||||
|
||||
idx_tensor = torch.tensor(indices, dtype=torch.long)
|
||||
poses = poses[idx_tensor]
|
||||
|
||||
# in x,y,z order
|
||||
# assumes that the scene is centered at the origin
|
||||
aabb_scale = self.config.scene_scale
|
||||
scene_box = SceneBox(
|
||||
aabb=torch.tensor(
|
||||
[[-aabb_scale, -aabb_scale, -aabb_scale], [aabb_scale, aabb_scale, aabb_scale]], dtype=torch.float32
|
||||
)
|
||||
)
|
||||
|
||||
fx = torch.tensor(fx, dtype=torch.float32)[idx_tensor]
|
||||
fy = torch.tensor(fy, dtype=torch.float32)[idx_tensor]
|
||||
cx = torch.tensor(cx, dtype=torch.float32)[idx_tensor]
|
||||
cy = torch.tensor(cy, dtype=torch.float32)[idx_tensor]
|
||||
height = torch.tensor(height, dtype=torch.int32)[idx_tensor]
|
||||
width = torch.tensor(width, dtype=torch.int32)[idx_tensor]
|
||||
distortion_params = torch.stack(distort, dim=0)[idx_tensor]
|
||||
|
||||
cameras = Cameras(
|
||||
fx=fx,
|
||||
fy=fy,
|
||||
cx=cx,
|
||||
cy=cy,
|
||||
distortion_params=distortion_params,
|
||||
height=height,
|
||||
width=width,
|
||||
camera_to_worlds=poses[:, :3, :4],
|
||||
camera_type=camera_type,
|
||||
)
|
||||
|
||||
cameras.rescale_output_resolution(scaling_factor=1.0 / downscale_factor)
|
||||
|
||||
if "applied_transform" in meta:
|
||||
applied_transform = torch.tensor(meta["applied_transform"], dtype=transform_matrix.dtype)
|
||||
transform_matrix = transform_matrix @ torch.cat(
|
||||
[applied_transform, torch.tensor([[0, 0, 0, 1]], dtype=transform_matrix.dtype)], 0
|
||||
)
|
||||
if "applied_scale" in meta:
|
||||
applied_scale = float(meta["applied_scale"])
|
||||
scale_factor *= applied_scale
|
||||
|
||||
dataparser_outputs = DataparserOutputs(
|
||||
image_filenames=image_filenames,
|
||||
cameras=cameras,
|
||||
scene_box=scene_box,
|
||||
mask_filenames=mask_filenames if len(mask_filenames) > 0 else None,
|
||||
dataparser_scale=scale_factor,
|
||||
dataparser_transform=transform_matrix,
|
||||
metadata={
|
||||
"depth_filenames": depth_filenames if len(depth_filenames) > 0 else None,
|
||||
"depth_unit_scale_factor": self.config.depth_unit_scale_factor,
|
||||
},
|
||||
)
|
||||
return dataparser_outputs
|
||||
|
||||
def _setup_downscale_factor(
|
||||
self, image_filenames: List[Path], mask_filenames: List[Path], depth_filenames: List[Path]
|
||||
):
|
||||
"""
|
||||
Setup the downscale factor for the dataset. This is used to downscale the images and cameras.
|
||||
"""
|
||||
|
||||
def get_fname(filepath: Path) -> Path:
|
||||
"""Returns transformed file name when downscale factor is applied"""
|
||||
parts = list(filepath.parts)
|
||||
parts[-2] += f"_{self._downscale_factor}"
|
||||
filepath = Path(*parts)
|
||||
return self.config.data / filepath
|
||||
|
||||
filepath = next(iter(image_filenames))
|
||||
if self._downscale_factor is None:
|
||||
if self.config.downscale_factor is None:
|
||||
test_img = Image.open(self.config.data / filepath)
|
||||
h, w = test_img.size
|
||||
max_res = max(h, w)
|
||||
df = 0
|
||||
while True:
|
||||
if (max_res / 2 ** (df)) < MAX_AUTO_RESOLUTION:
|
||||
break
|
||||
df += 1
|
||||
|
||||
self._downscale_factor = 2**df
|
||||
CONSOLE.log(f"Using image downscale factor of {self._downscale_factor}")
|
||||
else:
|
||||
self._downscale_factor = self.config.downscale_factor
|
||||
if self._downscale_factor > 1 and not all(get_fname(fp).parent.exists() for fp in image_filenames):
|
||||
# Downscaled images not found
|
||||
# Ask if user wants to downscale the images automatically here
|
||||
CONSOLE.print(
|
||||
f"[bold red]Downscaled images do not exist for factor of {self._downscale_factor}.[/bold red]"
|
||||
)
|
||||
if Confirm.ask("\nWould you like to downscale the images now?", default=False, console=CONSOLE):
|
||||
# Install the method
|
||||
image_dir = image_filenames[0].parent
|
||||
num_downscales = int(math.log2(self._downscale_factor))
|
||||
assert 2**num_downscales == self._downscale_factor, "Downscale factor must be a power of 2"
|
||||
downscale_images(image_dir, num_downscales, folder_name=image_dir.name, nearest_neighbor=False)
|
||||
if len(mask_filenames) > 0:
|
||||
mask_dir = mask_filenames[0].parent
|
||||
downscale_images(mask_dir, num_downscales, folder_name=mask_dir.name, nearest_neighbor=True)
|
||||
if len(depth_filenames) > 0:
|
||||
depth_dir = depth_filenames[0].parent
|
||||
downscale_images(depth_dir, num_downscales, folder_name=depth_dir.name, nearest_neighbor=False)
|
||||
else:
|
||||
sys.exit(1)
|
||||
|
||||
# Return transformed filenames
|
||||
if self._downscale_factor > 1:
|
||||
image_filenames = [get_fname(fp) for fp in image_filenames]
|
||||
mask_filenames = [get_fname(fp) for fp in mask_filenames]
|
||||
depth_filenames = [get_fname(fp) for fp in depth_filenames]
|
||||
assert isinstance(self._downscale_factor, int)
|
||||
return image_filenames, mask_filenames, depth_filenames, self._downscale_factor
|
||||
@@ -85,10 +85,7 @@ class InputDataset(Dataset):
|
||||
"""
|
||||
image = torch.from_numpy(self.get_numpy_image(image_idx).astype("float32") / 255.0)
|
||||
if self._dataparser_outputs.alpha_color is not None and image.shape[-1] == 4:
|
||||
assert image.shape[-1] == 4
|
||||
image = image[:, :, :3] * image[:, :, -1:] + self._dataparser_outputs.alpha_color * (1.0 - image[:, :, -1:])
|
||||
else:
|
||||
image = image[:, :, :3]
|
||||
return image
|
||||
|
||||
def get_data(self, image_idx: int) -> Dict:
|
||||
|
||||
@@ -159,3 +159,12 @@ class Optimizers:
|
||||
"""
|
||||
for k, v in loaded_state.items():
|
||||
self.optimizers[k].load_state_dict(v)
|
||||
|
||||
def load_schedulers(self, loaded_state: Dict[str, Any]) -> None:
|
||||
"""Helper to load the scheduler state from previous checkpoint
|
||||
|
||||
Args:
|
||||
loaded_state: the state from the previous checkpoint
|
||||
"""
|
||||
for k, v in loaded_state.items():
|
||||
self.schedulers[k].load_state_dict(v)
|
||||
@@ -266,7 +266,7 @@ class Trainer:
|
||||
name=EventName.TRAIN_RAYS_PER_SEC,
|
||||
duration=self.world_size
|
||||
* self.pipeline.datamanager.get_train_rays_per_batch()
|
||||
/ train_t.duration,
|
||||
/ max(0.001, train_t.duration),
|
||||
step=step,
|
||||
avg_over_steps=True,
|
||||
)
|
||||
@@ -406,6 +406,8 @@ class Trainer:
|
||||
# load the checkpoints for pipeline, optimizers, and gradient scalar
|
||||
self.pipeline.load_pipeline(loaded_state["pipeline"], loaded_state["step"])
|
||||
self.optimizers.load_optimizers(loaded_state["optimizers"])
|
||||
if "schedulers" in loaded_state and self.config.load_scheduler:
|
||||
self.optimizers.load_schedulers(loaded_state["schedulers"])
|
||||
self.grad_scaler.load_state_dict(loaded_state["scalers"])
|
||||
CONSOLE.print(f"Done loading Nerfstudio checkpoint from {load_path}")
|
||||
elif load_checkpoint is not None:
|
||||
@@ -415,6 +417,8 @@ class Trainer:
|
||||
# load the checkpoints for pipeline, optimizers, and gradient scalar
|
||||
self.pipeline.load_pipeline(loaded_state["pipeline"], loaded_state["step"])
|
||||
self.optimizers.load_optimizers(loaded_state["optimizers"])
|
||||
if "schedulers" in loaded_state and self.config.load_scheduler:
|
||||
self.optimizers.load_schedulers(loaded_state["schedulers"])
|
||||
self.grad_scaler.load_state_dict(loaded_state["scalers"])
|
||||
CONSOLE.print(f"Done loading Nerfstudio checkpoint from {load_checkpoint}")
|
||||
else:
|
||||
@@ -439,6 +443,7 @@ class Trainer:
|
||||
if hasattr(self.pipeline, "module")
|
||||
else self.pipeline.state_dict(),
|
||||
"optimizers": {k: v.state_dict() for (k, v) in self.optimizers.optimizers.items()},
|
||||
"schedulers": {k: v.state_dict() for (k, v) in self.optimizers.schedulers.items()},
|
||||
"scalers": self.grad_scaler.state_dict(),
|
||||
},
|
||||
ckpt_path,
|
||||
|
||||
@@ -28,13 +28,7 @@ import open3d as o3d
|
||||
import pymeshlab
|
||||
import torch
|
||||
from jaxtyping import Float
|
||||
from rich.progress import (
|
||||
BarColumn,
|
||||
Progress,
|
||||
TaskProgressColumn,
|
||||
TextColumn,
|
||||
TimeRemainingColumn,
|
||||
)
|
||||
from rich.progress import BarColumn, Progress, TaskProgressColumn, TextColumn, TimeRemainingColumn
|
||||
from torch import Tensor
|
||||
|
||||
from nerfstudio.cameras.cameras import Cameras
|
||||
@@ -85,6 +79,7 @@ def generate_point_cloud(
|
||||
num_points: int = 1000000,
|
||||
remove_outliers: bool = True,
|
||||
estimate_normals: bool = False,
|
||||
reorient_normals: bool = False,
|
||||
rgb_output_name: str = "rgb",
|
||||
depth_output_name: str = "depth",
|
||||
normal_output_name: Optional[str] = None,
|
||||
@@ -99,6 +94,7 @@ def generate_point_cloud(
|
||||
pipeline: Pipeline to evaluate with.
|
||||
num_points: Number of points to generate. May result in less if outlier removal is used.
|
||||
remove_outliers: Whether to remove outliers.
|
||||
reorient_normals: Whether to re-orient the normals based on the view direction.
|
||||
estimate_normals: Whether to estimate normals.
|
||||
rgb_output_name: Name of the RGB output.
|
||||
depth_output_name: Name of the depth output.
|
||||
@@ -122,6 +118,8 @@ def generate_point_cloud(
|
||||
points = []
|
||||
rgbs = []
|
||||
normals = []
|
||||
view_directions = []
|
||||
|
||||
with progress as progress_bar:
|
||||
task = progress_bar.add_task("Generating Point Cloud", total=num_points)
|
||||
while not progress_bar.finished:
|
||||
@@ -140,7 +138,7 @@ def generate_point_cloud(
|
||||
CONSOLE.print(f"Could not find {depth_output_name} in the model outputs", justify="center")
|
||||
CONSOLE.print(f"Please set --depth_output_name to one of: {outputs.keys()}", justify="center")
|
||||
sys.exit(1)
|
||||
rgb = outputs[rgb_output_name]
|
||||
rgba = pipeline.model.get_rgba_image(outputs, rgb_output_name)
|
||||
depth = outputs[depth_output_name]
|
||||
if normal_output_name is not None:
|
||||
if normal_output_name not in outputs:
|
||||
@@ -154,6 +152,15 @@ def generate_point_cloud(
|
||||
), "Normal values from method output must be in [0, 1]"
|
||||
normal = (normal * 2.0) - 1.0
|
||||
point = ray_bundle.origins + ray_bundle.directions * depth
|
||||
view_direction = ray_bundle.directions
|
||||
|
||||
# Filter points with opacity lower than 0.5
|
||||
mask = rgba[..., -1] > 0.5
|
||||
point = point[mask]
|
||||
view_direction = view_direction[mask]
|
||||
rgb = rgba[mask][..., :3]
|
||||
if normal is not None:
|
||||
normal = normal[mask]
|
||||
|
||||
if use_bounding_box:
|
||||
comp_l = torch.tensor(bounding_box_min, device=point.device)
|
||||
@@ -164,16 +171,19 @@ def generate_point_cloud(
|
||||
mask = torch.all(torch.concat([point > comp_l, point < comp_m], dim=-1), dim=-1)
|
||||
point = point[mask]
|
||||
rgb = rgb[mask]
|
||||
view_direction = view_direction[mask]
|
||||
if normal is not None:
|
||||
normal = normal[mask]
|
||||
|
||||
points.append(point)
|
||||
rgbs.append(rgb)
|
||||
view_directions.append(view_direction)
|
||||
if normal is not None:
|
||||
normals.append(normal)
|
||||
progress.advance(task, point.shape[0])
|
||||
points = torch.cat(points, dim=0)
|
||||
rgbs = torch.cat(rgbs, dim=0)
|
||||
view_directions = torch.cat(view_directions, dim=0).cpu()
|
||||
|
||||
pcd = o3d.geometry.PointCloud()
|
||||
pcd.points = o3d.utility.Vector3dVector(points.double().cpu().numpy())
|
||||
@@ -185,6 +195,8 @@ def generate_point_cloud(
|
||||
pcd, ind = pcd.remove_statistical_outlier(nb_neighbors=20, std_ratio=std_ratio)
|
||||
print("\033[A\033[A")
|
||||
CONSOLE.print("[bold green]:white_check_mark: Cleaning Point Cloud")
|
||||
if ind is not None:
|
||||
view_directions = view_directions[ind]
|
||||
|
||||
# either estimate_normals or normal_output_name, not both
|
||||
if estimate_normals:
|
||||
@@ -203,6 +215,13 @@ def generate_point_cloud(
|
||||
normals = normals[ind]
|
||||
pcd.normals = o3d.utility.Vector3dVector(normals.double().cpu().numpy())
|
||||
|
||||
# re-orient the normals
|
||||
if reorient_normals:
|
||||
normals = torch.from_numpy(np.array(pcd.normals)).float()
|
||||
mask = torch.sum(view_directions * normals, dim=-1) > 0
|
||||
normals[mask] *= -1
|
||||
pcd.normals = o3d.utility.Vector3dVector(normals.double().cpu().numpy())
|
||||
|
||||
return pcd
|
||||
|
||||
|
||||
@@ -213,6 +232,7 @@ def render_trajectory(
|
||||
depth_output_name: str,
|
||||
rendered_resolution_scaling_factor: float = 1.0,
|
||||
disable_distortion: bool = False,
|
||||
return_rgba_images: bool = False,
|
||||
) -> Tuple[List[np.ndarray], List[np.ndarray]]:
|
||||
"""Helper function to create a video of a trajectory.
|
||||
|
||||
@@ -223,6 +243,7 @@ def render_trajectory(
|
||||
depth_output_name: Name of the depth output.
|
||||
rendered_resolution_scaling_factor: Scaling factor to apply to the camera image resolution.
|
||||
disable_distortion: Whether to disable distortion.
|
||||
return_rgba_images: Whether to return RGBA images (default RGB).
|
||||
|
||||
Returns:
|
||||
List of rgb images, list of depth images.
|
||||
@@ -255,7 +276,11 @@ def render_trajectory(
|
||||
CONSOLE.print(f"Could not find {depth_output_name} in the model outputs", justify="center")
|
||||
CONSOLE.print(f"Please set --depth_output_name to one of: {outputs.keys()}", justify="center")
|
||||
sys.exit(1)
|
||||
images.append(outputs[rgb_output_name].cpu().numpy())
|
||||
if return_rgba_images:
|
||||
image = pipeline.model.get_rgba_image(outputs, rgb_output_name)
|
||||
else:
|
||||
image = outputs[rgb_output_name]
|
||||
images.append(image.cpu().numpy())
|
||||
depths.append(outputs[depth_output_name].cpu().numpy())
|
||||
return images, depths
|
||||
|
||||
|
||||
@@ -403,9 +403,11 @@ def export_textured_mesh(
|
||||
CONSOLE.print("Creating texture image by rendering with NeRF...")
|
||||
with torch.no_grad():
|
||||
outputs = pipeline.model.get_outputs_for_camera_ray_bundle(camera_ray_bundle)
|
||||
# TODO: this can be done better by using the alpha channel
|
||||
rgb = pipeline.model.get_rgba_image(outputs, "rgb")[..., :3]
|
||||
|
||||
# save the texture image
|
||||
texture_image = outputs["rgb"].cpu().numpy()
|
||||
texture_image = rgb.cpu().numpy()
|
||||
media.write_image(str(output_dir / "material_0.png"), texture_image)
|
||||
|
||||
CONSOLE.print("Writing relevant OBJ information to files...")
|
||||
|
||||
@@ -331,8 +331,12 @@ def export_tsdf_mesh(
|
||||
depth_output_name=depth_output_name,
|
||||
rendered_resolution_scaling_factor=1.0 / downscale_factor,
|
||||
disable_distortion=True,
|
||||
return_rgba_images=True,
|
||||
)
|
||||
|
||||
# TODO: this can be done better by removing transparent points from the TSDF
|
||||
color_images = [x[..., :3] for x in color_images]
|
||||
|
||||
# camera extrinsics and intrinsics
|
||||
c2w: Float[Tensor, "N 3 4"] = cameras.camera_to_worlds.to(device)
|
||||
# make c2w homogeneous
|
||||
|
||||
@@ -208,7 +208,12 @@ class RFFEncoding(Encoding):
|
||||
self.include_input = include_input
|
||||
|
||||
def get_out_dim(self) -> int:
|
||||
return self.num_frequencies * 2
|
||||
out_dim = self.num_frequencies * 2
|
||||
if self.include_input:
|
||||
if self.in_dim is None:
|
||||
raise ValueError("Input dimension has not been set")
|
||||
out_dim += self.in_dim
|
||||
return out_dim
|
||||
|
||||
def forward(
|
||||
self,
|
||||
@@ -264,7 +269,7 @@ class HashEncoding(Encoding):
|
||||
log2_hashmap_size: int = 19,
|
||||
features_per_level: int = 2,
|
||||
hash_init_scale: float = 0.001,
|
||||
implementation: Literal["tcnn", "torch"] = "torch",
|
||||
implementation: Literal["tcnn", "torch"] = "tcnn",
|
||||
interpolation: Optional[Literal["Nearest", "Linear", "Smoothstep"]] = None,
|
||||
) -> None:
|
||||
super().__init__(in_dim=3)
|
||||
@@ -274,18 +279,18 @@ class HashEncoding(Encoding):
|
||||
self.hash_table_size = 2**log2_hashmap_size
|
||||
|
||||
levels = torch.arange(num_levels)
|
||||
growth_factor = np.exp((np.log(max_res) - np.log(min_res)) / (num_levels - 1))
|
||||
growth_factor = np.exp((np.log(max_res) - np.log(min_res)) / (num_levels - 1)) if num_levels > 1 else 1
|
||||
self.scalings = torch.floor(min_res * growth_factor**levels)
|
||||
|
||||
self.hash_offset = levels * self.hash_table_size
|
||||
self.hash_table = torch.rand(size=(self.hash_table_size * num_levels, features_per_level)) * 2 - 1
|
||||
self.hash_table *= hash_init_scale
|
||||
self.hash_table = nn.Parameter(self.hash_table)
|
||||
|
||||
self.tcnn_encoding = None
|
||||
self.hash_table = torch.empty(0)
|
||||
if implementation == "tcnn" and not TCNN_EXISTS:
|
||||
print_tcnn_speed_warning("HashEncoding")
|
||||
elif implementation == "tcnn":
|
||||
implementation = "torch"
|
||||
|
||||
if implementation == "tcnn":
|
||||
encoding_config = {
|
||||
"otype": "HashGrid",
|
||||
"n_levels": self.num_levels,
|
||||
@@ -301,6 +306,10 @@ class HashEncoding(Encoding):
|
||||
n_input_dims=3,
|
||||
encoding_config=encoding_config,
|
||||
)
|
||||
elif implementation == "torch":
|
||||
self.hash_table = torch.rand(size=(self.hash_table_size * num_levels, features_per_level)) * 2 - 1
|
||||
self.hash_table *= hash_init_scale
|
||||
self.hash_table = nn.Parameter(self.hash_table)
|
||||
|
||||
if self.tcnn_encoding is None:
|
||||
assert (
|
||||
|
||||
@@ -102,6 +102,7 @@ class MLP(FieldComponent):
|
||||
self.build_nn_modules()
|
||||
elif implementation == "tcnn" and not TCNN_EXISTS:
|
||||
print_tcnn_speed_warning("MLP")
|
||||
self.build_nn_modules()
|
||||
elif implementation == "tcnn":
|
||||
activation_str = activation_to_tcnn_string(activation)
|
||||
output_activation_str = activation_to_tcnn_string(out_activation)
|
||||
|
||||
@@ -133,8 +133,8 @@ class Field(nn.Module):
|
||||
return field_outputs
|
||||
|
||||
|
||||
def shift_directions_for_tcnn(directions: Float[Tensor, "*bs 3"]) -> Float[Tensor, "*bs 3"]:
|
||||
"""Shift directions from [-1, 1] to [0, 1]
|
||||
def get_normalized_directions(directions: Float[Tensor, "*bs 3"]) -> Float[Tensor, "*bs 3"]:
|
||||
"""SH encoding must be in the range [0, 1]
|
||||
|
||||
Args:
|
||||
directions: batch of directions
|
||||
|
||||
@@ -56,7 +56,7 @@ class HashMLPDensityField(Field):
|
||||
base_res: int = 16,
|
||||
log2_hashmap_size: int = 18,
|
||||
features_per_level: int = 2,
|
||||
implementation: Literal["tcnn", "torch"] = "torch",
|
||||
implementation: Literal["tcnn", "torch"] = "tcnn",
|
||||
) -> None:
|
||||
super().__init__()
|
||||
self.register_buffer("aabb", aabb)
|
||||
|
||||
@@ -17,30 +17,20 @@ Field for Generfacto model
|
||||
"""
|
||||
|
||||
|
||||
from typing import Optional, Tuple, Dict, Literal
|
||||
from typing import Dict, Literal, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch.nn.parameter import Parameter
|
||||
from jaxtyping import Float
|
||||
from torch import Tensor, nn
|
||||
from torch.nn.parameter import Parameter
|
||||
|
||||
from nerfstudio.field_components.mlp import MLP
|
||||
from nerfstudio.cameras.rays import RayBundle, RaySamples
|
||||
from nerfstudio.data.scene_box import SceneBox
|
||||
from nerfstudio.field_components.activations import trunc_exp
|
||||
from nerfstudio.field_components.field_heads import FieldHeadNames
|
||||
from nerfstudio.field_components.encodings import HashEncoding, SHEncoding
|
||||
from nerfstudio.fields.base_field import Field
|
||||
|
||||
|
||||
def get_normalized_directions(directions: Float[Tensor, "bs 3"]):
|
||||
"""SH encoding must be in the range [0, 1]
|
||||
|
||||
Args:
|
||||
directions: batch of directions
|
||||
"""
|
||||
return (directions + 1.0) / 2.0
|
||||
from nerfstudio.field_components.field_heads import FieldHeadNames
|
||||
from nerfstudio.field_components.mlp import MLP
|
||||
from nerfstudio.fields.base_field import Field, get_normalized_directions
|
||||
|
||||
|
||||
class GenerfactoField(Field):
|
||||
|
||||
@@ -1,198 +0,0 @@
|
||||
# Copyright 2022 the Regents of the University of California, Nerfstudio Team and contributors. All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
"""
|
||||
Instant-NGP field implementations using tiny-cuda-nn, torch, ....
|
||||
"""
|
||||
|
||||
|
||||
from typing import Dict, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from jaxtyping import Float
|
||||
from torch import Tensor
|
||||
from torch.nn.parameter import Parameter
|
||||
|
||||
from nerfstudio.cameras.rays import RaySamples
|
||||
from nerfstudio.data.scene_box import SceneBox
|
||||
from nerfstudio.field_components.activations import trunc_exp
|
||||
from nerfstudio.field_components.embedding import Embedding
|
||||
from nerfstudio.field_components.field_heads import FieldHeadNames
|
||||
from nerfstudio.field_components.spatial_distortions import (
|
||||
SceneContraction,
|
||||
SpatialDistortion,
|
||||
)
|
||||
from nerfstudio.fields.base_field import Field, shift_directions_for_tcnn
|
||||
|
||||
try:
|
||||
import tinycudann as tcnn
|
||||
except ModuleNotFoundError:
|
||||
# tinycudann module doesn't exist
|
||||
pass
|
||||
|
||||
|
||||
class TCNNInstantNGPField(Field):
|
||||
"""TCNN implementation of the Instant-NGP field.
|
||||
|
||||
Args:
|
||||
aabb: parameters of scene aabb bounds
|
||||
num_layers: number of hidden layers
|
||||
hidden_dim: dimension of hidden layers
|
||||
geo_feat_dim: output geo feat dimensions
|
||||
num_layers_color: number of hidden layers for color network
|
||||
hidden_dim_color: dimension of hidden layers for color network
|
||||
use_appearance_embedding: whether to use appearance embedding
|
||||
num_images: number of images, required if use_appearance_embedding is True
|
||||
appearance_embedding_dim: dimension of appearance embedding
|
||||
contraction_type: type of contraction
|
||||
num_levels: number of levels of the hashmap for the base mlp
|
||||
log2_hashmap_size: size of the hashmap for the base mlp
|
||||
max_res: maximum resolution of the hashmap for the base mlp
|
||||
mode: which implementation to use for the field
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
aabb: Tensor,
|
||||
num_layers: int = 2,
|
||||
hidden_dim: int = 64,
|
||||
geo_feat_dim: int = 15,
|
||||
num_layers_color: int = 3,
|
||||
hidden_dim_color: int = 64,
|
||||
use_appearance_embedding: Optional[bool] = False,
|
||||
num_images: Optional[int] = None,
|
||||
appearance_embedding_dim: int = 32,
|
||||
num_levels: int = 16,
|
||||
log2_hashmap_size: int = 19,
|
||||
max_res: int = 2048,
|
||||
spatial_distortion: Optional[SpatialDistortion] = SceneContraction(),
|
||||
) -> None:
|
||||
super().__init__()
|
||||
|
||||
self.aabb = Parameter(aabb, requires_grad=False)
|
||||
self.geo_feat_dim = geo_feat_dim
|
||||
self.spatial_distortion = spatial_distortion
|
||||
|
||||
self.use_appearance_embedding = use_appearance_embedding
|
||||
if use_appearance_embedding:
|
||||
assert num_images is not None
|
||||
self.appearance_embedding_dim = appearance_embedding_dim
|
||||
self.appearance_embedding = Embedding(num_images, appearance_embedding_dim)
|
||||
|
||||
# TODO: set this properly based on the aabb
|
||||
base_res: int = 16
|
||||
features_per_level: int = 2
|
||||
growth_factor = np.exp((np.log(max_res) - np.log(base_res)) / (num_levels - 1))
|
||||
|
||||
self.direction_encoding = tcnn.Encoding(
|
||||
n_input_dims=3,
|
||||
encoding_config={
|
||||
"otype": "SphericalHarmonics",
|
||||
"degree": 4,
|
||||
},
|
||||
)
|
||||
|
||||
self.mlp_base = tcnn.NetworkWithInputEncoding(
|
||||
n_input_dims=3,
|
||||
n_output_dims=1 + self.geo_feat_dim,
|
||||
encoding_config={
|
||||
"otype": "HashGrid",
|
||||
"n_levels": num_levels,
|
||||
"n_features_per_level": features_per_level,
|
||||
"log2_hashmap_size": log2_hashmap_size,
|
||||
"base_resolution": base_res,
|
||||
"per_level_scale": growth_factor,
|
||||
},
|
||||
network_config={
|
||||
"otype": "FullyFusedMLP",
|
||||
"activation": "ReLU",
|
||||
"output_activation": "None",
|
||||
"n_neurons": hidden_dim,
|
||||
"n_hidden_layers": num_layers - 1,
|
||||
},
|
||||
)
|
||||
|
||||
in_dim = self.direction_encoding.n_output_dims + self.geo_feat_dim
|
||||
if self.use_appearance_embedding:
|
||||
in_dim += self.appearance_embedding_dim
|
||||
self.mlp_head = tcnn.Network(
|
||||
n_input_dims=in_dim,
|
||||
n_output_dims=3,
|
||||
network_config={
|
||||
"otype": "FullyFusedMLP",
|
||||
"activation": "ReLU",
|
||||
"output_activation": "Sigmoid",
|
||||
"n_neurons": hidden_dim_color,
|
||||
"n_hidden_layers": num_layers_color - 1,
|
||||
},
|
||||
)
|
||||
|
||||
def get_density(self, ray_samples: RaySamples) -> Tuple[Tensor, Tensor]:
|
||||
if self.spatial_distortion is not None:
|
||||
positions = ray_samples.frustums.get_positions()
|
||||
positions = self.spatial_distortion(positions)
|
||||
positions = (positions + 2.0) / 4.0
|
||||
else:
|
||||
positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
|
||||
# Make sure the tcnn gets inputs between 0 and 1.
|
||||
selector = ((positions > 0.0) & (positions < 1.0)).all(dim=-1)
|
||||
positions = positions * selector[..., None]
|
||||
positions_flat = positions.view(-1, 3)
|
||||
|
||||
h = self.mlp_base(positions_flat).view(*ray_samples.frustums.shape, -1)
|
||||
density_before_activation, base_mlp_out = torch.split(h, [1, self.geo_feat_dim], dim=-1)
|
||||
|
||||
# Rectifying the density with an exponential is much more stable than a ReLU or
|
||||
# softplus, because it enables high post-activation (float32) density outputs
|
||||
# from smaller internal (float16) parameters.
|
||||
density = trunc_exp(density_before_activation.to(positions))
|
||||
density = density * selector[..., None]
|
||||
return density, base_mlp_out
|
||||
|
||||
def get_outputs(
|
||||
self, ray_samples: RaySamples, density_embedding: Optional[Tensor] = None
|
||||
) -> Dict[FieldHeadNames, Tensor]:
|
||||
assert density_embedding is not None
|
||||
directions = shift_directions_for_tcnn(ray_samples.frustums.directions)
|
||||
directions_flat = directions.view(-1, 3)
|
||||
d = self.direction_encoding(directions_flat)
|
||||
|
||||
h = torch.cat([d, density_embedding.view(-1, self.geo_feat_dim)], dim=-1)
|
||||
|
||||
if self.use_appearance_embedding:
|
||||
if ray_samples.camera_indices is None:
|
||||
raise AttributeError("Camera indices are not provided.")
|
||||
camera_indices = ray_samples.camera_indices.squeeze()
|
||||
if self.training:
|
||||
embedded_appearance = self.appearance_embedding(camera_indices)
|
||||
else:
|
||||
embedded_appearance = torch.zeros(
|
||||
(*directions.shape[:-1], self.appearance_embedding_dim), device=directions.device
|
||||
)
|
||||
h = torch.cat([h, embedded_appearance.view(-1, self.appearance_embedding_dim)], dim=-1)
|
||||
|
||||
rgb = self.mlp_head(h).view(*ray_samples.frustums.directions.shape[:-1], -1).to(directions)
|
||||
return {FieldHeadNames.RGB: rgb}
|
||||
|
||||
def get_opacity(self, positions: Float[Tensor, "*bs 3"], step_size) -> Float[Tensor, "*bs 1"]:
|
||||
"""Returns the opacity for a position. Used primarily by the occupancy grid.
|
||||
|
||||
Args:
|
||||
positions: the positions to evaluate the opacity at.
|
||||
step_size: the step size to use for the opacity evaluation.
|
||||
"""
|
||||
density = self.density_fn(positions)
|
||||
opacity = density * step_size
|
||||
return opacity
|
||||
@@ -37,7 +37,7 @@ from nerfstudio.field_components.field_heads import (
|
||||
)
|
||||
from nerfstudio.field_components.mlp import MLP
|
||||
from nerfstudio.field_components.spatial_distortions import SpatialDistortion
|
||||
from nerfstudio.fields.base_field import Field, shift_directions_for_tcnn
|
||||
from nerfstudio.fields.base_field import Field, get_normalized_directions
|
||||
|
||||
|
||||
class NerfactoField(Field):
|
||||
@@ -50,10 +50,12 @@ class NerfactoField(Field):
|
||||
hidden_dim: dimension of hidden layers
|
||||
geo_feat_dim: output geo feat dimensions
|
||||
num_levels: number of levels of the hashmap for the base mlp
|
||||
base_res: base resolution of the hashmap for the base mlp
|
||||
max_res: maximum resolution of the hashmap for the base mlp
|
||||
log2_hashmap_size: size of the hashmap for the base mlp
|
||||
num_layers_color: number of hidden layers for color network
|
||||
num_layers_transient: number of hidden layers for transient network
|
||||
features_per_level: number of features per level for the hashgrid
|
||||
hidden_dim_color: dimension of hidden layers for color network
|
||||
hidden_dim_transient: dimension of hidden layers for transient network
|
||||
appearance_embedding_dim: dimension of appearance embedding
|
||||
@@ -232,7 +234,7 @@ class NerfactoField(Field):
|
||||
if ray_samples.camera_indices is None:
|
||||
raise AttributeError("Camera indices are not provided.")
|
||||
camera_indices = ray_samples.camera_indices.squeeze()
|
||||
directions = shift_directions_for_tcnn(ray_samples.frustums.directions)
|
||||
directions = get_normalized_directions(ray_samples.frustums.directions)
|
||||
directions_flat = directions.view(-1, 3)
|
||||
d = self.direction_encoding(directions_flat)
|
||||
|
||||
|
||||
@@ -123,11 +123,11 @@ class VanillaNerfWField(Field):
|
||||
"""Returns the outputs of the NeRF-W field.
|
||||
|
||||
Args:
|
||||
ray_samples (RaySamples): Ray samples.
|
||||
density_embedding (Float[Tensor, "*batch embedding_size"], optional): Density embedding.
|
||||
ray_samples: Ray samples.
|
||||
density_embedding: Density embedding.
|
||||
|
||||
Returns:
|
||||
Dict[FieldHeadNames, Tensor]: Outputs of the NeRF-W field.
|
||||
Outputs of the NeRF-W field.
|
||||
"""
|
||||
outputs = {}
|
||||
encoded_dir = self.direction_encoding(ray_samples.frustums.directions)
|
||||
|
||||
@@ -97,19 +97,19 @@ class SDFFieldConfig(FieldConfig):
|
||||
beta_init: float = 0.1
|
||||
"""Init learnable beta value for transformation of sdf to density"""
|
||||
encoding_type: Literal["hash", "periodic", "tensorf_vm"] = "hash"
|
||||
num_levels = 16
|
||||
num_levels: int = 16
|
||||
"""Number of encoding levels"""
|
||||
max_res = 2048
|
||||
max_res: int = 2048
|
||||
"""Maximum resolution of the encoding"""
|
||||
base_res = 16
|
||||
base_res: int = 16
|
||||
"""Base resolution of the encoding"""
|
||||
log2_hashmap_size = 19
|
||||
log2_hashmap_size: int = 19
|
||||
"""Size of the hash map"""
|
||||
features_per_level = 2
|
||||
features_per_level: int = 2
|
||||
"""Number of features per encoding level"""
|
||||
use_hash = True
|
||||
use_hash: bool = True
|
||||
"""Whether to use hash encoding"""
|
||||
smoothstep = True
|
||||
smoothstep: bool = True
|
||||
"""Whether to use the smoothstep function"""
|
||||
|
||||
|
||||
|
||||
@@ -98,14 +98,14 @@ class TensoRFField(Field):
|
||||
rgb_features = self.color_encoding(positions)
|
||||
rgb_features = self.B(rgb_features)
|
||||
|
||||
d_encoded = self.direction_encoding(d)
|
||||
rgb_features_encoded = self.feature_encoding(rgb_features)
|
||||
|
||||
if self.use_sh:
|
||||
sh_mult = self.sh(d)[:, :, None]
|
||||
rgb_sh = rgb_features.view(sh_mult.shape[0], sh_mult.shape[1], 3, sh_mult.shape[-1])
|
||||
rgb = torch.relu(torch.sum(sh_mult * rgb_sh, dim=-1) + 0.5)
|
||||
else:
|
||||
d_encoded = self.direction_encoding(d)
|
||||
rgb_features_encoded = self.feature_encoding(rgb_features)
|
||||
|
||||
out = self.mlp_head(torch.cat([rgb_features, d, rgb_features_encoded, d_encoded], dim=-1)) # type: ignore
|
||||
rgb = self.field_output_rgb(out)
|
||||
|
||||
|
||||
@@ -15,7 +15,7 @@
|
||||
"""Classic NeRF field"""
|
||||
|
||||
|
||||
from typing import Dict, Optional, Tuple
|
||||
from typing import Dict, Optional, Tuple, Type
|
||||
|
||||
import torch
|
||||
from torch import Tensor, nn
|
||||
@@ -57,7 +57,7 @@ class NeRFField(Field):
|
||||
head_mlp_num_layers: int = 2,
|
||||
head_mlp_layer_width: int = 128,
|
||||
skip_connections: Tuple[int] = (4,),
|
||||
field_heads: Optional[Tuple[FieldHead]] = (RGBFieldHead(),),
|
||||
field_heads: Optional[Tuple[Type[FieldHead]]] = (RGBFieldHead,),
|
||||
use_integrated_encoding: bool = False,
|
||||
spatial_distortion: Optional[SpatialDistortion] = None,
|
||||
) -> None:
|
||||
@@ -83,7 +83,7 @@ class NeRFField(Field):
|
||||
)
|
||||
|
||||
self.field_output_density = DensityFieldHead(in_dim=self.mlp_base.get_out_dim())
|
||||
self.field_heads = nn.ModuleList(field_heads)
|
||||
self.field_heads = nn.ModuleList([field_head() for field_head in field_heads] if field_heads else []) # type: ignore
|
||||
for field_head in self.field_heads:
|
||||
field_head.set_in_dim(self.mlp_head.get_out_dim()) # type: ignore
|
||||
|
||||
|
||||
@@ -505,14 +505,13 @@ class VolumetricSampler(Sampler):
|
||||
if camera_indices is not None:
|
||||
camera_indices = camera_indices[ray_indices]
|
||||
|
||||
zeros = torch.zeros_like(origins[:, :1])
|
||||
ray_samples = RaySamples(
|
||||
frustums=Frustums(
|
||||
origins=origins,
|
||||
directions=dirs,
|
||||
starts=starts[..., None],
|
||||
ends=ends[..., None],
|
||||
pixel_area=zeros,
|
||||
pixel_area=ray_bundle[ray_indices].pixel_area,
|
||||
),
|
||||
camera_indices=camera_indices,
|
||||
)
|
||||
|
||||
@@ -28,7 +28,7 @@ Example:
|
||||
"""
|
||||
import contextlib
|
||||
import math
|
||||
from typing import Generator, Literal, Optional, Union
|
||||
from typing import Generator, Literal, Optional, Tuple, Union
|
||||
|
||||
import nerfacc
|
||||
import torch
|
||||
@@ -39,7 +39,7 @@ from nerfstudio.cameras.rays import RaySamples
|
||||
from nerfstudio.utils import colors
|
||||
from nerfstudio.utils.math import components_from_spherical_harmonics, safe_normalize
|
||||
|
||||
BackgroundColor = Union[Literal["random", "last_sample", "black", "white"], Float[Tensor, "3"]]
|
||||
BackgroundColor = Union[Literal["random", "last_sample", "black", "white"], Float[Tensor, "3"], Float[Tensor, "*bs 3"]]
|
||||
BACKGROUND_COLOR_OVERRIDE: Optional[Float[Tensor, "3"]] = None
|
||||
|
||||
|
||||
@@ -75,7 +75,8 @@ class RGBRenderer(nn.Module):
|
||||
ray_indices: Optional[Int[Tensor, "num_samples"]] = None,
|
||||
num_rays: Optional[int] = None,
|
||||
) -> Float[Tensor, "*bs 3"]:
|
||||
"""Composite samples along ray and render color image
|
||||
"""Composite samples along ray and render color image.
|
||||
If background color is random, no BG color is added - as if the background was black!
|
||||
|
||||
Args:
|
||||
rgb: RGB for each sample
|
||||
@@ -101,19 +102,99 @@ class RGBRenderer(nn.Module):
|
||||
comp_rgb = torch.sum(weights * rgb, dim=-2)
|
||||
accumulated_weight = torch.sum(weights, dim=-2)
|
||||
|
||||
if background_color == "random":
|
||||
# If background color is random, the predicted color is returned without blending,
|
||||
# as if the background color was black.
|
||||
return comp_rgb
|
||||
|
||||
elif background_color == "last_sample":
|
||||
# Note, this is only supported for non-packed samples.
|
||||
background_color = rgb[..., -1, :]
|
||||
else:
|
||||
background_color = cls.get_background_color(background_color, shape=comp_rgb.shape, device=comp_rgb.device)
|
||||
assert isinstance(background_color, torch.Tensor)
|
||||
comp_rgb = comp_rgb + background_color * (1.0 - accumulated_weight)
|
||||
return comp_rgb
|
||||
|
||||
@classmethod
|
||||
def get_background_color(
|
||||
cls, background_color: BackgroundColor, shape: Tuple[int, ...], device: torch.device
|
||||
) -> Union[Float[Tensor, "3"], Float[Tensor, "*bs 3"]]:
|
||||
"""Returns the RGB background color for a specified background color.
|
||||
|
||||
Note:
|
||||
This function CANNOT be called for background_color being either "last_sample" or "random".
|
||||
|
||||
Args:
|
||||
rgb: RGB for each sample.
|
||||
background_color: The background color specification.
|
||||
|
||||
Returns:
|
||||
Background color as RGB.
|
||||
"""
|
||||
assert background_color not in {"last_sample", "random"}
|
||||
assert shape[-1] == 3, "Background color must be RGB."
|
||||
if BACKGROUND_COLOR_OVERRIDE is not None:
|
||||
background_color = BACKGROUND_COLOR_OVERRIDE
|
||||
if background_color == "last_sample":
|
||||
background_color = rgb[..., -1, :]
|
||||
if background_color == "random":
|
||||
background_color = torch.rand_like(comp_rgb).to(rgb.device)
|
||||
if isinstance(background_color, str) and background_color in colors.COLORS_DICT:
|
||||
background_color = colors.COLORS_DICT[background_color].to(rgb.device)
|
||||
background_color = colors.COLORS_DICT[background_color]
|
||||
assert isinstance(background_color, Tensor)
|
||||
|
||||
# Ensure correct shape
|
||||
return background_color.expand(shape).to(device)
|
||||
|
||||
def blend_background(
|
||||
self,
|
||||
image: Tensor,
|
||||
background_color: Optional[BackgroundColor] = None,
|
||||
) -> Float[Tensor, "*bs 3"]:
|
||||
"""Blends the background color into the image if image is RGBA.
|
||||
Otherwise no blending is performed (we assume opacity of 1).
|
||||
|
||||
Args:
|
||||
image: RGB/RGBA per pixel.
|
||||
opacity: Alpha opacity per pixel.
|
||||
background_color: Background color.
|
||||
|
||||
Returns:
|
||||
Blended RGB.
|
||||
"""
|
||||
if image.size(-1) < 4:
|
||||
return image
|
||||
|
||||
rgb, opacity = image[..., :3], image[..., 3:]
|
||||
if background_color is None:
|
||||
background_color = self.background_color
|
||||
if background_color in {"last_sample", "random"}:
|
||||
background_color = "black"
|
||||
background_color = self.get_background_color(background_color, shape=rgb.shape, device=rgb.device)
|
||||
assert isinstance(background_color, torch.Tensor)
|
||||
comp_rgb = comp_rgb + background_color.to(weights.device) * (1.0 - accumulated_weight)
|
||||
return rgb * opacity + background_color.to(rgb.device) * (1 - opacity)
|
||||
|
||||
return comp_rgb
|
||||
def blend_background_for_loss_computation(
|
||||
self,
|
||||
pred_image: Tensor,
|
||||
pred_accumulation: Tensor,
|
||||
gt_image: Tensor,
|
||||
) -> Tuple[Tensor, Tensor]:
|
||||
"""Blends a background color into the ground truth and predicted image for
|
||||
loss computation.
|
||||
|
||||
Args:
|
||||
gt_image: The ground truth image.
|
||||
pred_image: The predicted RGB values (without background blending).
|
||||
pred_accumulation: The predicted opacity/ accumulation.
|
||||
Returns:
|
||||
A tuple of the predicted and ground truth RGB values.
|
||||
"""
|
||||
background_color = self.background_color
|
||||
if background_color == "last_sample":
|
||||
background_color = "black" # No background blending for GT
|
||||
elif background_color == "random":
|
||||
background_color = torch.rand_like(pred_image)
|
||||
pred_image = pred_image + background_color * (1.0 - pred_accumulation)
|
||||
gt_image = self.blend_background(gt_image, background_color=background_color)
|
||||
return pred_image, gt_image
|
||||
|
||||
def forward(
|
||||
self,
|
||||
@@ -121,6 +202,7 @@ class RGBRenderer(nn.Module):
|
||||
weights: Float[Tensor, "*bs num_samples 1"],
|
||||
ray_indices: Optional[Int[Tensor, "num_samples"]] = None,
|
||||
num_rays: Optional[int] = None,
|
||||
background_color: Optional[BackgroundColor] = None,
|
||||
) -> Float[Tensor, "*bs 3"]:
|
||||
"""Composite samples along ray and render color image
|
||||
|
||||
@@ -129,15 +211,18 @@ class RGBRenderer(nn.Module):
|
||||
weights: Weights for each sample
|
||||
ray_indices: Ray index for each sample, used when samples are packed.
|
||||
num_rays: Number of rays, used when samples are packed.
|
||||
background_color: The background color to use for rendering.
|
||||
|
||||
Returns:
|
||||
Outputs of rgb values.
|
||||
"""
|
||||
if background_color is None:
|
||||
background_color = self.background_color
|
||||
|
||||
if not self.training:
|
||||
rgb = torch.nan_to_num(rgb)
|
||||
rgb = self.combine_rgb(
|
||||
rgb, weights, background_color=self.background_color, ray_indices=ray_indices, num_rays=num_rays
|
||||
rgb, weights, background_color=background_color, ray_indices=ray_indices, num_rays=num_rays
|
||||
)
|
||||
if not self.training:
|
||||
torch.clamp_(rgb, min=0.0, max=1.0)
|
||||
@@ -325,10 +410,17 @@ class SemanticRenderer(nn.Module):
|
||||
cls,
|
||||
semantics: Float[Tensor, "*bs num_samples num_classes"],
|
||||
weights: Float[Tensor, "*bs num_samples 1"],
|
||||
ray_indices: Optional[Int[Tensor, "num_samples"]] = None,
|
||||
num_rays: Optional[int] = None,
|
||||
) -> Float[Tensor, "*bs num_classes"]:
|
||||
"""Calculate semantics along the ray."""
|
||||
sem = torch.sum(weights * semantics, dim=-2)
|
||||
return sem
|
||||
if ray_indices is not None and num_rays is not None:
|
||||
# Necessary for packed samples from volumetric ray sampler
|
||||
return nerfacc.accumulate_along_rays(
|
||||
weights[..., 0], values=semantics, ray_indices=ray_indices, n_rays=num_rays
|
||||
)
|
||||
else:
|
||||
return torch.sum(weights * semantics, dim=-2)
|
||||
|
||||
|
||||
class NormalsRenderer(nn.Module):
|
||||
|
||||
@@ -187,6 +187,30 @@ class Model(nn.Module):
|
||||
outputs[output_name] = torch.cat(outputs_list).view(image_height, image_width, -1) # type: ignore
|
||||
return outputs
|
||||
|
||||
def get_rgba_image(self, outputs: Dict[str, torch.Tensor], output_name: str = "rgb") -> torch.Tensor:
|
||||
"""Returns the RGBA image from the outputs of the model.
|
||||
|
||||
Args:
|
||||
outputs: Outputs of the model.
|
||||
|
||||
Returns:
|
||||
RGBA image.
|
||||
"""
|
||||
accumulation_name = output_name.replace("rgb", "accumulation")
|
||||
if (
|
||||
not hasattr(self, "renderer_rgb")
|
||||
or not hasattr(self.renderer_rgb, "background_color")
|
||||
or accumulation_name not in outputs
|
||||
):
|
||||
raise NotImplementedError(f"get_rgba_image is not implemented for model {self.__class__.__name__}")
|
||||
rgb = outputs[output_name]
|
||||
if self.renderer_rgb.background_color == "random": # type: ignore
|
||||
acc = outputs[accumulation_name]
|
||||
if acc.dim() < rgb.dim():
|
||||
acc = acc.unsqueeze(-1)
|
||||
return torch.cat((rgb / acc.clamp(min=1e-10), acc), dim=-1)
|
||||
return torch.cat((rgb, torch.ones_like(rgb[..., :1])), dim=-1)
|
||||
|
||||
@abstractmethod
|
||||
def get_image_metrics_and_images(
|
||||
self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
|
||||
|
||||
@@ -25,8 +25,8 @@ from typing import Any, Dict, List, Literal, Tuple, Type, cast
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from torch.nn import Parameter
|
||||
from torchmetrics import PeakSignalNoiseRatio
|
||||
from torchmetrics.functional import structural_similarity_index_measure
|
||||
from torchmetrics.image import PeakSignalNoiseRatio
|
||||
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
|
||||
|
||||
from nerfstudio.cameras.rays import RayBundle
|
||||
@@ -293,7 +293,12 @@ class SurfaceModel(Model):
|
||||
"""
|
||||
loss_dict = {}
|
||||
image = batch["image"].to(self.device)
|
||||
loss_dict["rgb_loss"] = self.rgb_loss(image, outputs["rgb"])
|
||||
pred_image, image = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb"],
|
||||
pred_accumulation=outputs["accumulation"],
|
||||
gt_image=image,
|
||||
)
|
||||
loss_dict["rgb_loss"] = self.rgb_loss(image, pred_image)
|
||||
if self.training:
|
||||
# eikonal loss
|
||||
grad_theta = outputs["eik_grad"]
|
||||
@@ -337,6 +342,7 @@ class SurfaceModel(Model):
|
||||
"""
|
||||
metrics_dict = {}
|
||||
image = batch["image"].to(self.device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
metrics_dict["psnr"] = self.psnr(outputs["rgb"], image)
|
||||
return metrics_dict
|
||||
|
||||
@@ -352,6 +358,7 @@ class SurfaceModel(Model):
|
||||
A dictionary of metrics.
|
||||
"""
|
||||
image = batch["image"].to(self.device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
rgb = outputs["rgb"]
|
||||
acc = colormaps.apply_colormap(outputs["accumulation"])
|
||||
|
||||
|
||||
@@ -24,8 +24,8 @@ from typing import Dict, List, Literal, Optional, Tuple, Type
|
||||
import nerfacc
|
||||
import torch
|
||||
from torch.nn import Parameter
|
||||
from torchmetrics import PeakSignalNoiseRatio
|
||||
from torchmetrics.functional import structural_similarity_index_measure
|
||||
from torchmetrics.image import PeakSignalNoiseRatio
|
||||
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
|
||||
|
||||
from nerfstudio.cameras.rays import RayBundle
|
||||
@@ -110,6 +110,7 @@ class NGPModel(Model):
|
||||
|
||||
self.field = NerfactoField(
|
||||
aabb=self.scene_box.aabb,
|
||||
appearance_embedding_dim=0 if self.config.use_appearance_embedding else 32,
|
||||
num_images=self.num_train_data,
|
||||
log2_hashmap_size=self.config.log2_hashmap_size,
|
||||
max_res=self.config.max_res,
|
||||
@@ -218,14 +219,20 @@ class NGPModel(Model):
|
||||
|
||||
def get_metrics_dict(self, outputs, batch):
|
||||
image = batch["image"].to(self.device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
metrics_dict = {}
|
||||
metrics_dict["psnr"] = self.psnr(outputs["rgb"], image)
|
||||
metrics_dict["num_samples_per_batch"] = outputs["num_samples_per_ray"].sum()
|
||||
return metrics_dict
|
||||
|
||||
def get_loss_dict(self, outputs, batch, metrics_dict=None):
|
||||
image = batch["image"].to(self.device)
|
||||
rgb_loss = self.rgb_loss(image, outputs["rgb"])
|
||||
image = batch["image"][..., :3].to(self.device)
|
||||
pred_rgb, image = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb"],
|
||||
pred_accumulation=outputs["accumulation"],
|
||||
gt_image=image,
|
||||
)
|
||||
rgb_loss = self.rgb_loss(image, pred_rgb)
|
||||
loss_dict = {"rgb_loss": rgb_loss}
|
||||
return loss_dict
|
||||
|
||||
@@ -233,6 +240,7 @@ class NGPModel(Model):
|
||||
self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
|
||||
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
|
||||
image = batch["image"].to(self.device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
rgb = outputs["rgb"]
|
||||
acc = colormaps.apply_colormap(outputs["accumulation"])
|
||||
depth = colormaps.apply_depth_colormap(
|
||||
|
||||
@@ -21,8 +21,8 @@ from typing import Dict, List, Tuple
|
||||
|
||||
import torch
|
||||
from torch.nn import Parameter
|
||||
from torchmetrics import PeakSignalNoiseRatio
|
||||
from torchmetrics.functional import structural_similarity_index_measure
|
||||
from torchmetrics.image import PeakSignalNoiseRatio
|
||||
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
|
||||
|
||||
from nerfstudio.cameras.rays import RayBundle
|
||||
@@ -142,8 +142,18 @@ class MipNerfModel(Model):
|
||||
|
||||
def get_loss_dict(self, outputs, batch, metrics_dict=None):
|
||||
image = batch["image"].to(self.device)
|
||||
rgb_loss_coarse = self.rgb_loss(image, outputs["rgb_coarse"])
|
||||
rgb_loss_fine = self.rgb_loss(image, outputs["rgb_fine"])
|
||||
pred_coarse, image_coarse = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb_coarse"],
|
||||
pred_accumulation=outputs["accumulation_coarse"],
|
||||
gt_image=image,
|
||||
)
|
||||
pred_fine, image_fine = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb_fine"],
|
||||
pred_accumulation=outputs["accumulation_fine"],
|
||||
gt_image=image,
|
||||
)
|
||||
rgb_loss_coarse = self.rgb_loss(image_coarse, pred_coarse)
|
||||
rgb_loss_fine = self.rgb_loss(image_fine, pred_fine)
|
||||
loss_dict = {"rgb_loss_coarse": rgb_loss_coarse, "rgb_loss_fine": rgb_loss_fine}
|
||||
loss_dict = misc.scale_dict(loss_dict, self.config.loss_coefficients)
|
||||
return loss_dict
|
||||
@@ -153,6 +163,7 @@ class MipNerfModel(Model):
|
||||
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
|
||||
assert self.config.collider_params is not None, "mip-NeRF requires collider parameters to be set."
|
||||
image = batch["image"].to(outputs["rgb_coarse"].device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
rgb_coarse = outputs["rgb_coarse"]
|
||||
rgb_fine = outputs["rgb_fine"]
|
||||
acc_coarse = colormaps.apply_colormap(outputs["accumulation_coarse"])
|
||||
|
||||
@@ -24,8 +24,8 @@ from typing import Dict, List, Literal, Tuple, Type
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch.nn import Parameter
|
||||
from torchmetrics import PeakSignalNoiseRatio
|
||||
from torchmetrics.functional import structural_similarity_index_measure
|
||||
from torchmetrics.image import PeakSignalNoiseRatio
|
||||
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
|
||||
|
||||
from nerfstudio.cameras.rays import RayBundle, RaySamples
|
||||
@@ -70,7 +70,7 @@ class NerfactoModelConfig(ModelConfig):
|
||||
num_levels: int = 16
|
||||
"""Number of levels of the hashmap for the base mlp."""
|
||||
base_res: int = 16
|
||||
"""Resolution of the base grid for the hasgrid."""
|
||||
"""Resolution of the base grid for the hashgrid."""
|
||||
max_res: int = 2048
|
||||
"""Maximum resolution of the hashmap for the base mlp."""
|
||||
log2_hashmap_size: int = 19
|
||||
@@ -152,6 +152,8 @@ class NerfactoModel(Model):
|
||||
hidden_dim=self.config.hidden_dim,
|
||||
num_levels=self.config.num_levels,
|
||||
max_res=self.config.max_res,
|
||||
base_res=self.config.base_res,
|
||||
features_per_level=self.config.features_per_level,
|
||||
log2_hashmap_size=self.config.log2_hashmap_size,
|
||||
hidden_dim_color=self.config.hidden_dim_color,
|
||||
hidden_dim_transient=self.config.hidden_dim_transient,
|
||||
@@ -327,8 +329,11 @@ class NerfactoModel(Model):
|
||||
|
||||
def get_metrics_dict(self, outputs, batch):
|
||||
metrics_dict = {}
|
||||
image = batch["image"].to(self.device)
|
||||
metrics_dict["psnr"] = self.psnr(outputs["rgb"], image)
|
||||
gt_rgb = batch["image"].to(self.device) # RGB or RGBA image
|
||||
gt_rgb = self.renderer_rgb.blend_background(gt_rgb) # Blend if RGBA
|
||||
predicted_rgb = outputs["rgb"]
|
||||
metrics_dict["psnr"] = self.psnr(predicted_rgb, gt_rgb)
|
||||
|
||||
if self.training:
|
||||
metrics_dict["distortion"] = distortion_loss(outputs["weights_list"], outputs["ray_samples_list"])
|
||||
return metrics_dict
|
||||
@@ -336,7 +341,13 @@ class NerfactoModel(Model):
|
||||
def get_loss_dict(self, outputs, batch, metrics_dict=None):
|
||||
loss_dict = {}
|
||||
image = batch["image"].to(self.device)
|
||||
loss_dict["rgb_loss"] = self.rgb_loss(image, outputs["rgb"])
|
||||
pred_rgb, gt_rgb = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb"],
|
||||
pred_accumulation=outputs["accumulation"],
|
||||
gt_image=image,
|
||||
)
|
||||
|
||||
loss_dict["rgb_loss"] = self.rgb_loss(gt_rgb, pred_rgb)
|
||||
if self.training:
|
||||
loss_dict["interlevel_loss"] = self.config.interlevel_loss_mult * interlevel_loss(
|
||||
outputs["weights_list"], outputs["ray_samples_list"]
|
||||
@@ -358,25 +369,26 @@ class NerfactoModel(Model):
|
||||
def get_image_metrics_and_images(
|
||||
self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
|
||||
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
|
||||
image = batch["image"].to(self.device)
|
||||
rgb = outputs["rgb"]
|
||||
gt_rgb = batch["image"].to(self.device)
|
||||
predicted_rgb = outputs["rgb"] # Blended with background (black if random background)
|
||||
gt_rgb = self.renderer_rgb.blend_background(gt_rgb)
|
||||
acc = colormaps.apply_colormap(outputs["accumulation"])
|
||||
depth = colormaps.apply_depth_colormap(
|
||||
outputs["depth"],
|
||||
accumulation=outputs["accumulation"],
|
||||
)
|
||||
|
||||
combined_rgb = torch.cat([image, rgb], dim=1)
|
||||
combined_rgb = torch.cat([gt_rgb, predicted_rgb], dim=1)
|
||||
combined_acc = torch.cat([acc], dim=1)
|
||||
combined_depth = torch.cat([depth], dim=1)
|
||||
|
||||
# Switch images from [H, W, C] to [1, C, H, W] for metrics computations
|
||||
image = torch.moveaxis(image, -1, 0)[None, ...]
|
||||
rgb = torch.moveaxis(rgb, -1, 0)[None, ...]
|
||||
gt_rgb = torch.moveaxis(gt_rgb, -1, 0)[None, ...]
|
||||
predicted_rgb = torch.moveaxis(predicted_rgb, -1, 0)[None, ...]
|
||||
|
||||
psnr = self.psnr(image, rgb)
|
||||
ssim = self.ssim(image, rgb)
|
||||
lpips = self.lpips(image, rgb)
|
||||
psnr = self.psnr(gt_rgb, predicted_rgb)
|
||||
ssim = self.ssim(gt_rgb, predicted_rgb)
|
||||
lpips = self.lpips(gt_rgb, predicted_rgb)
|
||||
|
||||
# all of these metrics will be logged as scalars
|
||||
metrics_dict = {"psnr": float(psnr.item()), "ssim": float(ssim)} # type: ignore
|
||||
|
||||
@@ -24,8 +24,8 @@ from typing import Dict, List, Tuple, Type
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch.nn import Parameter
|
||||
from torchmetrics import PeakSignalNoiseRatio
|
||||
from torchmetrics.functional import structural_similarity_index_measure
|
||||
from torchmetrics.image import PeakSignalNoiseRatio
|
||||
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
|
||||
|
||||
from nerfstudio.cameras.rays import RayBundle
|
||||
@@ -230,6 +230,7 @@ class SemanticNerfWModel(Model):
|
||||
def get_metrics_dict(self, outputs, batch):
|
||||
metrics_dict = {}
|
||||
image = batch["image"].to(self.device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
metrics_dict["psnr"] = self.psnr(outputs["rgb"], image)
|
||||
metrics_dict["distortion"] = distortion_loss(outputs["weights_list"], outputs["ray_samples_list"])
|
||||
return metrics_dict
|
||||
@@ -237,6 +238,7 @@ class SemanticNerfWModel(Model):
|
||||
def get_loss_dict(self, outputs, batch, metrics_dict=None):
|
||||
loss_dict = {}
|
||||
image = batch["image"].to(self.device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
loss_dict["interlevel_loss"] = self.config.interlevel_loss_mult * interlevel_loss(
|
||||
outputs["weights_list"], outputs["ray_samples_list"]
|
||||
)
|
||||
@@ -263,6 +265,12 @@ class SemanticNerfWModel(Model):
|
||||
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
|
||||
image = batch["image"].to(self.device)
|
||||
rgb = outputs["rgb"]
|
||||
rgb, image = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=rgb,
|
||||
pred_accumulation=outputs["accumulation"],
|
||||
gt_image=image,
|
||||
)
|
||||
|
||||
rgb = torch.clamp(rgb, min=0, max=1)
|
||||
acc = colormaps.apply_colormap(outputs["accumulation"])
|
||||
depth = colormaps.apply_depth_colormap(
|
||||
|
||||
@@ -24,8 +24,8 @@ from typing import Dict, List, Literal, Tuple, Type, cast
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch.nn import Parameter
|
||||
from torchmetrics import PeakSignalNoiseRatio
|
||||
from torchmetrics.functional import structural_similarity_index_measure
|
||||
from torchmetrics.image import PeakSignalNoiseRatio
|
||||
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
|
||||
|
||||
from nerfstudio.cameras.rays import RayBundle
|
||||
@@ -303,9 +303,14 @@ class TensoRFModel(Model):
|
||||
def get_loss_dict(self, outputs, batch, metrics_dict=None) -> Dict[str, torch.Tensor]:
|
||||
# Scaling metrics by coefficients to create the losses.
|
||||
device = outputs["rgb"].device
|
||||
image = batch["image"].to(device)
|
||||
image = batch["image"][..., :3].to(device)
|
||||
pred_image, image = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb"],
|
||||
pred_accumulation=outputs["accumulation"],
|
||||
gt_image=image,
|
||||
)
|
||||
|
||||
rgb_loss = self.rgb_loss(image, outputs["rgb"])
|
||||
rgb_loss = self.rgb_loss(image, pred_image)
|
||||
|
||||
loss_dict = {"rgb_loss": rgb_loss}
|
||||
|
||||
@@ -334,6 +339,7 @@ class TensoRFModel(Model):
|
||||
self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
|
||||
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
|
||||
image = batch["image"].to(outputs["rgb"].device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
rgb = outputs["rgb"]
|
||||
acc = colormaps.apply_colormap(outputs["accumulation"])
|
||||
assert self.config.collider_params is not None
|
||||
|
||||
@@ -23,8 +23,8 @@ from typing import Any, Dict, List, Tuple, Type
|
||||
|
||||
import torch
|
||||
from torch.nn import Parameter
|
||||
from torchmetrics import PeakSignalNoiseRatio
|
||||
from torchmetrics.functional import structural_similarity_index_measure
|
||||
from torchmetrics.image import PeakSignalNoiseRatio
|
||||
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
|
||||
|
||||
from nerfstudio.cameras.rays import RayBundle
|
||||
@@ -192,9 +192,19 @@ class NeRFModel(Model):
|
||||
# Scaling metrics by coefficients to create the losses.
|
||||
device = outputs["rgb_coarse"].device
|
||||
image = batch["image"].to(device)
|
||||
coarse_pred, coarse_image = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb_coarse"],
|
||||
pred_accumulation=outputs["accumulation_coarse"],
|
||||
gt_image=image,
|
||||
)
|
||||
fine_pred, fine_image = self.renderer_rgb.blend_background_for_loss_computation(
|
||||
pred_image=outputs["rgb_fine"],
|
||||
pred_accumulation=outputs["accumulation_fine"],
|
||||
gt_image=image,
|
||||
)
|
||||
|
||||
rgb_loss_coarse = self.rgb_loss(image, outputs["rgb_coarse"])
|
||||
rgb_loss_fine = self.rgb_loss(image, outputs["rgb_fine"])
|
||||
rgb_loss_coarse = self.rgb_loss(coarse_image, coarse_pred)
|
||||
rgb_loss_fine = self.rgb_loss(fine_image, fine_pred)
|
||||
|
||||
loss_dict = {"rgb_loss_coarse": rgb_loss_coarse, "rgb_loss_fine": rgb_loss_fine}
|
||||
loss_dict = misc.scale_dict(loss_dict, self.config.loss_coefficients)
|
||||
@@ -204,6 +214,7 @@ class NeRFModel(Model):
|
||||
self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
|
||||
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
|
||||
image = batch["image"].to(outputs["rgb_coarse"].device)
|
||||
image = self.renderer_rgb.blend_background(image)
|
||||
rgb_coarse = outputs["rgb_coarse"]
|
||||
rgb_fine = outputs["rgb_fine"]
|
||||
acc_coarse = colormaps.apply_colormap(outputs["accumulation_coarse"])
|
||||
|
||||
@@ -20,11 +20,13 @@ from __future__ import annotations
|
||||
import typing
|
||||
from abc import abstractmethod
|
||||
from dataclasses import dataclass, field
|
||||
from pathlib import Path
|
||||
from time import time
|
||||
from typing import Any, Dict, List, Literal, Mapping, Optional, Tuple, Type, Union, cast
|
||||
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
from PIL import Image
|
||||
from rich.progress import (
|
||||
BarColumn,
|
||||
MofNCompleteColumn,
|
||||
@@ -104,7 +106,7 @@ class Pipeline(nn.Module):
|
||||
"""Returns the device that the model is on."""
|
||||
return self.model.device
|
||||
|
||||
def load_state_dict(self, state_dict: Mapping[str, Any], strict: bool = True):
|
||||
def load_state_dict(self, state_dict: Mapping[str, Any], strict: Optional[bool] = None):
|
||||
is_ddp_model_state = True
|
||||
model_state = {}
|
||||
for key, value in state_dict.items():
|
||||
@@ -120,7 +122,15 @@ class Pipeline(nn.Module):
|
||||
model_state = {key[len("module.") :]: value for key, value in model_state.items()}
|
||||
|
||||
pipeline_state = {key: value for key, value in state_dict.items() if not key.startswith("_model.")}
|
||||
self.model.load_state_dict(model_state, strict=strict)
|
||||
|
||||
try:
|
||||
self.model.load_state_dict(model_state, strict=True)
|
||||
except RuntimeError:
|
||||
if not strict:
|
||||
self.model.load_state_dict(model_state, strict=False)
|
||||
else:
|
||||
raise
|
||||
|
||||
super().load_state_dict(pipeline_state, strict=False)
|
||||
|
||||
@profiler.time_function
|
||||
@@ -173,8 +183,16 @@ class Pipeline(nn.Module):
|
||||
|
||||
@abstractmethod
|
||||
@profiler.time_function
|
||||
def get_average_eval_image_metrics(self, step: Optional[int] = None):
|
||||
"""Iterate over all the images in the eval dataset and get the average."""
|
||||
def get_average_eval_image_metrics(
|
||||
self, step: Optional[int] = None, output_path: Optional[Path] = None, get_std: bool = False
|
||||
):
|
||||
"""Iterate over all the images in the eval dataset and get the average.
|
||||
|
||||
Args:
|
||||
step: current training step
|
||||
output_path: optional path to save rendered images to
|
||||
get_std: Set True if you want to return std with the mean metric.
|
||||
"""
|
||||
|
||||
def load_pipeline(self, loaded_state: Dict[str, Any], step: int) -> None:
|
||||
"""Load the checkpoint from the given path
|
||||
@@ -339,9 +357,16 @@ class VanillaPipeline(Pipeline):
|
||||
return metrics_dict, images_dict
|
||||
|
||||
@profiler.time_function
|
||||
def get_average_eval_image_metrics(self, step: Optional[int] = None):
|
||||
def get_average_eval_image_metrics(
|
||||
self, step: Optional[int] = None, output_path: Optional[Path] = None, get_std: bool = False
|
||||
):
|
||||
"""Iterate over all the images in the eval dataset and get the average.
|
||||
|
||||
Args:
|
||||
step: current training step
|
||||
output_path: optional path to save rendered images to
|
||||
get_std: Set True if you want to return std with the mean metric.
|
||||
|
||||
Returns:
|
||||
metrics_dict: dictionary of metrics
|
||||
"""
|
||||
@@ -363,7 +388,15 @@ class VanillaPipeline(Pipeline):
|
||||
height, width = camera_ray_bundle.shape
|
||||
num_rays = height * width
|
||||
outputs = self.model.get_outputs_for_camera_ray_bundle(camera_ray_bundle)
|
||||
metrics_dict, _ = self.model.get_image_metrics_and_images(outputs, batch)
|
||||
metrics_dict, images_dict = self.model.get_image_metrics_and_images(outputs, batch)
|
||||
|
||||
if output_path is not None:
|
||||
camera_indices = camera_ray_bundle.camera_indices
|
||||
assert camera_indices is not None
|
||||
for key, val in images_dict.items():
|
||||
Image.fromarray((val * 255).byte().cpu().numpy()).save(
|
||||
output_path / "{0:06d}-{1}.jpg".format(int(camera_indices[0, 0, 0]), key)
|
||||
)
|
||||
assert "num_rays_per_sec" not in metrics_dict
|
||||
metrics_dict["num_rays_per_sec"] = num_rays / (time() - inner_start)
|
||||
fps_str = "fps"
|
||||
@@ -374,9 +407,16 @@ class VanillaPipeline(Pipeline):
|
||||
# average the metrics list
|
||||
metrics_dict = {}
|
||||
for key in metrics_dict_list[0].keys():
|
||||
metrics_dict[key] = float(
|
||||
torch.mean(torch.tensor([metrics_dict[key] for metrics_dict in metrics_dict_list]))
|
||||
)
|
||||
if get_std:
|
||||
key_std, key_mean = torch.std_mean(
|
||||
torch.tensor([metrics_dict[key] for metrics_dict in metrics_dict_list])
|
||||
)
|
||||
metrics_dict[key] = float(key_mean)
|
||||
metrics_dict[f"{key}_std"] = float(key_std)
|
||||
else:
|
||||
metrics_dict[key] = float(
|
||||
torch.mean(torch.tensor([metrics_dict[key] for metrics_dict in metrics_dict_list]))
|
||||
)
|
||||
self.train()
|
||||
return metrics_dict
|
||||
|
||||
@@ -391,7 +431,7 @@ class VanillaPipeline(Pipeline):
|
||||
(key[len("module.") :] if key.startswith("module.") else key): value for key, value in loaded_state.items()
|
||||
}
|
||||
self.model.update_to_step(step)
|
||||
self.load_state_dict(state, strict=True)
|
||||
self.load_state_dict(state)
|
||||
|
||||
def get_training_callbacks(
|
||||
self, training_callback_attributes: TrainingCallbackAttributes
|
||||
|
||||
@@ -138,7 +138,7 @@ def run_colmap(
|
||||
]
|
||||
if matching_method == "vocab_tree":
|
||||
vocab_tree_filename = get_vocab_tree()
|
||||
feature_matcher_cmd.append(f"--VocabTreeMatching.vocab_tree_path {vocab_tree_filename}")
|
||||
feature_matcher_cmd.append(f'--VocabTreeMatching.vocab_tree_path "{vocab_tree_filename}"')
|
||||
feature_matcher_cmd = " ".join(feature_matcher_cmd)
|
||||
with status(msg="[bold yellow]Running COLMAP feature matcher...", spinner="runner", verbose=verbose):
|
||||
run_command(feature_matcher_cmd, verbose=verbose)
|
||||
|
||||
@@ -60,16 +60,24 @@ class ImagesToNerfstudioDataset(ColmapConverterToNerfstudioDataset):
|
||||
if not self.skip_image_processing:
|
||||
# Copy images to output directory
|
||||
image_rename_map_paths = process_data_utils.copy_images(
|
||||
self.data, image_dir=self.image_dir, crop_factor=self.crop_factor, verbose=self.verbose
|
||||
self.data,
|
||||
image_dir=self.image_dir,
|
||||
crop_factor=self.crop_factor,
|
||||
verbose=self.verbose,
|
||||
num_downscales=self.num_downscales,
|
||||
)
|
||||
image_rename_map = dict((a.name, b.name) for a, b in image_rename_map_paths.items())
|
||||
num_frames = len(image_rename_map)
|
||||
summary_log.append(f"Starting with {num_frames} images")
|
||||
|
||||
# Downscale images
|
||||
summary_log.append(
|
||||
process_data_utils.downscale_images(self.image_dir, self.num_downscales, verbose=self.verbose)
|
||||
# # Create mask
|
||||
mask_path = process_data_utils.save_mask(
|
||||
image_dir=self.image_dir,
|
||||
num_downscales=self.num_downscales,
|
||||
crop_factor=(0.0, 0.0, 0.0, 0.0),
|
||||
)
|
||||
if mask_path is not None:
|
||||
summary_log.append("Saved mask(s)")
|
||||
else:
|
||||
num_frames = len(process_data_utils.list_images(self.data))
|
||||
if num_frames == 0:
|
||||
|
||||
@@ -131,6 +131,7 @@ def process_images(
|
||||
image_dir=image_dir,
|
||||
crop_border_pixels=crop_border_pixels,
|
||||
verbose=verbose,
|
||||
num_downscales=num_downscales,
|
||||
)
|
||||
num_frames = len(copied_image_paths)
|
||||
|
||||
@@ -145,9 +146,6 @@ def process_images(
|
||||
else:
|
||||
summary_log.append(f"Started with {num_frames} images")
|
||||
|
||||
# Downscale images
|
||||
summary_log.append(process_data_utils.downscale_images(image_dir, num_downscales, verbose=verbose))
|
||||
|
||||
# Save json
|
||||
if num_frames == 0:
|
||||
CONSOLE.print("[bold red]No images found, exiting")
|
||||
@@ -190,7 +188,11 @@ def process_depth_maps(
|
||||
|
||||
# Copy depth images to output directory
|
||||
copied_depth_maps_paths = process_data_utils.copy_and_upscale_polycam_depth_maps_list(
|
||||
polycam_depth_maps_filenames, depth_dir=depth_dir, crop_border_pixels=crop_border_pixels, verbose=verbose
|
||||
polycam_depth_maps_filenames,
|
||||
depth_dir=depth_dir,
|
||||
num_downscales=num_downscales,
|
||||
crop_border_pixels=crop_border_pixels,
|
||||
verbose=verbose,
|
||||
)
|
||||
|
||||
num_processed_depth_maps = len(copied_depth_maps_paths)
|
||||
@@ -211,11 +213,4 @@ def process_depth_maps(
|
||||
else:
|
||||
summary_log.append(f"Started with {num_processed_depth_maps} images")
|
||||
|
||||
# Downscale depth maps
|
||||
summary_log.append(
|
||||
process_data_utils.downscale_images(
|
||||
depth_dir, num_downscales, folder_name="depths", nearest_neighbor=True, verbose=verbose
|
||||
)
|
||||
)
|
||||
|
||||
return summary_log, polycam_depth_maps_filenames
|
||||
@@ -25,11 +25,19 @@ from typing import List, Literal, Optional, OrderedDict, Tuple, Union
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import imageio
|
||||
import rawpy
|
||||
|
||||
from nerfstudio.utils.rich_utils import CONSOLE, status
|
||||
from nerfstudio.utils.scripts import run_command
|
||||
|
||||
POLYCAM_UPSCALING_TIMES = 2
|
||||
|
||||
"""Lowercase suffixes to treat as raw image."""
|
||||
ALLOWED_RAW_EXTS = [".cr2"]
|
||||
"""Suffix to use for converted images from raw."""
|
||||
RAW_CONVERTED_SUFFIX = ".tiff"
|
||||
|
||||
|
||||
class CameraModel(Enum):
|
||||
"""Enum for camera types."""
|
||||
@@ -54,7 +62,7 @@ def list_images(data: Path) -> List[Path]:
|
||||
Returns:
|
||||
Paths to images contained in the directory
|
||||
"""
|
||||
allowed_exts = [".jpg", ".jpeg", ".png", ".tif", ".tiff"]
|
||||
allowed_exts = [".jpg", ".jpeg", ".png", ".tif", ".tiff"] + ALLOWED_RAW_EXTS
|
||||
image_paths = sorted([p for p in data.glob("[!.]*") if p.suffix.lower() in allowed_exts])
|
||||
return image_paths
|
||||
|
||||
@@ -103,6 +111,7 @@ def convert_video_to_images(
|
||||
video_path: Path,
|
||||
image_dir: Path,
|
||||
num_frames_target: int,
|
||||
num_downscales: int,
|
||||
crop_factor: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0),
|
||||
verbose: bool = False,
|
||||
) -> Tuple[List[str], int]:
|
||||
@@ -112,6 +121,7 @@ def convert_video_to_images(
|
||||
video_path: Path to the video.
|
||||
output_dir: Path to the output directory.
|
||||
num_frames_target: Number of frames to extract.
|
||||
num_downscales: Number of times to downscale the images. Downscales by 2 each time.
|
||||
crop_factor: Portion of the image to crop. Should be in [0,1] (top, bottom, left, right)
|
||||
verbose: If True, logs the output of the command.
|
||||
Returns:
|
||||
@@ -143,7 +153,6 @@ def convert_video_to_images(
|
||||
sys.exit(1)
|
||||
CONSOLE.print("Number of frames in video:", num_frames)
|
||||
|
||||
out_filename = image_dir / "frame_%05d.png"
|
||||
ffmpeg_cmd = f'ffmpeg -i "{video_path}"'
|
||||
|
||||
crop_cmd = ""
|
||||
@@ -152,41 +161,66 @@ def convert_video_to_images(
|
||||
width = 1 - crop_factor[2] - crop_factor[3]
|
||||
start_x = crop_factor[2]
|
||||
start_y = crop_factor[0]
|
||||
crop_cmd = f',"crop=w=iw*{width}:h=ih*{height}:x=iw*{start_x}:y=ih*{start_y}"'
|
||||
crop_cmd = f"crop=w=iw*{width}:h=ih*{height}:x=iw*{start_x}:y=ih*{start_y},"
|
||||
|
||||
num_frames = get_num_frames_in_video(video_path)
|
||||
spacing = num_frames // num_frames_target
|
||||
|
||||
downscale_chains = [f"[t{i}]scale=iw/{2**i}:ih/{2**i}[out{i}]" for i in range(num_downscales + 1)]
|
||||
downscale_dirs = [Path(str(image_dir) + (f"_{2**i}" if i > 0 else "")) for i in range(num_downscales + 1)]
|
||||
downscale_paths = [downscale_dirs[i] / "frame_%05d.png" for i in range(num_downscales + 1)]
|
||||
|
||||
for dir in downscale_dirs:
|
||||
dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
downscale_chain = (
|
||||
f"split={num_downscales + 1}"
|
||||
+ "".join([f"[t{i}]" for i in range(num_downscales + 1)])
|
||||
+ ";"
|
||||
+ ";".join(downscale_chains)
|
||||
)
|
||||
|
||||
if spacing > 1:
|
||||
ffmpeg_cmd += f" -vf thumbnail={spacing},setpts=N/TB{crop_cmd} -r 1"
|
||||
CONSOLE.print("Number of frames to extract:", math.ceil(num_frames / spacing))
|
||||
ffmpeg_cmd += " -vsync vfr"
|
||||
select_cmd = f"thumbnail={spacing},setpts=N/TB,"
|
||||
else:
|
||||
CONSOLE.print("[bold red]Can't satisfy requested number of frames. Extracting all frames.")
|
||||
ffmpeg_cmd += " -pix_fmt bgr8"
|
||||
if crop_cmd != "":
|
||||
ffmpeg_cmd += f" -vf {crop_cmd[1:]}"
|
||||
select_cmd = ""
|
||||
|
||||
downscale_cmd = f' -filter_complex "{select_cmd}{crop_cmd}{downscale_chain}"' + "".join(
|
||||
[f' -map "[out{i}]" "{downscale_paths[i]}"' for i in range(num_downscales + 1)]
|
||||
)
|
||||
|
||||
ffmpeg_cmd += downscale_cmd
|
||||
|
||||
ffmpeg_cmd += f" {out_filename}"
|
||||
run_command(ffmpeg_cmd, verbose=verbose)
|
||||
|
||||
num_final_frames = len(list(image_dir.glob("*.png")))
|
||||
summary_log = []
|
||||
summary_log.append(f"Starting with {num_frames} video frames")
|
||||
summary_log.append(f"We extracted {num_final_frames} images")
|
||||
CONSOLE.log("[bold green]:tada: Done converting video to images.")
|
||||
num_final_frames = len(list(image_dir.glob("*.png")))
|
||||
summary_log = []
|
||||
summary_log.append(f"Starting with {num_frames} video frames")
|
||||
summary_log.append(f"We extracted {num_final_frames} images")
|
||||
CONSOLE.log("[bold green]:tada: Done converting video to images.")
|
||||
|
||||
return summary_log, num_final_frames
|
||||
return summary_log, num_final_frames
|
||||
|
||||
|
||||
def copy_images_list(
|
||||
image_paths: List[Path],
|
||||
image_dir: Path,
|
||||
num_downscales: int,
|
||||
crop_border_pixels: Optional[int] = None,
|
||||
crop_factor: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0),
|
||||
verbose: bool = False,
|
||||
upscale_factor: Optional[int] = None,
|
||||
nearest_neighbor: bool = False,
|
||||
) -> List[Path]:
|
||||
"""Copy all images in a list of Paths. Useful for filtering from a directory.
|
||||
Args:
|
||||
image_paths: List of Paths of images to copy to a new directory.
|
||||
image_dir: Path to the output directory.
|
||||
num_downscales: Number of times to downscale the images. Downscales by 2 each time.
|
||||
crop_border_pixels: If not None, crops each edge by the specified number of pixels.
|
||||
crop_factor: Portion of the image to crop. Should be in [0,1] (top, bottom, left, right)
|
||||
verbose: If True, print extra logging.
|
||||
@@ -209,31 +243,61 @@ def copy_images_list(
|
||||
CONSOLE.log(f"Copying image {idx + 1} of {len(image_paths)}...")
|
||||
copied_image_path = image_dir / f"frame_{idx + 1:05d}{image_path.suffix}"
|
||||
try:
|
||||
shutil.copy(image_path, copied_image_path)
|
||||
# if CR2 raw, we want to read raw and write TIFF, and change the file suffix for downstream processing
|
||||
if image_path.suffix.lower() in ALLOWED_RAW_EXTS:
|
||||
copied_image_path = image_dir / f"frame_{idx + 1:05d}{RAW_CONVERTED_SUFFIX}"
|
||||
with rawpy.imread(str(image_path)) as raw:
|
||||
rgb = raw.postprocess()
|
||||
imageio.imsave(copied_image_path, rgb)
|
||||
image_paths[idx] = copied_image_path
|
||||
else:
|
||||
shutil.copy(image_path, copied_image_path)
|
||||
except shutil.SameFileError:
|
||||
pass
|
||||
copied_image_paths.append(copied_image_path)
|
||||
|
||||
nn_flag = "" if not nearest_neighbor else ":flags=neighbor"
|
||||
downscale_chains = [f"[t{i}]scale=iw/{2**i}:ih/{2**i}{nn_flag}[out{i}]" for i in range(num_downscales + 1)]
|
||||
downscale_dirs = [Path(str(image_dir) + (f"_{2**i}" if i > 0 else "")) for i in range(num_downscales + 1)]
|
||||
downscale_paths = [
|
||||
downscale_dirs[i] / ("frame_%05d" + copied_image_paths[0].suffix) for i in range(num_downscales + 1)
|
||||
]
|
||||
|
||||
for dir in downscale_dirs:
|
||||
dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
downscale_chain = (
|
||||
f"split={num_downscales + 1}"
|
||||
+ "".join([f"[t{i}]" for i in range(num_downscales + 1)])
|
||||
+ ";"
|
||||
+ ";".join(downscale_chains)
|
||||
)
|
||||
|
||||
num_frames = len(image_paths)
|
||||
ffmpeg_cmd = f'ffmpeg -y -noautorotate -i "{image_dir / f"frame_%05d{copied_image_paths[0].suffix}"}" -q:v 2 '
|
||||
|
||||
crop_cmd = ""
|
||||
if crop_border_pixels is not None:
|
||||
file_type = image_paths[0].suffix
|
||||
filename = f"frame_%05d{file_type}"
|
||||
crop = f"crop=iw-{crop_border_pixels*2}:ih-{crop_border_pixels*2}"
|
||||
ffmpeg_cmd = f'ffmpeg -y -noautorotate -i "{image_dir / filename}" -q:v 2 -vf {crop} "{image_dir / filename}"'
|
||||
run_command(ffmpeg_cmd, verbose=verbose)
|
||||
crop_cmd = f"crop=iw-{crop_border_pixels*2}:ih-{crop_border_pixels*2}[cropped];[cropped]"
|
||||
elif crop_factor != (0.0, 0.0, 0.0, 0.0):
|
||||
file_type = image_paths[0].suffix
|
||||
filename = f"frame_%05d{file_type}"
|
||||
height = 1 - crop_factor[0] - crop_factor[1]
|
||||
width = 1 - crop_factor[2] - crop_factor[3]
|
||||
start_x = crop_factor[2]
|
||||
start_y = crop_factor[0]
|
||||
crop_cmd = f',"crop=w=iw*{width}:h=ih*{height}:x=iw*{start_x}:y=ih*{start_y}"'
|
||||
ffmpeg_cmd = (
|
||||
f'ffmpeg -y -noautorotate -i "{image_dir / filename}" -q:v 2 -vf {crop_cmd[1:]} "{image_dir / filename}"'
|
||||
)
|
||||
run_command(ffmpeg_cmd, verbose=verbose)
|
||||
crop_cmd = f"crop=w=iw*{width}:h=ih*{height}:x=iw*{start_x}:y=ih*{start_y}[cropped];[cropped]"
|
||||
|
||||
num_frames = len(image_paths)
|
||||
select_cmd = "[0:v]"
|
||||
if upscale_factor is not None:
|
||||
select_cmd = f"[0:v]scale=iw*{upscale_factor}:ih*{upscale_factor}:flags=neighbor[upscaled];[upscaled]"
|
||||
|
||||
downscale_cmd = f' -filter_complex "{select_cmd}{crop_cmd}{downscale_chain}"' + "".join(
|
||||
[f' -map "[out{i}]" "{downscale_paths[i]}"' for i in range(num_downscales + 1)]
|
||||
)
|
||||
|
||||
ffmpeg_cmd += downscale_cmd
|
||||
if verbose:
|
||||
CONSOLE.log(f"... {ffmpeg_cmd}")
|
||||
run_command(ffmpeg_cmd, verbose=verbose)
|
||||
|
||||
if num_frames == 0:
|
||||
CONSOLE.log("[bold red]:skull: No usable images in the data folder.")
|
||||
@@ -246,6 +310,7 @@ def copy_images_list(
|
||||
def copy_and_upscale_polycam_depth_maps_list(
|
||||
polycam_depth_image_filenames: List[Path],
|
||||
depth_dir: Path,
|
||||
num_downscales: int,
|
||||
crop_border_pixels: Optional[int] = None,
|
||||
verbose: bool = False,
|
||||
) -> List[Path]:
|
||||
@@ -268,31 +333,26 @@ def copy_and_upscale_polycam_depth_maps_list(
|
||||
assert upscale_factor > 1
|
||||
assert isinstance(upscale_factor, int)
|
||||
|
||||
copied_depth_map_paths = []
|
||||
for idx, depth_map in enumerate(polycam_depth_image_filenames):
|
||||
destination = depth_dir / f"frame_{idx + 1:05d}{depth_map.suffix}"
|
||||
ffmpeg_cmd = [
|
||||
f'ffmpeg -y -i "{depth_map}" ',
|
||||
f"-q:v 2 -vf scale=iw*{upscale_factor}:ih*{upscale_factor}:flags=neighbor ",
|
||||
f'"{destination}"',
|
||||
]
|
||||
ffmpeg_cmd = " ".join(ffmpeg_cmd)
|
||||
run_command(ffmpeg_cmd, verbose=verbose)
|
||||
copied_depth_map_paths.append(destination)
|
||||
|
||||
if crop_border_pixels is not None:
|
||||
file_type = depth_dir.glob("frame_*").__next__().suffix
|
||||
filename = f"frame_%05d{file_type}"
|
||||
crop = f"crop=iw-{crop_border_pixels * 2}:ih-{crop_border_pixels * 2}"
|
||||
ffmpeg_cmd = f'ffmpeg -y -i "{depth_dir / filename}" -q:v 2 -vf {crop} "{depth_dir / filename}"'
|
||||
run_command(ffmpeg_cmd, verbose=verbose)
|
||||
copied_depth_map_paths = copy_images_list(
|
||||
image_paths=polycam_depth_image_filenames,
|
||||
image_dir=depth_dir,
|
||||
num_downscales=num_downscales,
|
||||
crop_border_pixels=crop_border_pixels,
|
||||
verbose=verbose,
|
||||
upscale_factor=upscale_factor,
|
||||
nearest_neighbor=True,
|
||||
)
|
||||
|
||||
CONSOLE.log("[bold green]:tada: Done upscaling depth maps.")
|
||||
return copied_depth_map_paths
|
||||
|
||||
|
||||
def copy_images(
|
||||
data: Path, image_dir: Path, verbose, crop_factor: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0)
|
||||
data: Path,
|
||||
image_dir: Path,
|
||||
verbose: bool = False,
|
||||
crop_factor: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0),
|
||||
num_downscales: int = 0,
|
||||
) -> OrderedDict[Path, Path]:
|
||||
"""Copy images from a directory to a new directory.
|
||||
|
||||
@@ -312,7 +372,11 @@ def copy_images(
|
||||
sys.exit(1)
|
||||
|
||||
copied_images = copy_images_list(
|
||||
image_paths=image_paths, image_dir=image_dir, crop_factor=crop_factor, verbose=verbose
|
||||
image_paths=image_paths,
|
||||
image_dir=image_dir,
|
||||
crop_factor=crop_factor,
|
||||
verbose=verbose,
|
||||
num_downscales=num_downscales,
|
||||
)
|
||||
return OrderedDict((original_path, new_path) for original_path, new_path in zip(image_paths, copied_images))
|
||||
|
||||
@@ -324,7 +388,8 @@ def downscale_images(
|
||||
nearest_neighbor: bool = False,
|
||||
verbose: bool = False,
|
||||
) -> str:
|
||||
"""Downscales the images in the directory. Uses FFMPEG.
|
||||
"""(Now deprecated; much faster integrated into copy_images.)
|
||||
Downscales the images in the directory. Uses FFMPEG.
|
||||
|
||||
Assumes images are named frame_00001.png, frame_00002.png, etc.
|
||||
|
||||
|
||||
@@ -30,9 +30,8 @@ class VideoToNerfstudioDataset(ColmapConverterToNerfstudioDataset):
|
||||
|
||||
This script does the following:
|
||||
|
||||
1. Converts the video into images.
|
||||
2. Scales images to a specified size.
|
||||
3. Calculates the camera poses for each image using `COLMAP <https://colmap.github.io/>`_.
|
||||
1. Converts the video into images and downscales them.
|
||||
2. Calculates the camera poses for each image using `COLMAP <https://colmap.github.io/>`_.
|
||||
"""
|
||||
|
||||
num_frames_target: int = 300
|
||||
@@ -53,14 +52,17 @@ class VideoToNerfstudioDataset(ColmapConverterToNerfstudioDataset):
|
||||
self.data,
|
||||
image_dir=temp_image_dir,
|
||||
num_frames_target=self.num_frames_target,
|
||||
num_downscales=0,
|
||||
crop_factor=(0.0, 0.0, 0.0, 0.0),
|
||||
verbose=self.verbose,
|
||||
)
|
||||
else:
|
||||
# If we're not dealing with equirects we can downscale in one step.
|
||||
summary_log, num_extracted_frames = process_data_utils.convert_video_to_images(
|
||||
self.data,
|
||||
image_dir=self.image_dir,
|
||||
num_frames_target=self.num_frames_target,
|
||||
num_downscales=self.num_downscales,
|
||||
crop_factor=self.crop_factor,
|
||||
verbose=self.verbose,
|
||||
)
|
||||
@@ -90,6 +92,11 @@ class VideoToNerfstudioDataset(ColmapConverterToNerfstudioDataset):
|
||||
|
||||
self.camera_type = "perspective"
|
||||
|
||||
# # Downscale images
|
||||
summary_log.append(
|
||||
process_data_utils.downscale_images(self.image_dir, self.num_downscales, verbose=self.verbose)
|
||||
)
|
||||
|
||||
# # Create mask
|
||||
mask_path = process_data_utils.save_mask(
|
||||
image_dir=self.image_dir,
|
||||
@@ -100,11 +107,6 @@ class VideoToNerfstudioDataset(ColmapConverterToNerfstudioDataset):
|
||||
if mask_path is not None:
|
||||
summary_log.append(f"Saved mask to {mask_path}")
|
||||
|
||||
# # Downscale images
|
||||
summary_log.append(
|
||||
process_data_utils.downscale_images(self.image_dir, self.num_downscales, verbose=self.verbose)
|
||||
)
|
||||
|
||||
# Run Colmap
|
||||
if not self.skip_colmap:
|
||||
self._run_colmap(mask_path)
|
||||
|
||||
@@ -21,6 +21,7 @@ from __future__ import annotations
|
||||
import json
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
import tyro
|
||||
|
||||
@@ -36,12 +37,16 @@ class ComputePSNR:
|
||||
load_config: Path
|
||||
# Name of the output file.
|
||||
output_path: Path = Path("output.json")
|
||||
# Optional path to save rendered outputs to.
|
||||
render_output_path: Optional[Path] = None
|
||||
|
||||
def main(self) -> None:
|
||||
"""Main function."""
|
||||
config, pipeline, checkpoint_path, _ = eval_setup(self.load_config)
|
||||
assert self.output_path.suffix == ".json"
|
||||
metrics_dict = pipeline.get_average_eval_image_metrics()
|
||||
if self.render_output_path is not None:
|
||||
self.render_output_path.mkdir(parents=True)
|
||||
metrics_dict = pipeline.get_average_eval_image_metrics(output_path=self.render_output_path, get_std=True)
|
||||
self.output_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
# Get the output and define the names to save to
|
||||
benchmark_info = {
|
||||
|
||||
@@ -97,6 +97,8 @@ class ExportPointCloud(Exporter):
|
||||
"""Number of points to generate. May result in less if outlier removal is used."""
|
||||
remove_outliers: bool = True
|
||||
"""Remove outliers from the point cloud."""
|
||||
reorient_normals: bool = True
|
||||
"""Reorient point cloud normals based on view direction."""
|
||||
normal_method: Literal["open3d", "model_output"] = "model_output"
|
||||
"""Method to estimate normals with."""
|
||||
normal_output_name: str = "normals"
|
||||
@@ -138,6 +140,7 @@ class ExportPointCloud(Exporter):
|
||||
pipeline=pipeline,
|
||||
num_points=self.num_points,
|
||||
remove_outliers=self.remove_outliers,
|
||||
reorient_normals=self.reorient_normals,
|
||||
estimate_normals=estimate_normals,
|
||||
rgb_output_name=self.rgb_output_name,
|
||||
depth_output_name=self.depth_output_name,
|
||||
@@ -243,6 +246,8 @@ class ExportPoissonMesh(Exporter):
|
||||
"""Number of points to generate. May result in less if outlier removal is used."""
|
||||
remove_outliers: bool = True
|
||||
"""Remove outliers from the point cloud."""
|
||||
reorient_normals: bool = True
|
||||
"""Reorient point cloud normals based on view direction."""
|
||||
depth_output_name: str = "depth"
|
||||
"""Name of the depth output."""
|
||||
rgb_output_name: str = "rgb"
|
||||
@@ -296,6 +301,7 @@ class ExportPoissonMesh(Exporter):
|
||||
pipeline=pipeline,
|
||||
num_points=self.num_points,
|
||||
remove_outliers=self.remove_outliers,
|
||||
reorient_normals=self.reorient_normals,
|
||||
estimate_normals=estimate_normals,
|
||||
rgb_output_name=self.rgb_output_name,
|
||||
depth_output_name=self.depth_output_name,
|
||||
|
||||
@@ -89,7 +89,10 @@ class ProcessRecord3D(BaseConverterToNerfstudioDataset):
|
||||
record3d_image_filenames = list(np.array(record3d_image_filenames)[idx])
|
||||
# Copy images to output directory
|
||||
copied_image_paths = process_data_utils.copy_images_list(
|
||||
record3d_image_filenames, image_dir=image_dir, verbose=self.verbose
|
||||
record3d_image_filenames,
|
||||
image_dir=image_dir,
|
||||
verbose=self.verbose,
|
||||
num_downscales=self.num_downscales,
|
||||
)
|
||||
num_frames = len(copied_image_paths)
|
||||
|
||||
@@ -101,9 +104,6 @@ class ProcessRecord3D(BaseConverterToNerfstudioDataset):
|
||||
f"larger than the current value ({self.max_dataset_size}), or -1 to use all images."
|
||||
)
|
||||
|
||||
# Downscale images
|
||||
summary_log.append(process_data_utils.downscale_images(image_dir, self.num_downscales, verbose=self.verbose))
|
||||
|
||||
metadata_path = self.data / "metadata.json"
|
||||
record3d_utils.record3d_to_json(copied_image_paths, metadata_path, self.output_dir, indices=idx)
|
||||
CONSOLE.rule("[bold green]:tada: :tada: :tada: All DONE :tada: :tada: :tada:")
|
||||
@@ -266,6 +266,7 @@ class ProcessMetashape(BaseConverterToNerfstudioDataset, _NoDefaultProcessMetash
|
||||
image_filenames,
|
||||
image_dir=image_dir,
|
||||
verbose=self.verbose,
|
||||
num_downscales=self.num_downscales,
|
||||
)
|
||||
num_frames = len(copied_image_paths)
|
||||
|
||||
@@ -282,9 +283,6 @@ class ProcessMetashape(BaseConverterToNerfstudioDataset, _NoDefaultProcessMetash
|
||||
else:
|
||||
summary_log.append(f"Started with {num_frames} images")
|
||||
|
||||
# Downscale images
|
||||
summary_log.append(process_data_utils.downscale_images(image_dir, self.num_downscales, verbose=self.verbose))
|
||||
|
||||
# Save json
|
||||
if num_frames == 0:
|
||||
CONSOLE.print("[bold red]No images found, exiting")
|
||||
@@ -353,6 +351,7 @@ class ProcessRealityCapture(BaseConverterToNerfstudioDataset, _NoDefaultProcessR
|
||||
image_filenames,
|
||||
image_dir=image_dir,
|
||||
verbose=self.verbose,
|
||||
num_downscales=self.num_downscales,
|
||||
)
|
||||
num_frames = len(copied_image_paths)
|
||||
|
||||
@@ -369,9 +368,6 @@ class ProcessRealityCapture(BaseConverterToNerfstudioDataset, _NoDefaultProcessR
|
||||
else:
|
||||
summary_log.append(f"Started with {num_frames} images")
|
||||
|
||||
# Downscale images
|
||||
summary_log.append(process_data_utils.downscale_images(image_dir, self.num_downscales, verbose=self.verbose))
|
||||
|
||||
# Save json
|
||||
if num_frames == 0:
|
||||
CONSOLE.print("[bold red]No images found, exiting")
|
||||
|
||||
+102
-37
@@ -74,6 +74,8 @@ def _render_trajectory_video(
|
||||
output_format: Literal["images", "video"] = "video",
|
||||
image_format: Literal["jpeg", "png"] = "jpeg",
|
||||
jpeg_quality: int = 100,
|
||||
depth_near_plane: Optional[float] = None,
|
||||
depth_far_plane: Optional[float] = None,
|
||||
colormap_options: colormaps.ColormapOptions = colormaps.ColormapOptions(),
|
||||
) -> None:
|
||||
"""Helper function to create a video of the spiral trajectory.
|
||||
@@ -87,6 +89,8 @@ def _render_trajectory_video(
|
||||
rendered_resolution_scaling_factor: Scaling factor to apply to the camera image resolution.
|
||||
seconds: Length of output video.
|
||||
output_format: How to save output data.
|
||||
depth_near_plane: Closest depth to consider when using the colormap for depth. If None, use min value.
|
||||
depth_far_plane: Furthest depth to consider when using the colormap for depth. If None, use max value.
|
||||
colormap_options: Options for colormap.
|
||||
"""
|
||||
CONSOLE.print("[bold green]Creating trajectory " + output_format)
|
||||
@@ -149,14 +153,28 @@ def _render_trajectory_video(
|
||||
)
|
||||
sys.exit(1)
|
||||
output_image = outputs[rendered_output_name]
|
||||
output_image = (
|
||||
colormaps.apply_colormap(
|
||||
image=output_image,
|
||||
colormap_options=colormap_options,
|
||||
is_depth = rendered_output_name.find("depth") != -1
|
||||
if is_depth:
|
||||
output_image = (
|
||||
colormaps.apply_depth_colormap(
|
||||
output_image,
|
||||
accumulation=outputs["accumulation"],
|
||||
near_plane=depth_near_plane,
|
||||
far_plane=depth_far_plane,
|
||||
colormap_options=colormap_options,
|
||||
)
|
||||
.cpu()
|
||||
.numpy()
|
||||
)
|
||||
else:
|
||||
output_image = (
|
||||
colormaps.apply_colormap(
|
||||
image=output_image,
|
||||
colormap_options=colormap_options,
|
||||
)
|
||||
.cpu()
|
||||
.numpy()
|
||||
)
|
||||
.cpu()
|
||||
.numpy()
|
||||
)
|
||||
render_image.append(output_image)
|
||||
render_image = np.concatenate(render_image, axis=1)
|
||||
if output_format == "images":
|
||||
@@ -313,6 +331,12 @@ class BaseRender:
|
||||
"""Scaling factor to apply to the camera image resolution."""
|
||||
eval_num_rays_per_chunk: Optional[int] = None
|
||||
"""Specifies number of rays per chunk during eval. If None, use the value in the config file."""
|
||||
rendered_output_names: List[str] = field(default_factory=lambda: ["rgb"])
|
||||
"""Name of the renderer outputs to use. rgb, depth, etc. concatenates them along y axis"""
|
||||
depth_near_plane: Optional[float] = None
|
||||
"""Closest depth to consider when using the colormap for depth. If None, use min value."""
|
||||
depth_far_plane: Optional[float] = None
|
||||
"""Furthest depth to consider when using the colormap for depth. If None, use max value."""
|
||||
colormap_options: colormaps.ColormapOptions = colormaps.ColormapOptions()
|
||||
"""Colormap options."""
|
||||
|
||||
@@ -321,8 +345,6 @@ class BaseRender:
|
||||
class RenderCameraPath(BaseRender):
|
||||
"""Render a camera path generated by the viewer or blender add-on."""
|
||||
|
||||
rendered_output_names: List[str] = field(default_factory=lambda: ["rgb"])
|
||||
"""Name of the renderer outputs to use. rgb, depth, etc. concatenates them along y axis"""
|
||||
camera_path_filename: Path = Path("camera_path.json")
|
||||
"""Filename of the camera path to render."""
|
||||
output_format: Literal["images", "video"] = "video"
|
||||
@@ -344,16 +366,23 @@ class RenderCameraPath(BaseRender):
|
||||
crop_data = get_crop_from_json(camera_path)
|
||||
camera_path = get_path_from_json(camera_path)
|
||||
|
||||
if camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value:
|
||||
if (
|
||||
camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value
|
||||
or camera_path.camera_type[0] == CameraType.VR180_L.value
|
||||
):
|
||||
# temp folder for writing left and right view renders
|
||||
temp_folder_path = self.output_path.parent / (self.output_path.stem + "_temp")
|
||||
|
||||
Path(temp_folder_path).mkdir(parents=True, exist_ok=True)
|
||||
left_eye_path = temp_folder_path / "ods_render_Left.mp4"
|
||||
left_eye_path = temp_folder_path / "render_left.mp4"
|
||||
|
||||
self.output_path = left_eye_path
|
||||
|
||||
CONSOLE.print("[bold green]:goggles: Omni-directional Stereo VR :goggles:")
|
||||
if camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value:
|
||||
CONSOLE.print("[bold green]:goggles: Omni-directional Stereo VR :goggles:")
|
||||
else:
|
||||
CONSOLE.print("[bold green]:goggles: VR180 :goggles:")
|
||||
|
||||
CONSOLE.print("Rendering left eye view")
|
||||
|
||||
# add mp4 suffix to video output if none is specified
|
||||
@@ -371,17 +400,26 @@ class RenderCameraPath(BaseRender):
|
||||
output_format=self.output_format,
|
||||
image_format=self.image_format,
|
||||
jpeg_quality=self.jpeg_quality,
|
||||
depth_near_plane=self.depth_near_plane,
|
||||
depth_far_plane=self.depth_far_plane,
|
||||
colormap_options=self.colormap_options,
|
||||
)
|
||||
|
||||
if camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value:
|
||||
if (
|
||||
camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value
|
||||
or camera_path.camera_type[0] == CameraType.VR180_L.value
|
||||
):
|
||||
# declare paths for left and right renders
|
||||
|
||||
left_eye_path = self.output_path
|
||||
right_eye_path = left_eye_path.parent / "ods_render_Right.mp4"
|
||||
right_eye_path = left_eye_path.parent / "render_right.mp4"
|
||||
|
||||
self.output_path = right_eye_path
|
||||
camera_path.camera_type[0] = CameraType.OMNIDIRECTIONALSTEREO_R.value
|
||||
|
||||
if camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value:
|
||||
camera_path.camera_type[0] = CameraType.OMNIDIRECTIONALSTEREO_R.value
|
||||
else:
|
||||
camera_path.camera_type[0] = CameraType.VR180_R.value
|
||||
|
||||
CONSOLE.print("Rendering right eye view")
|
||||
_render_trajectory_video(
|
||||
@@ -395,37 +433,60 @@ class RenderCameraPath(BaseRender):
|
||||
output_format=self.output_format,
|
||||
image_format=self.image_format,
|
||||
jpeg_quality=self.jpeg_quality,
|
||||
depth_near_plane=self.depth_near_plane,
|
||||
depth_far_plane=self.depth_far_plane,
|
||||
colormap_options=self.colormap_options,
|
||||
)
|
||||
|
||||
# stack the left and right eye renders for final output
|
||||
self.output_path = Path(str(left_eye_path.parent)[:-5] + ".mp4")
|
||||
ffmpeg_ods_command = ""
|
||||
if self.output_format == "video":
|
||||
ffmpeg_ods_command = f'ffmpeg -y -i "{left_eye_path}" -i "{right_eye_path}" -filter_complex "[0:v]pad=iw:2*ih[int];[int][1:v]overlay=0:h" -c:v libx264 -crf 23 -preset veryfast "{self.output_path}"'
|
||||
run_command(ffmpeg_ods_command, verbose=False)
|
||||
if self.output_format == "images":
|
||||
# create a folder for the stacked renders
|
||||
self.output_path = Path(str(left_eye_path.parent)[:-5])
|
||||
self.output_path.mkdir(parents=True, exist_ok=True)
|
||||
if self.image_format == "png":
|
||||
ffmpeg_ods_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.png")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.png")}" -filter_complex vstack -start_number 0 "{str(self.output_path)+"//%05d.png"}"'
|
||||
elif self.image_format == "jpeg":
|
||||
ffmpeg_ods_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.jpg")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.jpg")}" -filter_complex vstack -start_number 0 "{str(self.output_path)+"//%05d.jpg"}"'
|
||||
run_command(ffmpeg_ods_command, verbose=False)
|
||||
|
||||
# remove the temp files directory
|
||||
if str(left_eye_path.parent)[-5:] == "_temp":
|
||||
shutil.rmtree(left_eye_path.parent, ignore_errors=True)
|
||||
CONSOLE.print("[bold green]Final ODS Render Complete")
|
||||
if camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_R.value:
|
||||
# stack the left and right eye renders vertically for ODS final output
|
||||
ffmpeg_ods_command = ""
|
||||
if self.output_format == "video":
|
||||
ffmpeg_ods_command = f'ffmpeg -y -i "{left_eye_path}" -i "{right_eye_path}" -filter_complex "[0:v]pad=iw:2*ih[int];[int][1:v]overlay=0:h" -c:v libx264 -crf 23 -preset veryfast "{self.output_path}"'
|
||||
run_command(ffmpeg_ods_command, verbose=False)
|
||||
if self.output_format == "images":
|
||||
# create a folder for the stacked renders
|
||||
self.output_path = Path(str(left_eye_path.parent)[:-5])
|
||||
self.output_path.mkdir(parents=True, exist_ok=True)
|
||||
if self.image_format == "png":
|
||||
ffmpeg_ods_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.png")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.png")}" -filter_complex vstack -start_number 0 "{str(self.output_path)+"//%05d.png"}"'
|
||||
elif self.image_format == "jpeg":
|
||||
ffmpeg_ods_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.jpg")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.jpg")}" -filter_complex vstack -start_number 0 "{str(self.output_path)+"//%05d.jpg"}"'
|
||||
run_command(ffmpeg_ods_command, verbose=False)
|
||||
|
||||
# remove the temp files directory
|
||||
if str(left_eye_path.parent)[-5:] == "_temp":
|
||||
shutil.rmtree(left_eye_path.parent, ignore_errors=True)
|
||||
CONSOLE.print("[bold green]Final ODS Render Complete")
|
||||
else:
|
||||
# stack the left and right eye renders horizontally for VR180 final output
|
||||
self.output_path = Path(str(left_eye_path.parent)[:-5] + ".mp4")
|
||||
ffmpeg_vr180_command = ""
|
||||
if self.output_format == "video":
|
||||
ffmpeg_vr180_command = f'ffmpeg -y -i "{right_eye_path}" -i "{left_eye_path}" -filter_complex "[1:v]hstack=inputs=2" -c:a copy "{self.output_path}"'
|
||||
run_command(ffmpeg_vr180_command, verbose=False)
|
||||
if self.output_format == "images":
|
||||
# create a folder for the stacked renders
|
||||
self.output_path = Path(str(left_eye_path.parent)[:-5])
|
||||
self.output_path.mkdir(parents=True, exist_ok=True)
|
||||
if self.image_format == "png":
|
||||
ffmpeg_vr180_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.png")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.png")}" -filter_complex hstack -start_number 0 "{str(self.output_path)+"//%05d.png"}"'
|
||||
elif self.image_format == "jpeg":
|
||||
ffmpeg_vr180_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.jpg")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.jpg")}" -filter_complex hstack -start_number 0 "{str(self.output_path)+"//%05d.jpg"}"'
|
||||
run_command(ffmpeg_vr180_command, verbose=False)
|
||||
|
||||
# remove the temp files directory
|
||||
if str(left_eye_path.parent)[-5:] == "_temp":
|
||||
shutil.rmtree(left_eye_path.parent, ignore_errors=True)
|
||||
CONSOLE.print("[bold green]Final VR180 Render Complete")
|
||||
|
||||
|
||||
@dataclass
|
||||
class RenderInterpolated(BaseRender):
|
||||
"""Render a trajectory that interpolates between training or eval dataset images."""
|
||||
|
||||
rendered_output_names: List[str] = field(default_factory=lambda: ["rgb"])
|
||||
"""Name of the renderer outputs to use. rgb, depth, etc. concatenates them along y axis"""
|
||||
pose_source: Literal["eval", "train"] = "eval"
|
||||
"""Pose source to render."""
|
||||
interpolation_steps: int = 10
|
||||
@@ -469,6 +530,9 @@ class RenderInterpolated(BaseRender):
|
||||
rendered_resolution_scaling_factor=1.0 / self.downscale_factor,
|
||||
seconds=seconds,
|
||||
output_format=self.output_format,
|
||||
image_format=self.image_format,
|
||||
depth_near_plane=self.depth_near_plane,
|
||||
depth_far_plane=self.depth_far_plane,
|
||||
colormap_options=self.colormap_options,
|
||||
)
|
||||
|
||||
@@ -477,8 +541,6 @@ class RenderInterpolated(BaseRender):
|
||||
class SpiralRender(BaseRender):
|
||||
"""Render a spiral trajectory (often not great)."""
|
||||
|
||||
rendered_output_names: List[str] = field(default_factory=lambda: ["rgb"])
|
||||
"""Name of the renderer outputs to use. rgb, depth, etc. concatenates them along y axis"""
|
||||
seconds: float = 3.0
|
||||
"""How long the video should be."""
|
||||
output_format: Literal["images", "video"] = "video"
|
||||
@@ -511,6 +573,9 @@ class SpiralRender(BaseRender):
|
||||
rendered_resolution_scaling_factor=1.0 / self.downscale_factor,
|
||||
seconds=self.seconds,
|
||||
output_format=self.output_format,
|
||||
image_format=self.image_format,
|
||||
depth_near_plane=self.depth_near_plane,
|
||||
depth_far_plane=self.depth_far_plane,
|
||||
colormap_options=self.colormap_options,
|
||||
)
|
||||
|
||||
|
||||
@@ -22,6 +22,8 @@ import time
|
||||
from dataclasses import dataclass, field, fields
|
||||
from pathlib import Path
|
||||
|
||||
from typing import Literal
|
||||
|
||||
import tyro
|
||||
|
||||
from nerfstudio.configs.base_config import ViewerConfig
|
||||
@@ -30,6 +32,7 @@ from nerfstudio.pipelines.base_pipeline import Pipeline
|
||||
from nerfstudio.utils import writer
|
||||
from nerfstudio.utils.eval_utils import eval_setup
|
||||
from nerfstudio.viewer.server.viewer_state import ViewerState
|
||||
from nerfstudio.viewer_beta.viewer import Viewer as ViewerBetaState
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -51,6 +54,8 @@ class RunViewer:
|
||||
"""Path to config YAML file."""
|
||||
viewer: ViewerConfigWithoutNumRays = field(default_factory=ViewerConfigWithoutNumRays)
|
||||
"""Viewer configuration"""
|
||||
vis: Literal["viewer", "viewer_beta"] = "viewer"
|
||||
"""Type of viewer"""
|
||||
|
||||
def main(self) -> None:
|
||||
"""Main function."""
|
||||
@@ -61,7 +66,7 @@ class RunViewer:
|
||||
)
|
||||
num_rays_per_chunk = config.viewer.num_rays_per_chunk
|
||||
assert self.viewer.num_rays_per_chunk == -1
|
||||
config.vis = "viewer"
|
||||
config.vis = self.vis
|
||||
config.viewer = self.viewer.as_viewer_config()
|
||||
config.viewer.num_rays_per_chunk = num_rays_per_chunk
|
||||
|
||||
@@ -83,13 +88,24 @@ def _start_viewer(config: TrainerConfig, pipeline: Pipeline, step: int):
|
||||
"""
|
||||
base_dir = config.get_base_dir()
|
||||
viewer_log_path = base_dir / config.viewer.relative_log_filename
|
||||
viewer_state = ViewerState(
|
||||
config.viewer,
|
||||
log_filename=viewer_log_path,
|
||||
datapath=pipeline.datamanager.get_datapath(),
|
||||
pipeline=pipeline,
|
||||
)
|
||||
banner_messages = [f"Viewer at: {viewer_state.viewer_url}"]
|
||||
banner_messages = None
|
||||
viewer_state = None
|
||||
if config.vis == "viewer":
|
||||
viewer_state = ViewerState(
|
||||
config.viewer,
|
||||
log_filename=viewer_log_path,
|
||||
datapath=pipeline.datamanager.get_datapath(),
|
||||
pipeline=pipeline,
|
||||
)
|
||||
banner_messages = [f"Viewer at: {viewer_state.viewer_url}"]
|
||||
if config.vis == "viewer_beta":
|
||||
viewer_state = ViewerBetaState(
|
||||
config.viewer,
|
||||
log_filename=viewer_log_path,
|
||||
datapath=base_dir,
|
||||
pipeline=pipeline,
|
||||
)
|
||||
banner_messages = [f"Viewer Beta at: {viewer_state.viewer_url}"]
|
||||
|
||||
# We don't need logging, but writer.GLOBAL_BUFFER needs to be populated
|
||||
config.logging.local_writer.enable = False
|
||||
@@ -100,7 +116,8 @@ def _start_viewer(config: TrainerConfig, pipeline: Pipeline, step: int):
|
||||
dataset=pipeline.datamanager.train_dataset,
|
||||
train_state="completed",
|
||||
)
|
||||
viewer_state.viser_server.set_training_state("completed")
|
||||
if isinstance(viewer_state, ViewerState):
|
||||
viewer_state.viser_server.set_training_state("completed")
|
||||
viewer_state.update_scene(step=step)
|
||||
while True:
|
||||
time.sleep(0.01)
|
||||
|
||||
@@ -17,6 +17,8 @@ Miscellaneous helper code.
|
||||
"""
|
||||
|
||||
|
||||
from inspect import currentframe
|
||||
import typing
|
||||
import platform
|
||||
from typing import Any, Callable, Dict, List, Optional, TypeVar, Union
|
||||
import warnings
|
||||
@@ -182,3 +184,32 @@ def torch_compile(*args, **kwargs):
|
||||
return lambda x: x
|
||||
else:
|
||||
return torch.compile(*args, **kwargs)
|
||||
|
||||
|
||||
def get_orig_class(obj, default=None):
|
||||
"""Returns the __orig_class__ class of `obj` even when it is not initialized in __init__ (Python>=3.8).
|
||||
|
||||
Workaround for https://github.com/python/typing/issues/658.
|
||||
Inspired by https://github.com/Stewori/pytypes/pull/53.
|
||||
"""
|
||||
try:
|
||||
return object.__getattribute__(obj, "__orig_class__")
|
||||
except AttributeError:
|
||||
cls = object.__getattribute__(obj, "__class__")
|
||||
try:
|
||||
is_type_generic = isinstance(cls, typing.GenericMeta) # type: ignore
|
||||
except AttributeError: # Python 3.8
|
||||
is_type_generic = issubclass(cls, typing.Generic)
|
||||
if is_type_generic:
|
||||
frame = currentframe().f_back.f_back # type: ignore
|
||||
try:
|
||||
while frame:
|
||||
try:
|
||||
res = frame.f_locals["self"]
|
||||
if res.__origin__ is cls:
|
||||
return res
|
||||
except (KeyError, AttributeError):
|
||||
frame = frame.f_back
|
||||
finally:
|
||||
del frame
|
||||
return default
|
||||
@@ -243,6 +243,8 @@ class RenderStateMachine(threading.Thread):
|
||||
image_height: the maximum image height that can be rendered in the time budget
|
||||
image_width: the maximum image width that can be rendered in the time budget
|
||||
"""
|
||||
if aspect_ratio == 0:
|
||||
aspect_ratio = 0.001
|
||||
max_res = self.viewer.control_panel.max_res
|
||||
if self.state == "high":
|
||||
# high res is always static
|
||||
|
||||
@@ -118,8 +118,8 @@ class Viewer:
|
||||
def _(_: viser.CameraHandle) -> None:
|
||||
R = vtf.SO3(wxyz=client.camera.wxyz)
|
||||
R = R @ vtf.SO3.from_x_radians(np.pi)
|
||||
R = torch.tensor(R.as_matrix())
|
||||
pos = torch.tensor(client.camera.position, dtype=torch.float64) / VISER_NERFSTUDIO_SCALE_RATIO
|
||||
R = torch.tensor(R.as_matrix(), dtype=torch.float32)
|
||||
pos = torch.tensor(client.camera.position, dtype=torch.float32) / VISER_NERFSTUDIO_SCALE_RATIO
|
||||
c2w = torch.concatenate([R, pos[:, None]], dim=1)
|
||||
self.camera_state = CameraState(fov=client.camera.fov, aspect=client.camera.aspect, c2w=c2w)
|
||||
self.render_statemachine.action(RenderAction("move", self.camera_state))
|
||||
|
||||
@@ -436,5 +436,5 @@ class ViewerVec3(ViewerParameter[Tuple[float, float, float]]):
|
||||
|
||||
def _create_gui_handle(self, viser_server: ViserServer) -> None:
|
||||
self.gui_handle = viser_server.add_gui_vector3(
|
||||
self.name, self.default_value, self.step, disabled=self.disabled, hint=self.hint
|
||||
self.name, self.default_value, step=self.step, disabled=self.disabled, hint=self.hint
|
||||
)
|
||||
+2
-1
@@ -43,13 +43,14 @@ dependencies = [
|
||||
"pyngrok>=5.1.0",
|
||||
"python-socketio>=5.7.1",
|
||||
"pyquaternion>=0.9.9",
|
||||
"rawpy>=0.18.1",
|
||||
"requests",
|
||||
"rich>=12.5.1",
|
||||
"scikit-image>=0.19.3",
|
||||
"tensorboard>=2.13.0",
|
||||
"torch>=1.13.1",
|
||||
"torchvision>=0.14.1",
|
||||
"torchmetrics[image]>=0.9.3",
|
||||
"torchmetrics[image]>=1.0.1",
|
||||
"typing_extensions>=4.4.0",
|
||||
"viser>=0.0.12",
|
||||
"nuscenes-devkit>=1.1.1",
|
||||
|
||||
@@ -1,3 +1,4 @@
|
||||
import pickle
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
@@ -52,18 +53,49 @@ def config():
|
||||
def test_data_manager_type_inference(config):
|
||||
# Mock for a faster test
|
||||
|
||||
assert VanillaDataManager(config).dataset_type is InputDataset
|
||||
assert VanillaDataManager[DepthDataset](config).dataset_type is DepthDataset
|
||||
assert VanillaDataManager(config).dataset_type is InputDataset
|
||||
|
||||
class tmp2(VanillaDataManager[DepthDataset]):
|
||||
pass
|
||||
|
||||
assert tmp2(config).dataset_type is DepthDataset
|
||||
|
||||
class tmp(VanillaDataManager):
|
||||
pass
|
||||
|
||||
assert tmp(config).dataset_type is InputDataset
|
||||
|
||||
class tmp2(VanillaDataManager[DepthDataset]):
|
||||
pass
|
||||
|
||||
assert tmp2(config).dataset_type is DepthDataset
|
||||
class _pickle_enabled_tmp(VanillaDataManager):
|
||||
pass
|
||||
|
||||
|
||||
class _pickle_enabled_tmp2(VanillaDataManager[DepthDataset]):
|
||||
pass
|
||||
|
||||
|
||||
def test_data_manager_type_can_be_pickled(config):
|
||||
# Mock for a faster test
|
||||
assert VanillaDataManager[DepthDataset](config).dataset_type is DepthDataset
|
||||
obj = pickle.loads(pickle.dumps(VanillaDataManager[DepthDataset](config)))
|
||||
assert obj.dataset_type is DepthDataset
|
||||
assert isinstance(obj, VanillaDataManager)
|
||||
|
||||
assert VanillaDataManager(config).dataset_type is InputDataset
|
||||
obj = pickle.loads(pickle.dumps(VanillaDataManager(config)))
|
||||
assert obj.dataset_type is InputDataset
|
||||
assert isinstance(obj, VanillaDataManager)
|
||||
|
||||
assert _pickle_enabled_tmp(config).dataset_type is InputDataset
|
||||
obj = pickle.loads(pickle.dumps(_pickle_enabled_tmp(config)))
|
||||
assert obj.dataset_type is InputDataset
|
||||
assert isinstance(obj, _pickle_enabled_tmp)
|
||||
|
||||
assert _pickle_enabled_tmp2(config).dataset_type is DepthDataset
|
||||
obj = pickle.loads(pickle.dumps(_pickle_enabled_tmp2(config)))
|
||||
assert obj.dataset_type is DepthDataset
|
||||
assert isinstance(obj, _pickle_enabled_tmp2)
|
||||
|
||||
|
||||
def test_data_manager_type_can_be_serialized(config):
|
||||
|
||||
@@ -4,11 +4,11 @@ Test the fields
|
||||
import torch
|
||||
|
||||
from nerfstudio.cameras.rays import Frustums, RaySamples
|
||||
from nerfstudio.fields.instant_ngp_field import TCNNInstantNGPField
|
||||
from nerfstudio.fields.nerfacto_field import NerfactoField
|
||||
|
||||
|
||||
def test_tcnn_instant_ngp_field():
|
||||
"""Test the tiny-cuda-nn field"""
|
||||
def test_nerfacto_field():
|
||||
"""Test the Nerfacto field"""
|
||||
try:
|
||||
import tinycudann as tcnn # noqa: F401
|
||||
except ModuleNotFoundError as e:
|
||||
@@ -18,9 +18,11 @@ def test_tcnn_instant_ngp_field():
|
||||
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
||||
aabb_scale = 1.0
|
||||
aabb = torch.tensor(
|
||||
[[-aabb_scale, -aabb_scale, -aabb_scale], [aabb_scale, aabb_scale, aabb_scale]], dtype=torch.float32
|
||||
).to(device)
|
||||
field = TCNNInstantNGPField(aabb)
|
||||
[[-aabb_scale, -aabb_scale, -aabb_scale], [aabb_scale, aabb_scale, aabb_scale]],
|
||||
dtype=torch.float32,
|
||||
device=device,
|
||||
)
|
||||
field = NerfactoField(aabb, num_images=1).to(device)
|
||||
num_rays = 1024
|
||||
num_samples = 256
|
||||
positions = torch.rand((num_rays, num_samples, 3), dtype=torch.float32, device=device)
|
||||
@@ -32,9 +34,16 @@ def test_tcnn_instant_ngp_field():
|
||||
ends=torch.zeros((*directions.shape[:-1], 1), device=device),
|
||||
pixel_area=torch.ones((*directions.shape[:-1], 1), device=device),
|
||||
)
|
||||
ray_samples = RaySamples(frustums=frustums)
|
||||
ray_samples = RaySamples(
|
||||
frustums=frustums,
|
||||
camera_indices=torch.zeros(
|
||||
(num_rays, 1, 1),
|
||||
device=device,
|
||||
dtype=torch.int32,
|
||||
),
|
||||
)
|
||||
field.forward(ray_samples)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
test_tcnn_instant_ngp_field()
|
||||
test_nerfacto_field()
|
||||
@@ -4,7 +4,7 @@ MLP Test
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
from nerfstudio.field_components import MLP
|
||||
from nerfstudio.field_components.mlp import MLP
|
||||
|
||||
|
||||
def test_mlp():
|
||||
|
||||
Reference in new issue
Block a user