diff --git a/.dockerignore b/.dockerignore
index e1590ed27..92619bde0 100644
--- a/.dockerignore
+++ b/.dockerignore
@@ -12,7 +12,7 @@ build/
develop-eggs/
dist/
downloads/
-!scripts/downloads/
+!nerfstudio/scripts/downloads/
eggs/
.eggs/
lib/
diff --git a/.github/workflows/core_code_checks.yml b/.github/workflows/core_code_checks.yml
index 86ff5ccca..3e30fba7d 100644
--- a/.github/workflows/core_code_checks.yml
+++ b/.github/workflows/core_code_checks.yml
@@ -15,10 +15,10 @@ jobs:
steps:
- uses: actions/checkout@v3
- - name: Set up Python 3.7.13
+ - name: Set up Python 3.8.13
uses: actions/setup-python@v4
with:
- python-version: '3.7.13'
+ python-version: '3.8.13'
- uses: actions/cache@v2
with:
path: ${{ env.pythonLocation }}
@@ -28,17 +28,17 @@ jobs:
pip install --upgrade --upgrade-strategy eager -e .[dev]
- name: Run license checks
run: |
- ./scripts/licensing/license_headers.sh --check
+ ./nerfstudio/scripts/licensing/license_headers.sh --check
- name: Check notebook cell metadata
run: |
- python ./scripts/docs/add_nb_tags.py --check
+ python ./nerfstudio/scripts/docs/add_nb_tags.py --check
- name: Run isort
- run: isort docs/ nerfstudio/ scripts/ tests/ --profile black --check
+ run: isort docs/ nerfstudio/ tests/ --profile black --check
- name: Run Black
- run: black docs/ nerfstudio/ scripts/ tests/ --check
+ run: black docs/ nerfstudio/ tests/ --check
- name: Python Pylint
run: |
- pylint nerfstudio tests scripts
+ pylint nerfstudio tests
- name: Test with pytest
run: |
pytest
diff --git a/.gitignore b/.gitignore
index ab8a4e108..7f1688d59 100644
--- a/.gitignore
+++ b/.gitignore
@@ -12,7 +12,7 @@ build/
develop-eggs/
dist/
downloads/
-!scripts/downloads/
+!nerfstudio/scripts/downloads/
eggs/
.eggs/
lib/
@@ -171,6 +171,7 @@ events.out.*
# Data
data
!*/data
+!docs/reference/api/data/
# Misc
old/
diff --git a/.vscode/launch.json b/.vscode/launch.json
index 118282928..8719fd8a1 100644
--- a/.vscode/launch.json
+++ b/.vscode/launch.json
@@ -30,7 +30,7 @@
"name": "Python: train",
"type": "python",
"request": "launch",
- "program": "scripts/train.py",
+ "program": "nerfstudio/scripts/train.py",
"console": "integratedTerminal",
"args": [
"instant_ngp",
@@ -42,7 +42,7 @@
"name": "Python: train ngp",
"type": "python",
"request": "launch",
- "program": "scripts/train.py",
+ "program": "nerfstudio/scripts/train.py",
"console": "integratedTerminal",
"args": ["instant_ngp"]
},
@@ -50,7 +50,7 @@
"name": "Python: train ngp nerfstudio",
"type": "python",
"request": "launch",
- "program": "scripts/train.py",
+ "program": "nerfstudio/scripts/train.py",
"console": "integratedTerminal",
"args": [
"instant_ngp",
@@ -70,7 +70,7 @@
"name": "Python: train ngp-friends",
"type": "python",
"request": "launch",
- "program": "scripts/train.py",
+ "program": "nerfstudio/scripts/train.py",
"console": "integratedTerminal",
"args": [
"instant_ngp",
@@ -89,7 +89,7 @@
"name": "Python: train semantic_nerfw",
"type": "python",
"request": "launch",
- "program": "scripts/train.py",
+ "program": "nerfstudio/scripts/train.py",
"console": "integratedTerminal",
"args": ["semantic_nerf"]
},
@@ -97,10 +97,17 @@
"name": "Python: NeuS on Replica",
"type": "python",
"request": "launch",
+<<<<<<< HEAD
"program": "scripts/train.py",
"console": "integratedTerminal",
"justMyCode": false,
"env": {"CUDA_VISIBLE_DEVICES":"0"},
+=======
+ "program": "nerfstudio/scripts/train.py",
+ "console": "integratedTerminal",
+ "justMyCode": false,
+ "env": { "CUDA_VISIBLE_DEVICES": "0" },
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
"args": [
"neus",
"--pipeline.model.sdf-field.inside-outside=True",
@@ -112,5 +119,45 @@
"--include_mono_prior=True"
]
},
+<<<<<<< HEAD
+=======
+ {
+ "name": "Python: NeuS-facto on Replica",
+ "type": "python",
+ "request": "launch",
+ "program": "nerfstudio/scripts/train.py",
+ "console": "integratedTerminal",
+ "justMyCode": false,
+ "env": { "CUDA_VISIBLE_DEVICES": "0" },
+ "args": [
+ "neus-facto",
+ "--pipeline.model.sdf-field.inside-outside=True",
+ "--pipeline.model.mono-depth-loss-mult=0.1",
+ "--pipeline.model.mono-normal-loss-mult=0.05",
+ "--vis=wandb",
+ "sdfstudio-data",
+ "--data=data/sdfstudio-demo-data/replica-room0",
+ "--include_mono_prior=True"
+ ]
+ },
+ {
+ "name": "Python: NeuS-facto on DTU (no mono-prior)",
+ "type": "python",
+ "request": "launch",
+ "program": "nerfstudio/scripts/train.py",
+ "console": "integratedTerminal",
+ "justMyCode": false,
+ "env": { "CUDA_VISIBLE_DEVICES": "0" },
+ "args": [
+ "neus-facto",
+ "--pipeline.model.sdf-field.inside-outside=False",
+ "--vis=wandb",
+ "sdfstudio-data",
+ "--data=data/sdfstudio-demo-data/dtu-scan65",
+ "--include_mono_prior=False",
+ "--auto-orient=True"
+ ]
+ }
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
]
}
diff --git a/.vscode/settings.json b/.vscode/settings.json
index 5e3f61611..90f5ae01c 100644
--- a/.vscode/settings.json
+++ b/.vscode/settings.json
@@ -121,5 +121,6 @@
"__node_handle": "cpp"
},
"python.analysis.typeCheckingMode": "basic",
- "python.analysis.diagnosticMode": "workspace"
+ "python.analysis.diagnosticMode": "workspace",
+ "eslint.packageManager": "yarn"
}
diff --git a/README.md b/README.md
index 8730cb20a..2ce5b3b07 100644
--- a/README.md
+++ b/README.md
@@ -59,12 +59,14 @@
# About
+_It’s as simple as plug and play with nerfstudio!_
+
Nerfstudio provides a simple API that allows for a simplified end-to-end process of creating, training, and testing NeRFs.
The library supports a **more interpretable implementation of NeRFs by modularizing each component.**
With more modular NeRFs, we hope to create a more user-friendly experience in exploring the technology.
-Nerfstudio is a contributor-friendly repo with the goal of building a community where users can more easily build upon each other's contributions.
-It’s as simple as plug and play with nerfstudio!
+This is a contributor-friendly repo with the goal of building a community where users can more easily build upon each other's contributions.
+Nerfstudio initially launched as an opensource project by Berkeley students in [KAIR lab](https://people.eecs.berkeley.edu/~kanazawa/index.html#kair) at [Berkeley AI Research (BAIR)](https://bair.berkeley.edu/) in October 2022 as a part of a research project ([paper](https://arxiv.org/abs/2302.04264)). It is currently developed by Berkeley students and community contributors.
We are committed to providing learning resources to help you understand the basics of (if you're just getting started), and keep up-to-date with (if you're a seasoned veteran) all things NeRF. As researchers, we know just how hard it is to get onboarded with this next-gen technology. So we're here to help with tutorials, documentation, and more!
@@ -85,7 +87,7 @@ You must have an NVIDIA video card with CUDA installed on the system. This libra
### Create environment
-Nerfstudio requires `python >= 3.7`. We recommend using conda to manage dependencies. Make sure to install [Conda](https://docs.conda.io/en/latest/miniconda.html) before proceeding.
+Nerfstudio requires `python >= 3.8`. We recommend using conda to manage dependencies. Make sure to install [Conda](https://docs.conda.io/en/latest/miniconda.html) before proceeding.
```bash
conda create --name nerfstudio -y python=3.8
@@ -101,14 +103,14 @@ For CUDA 11.3:
```bash
pip install torch==1.12.1+cu113 torchvision==0.13.1+cu113 -f https://download.pytorch.org/whl/torch_stable.html
-pip install git+https://github.com/NVlabs/tiny-cuda-nn/#subdirectory=bindings/torch
+pip install ninja git+https://github.com/NVlabs/tiny-cuda-nn/#subdirectory=bindings/torch
```
For CUDA 11.7:
```bash
-pip install torch torchvision functorch --extra-index-url https://download.pytorch.org/whl/cu117
-pip install git+https://github.com/NVlabs/tiny-cuda-nn/#subdirectory=bindings/torch
+pip install torch==1.13.1 torchvision functorch --extra-index-url https://download.pytorch.org/whl/cu117
+pip install ninja git+https://github.com/NVlabs/tiny-cuda-nn/#subdirectory=bindings/torch
```
See [Dependencies](https://github.com/nerfstudio-project/nerfstudio/blob/main/docs/quickstart/installation.md#dependencies)
@@ -166,7 +168,13 @@ It is possible to load a pretrained model by running
ns-train nerfacto --data data/nerfstudio/poster --load-dir {outputs/.../nerfstudio_models}
```
-This will automatically start training. If you do not want it to train, add `--viewer.start-train False` to your training command.
+## Visualize existing run
+
+Given a pretrained model checkpoint, you can start the viewer by running
+
+```bash
+ns-viewer --load-config {outputs/.../config.yml}
+```
## 3. Exporting Results
@@ -196,6 +204,7 @@ ns-export pointcloud --help
Using an existing dataset is great, but likely you want to use your own data! We support various methods for using your own data. Before it can be used in nerfstudio, the camera location and orientations must be determined and then converted into our format using `ns-process-data`. We rely on external tools for this, instructions and information can be found in the documentation.
+<<<<<<< HEAD
| Data | Capture Device | Requirements | `ns-process-data` Speed |
| ------------------------------------------------------------------------------------------------- | -------------- | ----------------------------------------------- | ----------------------- |
| 📷 [Images](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#images-and-video) | Any | [COLMAP](https://colmap.github.io/install.html) | 🐢 |
@@ -206,6 +215,19 @@ Using an existing dataset is great, but likely you want to use your own data! We
| 📱 [Record3D](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#record3d-capture) | IOS with LiDAR | [Record3D app](https://record3d.app/) | 🐇 |
| 🖥 [Metashape](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#metashape) | Any | [Metashape](https://www.agisoft.com/) | 🐇 |
| 🛠 [Custom](https://docs.nerf.studio/en/latest/quickstart/data_conventions.html) | Any | Camera Poses | 🐇 |
+=======
+| Data | Capture Device | Requirements | `ns-process-data` Speed |
+| ---------------------------------------------------------------------------------------------------- | -------------- | ----------------------------------------------------------------- | ----------------------- |
+| 📷 [Images](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#images-and-video) | Any | [COLMAP](https://colmap.github.io/install.html) | 🐢 |
+| 📹 [Video](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#images-and-video) | Any | [COLMAP](https://colmap.github.io/install.html) | 🐢 |
+| 🌎 [360 Data](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#360_data) | Any | [COLMAP](https://colmap.github.io/install.html) | 🐢 |
+| 📱 [Polycam](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#polycam-capture) | IOS with LiDAR | [Polycam App](https://poly.cam/) | 🐇 |
+| 📱 [KIRI Engine](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#kiri-capture) | IOS or Android | [KIRI Engine App](https://www.kiriengine.com/) | 🐇 |
+| 📱 [Record3D](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#record3d-capture) | IOS with LiDAR | [Record3D app](https://record3d.app/) | 🐇 |
+| 🖥 [Metashape](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#metashape) | Any | [Metashape](https://www.agisoft.com/) | 🐇 |
+| 🖥 [RealityCapture](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html#realitycapture) | Any | [RealityCapture](https://www.capturingreality.com/realitycapture) | 🐇 |
+| 🛠 [Custom](https://docs.nerf.studio/en/latest/quickstart/data_conventions.html) | Any | Camera Poses | 🐇 |
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
## 5. Advanced Options
@@ -227,9 +249,9 @@ Each model contains many parameters that can be changed, too many to list here.
ns-train nerfacto --help
```
-### Tensorboard / WandB
+### Tensorboard / WandB / Viewer
-We support three different methods to track training progress, using the viewer, [tensorboard](https://www.tensorflow.org/tensorboard), and [Weights and Biases](https://wandb.ai/site). You can specify which visualizer to use by appending `--vis {viewer, tensorboard, wandb}` to the training command. Note that only one may be used at a time. Additionally the viewer only works for methods that are fast (ie. nerfacto, instant-ngp), for slower methods like NeRF, use the other loggers.
+We support three different methods to track training progress, using the viewer, [tensorboard](https://www.tensorflow.org/tensorboard), and [Weights and Biases](https://wandb.ai/site). You can specify which visualizer to use by appending `--vis {viewer, tensorboard, wandb, viewer+wandb, viewer+tensorboard}` to the training command. Simultaneously utilizing the viewer alongside wandb or tensorboard may cause stuttering issues during evaluation steps. The viewer only works for methods that are fast (ie. nerfacto, instant-ngp), for slower methods like NeRF, use the other loggers.
# Learn More
diff --git a/colab/demo.ipynb b/colab/demo.ipynb
index 4a87f1718..0bce8b064 100644
--- a/colab/demo.ipynb
+++ b/colab/demo.ipynb
@@ -7,7 +7,11 @@
"colab_type": "text"
},
"source": [
+<<<<<<< HEAD
""
+=======
+ ""
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
]
},
{
@@ -329,7 +333,7 @@
"#@markdown
The rendered video should be at renders/output.mp4!
\n",
"\n",
"\n",
- "base_dir = \"/content/outputs/data-nerfstudio-\" + scene + \"/nerfacto/\"\n",
+ "base_dir = \"/content/outputs/unnamed/nerfacto/\"\n",
"training_run_dir = base_dir + os.listdir(base_dir)[0]\n",
"\n",
"from IPython.core.display import display, HTML\n",
diff --git a/docs/conf.py b/docs/conf.py
index 2071057b9..824a61d78 100644
--- a/docs/conf.py
+++ b/docs/conf.py
@@ -42,6 +42,7 @@ extensions = [
"sphinx_design",
"sphinx.ext.mathjax",
"sphinxext.opengraph",
+ "sphinx.ext.viewcode",
]
# List of patterns, relative to source directory, that match files and
diff --git a/docs/developer_guides/config.md b/docs/developer_guides/config.md
index 29d093f9d..bf216278f 100644
--- a/docs/developer_guides/config.md
+++ b/docs/developer_guides/config.md
@@ -118,33 +118,3 @@ Often times, you just want to play with the parameters of an existing model with
# NOTE: the dataparser and associated configurations go at the end of the command
ns-train {METHOD_NAME} --vis viewer {DATA_PARSER} --scale-factor 0.5
```
-
-### Extending Nerfstudio with custom methods
-In order to extend the Nerfstudio and register your own methods, you can package your code as a python package
-and register it with Nerfstudio as a `nerfstudio.method_configs` entrypoint in the `pyproject.toml` file.
-The Nerfstudio will automatically look for all registered methods and will register them to be used
-by method such as `ns-train`.
-
-Here is an example:
-```python
-"""my_package/my_config.py"""
-
-from nerfstudio.engine.trainer import TrainerConfig
-from nerfstudio.plugins.types import MethodSpecification
-
-MyMethod = MethodSpecification(
- config=TrainerConfig(
- method_name="my-method",
- ...
- ),
- description="Custom description"
-)
-
-"""pyproject.toml"""
-[project]
-name = "my_package"
-...
-
-[project.entry-points.'nerfstudio.method_configs']
-my-method = 'my_package.my_config:MyMethod'
-```
\ No newline at end of file
diff --git a/docs/developer_guides/debugging_tools/benchmarking.md b/docs/developer_guides/debugging_tools/benchmarking.md
index 5e213fb1b..b38c09277 100644
--- a/docs/developer_guides/debugging_tools/benchmarking.md
+++ b/docs/developer_guides/debugging_tools/benchmarking.md
@@ -9,7 +9,7 @@ To launch training jobs automatically on each of these items, you can call:
```bash
-./scripts/benchmarking/launch_train_blender.sh -m {METHOD_NAME} [-s] [-v {VIS}] [{GPU_LIST}]
+./nerfstudio/scripts/benchmarking/launch_train_blender.sh -m {METHOD_NAME} [-s] [-v {VIS}] [{GPU_LIST}]
```
Simply replace the arguments in brackets with the correct arguments.
@@ -18,31 +18,31 @@ Simply replace the arguments in brackets with the correct arguments.
- `-s`: Launch a single job per GPU.
- `-v {VIS}`: Use another visualization than wandb, which is the default. Only other option is tensorboard.
- `{GPU_LIST}`: (optional) Specify the list of gpus you want to use on your machine space separated. for instance, if you want to use GPU's 0-3, you will need to pass in `0 1 2 3`. If left empty, the script will automatically find available GPU's and distribute training jobs on the available GPUs.
-
+
:::{admonition} Tip
:class: info
-To view all the arguments and annotations, you can run `./scripts/benchmarking/launch_train_blender.sh --help`
- :::
-
+To view all the arguments and annotations, you can run `./nerfstudio/scripts/benchmarking/launch_train_blender.sh --help`
+:::
A full example would be:
- Specifying gpus
- ```bash
- ./scripts/benchmarking/launch_train_blender.sh -m nerfacto 0 1 2 3
- ```
+
+ ```bash
+ ./nerfstudio/scripts/benchmarking/launch_train_blender.sh -m nerfacto 0 1 2 3
+ ```
- Automatically find available gpus
- ```bash
- ./scripts/benchmarking/launch_train_blender.sh -m nerfacto
- ```
+ ```bash
+ ./nerfstudio/scripts/benchmarking/launch_train_blender.sh -m nerfacto
+ ```
The script will automatically launch training on all of the items and save the checkpoints in an output directory with the experiment name and current timestamp.
## Evaluating trained Blender models
-Once you have launched training, and training converges, you can test your method with `scripts/benchmarking/launch_eval_blender.sh`.
+Once you have launched training, and training converges, you can test your method with `nerfstudio/scripts/benchmarking/launch_eval_blender.sh`.
Say we ran a benchmark on 08-10-2022 for `instant-ngp`. By default, the train script will save the benchmarks in the following format:
@@ -65,7 +65,7 @@ If we wanted to run the benchmark on all the blender data for the above example,
```bash
-./scripts/benchmarking/launch_eval_blender.sh -m instant-ngp -o outputs/ -t 2022-08-10_172517 [{GPU_LIST}]
+./nerfstudio/scripts/benchmarking/launch_eval_blender.sh -m instant-ngp -o outputs/ -t 2022-08-10_172517 [{GPU_LIST}]
```
The flags used in the benchmarking script are defined as follows:
@@ -90,4 +90,4 @@ outputs
:class: warning
Since we are running multiple backgrounded processes concurrently with this script, please note the terminal logs may be messy.
- :::
+:::
diff --git a/docs/developer_guides/debugging_tools/profiling.md b/docs/developer_guides/debugging_tools/profiling.md
index ed8796cec..aabada5f4 100644
--- a/docs/developer_guides/debugging_tools/profiling.md
+++ b/docs/developer_guides/debugging_tools/profiling.md
@@ -23,7 +23,24 @@ class RayGenerator(nn.Module):
...
```
-At termination of training or end of the training run, the profiler will print out the average execution time for all of the functions that have the profiler tag.
+Alternatively, you can also time parts of the code:
+```python
+...
+
+def forward(self, ray_indices: TensorType["num_rays", 3]) -> RayBundle:
+ # implementation here
+ with profiler.time_function("code1"):
+ # some code here
+ ...
+
+ with profiler.time_function("code2"):
+ # some code here
+ ...
+ ...
+```
+
+
+At termination of training or end of the training run, the profiler will print out the average execution time for all of the functions or code blocks that have the profiler tag.
:::{admonition} Tip
:class: info
@@ -32,6 +49,14 @@ Use this profiler if there are *specific/individual functions* you want to measu
:::
+#### Profiling with PyTorch profiler
+
+If you want to profile the training or evaluation code and track the memory and CUDA kernel launches, consider using [PyTorch profiler](https://pytorch.org/tutorials/recipes/recipes/profiler_recipe.html).
+It will run the profiler for some selected step numbers, once with `CUDA_LAUNCH_BLOCKING=1`, once with `CUDA_LAUNCH_BLOCKING=0`.
+The PyTorch profiler can be enabled with `--logging.profiler=pytorch` flag.
+The outputs of the profiler are trace files stored in `{PATH_TO_MODEL_OUTPUT}/profiler_traces`, and can be loaded in Google Chrome by typing `chrome://tracing`.
+
+
#### Profiling with PySpy
If you want to profile the entire codebase, consider using [PySpy](https://github.com/benfred/py-spy).
diff --git a/docs/developer_guides/new_methods.md b/docs/developer_guides/new_methods.md
new file mode 100644
index 000000000..baafad440
--- /dev/null
+++ b/docs/developer_guides/new_methods.md
@@ -0,0 +1,89 @@
+# Adding a New Method
+
+Nerfstudio aims to offer researchers a codebase that they can utilize to extend and develop novel methods. Our vision is for users to establish a distinct repository that imports nerfstudio and overrides pipeline components to cater to specific functionality requirements of the new approach. If any of the new features require modifications to the core nerfstudio repository and can be generally useful, we encourage you to submit a PR to enable others to benefit from it.
+
+Examples are often the best way to learn, take a look at the [LERF](https://github.com/kerrj/lerf) repository for good example of how to use nerfstudio in your projects.
+
+## File Structure
+
+We recommend the following file structure:
+
+```
+├── my_method
+│ ├── __init__.py
+│ ├── my_config.py
+│ ├── custom_pipeline.py [optional]
+│ ├── custom_model.py [optional]
+│ ├── custom_field.py [optional]
+│ ├── custom_datamanger.py [optional]
+│ ├── ...
+├── pyproject.toml
+```
+
+## Registering custom model with nerfstudio
+
+In order to extend the Nerfstudio and register your own methods, you can package your code as a python package
+and register it with Nerfstudio as a `nerfstudio.method_configs` entrypoint in the `pyproject.toml` file.
+Nerfstudio will automatically look for all registered methods and will register them to be used
+by methods such as `ns-train`.
+
+First create a config file:
+
+```python
+"""my_method/my_config.py"""
+
+from nerfstudio.engine.trainer import TrainerConfig
+from nerfstudio.plugins.types import MethodSpecification
+
+MyMethod = MethodSpecification(
+ config=TrainerConfig(
+ method_name="my-method",
+ pipeline=...
+ ...
+ ),
+ description="Custom description"
+)
+```
+
+Then create a `pyproject.toml` file. This is where the entrypoint to your method is set and also where you can specify additional dependencies required by your codebase.
+
+```python
+"""pyproject.toml"""
+
+[project]
+name = "my_method"
+
+dependencies = [
+ "nerfstudio" # you may want to consider pinning the version, ie "nerfstudio==0.1.19"
+]
+
+[tool.setuptools.packages.find]
+include = ["my_method*"]
+
+[project.entry-points.'nerfstudio.method_configs']
+my-method = 'my_method.my_config:MyMethod'
+```
+
+finally run the following to register the method,
+
+```
+pip install -e .
+```
+
+When developing a new method you don't always want to install your code as a package.
+Instead, you may use the `NERFSTUDIO_METHOD_CONFIGS` environment variable to temporarily register your custom method.
+```
+export NERFSTUDIO_METHOD_CONFIGS="my-method=my_method.my_config:MyMethod"
+```
+
+## Running custom method
+
+After registering your method you should be able to run the method with,
+
+```
+ns-train my-method --data DATA_DIR
+```
+
+## Adding to the _nerf.studio_ documentation
+
+We invite researchers to contribute their own methods to our online documentation. You can find more information on how to do this {ref}`here`.
diff --git a/docs/developer_guides/pipelines/dataparsers.md b/docs/developer_guides/pipelines/dataparsers.md
index 3a38664f9..19b964e5a 100644
--- a/docs/developer_guides/pipelines/dataparsers.md
+++ b/docs/developer_guides/pipelines/dataparsers.md
@@ -30,8 +30,16 @@ class DataparserOutputs:
"""Color of dataset background."""
scene_box: SceneBox = SceneBox()
"""Scene box of dataset. Used to bound the scene or provide the scene scale depending on model."""
- semantics: Optional[Semantics] = None
- """Semantics information."""
+ mask_filenames: Optional[List[Path]] = None
+ """Filenames for any masks that are required"""
+ metadata: Dict[str, Any] = to_immutable_dict({})
+ """Dictionary of any metadata that be required for the given experiment.
+ Will be processed by the InputDataset to create any additional tensors that may be required.
+ """
+ dataparser_transform: TensorType[3, 4] = torch.eye(4)[:3, :]
+ """Transform applied by the dataparser."""
+ dataparser_scale: float = 1.0
+ """Scale applied by the dataparser."""
@dataclass
class DataParser:
@@ -115,48 +123,12 @@ You can also pull out information from the DataParserOutputs for other DataManga
ray_generator = RayGenerator(dataparser_outputs.cameras)
```
-## Our Implementations
+## Included DataParsers
-Below we enumerate the various dataparsers that we have implemented in our codebase. Feel free to use ours or add your own. Also any contributions are welcome and appreciated!
+```{toctree}
+---
+maxdepth: 2
+---
-###### Nerfstudio
-
-This is our custom dataparser. We have a script to convert images or videos with COLMAP to this format.
-
-```{button-link} https://github.com/nerfstudio-project/nerfstudio/blob/master/nerfstudio/data/dataparsers/nerfstudio_dataparser.py
-:color: primary
-:outline:
-See the code!
-```
-
-###### Blender
-
-We support the synthetic Blender dataset from the original NeRF paper.
-
-```{button-link} https://github.com/nerfstudio-project/nerfstudio/blob/master/nerfstudio/data/dataparsers/blender_dataparser.py
-:color: primary
-:outline:
-See the code!
-```
-
-###### Instant NGP
-
-This supports the Instant NGP dataset.
-
-```{button-link} https://github.com/nerfstudio-project/nerfstudio/blob/master/nerfstudio/data/dataparsers/instant_ngp_dataparser.py
-:color: primary
-:outline:
-See the code!
-```
-
-###### Record3D
-
-This dataparser can use recorded data from a >= iPhone 12 Pro using the [Record3D app](https://record3d.app/) . Record a video and export with the `EXR + JPG sequence` format. Unzip export and `rgb` folder before training.
-
-For more information on capturing with Record3D, see the [Custom Dataset Docs](/quickstart/custom_dataset.md).
-
-```{button-link} https://github.com/nerfstudio-project/nerfstudio/blob/master/nerfstudio/data/dataparsers/record3d_dataparser.py
-:color: primary
-:outline:
-See the code!
+../../reference/api/data/dataparsers
```
diff --git a/docs/developer_guides/viewer/custom_gui.md b/docs/developer_guides/viewer/custom_gui.md
new file mode 100644
index 000000000..e11381d02
--- /dev/null
+++ b/docs/developer_guides/viewer/custom_gui.md
@@ -0,0 +1,105 @@
+# Custom GUI
+
+We provide support for custom viewer GUI elements that can be defined in any `nn.Module`. Although we don't have any specific use cases in mind, here are some examples of what can be achieved with this feature:
+
+- Using text input to modify the rendering
+- Logging numerical values to the viewer
+- Using checkboxes to turn off and on losses
+- Using a dropdown to switch between appearances
+
+## Adding an Element
+
+To define a custom element, create an instance of one of the provided classes in `nerfstudio.viewer.server.viewer_elements`, and assign it as a class variable in your `nn.Module`.
+
+```python
+from nerfstudio.viewer.server.viewer_elements import ViewerNumber
+
+class MyClass(nn.Module):#must inherit from nn.Module
+ def __init__(self):
+ # Must be a class variable
+ self.custom_value = ViewerNumber(name="My Value", default_value=1.0)
+```
+**Element Hierarchy**
+The viewer recursively searches all `nn.Module` children of the base `Pipeline` object, and arranges parameters into folders based on their variable names.
+For example, a `ViewerElement` defined in `pipeline.model.field` will be in the "Custom/model/field" folder in the GUI.
+
+**Reading the value**
+To read the value of a custom element, simply access its `value` attribute. In this case it will be `1.0` unless modified by the user in the viewer.
+
+```python
+current_value = self.custom_value.value
+```
+
+**Callbacks**
+You can register a callback that will be called whenever a new value for your GUI element is available. For example, one can use a callback to update config parameters when elements are changed:
+```python
+def on_change_callback(handle: ViewerCheckbox) -> None:
+ self.config.example_parameter = handle.value
+
+self.custom_checkbox = ViewerCheckbox(
+ name="Checkbox",
+ default_value=False,
+ cb_hook=on_change_callback,
+)
+```
+
+**Thread safety**
+Note that `ViewerElement` values can change asynchronously to model execution. So, it's best practice to store the value of a viewer element once at the beginning
+of a forward pass and refer to the static variable afterwards.
+```python
+class MyModel(Model):
+ def __init__(self):
+ self.slider = ViewerSlider(name="Slider", default_value=0.5, min_value=0.0, max_value=1.0)
+
+ def get_outputs(self,ray)
+ slider_val = self.slider.value
+ #self.slider.value could change after this, unsafe to use
+
+```
+
+
+**Writing to the element**
+You can write to a viewer element in Python, which provides a convenient way to track values in your code without the need for wandb/tensorboard or relying on `print` statements.
+
+```python
+self.custom_value.value = x
+```
+
+:::{admonition} Warning
+:class: warning
+
+Updating module state while training can have unexpected side effects. It is up to the user to ensure that GUI actions are safe. Conditioning on `self.training` can help determine whether effects are applied during forward passes for training or rendering.
+:::
+
+## Example Elements
+
+```{image} imgs/custom_controls.png
+:align: center
+:width: 400
+```
+
+This was created with the following elements:
+
+```python
+from nerfstudio.viewer.server.viewer_elements import *
+
+class MyModel(Model):
+ def __init__(self):
+ self.a = ViewerButton(name="My Button", cb_hook=self.handle_btn)
+ self.b = ViewerNumber(name="Number", default_value=1.0)
+ self.c = ViewerCheckbox(name="Checkbox", default_value=False)
+ self.d = ViewerDropdown(name="Dropdown", default_value="A", options=["A", "B"])
+ self.e = ViewerSlider(name="Slider", default_value=0.5, min_value=0.0, max_value=1.0)
+ self.f = ViewerText(name="Text", default_value="Hello World")
+ self.g = ViewerVec3(name="3D Vector", default_value=(0.1, 0.7, 0.1))
+
+ self.rgb_renderer = RGBRenderer()
+...
+class RGBRenderer(nn.Module):
+ def __init__(self):
+ #lives in "Custom/model/rgb_renderer" GUI folder
+ self.a = ViewerRGB(name="F", default_value=(0.1, 0.7, 0.1))
+...
+```
+
+For more information on the available classes and their arguments, refer to the [API documentation](../../reference/api/viewer.rst)
diff --git a/docs/developer_guides/viewer/imgs/custom_controls.png b/docs/developer_guides/viewer/imgs/custom_controls.png
new file mode 100644
index 000000000..557f76b5a
Binary files /dev/null and b/docs/developer_guides/viewer/imgs/custom_controls.png differ
diff --git a/docs/developer_guides/viewer/imgs/viewer_figure.png b/docs/developer_guides/viewer/imgs/viewer_figure.png
deleted file mode 100644
index 3d0fd2846..000000000
Binary files a/docs/developer_guides/viewer/imgs/viewer_figure.png and /dev/null differ
diff --git a/docs/developer_guides/viewer/index.md b/docs/developer_guides/viewer/index.md
new file mode 100644
index 000000000..eebc29d32
--- /dev/null
+++ b/docs/developer_guides/viewer/index.md
@@ -0,0 +1,22 @@
+# Viewer
+
+> We have a real-time web viewer that requires no installation. It's available at [https://viewer.nerf.studio/](https://viewer.nerf.studio/), where you can connect to your training job.
+
+The viewer is built on [Viser](https://github.com/brentyi/viser/tree/main/viser) using [ThreeJS](https://threejs.org/) and packaged into a [ReactJS](https://reactjs.org/) application. This client viewer application will connect via a websocket to a server running on your machine.
+
+```{toctree}
+:titlesonly:
+
+custom_gui
+local_viewer
+```
+
+## Acknowledgements and references
+
+We thank the authors and contributors to the following repos, which we've started, used, and modified for our use-cases.
+
+- [Viser](https://github.com/brentyi/viser/tree/main/viser) - made by [Brent Yi](https://github.com/brentyi)
+- [meshcat-python](https://github.com/rdeits/meshcat-python) - made by [Robin Deits](https://github.com/rdeits)
+- [meshcat](https://github.com/rdeits/meshcat) - made by [Robin Deits](https://github.com/rdeits)
+- [ThreeJS](https://threejs.org/)
+- [ReactJS](https://reactjs.org/)
diff --git a/docs/developer_guides/viewer/local_viewer.md b/docs/developer_guides/viewer/local_viewer.md
new file mode 100644
index 000000000..d5912bd89
--- /dev/null
+++ b/docs/developer_guides/viewer/local_viewer.md
@@ -0,0 +1,62 @@
+# Local Server
+
+If you are unable to connect to `https://viewer.nerf.studio`, want to use Safari, or want develop the viewer codebase, you can launch your own local viewer.
+
+## Installing Dependencies
+
+```shell
+cd nerfstudio/viewer/app
+```
+
+Install npm (to install yarn) and yarn
+
+```shell
+sudo apt-get install npm
+npm install --global yarn
+```
+
+Install nvm and set the node version
+Install nvm with [instructions](https://heynode.com/tutorial/install-nodejs-locally-nvm/).
+
+```shell
+nvm install 17.8.0
+```
+
+Now running `node --version` in the shell should print "v17.8.0".
+Install package.json dependencies and start the client viewer app:
+
+```shell
+yarn install
+```
+
+## Launch the web client
+
+From the `nerfstudio/viewer/app` folder, run:
+
+```shell
+yarn start
+```
+
+The local webserver runs on port 4000 by default,
+so when `ns-train` is running, you can connect to the viewer locally at
+[http://localhost:4000/?websocket_url=ws://localhost:7007](http://localhost:4000/?websocket_url=ws://localhost:7007)
+
+## FAQ
+
+### Engine node incompatible
+
+While running `yarn install`, you run into: `The engine "node" is incompatible with this module.`
+
+**Solution**:
+
+Install nvm with instructions at [instructions](https://heynode.com/tutorial/install-nodejs-locally-nvm/).
+
+```shell
+nvm install 17.8.0
+```
+
+If you cannot install nvm, try ignoring the engines
+
+```shell
+yarn install --ignore-engines
+```
diff --git a/docs/extensions/blender_addon.md b/docs/extensions/blender_addon.md
index 2f410ff4f..8e2fa4bd2 100644
--- a/docs/extensions/blender_addon.md
+++ b/docs/extensions/blender_addon.md
@@ -1,58 +1,75 @@
# Blender VFX add-on
-
+
-
## Overview
-This Blender add-on allows for compositing with a Nerfstudio render as a background layer by generating a camera path JSON file from the Blender camera path, as well as a way to import Nerfstudio JSON files as a Blender camera baked with the Nerfstudio camera path. This is achieved by importing a mesh or point-cloud representation of the NeRF scene from Nerfstudio into Blender and getting the camera coordinates relative to the transformations of the NeRF representation. Dynamic FOV from the Blender camera is supported and will match the Nerfstudio render. Perspective and equirectangular cameras are also supported.
+This Blender add-on allows for compositing with a Nerfstudio render as a background layer by generating a camera path JSON file from the Blender camera path, as well as a way to import Nerfstudio JSON files as a Blender camera baked with the Nerfstudio camera path. This add-on also allows compositing multiple NeRF objects into a NeRF scene. This is achieved by importing a mesh or point-cloud representation of the NeRF scene from Nerfstudio into Blender and getting the camera coordinates relative to the transformations of the NeRF representation. Dynamic FOV from the Blender camera is supported and will match the Nerfstudio render. Perspective and equirectangular cameras are supported.
-## Prerequisites
-
-First install [Blender](https://www.blender.org/). The python file add-on can be downloaded from the main repo in the `scripts/blender` folder. Before starting, export the mesh or point cloud representation of the NeRF from Nerfstudio, which will be used as reference for the actual NeRF in the Blender scene. Mesh export at a good quality is preferred, however, if the export is not clear or the NeRF is very large, a detailed point cloud export will also work.
+
+
+
## Add-on Setup Instructions
-1. Open a new or existing scene to add the NeRF background in.
+1. The add-on requires Blender 3.0 or newer, install Blender [here](https://www.blender.org/).
+2. Download Blender Add-on Script
-2. Install and enable the add-on in Blender in Edit → Preferences → Add-Ons. The add-on will be visible in the Render Properties tab on the right panel.
-
-
-
-
+3. Install and enable the add-on in Blender in `Edit → Preferences → Add-Ons`. The add-on will be visible in the Render Properties tab on the right panel.
+
+
+
-3. Import the mesh or point cloud representation of the NeRF into the scene. It is preferred that a mesh is used at a good enough fidelity. You may need to crop the mesh further. Since it is used as a reference and won't be visible in the final render, only the parts that the blender animation will interact with may be necessary to import.
+4. The add-on should now be installed in the `Render Properties` panel
+
+
+
+
+## Scene Setup
+
+1. Export the mesh or point cloud representation of the NeRF from Nerfstudio, which will be used as reference for the actual NeRF in the Blender scene. Mesh export at a good quality is preferred, however, if the export is not clear or the NeRF is large, a detailed point cloud export will also work.
+
+2. Import the mesh or point cloud representation of the NeRF into the scene. You may need to crop the mesh further. Since it is used as a reference and won't be visible in the final render, only the parts that the blender animation will interact with may be necessary to import.
+
+3. Select the NeRF mesh or point cloud in the add-on.
4. Resize, position, or rotate the NeRF representation to fit your scene.
-
## Generate Nerfstudio JSON Camera Path from Blender Camera
1. There are a few ways to hide the reference mesh for the Blender render
- - In object properties, select "Shadow Catcher". This makes the representation invisible in the render, but all shadows cast on it will render. You may have to switch to the cycles renderer to see the shadow catcher option.
-
-
- - Note: This may not give ideal results if the mesh is not very clear or occludes other objects in the scene. If this is the case, you can hide the mesh from the render instead by clicking the camera button in the Outliner next to its name.
-
+ - In object properties, select "Shadow Catcher". This makes the representation invisible in the render, but all shadows cast on it will render. You may have to switch to the cycles renderer to see the shadow catcher option.
+
+
+
+
+ - Note: This may not give ideal results if the mesh is not very clear or occludes other objects in the scene. If this is the case, you can hide the mesh from the render instead by clicking the camera button in the Outliner next to its name.
+
+
+
2. Verify that the animation plays and the NeRF representation does not occlude the camera.
-3. Go to the Nerfstudio Add-on in Render Properties and expand the "Nerfstudio Path Generator" tab in the panel. Use the object selector to select the NeRF representation. Then, select the file path for the output JSON camera path file.
-4. Click "Generate JSON file". The output JSON file is named `camera_path_blender.json`.
+3. Go to the Nerfstudio Add-on in Render Properties and expand the "Nerfstudio Path Generator" tab in the panel. Use the object selector to select the NeRF representation. Then, select the file path for the output JSON camera path file.
+4. Click "Generate JSON file". The output JSON file is named `camera_path_blender.json`.
+
-
+
5. Render the NeRF with the generated camera path using Nerfstudio in the command prompt or terminal.
-6. Before rendering the Blender animation, go to the Render Properties and in the Film settings select "Transparent" so that the render will be rendered with a clear background to allow it to be composited over the NeRF render.
+6. Before rendering the Blender animation, go to the Render Properties and in the Film settings select "Transparent" so that the render will be rendered with a clear background to allow it to be composited over the NeRF render.
+
+
-
-7. Now the scene can be rendered and composited over the camera aligned Nerfstudio render.
+7. Now the scene can be rendered and composited over the camera aligned Nerfstudio render.
+
+
### Examples
@@ -63,23 +80,29 @@ First install [Blender](https://www.blender.org/). The python file add-on can be
### Additional details
-- You can also apply an environment texture to the Blender scene by using Nerfstudio to render an equirectangular image (360 image) of the NeRF from a place in the scene.
-- The settings for the Blender equirectangular camera are: "Panoramic" camera type and panorama type of "Equirectangular".
-
+- You can also apply an environment texture to the Blender scene by using Nerfstudio to render an equirectangular image (360 image) of the NeRF from a place in the scene.
+- The settings for the Blender equirectangular camera are: "Panoramic" camera type and panorama type of "Equirectangular".
+
+
+
- The generated JSON camera path follows the user specified frame start, end, and step fields in the Output Properties in Blender. The JSON file specifies the user specified x and y render resolutions at the given % in the Output Properties.
- The add-on computes the camera coordinates based on the active camera in the scene.
- FOV animated changes of the camera will be matched with the NeRF render.
- Perspective and equirectangular cameras are supported and can be selected within Blender.
- The generated JSON file can be imported into Nerfstudio. Each keyframe of the camera transform in the frame sequence in Blender will be a keyframe in Nerfstudio. The exported JSON camera path is baked, where each frame in the sequence is a keyframe. This is to ensure that frame interpolation across Nerfstudio and Blender do not differ.
+
+
- It is recommended to run the camera path in the Nerfstudio web interface with the NeRF to ensure that the NeRF is visible throughout the camera path.
- The fps and keyframe timestamps are based on the "Frame Rate" setting in the Output Properties in Blender.
- The NeRF representation can also be transformed (position, rotation, and scale) as well as animated.
+- The pivot point of the NeRF representation should not be changed
- It is recommended to export a high fidelity mesh as the NeRF representation from Nerfstudio. However if that is not possible or the scene is too large, a point cloud representation also works.
- For compositing, it is recommended to convert the video render into image frames to ensure the Blender and NeRF renders are in sync.
- Currently, dynamic camera focus is not supported.
- Fisheye and orthographic cameras are not supported.
+- A walkthrough of this section is included in the tutorial video.
## Create Blender Camera from Nerfstudio JSON Camera Path
@@ -87,7 +110,6 @@ First install [Blender](https://www.blender.org/). The python file add-on can be
-
1. Expand the "Nerfstudio Camera Generator" tab in the panel. After inputting the NeRF representation, select the JSON Nerfstudio file and click "Create Camera from JSON"
2. A new camera named "NerfstudioCamera" should appear in the viewport with the camera path and FOV of the input file. This camera's type will match the Nerfstudio input file, except fisheye cameras.
@@ -103,13 +125,97 @@ First install [Blender](https://www.blender.org/). The python file add-on can be
- Scale of the camera is not keyframed from the Nerfstudio camera path.
- This newly created camera has a sensor fit of "Vertical"
+## Compositing NeRF Objects in NeRF Environments
+
+You can composite NeRF objects into a scene with a NeRF background by rendering the cropped NeRF object along with an accumulation render as an alpha mask and compositing that over the background NeRF render.
+
+
+
+
+
+1. Import the background NeRF scene as a point cloud (or mesh, but point cloud is preferred for large scenes).
+
+2. Export a cropped NeRF mesh of the NeRF object(s)
+
+ - Open the NeRF object from the Nerfstudio viewer and select "Crop Viewport" and accordingly adjust the Scale and Center values of the bounding box to crop the NeRF scene to around the bounds of the object of interest.
+
+
+
+
+
+ - Copy over the scale and center values into the Export panel and export the NeRF object as a mesh (point cloud will also work but shadows can be rendered if the object is a mesh)
+
+ - Keep note of the scale and center values for the crop. This can be done by creating a new JSON camera path in the editor which will add a crop section towards the end of the file.
+
+
+
+
+
+3. Import the NeRF object representation. Rescale and position the scene and NeRF object and background environment. You can also animate either of them.
+
+4. (Optional) To add shadows of the NeRF object(s)
+
+ - Add a plane representing the ground of the environment. In object properties, select "Shadow Catcher" under Visibility. You may have to switch to the cycles renderer to see the shadow catcher option.
+
+ - In the object properties of the NeRF object, go to the Ray Visibility section and deselect the "Camera" option. This will hide the mesh in the Blender render, but keep its shadow.
+
+
+
+
+
+ - Render the Blender animation with only the shadow of the object on the shadow catcher visible. Render with a transparent background by selecting "Transparent" under the Film Settings in the Render Properties.
+
+5. Go to the Nerfstudio Add-on in Render Properties and expand the "Nerfstudio Path Generator" tab in the panel. Use the object selector to select the NeRF environment representation. Then, select the file path for the output JSON camera path file. Click "Generate JSON file". The output JSON file is named `camera_path_blender.json`. It is recommended to rename this JSON file to keep track of the multiple camera paths that will be used to construct the full render.
+
+6. Generate a Nerfstudio camera path now for the NeRF object. Select the object selector to select the NeRF object. Before generating the new JSON file, you may need to rename the previously generated camera path for the environment or move it to a different directory otherwise the new JSON file will overwrite it. Click "Generate JSON file". The new output JSON file is named `camera_path_blender.json`. You will need to repeat this process for each NeRF object you want to composite in your scene.
+
+7. Render the NeRF of the background environment using the generated camera path for the environment using the Nerfstudio in the command line or terminal.
+
+8. Render the NeRF object
+
+ - Open the recently generated blender Nerfstudio JSON camera path and add the crop parameters to the camera path. This section will be placed towards the end of the Blender Nerfstudio camera path after the `is_cycle` field. This can be done by copying over the crop section from the JSON camera path with the scene crop which was exported earlier. Alternatively, you can enter the crop values manually in this format.
+
+
+
+
+ - Render the NeRF object using Nerfstudio and the edited camera path in the command line or terminal. This will be the RGB render.
+
+ - Next, render the accumulation render as an alpha mask of the NeRF object by adding the command line argument `--rendered-output-names accumulation` to the render command.
+
+
+
+
+
+9. Convert each of the Nerfstudio render videos into an image sequence of frames as PNG or JPG files. This will ensure that the frames will be aligned when compositing. You can convert the video mp4 to an image sequence by creating a Blender Video Editing file and rendering the mp4 as JPGs or PNGs.
+
+10. Composite the NeRF renders in a video editing software such as Adobe Premiere Pro.
+
+ - Place the render of the Nerfstudio background environment at the lowest layer, then place the shadow render of the NeRF object if created.
+
+ - Place the RGB NeRF render of the NeRF object over the environment (and shadow if present) layers and then place the accumulation NeRF object render over the RGB NeRF object render.
+
+ - Apply a filter to use the accumulation render as an alpha mask. In Premiere Pro, apply the effect "Track Matte Key" to the RGB render and select the "Matte" as the video track of the accumulation render and under "Composite Using" select "Matte Luma".
+
+### Additional Details
+
+- The RGB and accumulation renders will need to be rendered for each NeRF cropped object in the scene, but not for the NeRF environment if it is not cropped.
+- If you will composite a shadow layer, the quality of the exported mesh of the NeRF object should have enough fidelity to cast a shadow, but the texture doesn't need to be clear.
+- If motion tracking or compositing over real camera footage, you can add planes or cubes to represent walls or doorways as shadow catcher or holdout objects. This will composite the shadow layer over the NeRF environment and help create alpha masks.
+- The pivot point of the NeRF representations should not be changed.
+- A walkthrough of this section is included in the tutorial video.
+
+### Examples
+
+
+
+
+
## Implementation Details
-For generating the JSON camera path, we iterate over the scene frame sequence (from the start to the end with step intervals) and get the camera 4x4 world matrix at each frame. The world transformation matrix gives the position, rotation, and scale of the camera. We then obtain the world matrix of the NeRF representation at each frame and transform the camera coordinates with this to get the final camera world matrix. This allows us to re-position, rotate, and scale the NeRF representation in Blender and generate the right camera path to render the NeRF accordingly in Nerfstudio. Additionally, we calculate the FOV of the camera at each frame based on the sensor fit (horizontal or vertical), angle of view, and aspect ratio.
+For generating the JSON camera path, we iterate over the scene frame sequence (from the start to the end with step intervals) and get the camera 4x4 world matrix at each frame. The world transformation matrix gives the position, rotation, and scale of the camera. We then obtain the world matrix of the NeRF representation at each frame and transform the camera coordinates with this to get the final camera world matrix. This allows us to re-position, rotate, and scale the NeRF representation in Blender and generate the right camera path to render the NeRF accordingly in Nerfstudio. Additionally, we calculate the FOV of the camera at each frame based on the sensor fit (horizontal or vertical), angle of view, and aspect ratio.
Next, we construct the list of keyframes which is very similar to the world matrices of the transformed camera matrix.
Camera properties in the JSON file are based on user specified fields such as resolution (user specified in Output Properties in Blender), camera type (Perspective or Equirectangular). In the JSON file, `aspect` is specified as 1.0, `smoothness_value` is set to 0, and `is_cycle` is set to false. The Nerfstudio render is the fps specified in Blender where the duration is the total number of frames divided by the fps.
Finally, we construct the full JSON object and write it to the file path specified by the user.
-For generating the camera from the JSON file, we create a new Blender camera based on the input file and iterate through the `camera_path` field in the JSON to get the world matrix of the object from the `matrix_to_world` and similarly get the FOV from the `fov` fields. At each iteration, we set the camera to these parameters and insert a keyframe based on the position, rotation, and scale of the camera as well as the focal length of the camera based on the vertical FOV input.
-
+For generating the camera from the JSON file, we create a new Blender camera based on the input file and iterate through the `camera_path` field in the JSON to get the world matrix of the object from the `matrix_to_world` and similarly get the FOV from the `fov` fields. At each iteration, we set the camera to these parameters and insert a keyframe based on the position, rotation, and scale of the camera as well as the focal length of the camera based on the vertical FOV input.
diff --git a/docs/extensions/imgs/sdfstudio_overview.svg b/docs/extensions/imgs/sdfstudio_overview.svg
new file mode 100644
index 000000000..9183ef453
--- /dev/null
+++ b/docs/extensions/imgs/sdfstudio_overview.svg
@@ -0,0 +1,33888 @@
+
+
+
+
diff --git a/docs/extensions/sdfstudio.md b/docs/extensions/sdfstudio.md
new file mode 100644
index 000000000..4c8f24874
--- /dev/null
+++ b/docs/extensions/sdfstudio.md
@@ -0,0 +1,51 @@
+# SDFStudio
+
+[project website](https://autonomousvision.github.io/sdfstudio/)
+
+```{image} imgs/sdfstudio_overview.svg
+:width: 800
+:align: center
+:alt: sdfstudio overview figure
+```
+
+## Overview
+
+SDFStudio is built on top of nerfstudio. It implements multiple implicit surface reconstruction methods including:
+
+- UniSurf
+- VolSDF
+- NeuS
+- MonoSDF
+- Mono-UniSurf
+- Mono-NeuS
+- Geo-NeuS
+- Geo-UniSurf
+- Geo-VolSDF
+- NeuS-acc
+- NeuS-facto
+- NeuralReconW
+
+You can learn more about these methods [here](https://github.com/autonomousvision/sdfstudio/blob/master/docs/sdfstudio-methods.md#Methods)
+
+## Surface models in nerfstudio
+
+We intend to integrate many of the SDFStudio improvments back into the nerstudio core repository.
+
+Supported methods:
+
+- NeuS
+- NeuS-facto
+
+## Citation
+
+If you use these surface based models in your research, you should consider citing the authors of SDFStudio,
+
+```none
+@misc{Yu2022SDFStudio,
+ author = {Yu, Zehao and Chen, Anpei and Antic, Bozidar and Peng, Songyou Peng and Bhattacharyya, Apratim
+ and Niemeyer, Michael and Tang, Siyu and Sattler, Torsten and Geiger, Andreas},
+ title = {SDFStudio: A Unified Framework for Surface Reconstruction},
+ year = {2022},
+ url = {https://github.com/autonomousvision/sdfstudio},
+}
+```
diff --git a/docs/index.md b/docs/index.md
index b03e8712b..ee611c573 100644
--- a/docs/index.md
+++ b/docs/index.md
@@ -60,6 +60,7 @@ Contributing
:caption: Extensions
extensions/blender_addon
extensions/unreal_engine
+extensions/sdfstudio
```
```{toctree}
@@ -74,8 +75,9 @@ nerfology/model_components/index
:hidden:
:caption: Developer Guides
+developer_guides/new_methods
developer_guides/pipelines/index
-developer_guides/viewer/viewer_overview
+developer_guides/viewer/index
developer_guides/config
developer_guides/debugging_tools/index
```
diff --git a/docs/nerfology/methods/in2n.md b/docs/nerfology/methods/in2n.md
new file mode 100644
index 000000000..bd9ebccb6
--- /dev/null
+++ b/docs/nerfology/methods/in2n.md
@@ -0,0 +1,96 @@
+# Instruct-NeRF2NeRF
+
+
Editing 3D Scenes with Instructions
+
+```{button-link} https://instruct-nerf2nerf.github.io/
+:color: primary
+:outline:
+Paper Website
+```
+
+```{button-link} https://github.com/ayaanzhaque/instruct-nerf2nerf
+:color: primary
+:outline:
+Code
+```
+
+
+
+**Instruct-NeRF2NeRF enables instruction-based editing of NeRFs via a 2D diffusion model**
+
+## Installation
+
+First install nerfstudio dependencies. Then run:
+
+```bash
+pip install git+https://github.com/ayaanzhaque/instruct-nerf2nerf
+```
+
+## Running Instruct-NeRF2NeRF
+
+Details for running Instruct-NeRF2NeRF (built with Nerfstudio!) can be found [here](https://github.com/ayaanzhaque/instruct-nerf2nerf). Once installed, run:
+
+```bash
+ns-train in2n --help
+```
+
+Three variants of Instruct-NeRF2NeRF are provided:
+
+| Method | Description | Memory | Quality |
+| ------------ | ---------------------------- | ------ | ------- |
+| `in2n` | Full model, used in paper | ~15GB | Best |
+| `in2n-small` | Half precision model | ~12GB | Good |
+| `in2n-tiny` | Half prevision with no LPIPS | ~10GB | Ok |
+
+## Method
+
+### Overview
+
+Instruct-NeRF2NeRF is a method for editing NeRF scenes with text-instructions. Given a NeRF of a scene and the collection of images used to reconstruct it, the method uses an image-conditioned diffusion model ([InstructPix2Pix](https://www.timothybrooks.com/instruct-pix2pix)) to iteratively edit the input images while optimizing the underlying scene, resulting in an optimized 3D scene that respects the edit instruction. The paper demonstrates that their method is able to edit large-scale, real-world scenes, and is able to accomplish more realistic, targeted edits than prior work.
+
+## Pipeline
+
+
+
+This section will walk through each component of the Instruct-NeRF2NeRF method.
+
+### How it Works
+
+Instruct-NeRF2NeRF gradually updates a reconstructed NeRF scene by iteratively updating the dataset images while training the NeRF:
+
+1. An image is rendered from the scene at a training viewpoint.
+2. It is edited by InstructPix2Pix given a global text instruction.
+3. The training dataset image is replaced with the edited image.
+4. The NeRF continues training as usual.
+
+### Editing Images with InstructPix2Pix
+
+InstructPix2Pix is an image-editing diffusion model which can be prompted using text instructions. More details on InstructPix2Pix can be found [here](https://www.timothybrooks.com/instruct-pix2pix).
+
+Traditionally, at inference time, InstructPix2Pix takes as input random noise and is conditioned on an image (the image to edit) and a text instruction. The strength of the edit can be controlled using the image and text classifier-free guidance scales.
+
+To update a dataset image a given viewpoint, Instruct-NeRF2NeRF first takes the original, unedited training image as image conditioning and uses the global text instruction as text conditioning. The main input to the diffusion model is a noised version of the current render from the given viewpoint. The noise is sampled from a normal distribution and scaled based on a randomly chosen timestep. Then InstructPix2Pix slowly denoises the rendered image by predicting the noised version of the image at previous timesteps until the image is fully denoised. This will produce an edited version of the input image.
+
+This process mixes the information of the diffusion model, which attempts to edit the image, the current 3D structure of the NeRF, and view-consistent information from the unedited, ground-truth images. By combining this set of information, the edit is respected while maintaining 3D consistency.
+
+The code snippet for how an image is edited in the pipeline can be found [here](https://github.com/ayaanzhaque/instruct-nerf2nerf/blob/main/in2n/ip2p.py).
+
+### Iterative Dataset Update
+
+When NeRF training starts, the dataset consists of the original, unedited images used to train the original scene. These images are saved separately to use as conditioning for InstructPix2Pix. At each optimization step, some number of NeRF optimization steps are performed, and then some number of images (often just one) are updated. The images are randomly ordered prior to training and then at each step, the images are chosen in order to edit. Once an image has been edited, it is replaced in the dataset. Importantly, at each NeRF step, rays are sampled across the entire dataset, meaning there is a mixed source of supervision between edited images and unedited images. This allows for a gradual optimization that balances maintaining the 3D structure and consistency of the NeRF as well as performing the edit.
+
+At early iterations of this process, the edited images may be inconistent with one another, as InstructPix2Pix often doesn't perform consistent edits across viewpoints. However, over time, since images are edited using the current render of the NeRF, the edits begin to converge towards a globally consistent depiction of the underlying scene. Here is an example of how the underlying dataset evolves and becomes more consistent.
+
+
+
+The traditional method for supervising NeRFs using diffusion models is to use a Score Distillation Sampling (SDS) loss, as proposed in [DreamFusion](https://dreamfusion3d.github.io/). The Iterative Dataset Update method can be viewed as a variant of SDS, as instead of updating a discrete set of images at each step, the loss is a mix of rays from various viewpoints which are edited to varying degrees. The results show that this leads to higher quality performance and more stable optimization.
+
+## Results
+
+For results, view the [project page](https://instruct-nerf2nerf.github.io/)!
diff --git a/docs/nerfology/methods/index.md b/docs/nerfology/methods/index.md
index 9eb1af0a5..441a6d705 100644
--- a/docs/nerfology/methods/index.md
+++ b/docs/nerfology/methods/index.md
@@ -1,8 +1,8 @@
# Methods
-We provide a set of pre implemented nerfstudio methods.
+We provide a set of pre implemented nerfstudio methods.
-**The goal of nerfstudio is to modularize the various NeRF techniques as much as possible.**
+**The goal of nerfstudio is to modularize the various NeRF techniques as much as possible.**
As a result, many of the techniques from these pre-implemented methods can be mixed 🎨.
@@ -20,9 +20,9 @@ To list the available methods run:
ns-train --help
```
-## Guides
+## Implemented Methods
-In addition to their implementations, we have provided guides that walk through each of these method.
+The following methods are supported in nerfstudio:
```{toctree}
:maxdepth: 1
@@ -30,5 +30,29 @@ In addition to their implementations, we have provided guides that walk through
Mip-NeRF
Nerfacto
Instant-NGP
+ Instruct-NeRF2NeRF
+ LERF
Semantic NeRF-W
+ Tetra-NeRF
```
+
+(own_method_docs)=
+
+## Adding Your Own Method
+
+If you're a researcher looking to develop new NeRF-related methods, we hope that you find nerfstudio to be a useful tool. We've provided documentation about integrating with the nerfstudio codebase, which you can find [here](../../developer_guides/new_methods.md).
+
+We also welcome additions to the list of methods above. To do this, simply create a pull request that adds a markdown file describing the model to the docs/nerfology/methods folder, and update the list in this file. For reference on the layout, you can check out the [Instruct-NeRF2NeRF](in2n) page. Please try to include the following information:
+
+- Installation instructions
+- Instructions for running the method
+- Requirements (dataset, GPU, ect)
+- Method description (the more detailed the better, treat it like a blog post)
+
+You are welcome to include assets (such as images or video) in the description, but please host them elsewhere.
+
+:::{admonition} Note
+:class: note
+
+Please ensure that the documentation is clear and easy to understand for other users who may want to try out your method.
+:::
diff --git a/docs/nerfology/methods/lerf.md b/docs/nerfology/methods/lerf.md
new file mode 100644
index 000000000..509c88fac
--- /dev/null
+++ b/docs/nerfology/methods/lerf.md
@@ -0,0 +1,91 @@
+# LERF
+
+
📎 Language Embedded Radiance Fields 🚜
+
+```{button-link} https://www.lerf.io/
+:color: primary
+:outline:
+Paper Website
+```
+
+```{button-link} https://github.com/kerrj/lerf
+:color: primary
+:outline:
+Code
+```
+
+
+
+**Grounding CLIP vectors volumetrically inside NeRF allows flexible natural language queries in 3D**
+
+## Installation
+
+First install nerfstudio dependencies. Then run:
+
+```bash
+pip install git+https://github.com/kerrj/lerf
+```
+
+## Running LERF
+
+Details for running LERF (built with Nerfstudio!) can be found [here](https://github.com/kerrj/lerf). Once installed, run:
+
+```bash
+ns-train lerf --help
+```
+
+Three variants of LERF are provided:
+
+| Method | Description | Memory | Quality |
+| ----------- | ----------------------------------------------- | ------ | ------- |
+| `lerf-big` | LERF with OpenCLIP ViT-L/14 | ~22 GB | Best |
+| `lerf` | Model with OpenCLIP ViT-B/16, used in paper | ~15 GB | Good |
+| `lerf-lite` | LERF with smaller network and less LERF samples | ~8 GB | Ok |
+
+`lerf-lite` should work on a single NVIDIA 2080.
+`lerf-big` is experimental, and needs further tuning.
+
+## Method
+
+LERF enables pixel-aligned queries of the distilled 3D CLIP embeddings without relying on region proposals, masks, or fine-tuning, supporting long-tail open-vocabulary queries hierarchically across the volume.
+
+### Multi-scale supervision
+
+To supervise language embeddings, we pre-compute an image pyramid of CLIP features for each training view. Then, each sampled ray during optimization is supervised by interpolating the CLIP embedding within this pyramid.
+
+
+
+### LERF Optimization
+
+LERF optimizes a dense, multi-scale language 3D field by volume rendering CLIP embeddings along training rays, supervising these embeddings with multi-scale CLIP features across multi-view training images.
+
+Inspired by Distilled Feature Fields (DFF), we use DINO features to regularize CLIP features. This leads to qualitative improvements in object boundaries, as CLIP embeddings in 3D can be sensitive to floaters and regions with few views.
+
+After optimization, LERF can extract 3D relevancy maps for language queries interactively in real-time.
+
+
+
+### Visualizing relevancy for text queries
+
+Set the "Output Render" type to `relevancy_0`, and enter the text query in the "LERF Positives" textbox (see image). The output render will show the 3D relevancy map for the query. View the [project page](https://lerf.io) for more examples and details about the relevancy map normalization.
+
+
+
+
+
+## Results
+
+For results, view the [project page](https://lerf.io)!
+
+Datasets used in the original paper can be found [here](https://drive.google.com/drive/folders/1LUzwEvBCE19PNYcwfmrG-9FLpZLbi4on?usp=sharing).
+
+```none
+@article{lerf2023,
+ author = {Kerr, Justin and Kim, Chung Min and Goldberg, Ken and Kanazawa, Angjoo and Tancik, Matthew},
+ title = {LERF: Language Embedded Radiance Fields},
+ journal = {arXiv preprint arXiv:2303.09553},
+ year = {2023},
+}
+```
diff --git a/docs/nerfology/methods/nerfacto.md b/docs/nerfology/methods/nerfacto.md
index a38f91bff..c1137884a 100644
--- a/docs/nerfology/methods/nerfacto.md
+++ b/docs/nerfology/methods/nerfacto.md
@@ -7,13 +7,21 @@
```bash
ns-train nerfacto --help
```
-
+
+We provide a few additional variants:
+
+| Method | Description | Memory | Speed |
+| ---------------- | --------------------- | ------ | ------ |
+| `nerfacto` | Default Model | ~6GB | Fast |
+| `nerfacto-big` | Larger higher quality | ~12GB | Slower |
+| `depth-nerfacto` | Supervise on depth | ~6GB | Fast |
+
## Method
-
+
### Overview
-
+
We created the nerfacto model to act as our default for real data captures of static scenes. The model is not existing published work, but rather a combination of many published methods that we have found work well for real data. This guide discusses the details of the model, understanding the [NeRF model](./nerf.md) is a prerequisite.
-
+
```{admonition} TLDR
We combine the following techniques in this model:
* Camera pose refinement
@@ -22,55 +30,55 @@ We combine the following techniques in this model:
* Scene contraction
* Hash encoding
```
-
+
```{warning}
🏗️ This guide is under construction 🏗️
```
-
+
## Pipeline
-
+
```{image} imgs/nerfacto/models_nerfacto_pipeline-light.png
:align: center
:class: only-light
```
-
+
```{image} imgs/nerfacto/models_nerfacto_pipeline-dark.png
:align: center
:class: only-dark
```
-
+
Here is an overview pipeline for nerfacto, we will walk through each component in this guide.
-
+
### Pose Refinement
-
+
It is not uncommon to have errors in the predicted camera poses. This is even more of a factor when using poses acquired from devices such as phones (ie. if you use the Record3D IOS app to capture data). Misaligned poses result in both cloudy artifacts in the scene and a reduction of sharpness and details. The NeRF framework allows us to backpropagate loss gradients to the input pose calculations. We can use this information to optimize and refine the poses.
-
+
### Piecewise Sampler
-
+
We use a Piecewise sampler to produce the initial set of samples of the scene. This sampler allocates half of the samples uniformly up to a distance of 1 from the camera. The remaining samples are distributed such that the step size increases with each sample. The step size is chosen such that the [frustums](../model_components/visualize_samples.ipynb) are scaled versions of themselves. By increasing the step sizes, we are able to sample distant objects will still having a dense set of samples for nearby objects.
-
+
### Proposal Sampler
-
+
The proposal sampler consolidates the sample locations to the regions of the scene that contribute most to the final render (typically the first surface intersection). This greatly improves reconstruction quality. The proposal network sampler requires a density function for the scene. The density function can be implemented in a variety of ways, we find that using a small fused-mlp with a hash encoding has sufficient accuracy and is fast. The proposal network sampler can be chained together with multiple density functions to further consolidate the sampling. We have found that two density functions are better than one. Larger than 2 leads to diminishing returns.
-
+
#### Density Field
-
+
The density field only needs to represent a coarse density representation of the scene to guide sampling. Combining a hash encoding with a small fused MLP (from [tiny-cuda-nn](https://github.com/NVlabs/tiny-cuda-nn)) provides a fast way to query the scene. We can make it more efficient by decreasing the encoding dictionary size and number of feature levels. These simplifications have little impact on the reconstruction quality because the density function does not need to learn high frequency details during the initial passes.
-
+
### Nerfacto Field
-
+
```{image} imgs/nerfacto/models_nerfacto_field-light.png
:align: center
:class: only-light
:width: 600
```
-
+
```{image} imgs/nerfacto/models_nerfacto_field-dark.png
:align: center
:class: only-dark
:width: 600
```
-
+
```{button-link} https://github.com/nerfstudio-project/nerfstudio/blob/main/nerfstudio/models/nerfacto.py
:color: primary
:outline:
diff --git a/docs/nerfology/methods/tetranerf.md b/docs/nerfology/methods/tetranerf.md
new file mode 100644
index 000000000..e18163087
--- /dev/null
+++ b/docs/nerfology/methods/tetranerf.md
@@ -0,0 +1,77 @@
+# Tetra-NeRF
+
+
Tetra-NeRF: Representing Neural Radiance Fields Using Tetrahedra
"
+ ]
+ },
+ "metadata": {},
+ "output_type": "display_data"
+ }
+ ],
+ "source": [
+ "# COLLAPSED\n",
+ "import torch\n",
+ "from nerfstudio.cameras.rays import RayBundle\n",
+ "from nerfstudio.model_components import ray_sampler\n",
+ "import plotly.graph_objects as go\n",
+ "from plotly.subplots import make_subplots\n",
+ "\n",
+ "num_coarse_samples = 20\n",
+ "num_samples = 1000\n",
+ "near = 2\n",
+ "far = 5\n",
+ "train_stratified = False\n",
+ "\n",
+ "fig = make_subplots(\n",
+ " rows=1,\n",
+ " cols=2,\n",
+ " subplot_titles=(\"PDF\", \"Samples\"),\n",
+ ")\n",
+ "\n",
+ "uniform_sampler = ray_sampler.UniformSampler(num_samples=num_coarse_samples, train_stratified=train_stratified)\n",
+ "pdf_sampler = ray_sampler.PDFSampler(num_samples=num_samples, train_stratified=train_stratified, include_original=False)\n",
+ "\n",
+ "ray_bundle = RayBundle(\n",
+ " origins=torch.ones([1, 3]),\n",
+ " directions=torch.ones([1, 3]),\n",
+ " pixel_area=torch.ones([1, 1]),\n",
+ " nears=torch.ones([1, 1]) * near,\n",
+ " fars=torch.ones([1, 1]) * far,\n",
+ ")\n",
+ "\n",
+ "coarse_ray_samples = uniform_sampler(ray_bundle)\n",
+ "\n",
+ "# Generate arbitrary PDF\n",
+ "weights = torch.ones(num_coarse_samples)\n",
+ "weights += torch.sin(torch.linspace(0, 3 * torch.pi, num_coarse_samples))\n",
+ "weights += torch.sin(torch.linspace(0, 0.5 * torch.pi, num_coarse_samples))\n",
+ "weights -= torch.min(weights)\n",
+ "weights /= torch.sum(weights)\n",
+ "\n",
+ "samples = pdf_sampler.generate_ray_samples(ray_bundle, coarse_ray_samples, weights[None, :, None], num_samples)\n",
+ "\n",
+ "# Plotting stuff\n",
+ "x = torch.ones((num_coarse_samples * 2))\n",
+ "x[::2] = coarse_ray_samples.frustums.starts[0, :, 0]\n",
+ "x[1::2] = coarse_ray_samples.frustums.ends[0, :, 0]\n",
+ "\n",
+ "y = torch.ones((num_coarse_samples * 2))\n",
+ "y[::2] = weights\n",
+ "y[1::2] = weights\n",
+ "\n",
+ "pdf_trace = go.Scatter(x=x, y=y)\n",
+ "fig.append_trace(pdf_trace, 1, 1)\n",
+ "\n",
+ "samples_trace = go.Histogram(x=samples.frustums.starts[0, :, 0], nbinsx=100)\n",
+ "fig.append_trace(samples_trace, 1, 2)\n",
+ "\n",
+ "fig.update_yaxes(title_text=\"# Samples\", row=1, col=2)\n",
+ "fig.update_xaxes(title_text=\"Distance\", row=1, col=1)\n",
+ "fig.update_xaxes(title_text=\"Distance\", row=1, col=2)\n",
+ "\n",
+ "# Overlay both histograms\n",
+ "fig.update_layout(height=400, hovermode=False, showlegend=False, margin=dict(l=20, r=20, t=50, b=20))\n",
+ "fig.update_traces(opacity=0.7)\n",
+ "fig.show()"
+ ]
+ }
+ ],
+ "metadata": {
+ "kernelspec": {
+ "display_name": "Python 3",
+ "language": "python",
+ "name": "python3"
+ },
+ "language_info": {
+ "codemirror_mode": {
+ "name": "ipython",
+ "version": 3
+ },
+ "file_extension": ".py",
+ "mimetype": "text/x-python",
+ "name": "python",
+ "nbconvert_exporter": "python",
+ "pygments_lexer": "ipython3",
+ "version": "3.10.7"
+ },
+ "vscode": {
+ "interpreter": {
+ "hash": "916dbcbb3f70747c44a77c7bcd40155683ae19c65e1c03b4aa3499c5328201f1"
+ }
+ }
+ },
+ "nbformat": 4,
+ "nbformat_minor": 2
}
diff --git a/docs/quickstart/custom_dataset.md b/docs/quickstart/custom_dataset.md
index 4295bf4bc..5132df1c6 100644
--- a/docs/quickstart/custom_dataset.md
+++ b/docs/quickstart/custom_dataset.md
@@ -5,7 +5,7 @@ Training model on existing datasets is only so fun. If you would like to train o
To process your own data run:
```bash
-ns-process-data {video,images,polycam,insta360,record3d} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR}
+ns-process-data {video,images,polycam,record3d} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR}
```
A full set of arguments can be found {doc}`here`.
@@ -20,6 +20,7 @@ We Currently support the following custom data types:
| 📱 [KIRI Engine](kiri) | IOS or Android | [KIRI Engine App](https://www.kiriengine.com/) | 🐇 |
| 📱 [Record3D](record3d) | IOS with LiDAR | [Record3D app](https://record3d.app/) | 🐇 |
| 🖥 [Metashape](metashape) | Any | [Metashape](https://www.agisoft.com/) | 🐇 |
+| 🖥 [RealityCapture](realitycapture) | Any | [RealityCapture](https://www.capturingreality.com/realitycapture) | 🐇 |
(images_and_video)=
@@ -33,12 +34,6 @@ To assist running on custom data we have a script that will process a video or f
- COLMAP can be finicky. Try your best to capture overlapping, non-blurry images.
:::
-:::{admonition} Note
-:class: warning
-
-- If COLMAP opens in a new window, simply close it to resume processing.
- :::
-
### Processing Data
```bash
@@ -264,6 +259,8 @@ ns-train nerfacto --data {output directory}
## Metashape
+All images must use the same sensor type (but multiple sensors are supported).
+
1. Align your images using Metashape. `File -> Workflow -> Align Photos...`
```{image} https://user-images.githubusercontent.com/3310961/203389662-12760210-2b52-49d4-ab21-4f23bfa4a2b3.png
@@ -292,6 +289,29 @@ ns-process-data metashape --data {data directory} --xml {xml file} --output-dir
ns-train nerfacto --data {output directory}
```
+<<<<<<< HEAD
+=======
+(realitycapture)=
+
+## RealityCapture
+
+1. Align your images using RealityCapture. `ALIGNMENT -> Align Images`
+
+2. Export the camera alignment as a `csv` file. Choose `Internal/External camera parameters`
+
+3. Convert the data to the nerfstudio format.
+
+```bash
+ns-process-data realitycapture --data {data directory} --csv {csv file} --output-dir {output directory}
+```
+
+4. Train with nerfstudio!
+
+```bash
+ns-train nerfacto --data {output directory}
+```
+
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
(360_data)=
## 360 Data (Equirectangular)
@@ -303,10 +323,17 @@ Equirectangular data is data that has been taken by a 360 camera such as Insta36
For a set of equirectangular images, process the data using the following command:
```bash
+<<<<<<< HEAD
ns-process-data images --camera-type equirectangular --images-per-equirect {8, or 14} --data {data directory} --output-dir {output directory}
```
The images-per-equirect argument is the number of images that will be sampled from each equirectangular image. We have found that 8 images per equirectangular image is sufficient for most use cases so it defaults to that. However, if you find that there isn't enough detail in the nerf or that colmap is having trouble aligning the images, you can try increasing the number of images per equirectangular image to 14.
+=======
+ns-process-data images --camera-type equirectangular --images-per-equirect {8, or 14} --crop-factor {top bottom left right} --data {data directory} --output-dir {output directory}
+```
+
+The images-per-equirect argument is the number of images that will be sampled from each equirectangular image. We have found that 8 images per equirectangular image is sufficient for most use cases so it defaults to that. However, if you find that there isn't enough detail in the nerf or that colmap is having trouble aligning the images, you can try increasing the number of images per equirectangular image to 14. See the video section below for details on cropping.
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
### Videos
@@ -326,4 +353,10 @@ The `crop-factor` argument is optional but often very helpful. This is because e
+<<<<<<< HEAD
This obscene mesh of human is obviously not helpful in training a nerf so we can remove it by cropping the bottom 20% of the image. This can be done by using the `--crop-factor 0 0.2 0 0` argument.
+=======
+The pixels representing the distorted hand and head are obviously not useful in training a nerf so we can remove it by cropping the bottom 20% of the image. This can be done by using the `--crop-factor 0 0.2 0 0` argument.
+
+If cropping only needs to be done from the bottom, you can use the `--crop-bottom [num]` argument which would be the same as doing `--crop-factor 0.0 [num] 0.0 0.0`
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
diff --git a/docs/quickstart/export_geometry.md b/docs/quickstart/export_geometry.md
index 28d29fc54..2ffd51895 100644
--- a/docs/quickstart/export_geometry.md
+++ b/docs/quickstart/export_geometry.md
@@ -19,7 +19,6 @@ Poisson surface reconstruction gives the highest quality meshes. See the steps b
> **Note:**
> This will only work with a Model that computes or predicts normals, e.g., nerfacto.
-
1. Train nerfacto with network settings that predict normals.
```bash
@@ -51,7 +50,7 @@ ns-export --help
Say you want to simplify and/or smooth a mesh offline, and then you want to texture it with NeRF. You can do that with the following command. It will work for any mesh filetypes that [PyMeshLab](https://pymeshlab.readthedocs.io/en/latest/) can support, for example a `.ply`.
```python
-python scripts/texture.py --load-config CONFIG.yml --input-mesh-filename FILENAME --output-dir OUTPUT_DIR
+python nerfstudio/scripts/texture.py --load-config CONFIG.yml --input-mesh-filename FILENAME --output-dir OUTPUT_DIR
```
## Dependencies
diff --git a/docs/quickstart/first_nerf.md b/docs/quickstart/first_nerf.md
index 73e40a9d8..1d71fac49 100644
--- a/docs/quickstart/first_nerf.md
+++ b/docs/quickstart/first_nerf.md
@@ -38,8 +38,6 @@ It is possible to load a pretrained model by running
ns-train nerfacto --data data/nerfstudio/poster --load-dir {outputs/.../nerfstudio_models}
```
-This will automatically start training. If you do not want it to train, add `--viewer.start-train False` to your training command.
-
## Visualize existing run
Given a pretrained model checkpoint, you can start the viewer by running
@@ -98,9 +96,9 @@ ns-train nerfacto nerfstudio-data --help
Each script will have some other minor quirks (like the training script dataparser subcommand needing to come after the model subcommand), read up on them [here](../reference/cli/index.md).
-## Tensorboard / WandB
+## Tensorboard / WandB / Viewer
-We support three different methods to track training progress, using the viewer, [tensorboard](https://www.tensorflow.org/tensorboard), and [Weights and Biases](https://wandb.ai/site). You can specify which visualizer to use by appending `--vis {viewer, tensorboard, wandb}` to the training command. Note that only one may be used at a time. Additionally the viewer only works for methods that are fast (ie. nerfacto, instant-ngp), for slower methods like NeRF, use the other loggers.
+We support three different methods to track training progress, using the viewer, [tensorboard](https://www.tensorflow.org/tensorboard), and [Weights and Biases](https://wandb.ai/site). You can specify which visualizer to use by appending `--vis {viewer, tensorboard, wandb, viewer+wandb, viewer+tensorboard}` to the training command. Simultaneously utilizing the viewer alongside wandb or tensorboard may cause stuttering issues during evaluation steps. The viewer only works for methods that are fast (ie. nerfacto, instant-ngp), for slower methods like NeRF, use the other loggers.
## Evaluating Runs
diff --git a/docs/quickstart/installation.md b/docs/quickstart/installation.md
index 950aefb2a..58f9ffe1d 100644
--- a/docs/quickstart/installation.md
+++ b/docs/quickstart/installation.md
@@ -33,7 +33,7 @@ Install CUDA 11.7. You can find CUDA download links [here](https://developer.nvi
## Create environment
-Nerfstudio requires `python >= 3.7`. We recommend using conda to manage dependencies. Make sure to install [Conda](https://docs.conda.io/en/latest/miniconda.html) before proceeding.
+Nerfstudio requires `python >= 3.8`. We recommend using conda to manage dependencies. Make sure to install [Conda](https://docs.conda.io/en/latest/miniconda.html) before proceeding.
```bash
conda create --name nerfstudio -y python=3.8
@@ -71,7 +71,7 @@ pip uninstall torch torchvision functorch
Install pytorch 1.13.1 with CUDA and [tiny-cuda-nn](https://github.com/NVlabs/tiny-cuda-nn)
```bash
-pip install torch torchvision functorch --extra-index-url https://download.pytorch.org/whl/cu117
+pip install torch==1.13.1 torchvision functorch --extra-index-url https://download.pytorch.org/whl/cu117
```
:::
@@ -79,10 +79,10 @@ pip install torch torchvision functorch --extra-index-url https://download.pytor
### tinycudann
-After pytorch, install the torch bindings for tinycudann:
+After pytorch and ninja, install the torch bindings for tinycudann:
```bash
-pip install git+https://github.com/NVlabs/tiny-cuda-nn/#subdirectory=bindings/torch
+pip install ninja git+https://github.com/NVlabs/tiny-cuda-nn/#subdirectory=bindings/torch
```
## Installing nerfstudio
diff --git a/docs/reference/api/data.rst b/docs/reference/api/data.rst
deleted file mode 100644
index de7b57abe..000000000
--- a/docs/reference/api/data.rst
+++ /dev/null
@@ -1,39 +0,0 @@
-.. _dataset:
-
-Data
-============
-
-Data Parsers
-----------------
-
-.. automodule:: nerfstudio.data.dataparsers
- :members:
- :show-inheritance:
-
-Datasets
-----------------
-
-.. automodule:: nerfstudio.data.datasets
- :members:
- :show-inheritance:
-
-Dataloaders
-----------------
-
-.. automodule:: nerfstudio.data.utils.dataloaders
- :members:
- :show-inheritance:
-
-Pixel Samplers
-----------------
-
-.. automodule:: nerfstudio.data.pixel_samplers
- :members:
- :show-inheritance:
-
-Scene Box
-----------------
-
-.. automodule:: nerfstudio.data.scene_box
- :members:
- :show-inheritance:
\ No newline at end of file
diff --git a/docs/reference/api/data/datamanagers.rst b/docs/reference/api/data/datamanagers.rst
new file mode 100644
index 000000000..43e5d6cce
--- /dev/null
+++ b/docs/reference/api/data/datamanagers.rst
@@ -0,0 +1,10 @@
+.. _datamanagers:
+
+Datamanagers
+============
+
+Base
+----------------
+
+.. automodule:: nerfstudio.data.datamanagers.base_datamanager
+ :members:
\ No newline at end of file
diff --git a/docs/reference/api/data/dataparsers.rst b/docs/reference/api/data/dataparsers.rst
new file mode 100644
index 000000000..e35f83ea0
--- /dev/null
+++ b/docs/reference/api/data/dataparsers.rst
@@ -0,0 +1,117 @@
+.. _dataparser:
+
+Data Parsers
+============
+
+* `Base Data Parser`_
+* `ARKitScenes`_
+* `Blender`_
+* `D-NeRF`_
+* `dycheck`_
+* `Instant-NGP`_
+* `Minimal`_
+* `NeRF-OSR`_
+* `Nerfstudio`_
+* `nuScenes`_
+* `Phototourism`_
+* `ScanNet`_
+* `SDFStudio`_
+* `sitcoms3D`_
+
+
+Base Data Parser
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.base_dataparser
+ :members:
+
+ARKitScenes
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.arkitscenes_dataparser
+ :members:
+ :show-inheritance:
+
+Blender
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.blender_dataparser
+ :members:
+ :show-inheritance:
+
+D-NeRF
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.dnerf_dataparser
+ :members:
+ :show-inheritance:
+
+dycheck
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.dycheck_dataparser
+ :members:
+ :show-inheritance:
+
+Instant-NGP
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.instant_ngp_dataparser
+ :members:
+ :show-inheritance:
+
+Minimal
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.minimal_dataparser
+ :members:
+ :show-inheritance:
+
+NeRF-OSR
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.nerfosr_dataparser
+ :members:
+ :show-inheritance:
+
+Nerfstudio
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.nerfstudio_dataparser
+ :members:
+ :show-inheritance:
+
+nuScenes
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.nuscenes_dataparser
+ :members:
+ :show-inheritance:
+
+Phototourism
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.phototourism_dataparser
+ :members:
+ :show-inheritance:
+
+ScanNet
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.scannet_dataparser
+ :members:
+ :show-inheritance:
+
+SDFStudio
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.sdfstudio_dataparser
+ :members:
+ :show-inheritance:
+
+sitcoms3D
+----------------
+
+.. automodule:: nerfstudio.data.dataparsers.sitcoms3d_dataparser
+ :members:
+ :show-inheritance:
diff --git a/docs/reference/api/data/datasets.rst b/docs/reference/api/data/datasets.rst
new file mode 100644
index 000000000..ee4fd1ab5
--- /dev/null
+++ b/docs/reference/api/data/datasets.rst
@@ -0,0 +1,24 @@
+.. _datasets:
+
+Datasets
+============
+
+Base
+----------------
+
+.. automodule:: nerfstudio.data.datasets.base_dataset
+ :members:
+
+SDF Dataset
+----------------
+
+.. automodule:: nerfstudio.data.datasets.sdf_dataset
+ :members:
+ :show-inheritance:
+
+Semantic Dataset
+----------------
+
+.. automodule:: nerfstudio.data.datasets.semantic_dataset
+ :members:
+ :show-inheritance:
\ No newline at end of file
diff --git a/docs/reference/api/data/index.rst b/docs/reference/api/data/index.rst
new file mode 100644
index 000000000..6e10f9384
--- /dev/null
+++ b/docs/reference/api/data/index.rst
@@ -0,0 +1,26 @@
+.. _dataset:
+
+Data
+============
+
+.. toctree::
+ :titlesonly:
+
+ dataparsers
+ datamanagers
+ datasets
+ utils
+
+Pixel Samplers
+----------------
+
+.. automodule:: nerfstudio.data.pixel_samplers
+ :members:
+ :show-inheritance:
+
+Scene Box
+----------------
+
+.. automodule:: nerfstudio.data.scene_box
+ :members:
+ :show-inheritance:
\ No newline at end of file
diff --git a/docs/reference/api/data/utils.rst b/docs/reference/api/data/utils.rst
new file mode 100644
index 000000000..5f225e6da
--- /dev/null
+++ b/docs/reference/api/data/utils.rst
@@ -0,0 +1,28 @@
+.. _datautils:
+
+Utils
+============
+
+Base
+----------------
+
+.. automodule:: nerfstudio.data.utils.colmap_parsing_utils
+ :members:
+
+Data
+----------------
+
+.. automodule:: nerfstudio.data.utils.data_utils
+ :members:
+
+Dataloader
+----------------
+
+.. automodule:: nerfstudio.data.utils.dataloaders
+ :members:
+
+Nerfstudio Collate
+-------------------
+
+.. automodule:: nerfstudio.data.utils.nerfstudio_collate
+ :members:
\ No newline at end of file
diff --git a/docs/reference/api/index.rst b/docs/reference/api/index.rst
index c1c9ce0b2..01c7d7fe7 100644
--- a/docs/reference/api/index.rst
+++ b/docs/reference/api/index.rst
@@ -8,7 +8,7 @@ TODO: Explanation of each component
.. toctree::
config
- data
+ data/index
fields
field_components/index
models
diff --git a/docs/reference/api/viewer.rst b/docs/reference/api/viewer.rst
index 508fddf68..4be105c86 100644
--- a/docs/reference/api/viewer.rst
+++ b/docs/reference/api/viewer.rst
@@ -3,6 +3,6 @@
Viewer
============
-.. automodule:: nerfstudio.viewer
+.. automodule:: nerfstudio.viewer.server.viewer_elements
:members:
:show-inheritance:
diff --git a/docs/reference/cli/index.md b/docs/reference/cli/index.md
index 9e1b8fae4..4daee6555 100644
--- a/docs/reference/cli/index.md
+++ b/docs/reference/cli/index.md
@@ -6,21 +6,22 @@ We provide a command line interface for training your own NeRFs (no coding neces
Here are the popular commands that we offer. If you've cloned the repo, you can also look at the [pyproject.toml file](https://github.com/nerfstudio-project/nerfstudio/blob/main/pyproject.toml) at the `[project.scripts]` section for details.
-| Command | Description | Filename |
-| ---------------- | -------------------------------------- | ---------------------------------- |
-| ns-install-cli | Install tab completion for all scripts | scripts/completions/install.py |
-| ns-process-data | Generate a dataset from your own data | scripts/process_data.py |
-| ns-download-data | Download existing captures | scripts/downloads/download_data.py |
-| ns-train | Generate a NeRF | scripts/train.py |
-| ns-viewer | View a trained NeRF | scripts/viewer/run_viewer.py |
-| ns-eval | Run evaluation metrics for your Model | scripts/eval.py |
-| ns-render | Render out a video of your NeRF | scripts/render.py |
-| ns-export | Export a NeRF into other formats | scripts/exporter.py |
+| Command | Description | Filename |
+| ------------------------------------ | -------------------------------------- | --------------------------------------------- |
+| [ns-install-cli](ns_install_cli) | Install tab completion for all scripts | nerfstudio/scripts/completions/install.py |
+| [ns-process-data](ns_process_data) | Generate a dataset from your own data | nerfstudio/scripts/process_data.py |
+| [ns-download-data](ns_download_data) | Download existing captures | nerfstudio/scripts/downloads/download_data.py |
+| [ns-train](ns_train) | Generate a NeRF | nerfstudio/scripts/train.py |
+| [ns-viewer](ns_viewer) | View a trained NeRF | nerfstudio/scripts/viewer/run_viewer.py |
+| [ns-eval](ns_eval) | Run evaluation metrics for your Model | nerfstudio/scripts/eval.py |
+| [ns-render](ns_render) | Render out a video of your NeRF | nerfstudio/scripts/render.py |
+| [ns-export](ns_export) | Export a NeRF into other formats | nerfstudio/scripts/exporter.py |
```{toctree}
:maxdepth: 1
:hidden:
+ns_install_cli
ns_process_data
ns_download_data
ns_train
diff --git a/docs/reference/cli/ns_download_data.md b/docs/reference/cli/ns_download_data.md
index d096b4e07..1105ef12b 100644
--- a/docs/reference/cli/ns_download_data.md
+++ b/docs/reference/cli/ns_download_data.md
@@ -2,7 +2,7 @@
```{eval-rst}
.. argparse::
- :module: scripts.downloads.download_data
+ :module: nerfstudio.scripts.downloads.download_data
:func: get_parser_fn
:prog: ns-download-data
:nodefault:
diff --git a/docs/reference/cli/ns_eval.md b/docs/reference/cli/ns_eval.md
index a794ac9e8..86e4aa0ba 100644
--- a/docs/reference/cli/ns_eval.md
+++ b/docs/reference/cli/ns_eval.md
@@ -2,7 +2,7 @@
```{eval-rst}
.. argparse::
- :module: scripts.eval
+ :module: nerfstudio.scripts.eval
:func: get_parser_fn
:prog: ns-eval
:nodefault:
diff --git a/docs/reference/cli/ns_export.md b/docs/reference/cli/ns_export.md
index cdfc54f2f..839211915 100644
--- a/docs/reference/cli/ns_export.md
+++ b/docs/reference/cli/ns_export.md
@@ -2,7 +2,7 @@
```{eval-rst}
.. argparse::
- :module: scripts.exporter
+ :module: nerfstudio.scripts.exporter
:func: get_parser_fn
:prog: ns-export
:nodefault:
diff --git a/docs/reference/cli/ns_install_cli.md b/docs/reference/cli/ns_install_cli.md
new file mode 100644
index 000000000..30fa9598f
--- /dev/null
+++ b/docs/reference/cli/ns_install_cli.md
@@ -0,0 +1,9 @@
+# ns-install-cli
+
+```{eval-rst}
+.. argparse::
+ :module: nerfstudio.scripts.completions.install
+ :func: get_parser_fn
+ :prog: ns-install-cli
+ :nodefault:
+```
diff --git a/docs/reference/cli/ns_process_data.md b/docs/reference/cli/ns_process_data.md
index bb5bd24ac..9f9540d44 100644
--- a/docs/reference/cli/ns_process_data.md
+++ b/docs/reference/cli/ns_process_data.md
@@ -8,7 +8,7 @@ You may also want to install [hloc](https://github.com/cvg/Hierarchical-Localiza
```{eval-rst}
.. argparse::
- :module: scripts.process_data
+ :module: nerfstudio.scripts.process_data
:func: get_parser_fn
:prog: ns-process-data
:nodefault:
diff --git a/docs/reference/cli/ns_render.md b/docs/reference/cli/ns_render.md
index 7a01f9bae..e006e62ee 100644
--- a/docs/reference/cli/ns_render.md
+++ b/docs/reference/cli/ns_render.md
@@ -7,7 +7,7 @@ Make sure to have [FFmpeg](https://ffmpeg.org/download.html) installed.
```{eval-rst}
.. argparse::
- :module: scripts.render
+ :module: nerfstudio.scripts.render
:func: get_parser_fn
:prog: ns-render
:nodefault:
diff --git a/docs/reference/cli/ns_viewer.md b/docs/reference/cli/ns_viewer.md
index 841472a5f..bb6333550 100644
--- a/docs/reference/cli/ns_viewer.md
+++ b/docs/reference/cli/ns_viewer.md
@@ -2,7 +2,7 @@
```{eval-rst}
.. argparse::
- :module: scripts.viewer.run_viewer
+ :module: nerfstudio.scripts.viewer.run_viewer
:func: get_parser_fn
:prog: ns-viewer
:nodefault:
diff --git a/docs/reference/contributing.md b/docs/reference/contributing.md
index a9651cbed..101cb873e 100644
--- a/docs/reference/contributing.md
+++ b/docs/reference/contributing.md
@@ -7,13 +7,14 @@ Below, we document the contribution pipeline and good-to-knows for when you're r
The project is set up for development in VSCode, we recommend using it if you plan to contribute.
## Overview
+
Below are the various tooling features our team uses to maintain this codebase.
-| Tooling | Support |
-| --------------- | ------------- |
-| Linter | [Black](https://black.readthedocs.io/en/stable/) |
-| Testing | [PyTest](https://docs.pytest.org/en/7.1.x/) |
-| Docs | [Sphinx](https://www.sphinx-doc.org/en/master/) |
+| Tooling | Support |
+| --------------- | ---------------------------------------------------------- |
+| Linter | [Black](https://black.readthedocs.io/en/stable/) |
+| Testing | [PyTest](https://docs.pytest.org/en/7.1.x/) |
+| Docs | [Sphinx](https://www.sphinx-doc.org/en/master/) |
| Docstring style | [Google](https://google.github.io/styleguide/pyguide.html) |
## Requirements
@@ -53,8 +54,8 @@ conda install -c conda-forge pandoc
:::{admonition} Attention
:class: attention
- In order to merge changes to the code base, all of these checks must be passing. If you pass these tests locally, you will likely pass on github servers as well (results in a green checkmark next to your commit).
- :::
+ In order to merge changes to the code base, all of these checks must be passing. If you pass these tests locally, you will likely pass on github servers as well (results in a green checkmark next to your commit).
+ :::
3. Open pull request! 💌
@@ -65,7 +66,7 @@ conda install -c conda-forge pandoc
Run the following to build the documentation:
```bash
-python scripts/docs/build_docs.py
+python nerfstudio/scripts/docs/build_docs.py
```
:::{admonition} Tip
@@ -84,7 +85,7 @@ If you want the code to build on save you can use [sphinx autobuild](https://git
:class: info
If changes to the structure are made, the build files may be incorrect.
- :::
+:::
```bash
pip install sphinx-autobuild
diff --git a/nerfstudio/cameras/camera_optimizers.py b/nerfstudio/cameras/camera_optimizers.py
index afd002a71..4b37f2072 100644
--- a/nerfstudio/cameras/camera_optimizers.py
+++ b/nerfstudio/cameras/camera_optimizers.py
@@ -20,13 +20,13 @@ from __future__ import annotations
import functools
from dataclasses import dataclass, field
-from typing import Type, Union
+from typing import Literal, Type, Union
import torch
import tyro
from torch import nn
from torchtyping import TensorType
-from typing_extensions import Literal, assert_never
+from typing_extensions import assert_never
from nerfstudio.cameras.lie_groups import exp_map_SE3, exp_map_SO3xR3
from nerfstudio.configs.base_config import InstantiateConfig
diff --git a/nerfstudio/cameras/camera_paths.py b/nerfstudio/cameras/camera_paths.py
index a313cad4d..9754a2bbf 100644
--- a/nerfstudio/cameras/camera_paths.py
+++ b/nerfstudio/cameras/camera_paths.py
@@ -125,10 +125,6 @@ def get_path_from_json(camera_path: Dict[str, Any]) -> Cameras:
image_height = camera_path["render_height"]
image_width = camera_path["render_width"]
- if "camera_type" in camera_path:
- camera_type = camera_path["camera_type"]
- else:
- camera_type = "perspective"
if "camera_type" not in camera_path:
camera_type = CameraType.PERSPECTIVE
diff --git a/nerfstudio/cameras/camera_utils.py b/nerfstudio/cameras/camera_utils.py
index 79490ae67..7c2364929 100644
--- a/nerfstudio/cameras/camera_utils.py
+++ b/nerfstudio/cameras/camera_utils.py
@@ -17,13 +17,12 @@ Camera transformation helper code.
"""
import math
-from typing import List, Optional, Tuple
+from typing import List, Literal, Optional, Tuple
import numpy as np
import torch
from numpy.typing import ArrayLike
from torchtyping import TensorType
-from typing_extensions import Literal
_EPS = np.finfo(float).eps * 4.0
@@ -164,8 +163,8 @@ def quaternion_matrix(quaternion: ArrayLike) -> np.ndarray:
def get_interpolated_poses(pose_a: ArrayLike, pose_b: ArrayLike, steps: int = 10) -> List[float]:
"""Return interpolation of poses with specified number of steps.
Args:
- poseA: first pose
- poseB: second pose
+ pose_a: first pose
+ pose_b: second pose
steps: number of steps the interpolated pose path should contain
"""
@@ -190,8 +189,8 @@ def get_interpolated_k(k_a, k_b, steps: int = 10) -> TensorType[3, 4]:
Returns interpolated path between two camera poses with specified number of steps.
Args:
- KA: camera matrix 1
- KB: camera matrix 2
+ k_a: camera matrix 1
+ k_b: camera matrix 2
steps: number of steps the interpolated pose path should contain
"""
Ks = []
diff --git a/nerfstudio/cameras/cameras.py b/nerfstudio/cameras/cameras.py
index e0ed08e4f..9d0fb26d8 100644
--- a/nerfstudio/cameras/cameras.py
+++ b/nerfstudio/cameras/cameras.py
@@ -17,7 +17,6 @@ Camera Models
"""
import base64
import math
-import os
from dataclasses import dataclass
from enum import Enum, auto
from typing import Dict, List, Optional, Tuple, Union
@@ -33,7 +32,6 @@ import nerfstudio.utils.poses as pose_utils
from nerfstudio.cameras import camera_utils
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.data.scene_box import SceneBox
-from nerfstudio.utils.misc import strtobool
from nerfstudio.utils.tensor_dataclass import TensorDataclass
TORCH_DEVICE = Union[torch.device, str] # pylint: disable=invalid-name
@@ -62,11 +60,7 @@ CAMERA_MODEL_TO_TYPE = {
class Cameras(TensorDataclass):
"""Dataparser outputs for the image dataset and the ray generator.
- Note: currently only supports cameras with the same principal points and types. The reason we type
- the focal lengths, principal points, and image sizes as tensors is to allow for batched cameras
- down the line in cases where your batches of camera data don't come from the same cameras.
-
- If a single value is provided, it is broadcasted to all cameras.
+ If a single value is provided, it is broadcasted to all cameras.
Args:
camera_to_worlds: Camera to world matrices. Tensor of per-image c2w matrices, in [R | t] format
@@ -79,6 +73,8 @@ class Cameras(TensorDataclass):
distortion_params: OpenCV 6 radial distortion coefficients
camera_type: Type of camera model. This will be an int corresponding to the CameraType enum.
times: Timestamps for each camera
+ metadata: Additional metadata or data needed for interpolation, will mimic shape of the cameras
+ and will be broadcasted to the rays generated from any derivative RaySamples we create with this
"""
camera_to_worlds: TensorType["num_cameras":..., 3, 4]
@@ -91,6 +87,7 @@ class Cameras(TensorDataclass):
distortion_params: Optional[TensorType["num_cameras":..., 6]]
camera_type: TensorType["num_cameras":..., 1]
times: Optional[TensorType["num_cameras", 1]]
+ metadata: Optional[Dict]
def __init__(
self,
@@ -111,6 +108,7 @@ class Cameras(TensorDataclass):
]
] = CameraType.PERSPECTIVE,
times: Optional[TensorType["num_cameras"]] = None,
+ metadata: Optional[Dict] = None,
) -> None:
"""Initializes the Cameras object.
@@ -146,9 +144,9 @@ class Cameras(TensorDataclass):
self.camera_type = self._init_get_camera_type(camera_type)
self.times = self._init_get_times(times)
- self.__post_init__() # This will do the dataclass post_init and broadcast all the tensors
+ self.metadata = metadata
- self._use_nerfacc = strtobool(os.environ.get("INTERSECT_WITH_NERFACC", "TRUE"))
+ self.__post_init__() # This will do the dataclass post_init and broadcast all the tensors
def _init_get_fc_xy(self, fc_xy: Union[float, torch.Tensor], name: str) -> torch.Tensor:
"""
@@ -631,7 +629,7 @@ class Cameras(TensorDataclass):
if distortion_params is not None:
mask = (self.camera_type[true_indices] != CameraType.EQUIRECTANGULAR.value).squeeze(-1) # (num_rays)
coord_mask = torch.stack([mask, mask, mask], dim=0)
- if mask.any():
+ if mask.any() and (distortion_params != 0).any():
coord_stack[coord_mask, :] = camera_utils.radial_and_tangential_undistort(
coord_stack[coord_mask, :].reshape(3, -1, 2),
distortion_params[mask, :],
@@ -716,13 +714,23 @@ class Cameras(TensorDataclass):
times = self.times[camera_indices, 0] if self.times is not None else None
+ metadata = (
+ self._apply_fn_to_dict(self.metadata, lambda x: x[true_indices]) if self.metadata is not None else None
+ )
+ if metadata is not None:
+ metadata["directions_norm"] = directions_norm[0].detach()
+ else:
+ metadata = {"directions_norm": directions_norm[0].detach()}
+
+ times = self.times[camera_indices, 0] if self.times is not None else None
+
return RayBundle(
origins=origins,
directions=directions,
pixel_area=pixel_area,
camera_indices=camera_indices,
times=times,
- metadata={"directions_norm": directions_norm[0].detach()},
+ metadata=metadata,
)
def to_json(
diff --git a/nerfstudio/cameras/rays.py b/nerfstudio/cameras/rays.py
index 0184b4c80..0eee58ba5 100644
--- a/nerfstudio/cameras/rays.py
+++ b/nerfstudio/cameras/rays.py
@@ -57,7 +57,11 @@ class Frustums(TensorDataclass):
return pos
def get_start_positions(self) -> TensorType[..., 3]:
+<<<<<<< HEAD
"""Calulates "start" position of frustum.
+=======
+ """Calculates "start" position of frustum.
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
Returns:
xyz positions.
@@ -193,7 +197,7 @@ class RayBundle(TensorDataclass):
"""Times at which rays are sampled"""
def set_camera_indices(self, camera_index: int) -> None:
- """Sets all of the the camera indices to a specific camera index.
+ """Sets all the camera indices to a specific camera index.
Args:
camera_index: Camera index.
diff --git a/nerfstudio/configs/base_config.py b/nerfstudio/configs/base_config.py
index 9d95cc269..22c149441 100644
--- a/nerfstudio/configs/base_config.py
+++ b/nerfstudio/configs/base_config.py
@@ -21,13 +21,18 @@ from __future__ import annotations
import warnings
from dataclasses import dataclass
from pathlib import Path
+<<<<<<< HEAD
from typing import Any, List, Optional, Tuple, Type
+=======
+from typing import Any, List, Literal, Optional, Tuple, Type
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
# model instances
from nerfstudio.utils import writer
warnings.filterwarnings("ignore", module="torchvision")
+
# Pretty printing class
class PrintableConfig: # pylint: disable=too-few-public-methods
"""Printable Config defining str function"""
@@ -116,9 +121,11 @@ class LoggingConfig(PrintableConfig):
e.g. if 20, averages will be computed over past 20 occurrences."""
local_writer: LocalWriterConfig = LocalWriterConfig(enable=True)
"""if provided, will print stats locally. if None, will disable printing"""
- enable_profiler: bool = True
- """whether to enable profiling code; prints speed of functions at the end of a program.
- profiler logs run times of functions and prints at end of training"""
+ profiler: Literal["none", "basic", "pytorch"] = "basic"
+ """how to profile the code;
+ "basic" - prints speed of all decorated functions at the end of a program.
+ "pytorch" - same as basic, but it also traces few training steps.
+ """
# Viewer related configs
@@ -128,17 +135,12 @@ class ViewerConfig(PrintableConfig):
relative_log_filename: str = "viewer_log_filename.txt"
"""Filename to use for the log file."""
- start_train: bool = True
- """whether to immediately start training upon loading viewer
- if False, will just visualize dataset but you can toggle training in viewer"""
- zmq_port: Optional[int] = None
- """The zmq port to connect to for communication. If None, find an available port."""
- launch_bridge_server: bool = True
- """whether or not to launch the bridge server"""
- websocket_port: Optional[int] = 7007
- """the default websocket port to connect to"""
- ip_address: str = "127.0.0.1"
- """the ip address where the bridge server is running"""
+ websocket_port: Optional[int] = None
+ """The websocket port to connect to. If None, find an available port."""
+ websocket_port_default: int = 7007
+ """The default websocket port to connect to if websocket_port is not specified"""
+ websocket_host: str = "0.0.0.0"
+ """The host address to bind the websocket server to."""
num_rays_per_chunk: int = 32768
"""number of rays per chunk to render with viewer"""
max_num_display_images: int = 512
@@ -146,3 +148,10 @@ class ViewerConfig(PrintableConfig):
actually used in training/evaluation. If -1, display all."""
quit_on_train_completion: bool = False
"""Whether to kill the training job when it has completed. Note this will stop rendering in the viewer."""
+<<<<<<< HEAD
+=======
+ image_format: Literal["jpeg", "png"] = "jpeg"
+ """Image format viewer should use; jpeg is lossy compression, while png is lossless."""
+ jpeg_quality: int = 90
+ """Quality tradeoff to use for jpeg compression."""
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
diff --git a/nerfstudio/configs/config_utils.py b/nerfstudio/configs/config_utils.py
index 59b1b252b..42bf7a082 100644
--- a/nerfstudio/configs/config_utils.py
+++ b/nerfstudio/configs/config_utils.py
@@ -26,6 +26,7 @@ from rich.console import Console
CONSOLE = Console()
# pylint: disable=import-outside-toplevel
+
# cannot use mutable types directly within dataclass; abstracting default factory calls
def to_immutable_dict(d: Dict[str, Any]):
"""Method to convert mutable dict to default factory dict
diff --git a/nerfstudio/configs/experiment_config.py b/nerfstudio/configs/experiment_config.py
index 765c64ef7..0439f2af6 100644
--- a/nerfstudio/configs/experiment_config.py
+++ b/nerfstudio/configs/experiment_config.py
@@ -19,11 +19,10 @@ from __future__ import annotations
from dataclasses import dataclass
from datetime import datetime
from pathlib import Path
-from typing import Any, Dict, Optional
+from typing import Any, Dict, Literal, Optional
import yaml
from rich.console import Console
-from typing_extensions import Literal
from nerfstudio.configs.base_config import (
InstantiateConfig,
@@ -50,6 +49,8 @@ class ExperimentConfig(InstantiateConfig):
"""Method name. Required to set in python or via cli"""
experiment_name: Optional[str] = None
"""Experiment name. If None, will automatically be set to dataset name"""
+ project_name: Optional[str] = "nerfstudio-project"
+ """Project name."""
timestamp: str = "{timestamp}"
"""Experiment timestamp."""
machine: MachineConfig = MachineConfig()
diff --git a/nerfstudio/configs/method_configs.py b/nerfstudio/configs/method_configs.py
index 2dcfe452c..b07bedc5e 100644
--- a/nerfstudio/configs/method_configs.py
+++ b/nerfstudio/configs/method_configs.py
@@ -21,10 +21,10 @@ from __future__ import annotations
from typing import Dict
import tyro
-from nerfacc import ContractionType
from nerfstudio.cameras.camera_optimizers import CameraOptimizerConfig
from nerfstudio.configs.base_config import ViewerConfig
+<<<<<<< HEAD
from nerfstudio.data.datamanagers.base_datamanager import VanillaDataManagerConfig
from nerfstudio.data.datamanagers.depth_datamanager import DepthDataManagerConfig
from nerfstudio.data.datamanagers.sdf_datamanager import SDFDataManagerConfig
@@ -34,6 +34,11 @@ from nerfstudio.data.datamanagers.dreamfusion_datamanager import (
from nerfstudio.data.datamanagers.semantic_datamanager import SemanticDataManagerConfig
from nerfstudio.data.datamanagers.variable_res_datamanager import (
VariableResDataManagerConfig,
+=======
+from nerfstudio.data.datamanagers.base_datamanager import (
+ VanillaDataManager,
+ VanillaDataManagerConfig,
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
)
from nerfstudio.data.dataparsers.blender_dataparser import BlenderDataParserConfig
from nerfstudio.data.dataparsers.dnerf_dataparser import DNeRFDataParserConfig
@@ -47,13 +52,21 @@ from nerfstudio.data.dataparsers.phototourism_dataparser import (
)
from nerfstudio.data.dataparsers.sdfstudio_dataparser import SDFStudioDataParserConfig
from nerfstudio.data.dataparsers.sitcoms3d_dataparser import Sitcoms3DDataParserConfig
+from nerfstudio.data.datasets.depth_dataset import DepthDataset
+from nerfstudio.data.datasets.sdf_dataset import SDFDataset
+from nerfstudio.data.datasets.semantic_dataset import SemanticDataset
from nerfstudio.engine.optimizers import AdamOptimizerConfig, RAdamOptimizerConfig
from nerfstudio.engine.schedulers import (
CosineDecaySchedulerConfig,
ExponentialDecaySchedulerConfig,
+<<<<<<< HEAD
+=======
+ MultiStepSchedulerConfig,
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
)
from nerfstudio.engine.trainer import TrainerConfig
from nerfstudio.field_components.temporal_distortions import TemporalDistortionKind
+from nerfstudio.fields.sdf_field import SDFFieldConfig
from nerfstudio.models.depth_nerfacto import DepthNerfactoModelConfig
from nerfstudio.models.dreamfusion import DreamFusionModelConfig
from nerfstudio.models.instant_ngp import InstantNGPModelConfig
@@ -62,6 +75,10 @@ from nerfstudio.models.nerfacto import NerfactoModelConfig
from nerfstudio.models.nerfplayer_nerfacto import NerfplayerNerfactoModelConfig
from nerfstudio.models.nerfplayer_ngp import NerfplayerNGPModelConfig
from nerfstudio.models.neus import NeuSModelConfig
+<<<<<<< HEAD
+=======
+from nerfstudio.models.neus_facto import NeuSFactoModelConfig
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
from nerfstudio.models.semantic_nerfw import SemanticNerfWModelConfig
from nerfstudio.models.tensorf import TensoRFModelConfig
from nerfstudio.models.vanilla_nerf import NeRFModel, VanillaModelConfig
@@ -86,6 +103,10 @@ descriptions = {
"nerfplayer-nerfacto": "NeRFPlayer with nerfacto backbone.",
"nerfplayer-ngp": "NeRFPlayer with InstantNGP backbone.",
"neus": "Implementation of NeuS. (slow)",
+<<<<<<< HEAD
+=======
+ "neus-facto": "Implementation of NeuS-Facto. (slow)",
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
}
method_configs["nerfacto"] = TrainerConfig(
@@ -100,7 +121,9 @@ method_configs["nerfacto"] = TrainerConfig(
train_num_rays_per_batch=4096,
eval_num_rays_per_batch=4096,
camera_optimizer=CameraOptimizerConfig(
- mode="SO3xR3", optimizer=AdamOptimizerConfig(lr=6e-4, eps=1e-8, weight_decay=1e-2)
+ mode="SO3xR3",
+ optimizer=AdamOptimizerConfig(lr=6e-4, eps=1e-8, weight_decay=1e-2),
+ scheduler=ExponentialDecaySchedulerConfig(lr_final=6e-6, max_steps=200000),
),
),
model=NerfactoModelConfig(eval_num_rays_per_chunk=1 << 15),
@@ -108,12 +131,52 @@ method_configs["nerfacto"] = TrainerConfig(
optimizers={
"proposal_networks": {
"optimizer": AdamOptimizerConfig(lr=1e-2, eps=1e-15),
- "scheduler": None,
+ "scheduler": ExponentialDecaySchedulerConfig(lr_final=0.0001, max_steps=200000),
},
"fields": {
"optimizer": AdamOptimizerConfig(lr=1e-2, eps=1e-15),
+ "scheduler": ExponentialDecaySchedulerConfig(lr_final=0.0001, max_steps=200000),
+ },
+ },
+ viewer=ViewerConfig(num_rays_per_chunk=1 << 15),
+ vis="viewer",
+)
+method_configs["nerfacto-big"] = TrainerConfig(
+ method_name="nerfacto",
+ steps_per_eval_batch=500,
+ steps_per_save=2000,
+ max_num_iterations=100000,
+ mixed_precision=True,
+ pipeline=VanillaPipelineConfig(
+ datamanager=VanillaDataManagerConfig(
+ dataparser=NerfstudioDataParserConfig(),
+ train_num_rays_per_batch=4096,
+ eval_num_rays_per_batch=4096,
+ camera_optimizer=CameraOptimizerConfig(
+ mode="SO3xR3", optimizer=RAdamOptimizerConfig(lr=6e-4, eps=1e-8, weight_decay=1e-3)
+ ),
+ ),
+ model=NerfactoModelConfig(
+ eval_num_rays_per_chunk=1 << 15,
+ num_nerf_samples_per_ray=128,
+ num_proposal_samples_per_ray=(512, 256),
+ hidden_dim=128,
+ hidden_dim_color=128,
+ hidden_dim_transient=128,
+ max_res=3000,
+ proposal_weights_anneal_max_num_iters=5000,
+ log2_hashmap_size=21,
+ ),
+ ),
+ optimizers={
+ "proposal_networks": {
+ "optimizer": RAdamOptimizerConfig(lr=1e-2, eps=1e-15),
"scheduler": None,
},
+ "fields": {
+ "optimizer": RAdamOptimizerConfig(lr=1e-2, eps=1e-15),
+ "scheduler": ExponentialDecaySchedulerConfig(lr_final=1e-4, max_steps=100000),
+ },
},
viewer=ViewerConfig(num_rays_per_chunk=1 << 15),
vis="viewer",
@@ -126,7 +189,8 @@ method_configs["depth-nerfacto"] = TrainerConfig(
max_num_iterations=30000,
mixed_precision=True,
pipeline=VanillaPipelineConfig(
- datamanager=DepthDataManagerConfig(
+ datamanager=VanillaDataManagerConfig(
+ _target=VanillaDataManager[DepthDataset],
dataparser=NerfstudioDataParserConfig(),
train_num_rays_per_batch=4096,
eval_num_rays_per_batch=4096,
@@ -198,16 +262,20 @@ method_configs["instant-ngp"] = TrainerConfig(
max_num_iterations=30000,
mixed_precision=True,
pipeline=DynamicBatchPipelineConfig(
- datamanager=VanillaDataManagerConfig(dataparser=NerfstudioDataParserConfig(), train_num_rays_per_batch=8192),
+ datamanager=VanillaDataManagerConfig(
+ dataparser=NerfstudioDataParserConfig(),
+ train_num_rays_per_batch=4096,
+ eval_num_rays_per_batch=4096,
+ ),
model=InstantNGPModelConfig(eval_num_rays_per_chunk=8192),
),
optimizers={
"fields": {
"optimizer": AdamOptimizerConfig(lr=1e-2, eps=1e-15),
- "scheduler": None,
+ "scheduler": ExponentialDecaySchedulerConfig(lr_final=0.0001, max_steps=200000),
}
},
- viewer=ViewerConfig(num_rays_per_chunk=64000),
+ viewer=ViewerConfig(num_rays_per_chunk=1 << 12),
vis="viewer",
)
@@ -222,9 +290,10 @@ method_configs["instant-ngp-bounded"] = TrainerConfig(
datamanager=VanillaDataManagerConfig(dataparser=InstantNGPDataParserConfig(), train_num_rays_per_batch=8192),
model=InstantNGPModelConfig(
eval_num_rays_per_chunk=8192,
- contraction_type=ContractionType.AABB,
- render_step_size=0.001,
- max_num_samples_per_ray=48,
+ grid_levels=1,
+ alpha_thre=0.0,
+ cone_angle=0.0,
+ disable_scene_contraction=True,
near_plane=0.01,
background_color="black",
),
@@ -232,10 +301,10 @@ method_configs["instant-ngp-bounded"] = TrainerConfig(
optimizers={
"fields": {
"optimizer": AdamOptimizerConfig(lr=1e-2, eps=1e-15),
- "scheduler": None,
+ "scheduler": ExponentialDecaySchedulerConfig(lr_final=0.0001, max_steps=200000),
}
},
- viewer=ViewerConfig(num_rays_per_chunk=64000),
+ viewer=ViewerConfig(num_rays_per_chunk=1 << 12),
vis="viewer",
)
@@ -267,8 +336,11 @@ method_configs["semantic-nerfw"] = TrainerConfig(
max_num_iterations=30000,
mixed_precision=True,
pipeline=VanillaPipelineConfig(
- datamanager=SemanticDataManagerConfig(
- dataparser=Sitcoms3DDataParserConfig(), train_num_rays_per_batch=4096, eval_num_rays_per_batch=8192
+ datamanager=VanillaDataManagerConfig(
+ _target=VanillaDataManager[SemanticDataset],
+ dataparser=Sitcoms3DDataParserConfig(),
+ train_num_rays_per_batch=4096,
+ eval_num_rays_per_batch=8192,
),
model=SemanticNerfWModelConfig(eval_num_rays_per_chunk=1 << 16),
),
@@ -315,8 +387,12 @@ method_configs["tensorf"] = TrainerConfig(
pipeline=VanillaPipelineConfig(
datamanager=VanillaDataManagerConfig(
dataparser=BlenderDataParserConfig(),
+ train_num_rays_per_batch=4096,
+ eval_num_rays_per_batch=4096,
+ ),
+ model=TensoRFModelConfig(
+ regularization="tv",
),
- model=TensoRFModelConfig(),
),
optimizers={
"fields": {
@@ -361,13 +437,18 @@ method_configs["phototourism"] = TrainerConfig(
max_num_iterations=30000,
mixed_precision=True,
pipeline=VanillaPipelineConfig(
- datamanager=VariableResDataManagerConfig( # NOTE: one of the only differences with nerfacto
+ datamanager=VanillaDataManagerConfig(
dataparser=PhototourismDataParserConfig(), # NOTE: one of the only differences with nerfacto
train_num_rays_per_batch=4096,
eval_num_rays_per_batch=4096,
camera_optimizer=CameraOptimizerConfig(
mode="SO3xR3", optimizer=AdamOptimizerConfig(lr=6e-4, eps=1e-8, weight_decay=1e-2)
),
+ # Large dataset, so using prior values from VariableResDataManager.
+ train_num_images_to_sample_from=40,
+ train_num_times_to_repeat_images=100,
+ eval_num_images_to_sample_from=40,
+ eval_num_times_to_repeat_images=100,
),
model=NerfactoModelConfig(eval_num_rays_per_chunk=1 << 15),
),
@@ -394,6 +475,7 @@ method_configs["dreamfusion"] = TrainerConfig(
max_num_iterations=30000,
mixed_precision=True,
pipeline=VanillaPipelineConfig(
+<<<<<<< HEAD
generative=True,
datamanager=DreamFusionDataManagerConfig(
horizontal_rotation_warmup=4000,
@@ -437,6 +519,10 @@ method_configs["nerfplayer-nerfacto"] = TrainerConfig(
method_name="nerfplayer-nerfacto",
pipeline=VanillaPipelineConfig(
datamanager=DepthDataManagerConfig(
+=======
+ datamanager=VanillaDataManagerConfig(
+ _target=VanillaDataManager[DepthDataset],
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
dataparser=DycheckDataParserConfig(),
train_num_rays_per_batch=4096,
eval_num_rays_per_batch=4096,
@@ -467,12 +553,17 @@ method_configs["nerfplayer-ngp"] = TrainerConfig(
max_num_iterations=30000,
mixed_precision=True,
pipeline=DynamicBatchPipelineConfig(
- datamanager=DepthDataManagerConfig(dataparser=DycheckDataParserConfig(), train_num_rays_per_batch=8192),
+ datamanager=VanillaDataManagerConfig(
+ _target=VanillaDataManager[DepthDataset],
+ dataparser=DycheckDataParserConfig(),
+ train_num_rays_per_batch=8192,
+ ),
model=NerfplayerNGPModelConfig(
eval_num_rays_per_chunk=8192,
- contraction_type=ContractionType.AABB,
+ grid_levels=1,
+ alpha_thre=0.0,
render_step_size=0.001,
- max_num_samples_per_ray=48,
+ disable_scene_contraction=True,
near_plane=0.01,
),
),
@@ -495,7 +586,12 @@ method_configs["neus"] = TrainerConfig(
max_num_iterations=100000,
mixed_precision=False,
pipeline=VanillaPipelineConfig(
+<<<<<<< HEAD
datamanager=SDFDataManagerConfig(
+=======
+ datamanager=VanillaDataManagerConfig(
+ _target=VanillaDataManager[SDFDataset],
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
dataparser=SDFStudioDataParserConfig(),
train_num_rays_per_batch=1024,
eval_num_rays_per_batch=1024,
@@ -519,13 +615,67 @@ method_configs["neus"] = TrainerConfig(
vis="viewer",
)
+<<<<<<< HEAD
+=======
+method_configs["neus-facto"] = TrainerConfig(
+ method_name="neus-facto",
+ steps_per_eval_image=5000,
+ steps_per_eval_batch=5000,
+ steps_per_save=2000,
+ steps_per_eval_all_images=1000000, # set to a very large model so we don't eval with all images
+ max_num_iterations=20001,
+ mixed_precision=False,
+ pipeline=VanillaPipelineConfig(
+ datamanager=VanillaDataManagerConfig(
+ _target=VanillaDataManager[SDFDataset],
+ dataparser=SDFStudioDataParserConfig(),
+ train_num_rays_per_batch=2048,
+ eval_num_rays_per_batch=2048,
+ camera_optimizer=CameraOptimizerConfig(
+ mode="SO3xR3", optimizer=AdamOptimizerConfig(lr=6e-4, eps=1e-8, weight_decay=1e-2)
+ ),
+ ),
+ model=NeuSFactoModelConfig(
+ # proposal network allows for signifanctly smaller sdf/color network
+ sdf_field=SDFFieldConfig(
+ use_grid_feature=True,
+ num_layers=2,
+ num_layers_color=2,
+ hidden_dim=256,
+ bias=0.5,
+ beta_init=0.8,
+ use_appearance_embedding=False,
+ ),
+ background_model="none",
+ eval_num_rays_per_chunk=2048,
+ ),
+ ),
+ optimizers={
+ "proposal_networks": {
+ "optimizer": AdamOptimizerConfig(lr=1e-2, eps=1e-15),
+ "scheduler": MultiStepSchedulerConfig(max_steps=20001, milestones=(10000, 1500, 18000)),
+ },
+ "fields": {
+ "optimizer": AdamOptimizerConfig(lr=5e-4, eps=1e-15),
+ "scheduler": CosineDecaySchedulerConfig(warm_up_end=500, learning_rate_alpha=0.05, max_steps=20001),
+ },
+ "field_background": {
+ "optimizer": AdamOptimizerConfig(lr=5e-4, eps=1e-15),
+ "scheduler": CosineDecaySchedulerConfig(warm_up_end=500, learning_rate_alpha=0.05, max_steps=20001),
+ },
+ },
+ viewer=ViewerConfig(num_rays_per_chunk=1 << 15),
+ vis="viewer",
+)
+
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
external_methods, external_descriptions = discover_methods()
-method_configs.update(external_methods)
-descriptions.update(external_descriptions)
+all_methods = {**method_configs, **external_methods}
+all_descriptions = {**descriptions, **external_descriptions}
AnnotatedBaseConfigUnion = tyro.conf.SuppressFixed[ # Don't show unparseable (fixed) arguments in helptext.
tyro.conf.FlagConversionOff[
- tyro.extras.subcommand_type_from_defaults(defaults=method_configs, descriptions=descriptions)
+ tyro.extras.subcommand_type_from_defaults(defaults=all_methods, descriptions=all_descriptions)
]
]
"""Union[] type over config types, annotated with default instances for use with
diff --git a/nerfstudio/data/datamanagers/base_datamanager.py b/nerfstudio/data/datamanagers/base_datamanager.py
index 7ff2f9aaf..4d4f88dae 100644
--- a/nerfstudio/data/datamanagers/base_datamanager.py
+++ b/nerfstudio/data/datamanagers/base_datamanager.py
@@ -18,10 +18,11 @@ Datamanager.
from __future__ import annotations
+import functools
from abc import abstractmethod
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Any, Dict, List, Optional, Tuple, Type, Union
+from typing import Any, Dict, Generic, List, Literal, Optional, Tuple, Type, Union
import torch
import tyro
@@ -30,7 +31,7 @@ from torch import nn
from torch.nn import Parameter
from torch.utils.data import Dataset
from torch.utils.data.distributed import DistributedSampler
-from typing_extensions import Literal
+from typing_extensions import TypeVar
from nerfstudio.cameras.camera_optimizers import CameraOptimizerConfig
from nerfstudio.cameras.cameras import CameraType
@@ -47,6 +48,7 @@ from nerfstudio.data.dataparsers.instant_ngp_dataparser import (
InstantNGPDataParserConfig,
)
from nerfstudio.data.dataparsers.minimal_dataparser import MinimalDataParserConfig
+from nerfstudio.data.dataparsers.nerfosr_dataparser import NeRFOSRDataParserConfig
from nerfstudio.data.dataparsers.nerfstudio_dataparser import NerfstudioDataParserConfig
from nerfstudio.data.dataparsers.nuscenes_dataparser import NuScenesDataParserConfig
from nerfstudio.data.dataparsers.phototourism_dataparser import (
@@ -73,6 +75,31 @@ from nerfstudio.utils.misc import IterableWrapper
CONSOLE = Console(width=120)
+
+def variable_res_collate(batch: List[Dict]) -> Dict:
+ """Default collate function for the cached dataloader.
+ Args:
+ batch: Batch of samples from the dataset.
+ Returns:
+ Collated batch.
+ """
+ images = []
+ masks = []
+ for data in batch:
+ image = data.pop("image")
+ mask = data.pop("mask", None)
+ images.append(image)
+ if mask is not None:
+ masks.append(mask)
+
+ new_batch: dict = nerfstudio_collate(batch)
+ new_batch["image"] = images
+ if masks:
+ new_batch["mask"] = masks
+
+ return new_batch
+
+
AnnotatedDataParserUnion = tyro.conf.OmitSubcommandPrefixes[ # Omit prefixes of flags in subcommands.
tyro.extras.subcommand_type_from_defaults(
{
@@ -87,6 +114,7 @@ AnnotatedDataParserUnion = tyro.conf.OmitSubcommandPrefixes[ # Omit prefixes of
"dycheck-data": DycheckDataParserConfig(),
"scannet-data": ScanNetDataParserConfig(),
"sdfstudio-data": SDFStudioDataParserConfig(),
+ "nerfosr-data": NeRFOSRDataParserConfig(),
"sitcoms3d-data": Sitcoms3DDataParserConfig(),
},
prefix_names=False, # Omit prefixes in subcommands themselves.
@@ -122,10 +150,11 @@ class DataManager(nn.Module):
Usage:
To get data, use the next_train and next_eval functions.
This data manager's next_train and next_eval methods will return 2 things:
- 1. A Raybundle: This will contain the rays we are sampling, with latents and
- conditionals attached (everything needed at inference)
- 2. A "batch" of auxiliary information: This will contain the mask, the ground truth
- pixels, etc needed to actually train, score, etc the model
+
+ 1. A Raybundle: This will contain the rays we are sampling, with latents and
+ conditionals attached (everything needed at inference)
+ 2. A "batch" of auxiliary information: This will contain the mask, the ground truth
+ pixels, etc needed to actually train, score, etc the model
Rationale:
Because of this abstraction we've added, we can support more NeRF paradigms beyond the
@@ -151,6 +180,7 @@ class DataManager(nn.Module):
eval_count (int): the step number of our eval iteration, needs to be incremented manually
train_dataset (Dataset): the dataset for the train dataset
eval_dataset (Dataset): the dataset for the eval dataset
+ includes_time (bool): whether the dataset includes time information
Additional attributes specific to each subclass are defined in the setup_train and setup_eval
functions.
@@ -161,6 +191,7 @@ class DataManager(nn.Module):
eval_dataset: Optional[Dataset] = None
train_sampler: Optional[DistributedSampler] = None
eval_sampler: Optional[DistributedSampler] = None
+ includes_time: bool = False
def __init__(self):
"""Constructor for the DataManager class.
@@ -337,7 +368,10 @@ class VanillaDataManagerConfig(DataManagerConfig):
"""Size of patch to sample from. If >1, patch-based sampling will be used."""
-class VanillaDataManager(DataManager): # pylint: disable=abstract-method
+TDataset = TypeVar("TDataset", bound=InputDataset, default=InputDataset)
+
+
+class VanillaDataManager(DataManager, Generic[TDataset]): # pylint: disable=abstract-method
"""Basic stored data manager implementation.
This is pretty much a port over from our old dataloading utilities, and is a little jank
@@ -351,8 +385,8 @@ class VanillaDataManager(DataManager): # pylint: disable=abstract-method
"""
config: VanillaDataManagerConfig
- train_dataset: InputDataset
- eval_dataset: InputDataset
+ train_dataset: TDataset
+ eval_dataset: TDataset
train_dataparser_outputs: DataparserOutputs
train_pixel_sampler: Optional[PixelSampler] = None
eval_pixel_sampler: Optional[PixelSampler] = None
@@ -366,6 +400,7 @@ class VanillaDataManager(DataManager): # pylint: disable=abstract-method
local_rank: int = 0,
**kwargs, # pylint: disable=unused-argument
):
+ self.dataset_type: Type[TDataset] = kwargs.get("_dataset_type", TDataset.__default__)
self.config = config
self.device = device
self.world_size = world_size
@@ -379,28 +414,49 @@ class VanillaDataManager(DataManager): # pylint: disable=abstract-method
else:
self.config.data = self.config.dataparser.data
self.dataparser = self.dataparser_config.setup()
+<<<<<<< HEAD
+=======
+ self.includes_time = self.dataparser.includes_time
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
self.train_dataparser_outputs = self.dataparser.get_dataparser_outputs(split="train")
self.train_dataset = self.create_train_dataset()
self.eval_dataset = self.create_eval_dataset()
+
+ if self.train_dataparser_outputs is not None:
+ cameras = self.train_dataparser_outputs.cameras
+ if len(cameras) > 1:
+ for i in range(1, len(cameras)):
+ if cameras[0].width != cameras[i].width or cameras[0].height != cameras[i].height:
+ CONSOLE.print("Variable resolution, using variable_res_collate")
+ self.config.collate_fn = variable_res_collate
+ break
+
super().__init__()
- def create_train_dataset(self) -> InputDataset:
+ def __class_getitem__(cls, item):
+ return type(
+ cls.__name__,
+ (cls,),
+ {"__module__": cls.__module__, "__init__": functools.partialmethod(cls.__init__, _dataset_type=item)},
+ )
+
+ def create_train_dataset(self) -> TDataset:
"""Sets up the data loaders for training"""
- return InputDataset(
+ return self.dataset_type(
dataparser_outputs=self.train_dataparser_outputs,
scale_factor=self.config.camera_res_scale_factor,
)
- def create_eval_dataset(self) -> InputDataset:
+ def create_eval_dataset(self) -> TDataset:
"""Sets up the data loaders for evaluation"""
- return InputDataset(
+ return self.dataset_type(
dataparser_outputs=self.dataparser.get_dataparser_outputs(split=self.test_split),
scale_factor=self.config.camera_res_scale_factor,
)
def _get_pixel_sampler( # pylint: disable=no-self-use
- self, dataset: InputDataset, *args: Any, **kwargs: Any
+ self, dataset: TDataset, *args: Any, **kwargs: Any
) -> PixelSampler:
"""Infer pixel sampler to use."""
if self.config.patch_size > 1:
diff --git a/nerfstudio/data/datamanagers/depth_datamanager.py b/nerfstudio/data/datamanagers/depth_datamanager.py
deleted file mode 100644
index 465e79e2d..000000000
--- a/nerfstudio/data/datamanagers/depth_datamanager.py
+++ /dev/null
@@ -1,48 +0,0 @@
-# Copyright 2022 The Nerfstudio Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-"""
-Depth datamanager.
-"""
-
-from dataclasses import dataclass, field
-from typing import Type
-
-from nerfstudio.data.datamanagers import base_datamanager
-from nerfstudio.data.datasets.depth_dataset import DepthDataset
-
-
-@dataclass
-class DepthDataManagerConfig(base_datamanager.VanillaDataManagerConfig):
- """A depth datamanager - required to use with .setup()"""
-
- _target: Type = field(default_factory=lambda: DepthDataManager)
-
-
-class DepthDataManager(base_datamanager.VanillaDataManager): # pylint: disable=abstract-method
- """Data manager implementation for data that also requires processing depth data.
- Args:
- config: the DataManagerConfig used to instantiate class
- """
-
- def create_train_dataset(self) -> DepthDataset:
- self.train_dataparser_outputs = self.dataparser.get_dataparser_outputs(split="train")
- return DepthDataset(
- dataparser_outputs=self.train_dataparser_outputs,
- )
-
- def create_eval_dataset(self) -> DepthDataset:
- return DepthDataset(
- dataparser_outputs=self.dataparser.get_dataparser_outputs(split=self.test_split),
- )
diff --git a/nerfstudio/data/datamanagers/semantic_datamanager.py b/nerfstudio/data/datamanagers/semantic_datamanager.py
deleted file mode 100644
index 322b1d3bd..000000000
--- a/nerfstudio/data/datamanagers/semantic_datamanager.py
+++ /dev/null
@@ -1,54 +0,0 @@
-# Copyright 2022 The Nerfstudio Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-"""
-Semantic datamanager.
-"""
-
-from dataclasses import dataclass, field
-from typing import Type
-
-from nerfstudio.data.datamanagers.base_datamanager import (
- VanillaDataManager,
- VanillaDataManagerConfig,
-)
-from nerfstudio.data.datasets.semantic_dataset import SemanticDataset
-
-
-@dataclass
-class SemanticDataManagerConfig(VanillaDataManagerConfig):
- """A semantic datamanager - required to use with .setup()"""
-
- _target: Type = field(default_factory=lambda: SemanticDataManager)
-
-
-class SemanticDataManager(VanillaDataManager): # pylint: disable=abstract-method
- """Data manager implementation for data that also requires processing semantic data.
-
- Args:
- config: the DataManagerConfig used to instantiate class
- """
-
- def create_train_dataset(self) -> SemanticDataset:
- self.train_dataparser_outputs = self.dataparser.get_dataparser_outputs(split="train")
- return SemanticDataset(
- dataparser_outputs=self.train_dataparser_outputs,
- scale_factor=self.config.camera_res_scale_factor,
- )
-
- def create_eval_dataset(self) -> SemanticDataset:
- return SemanticDataset(
- dataparser_outputs=self.dataparser.get_dataparser_outputs(split=self.test_split),
- scale_factor=self.config.camera_res_scale_factor,
- )
diff --git a/nerfstudio/data/datamanagers/variable_res_datamanager.py b/nerfstudio/data/datamanagers/variable_res_datamanager.py
deleted file mode 100644
index b821bc034..000000000
--- a/nerfstudio/data/datamanagers/variable_res_datamanager.py
+++ /dev/null
@@ -1,66 +0,0 @@
-# Copyright 2022 The Nerfstudio Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-"""
-Data loader for variable resolution datasets, where batching raw image tensors isn't possible.
-"""
-
-from __future__ import annotations
-
-from dataclasses import dataclass
-from typing import Dict, List
-
-from nerfstudio.data.datamanagers.base_datamanager import VanillaDataManagerConfig
-from nerfstudio.data.utils.nerfstudio_collate import nerfstudio_collate
-
-
-def variable_res_collate(batch: List[Dict]) -> Dict:
- """Default collate function for the cached dataloader.
- Args:
- batch: Batch of samples from the dataset.
- Returns:
- Collated batch.
- """
- images = []
- masks = []
- for data in batch:
- image = data.pop("image")
- mask = data.pop("mask", None)
- images.append(image)
- if mask:
- masks.append(mask)
-
- new_batch: dict = nerfstudio_collate(batch)
- new_batch["image"] = images
- if masks:
- new_batch["mask"] = masks
-
- return new_batch
-
-
-@dataclass
-class VariableResDataManagerConfig(VanillaDataManagerConfig):
- """A datamanager for variable resolution datasets, with presets to optimize
- for the fact that we are now dealing with lists of images and masks.
- """
-
- train_num_images_to_sample_from: int = 40
- """Number of images to sample during training iteration."""
- train_num_times_to_repeat_images: int = 100
- """When not training on all images, number of iterations before picking new
- images. If -1, never pick new images."""
- eval_num_images_to_sample_from: int = 40
- """Number of images to sample during eval iteration."""
- eval_num_times_to_repeat_images: int = 100
- collate_fn = staticmethod(variable_res_collate)
diff --git a/nerfstudio/data/dataparsers/arkitscenes_dataparser.py b/nerfstudio/data/dataparsers/arkitscenes_dataparser.py
index a92745bc6..cda832ef8 100644
--- a/nerfstudio/data/dataparsers/arkitscenes_dataparser.py
+++ b/nerfstudio/data/dataparsers/arkitscenes_dataparser.py
@@ -16,7 +16,7 @@
import math
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Type
+from typing import Literal, Type
import cv2
import numpy as np
diff --git a/nerfstudio/data/dataparsers/base_dataparser.py b/nerfstudio/data/dataparsers/base_dataparser.py
index 89c7c4e21..74d934ced 100644
--- a/nerfstudio/data/dataparsers/base_dataparser.py
+++ b/nerfstudio/data/dataparsers/base_dataparser.py
@@ -20,7 +20,7 @@ import json
from abc import abstractmethod
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Any, Dict, List, Optional, Type
+from typing import Any, Dict, List, Literal, Optional, Type
import torch
from torchtyping import TensorType
@@ -89,6 +89,26 @@ class DataparserOutputs:
with open(path, "w", encoding="UTF-8") as file:
json.dump(data, file, indent=4)
+ def transform_poses_to_original_space(
+ self,
+ poses: TensorType["num_poses", 3, 4],
+ camera_convention: Literal["opengl", "opencv"] = "opencv",
+ ) -> TensorType["num_poses", 3, 4]:
+ """
+ Transforms the poses in the transformed space back to the original world coordinate system.
+ Args:
+ poses: Poses in the transformed space
+ camera_convention: Camera system convention used for the transformed poses
+ Returns:
+ Original poses
+ """
+ return transform_poses_to_original_space(
+ poses,
+ self.dataparser_transform,
+ self.dataparser_scale,
+ camera_convention=camera_convention,
+ )
+
@dataclass
class DataParserConfig(cfg.InstantiateConfig):
@@ -106,9 +126,14 @@ class DataParser:
Args:
config: datasetparser config containing all information needed to instantiate dataset
+
+ Attributes:
+ config: datasetparser config containing all information needed to instantiate dataset
+ includes_time: Does the dataset include time information in the camera poses.
"""
config: DataParserConfig
+ includes_time: bool = False
def __init__(self, config: DataParserConfig):
super().__init__()
@@ -136,3 +161,46 @@ class DataParser:
"""
dataparser_outputs = self._generate_dataparser_outputs(split)
return dataparser_outputs
+
+
+def transform_poses_to_original_space(
+ poses: TensorType["num_poses", 3, 4],
+ applied_transform: TensorType[3, 4],
+ applied_scale: float,
+ camera_convention: Literal["opengl", "opencv"] = "opencv",
+) -> TensorType["num_poses", 3, 4]:
+ """
+ Transforms the poses in the transformed space back to the original world coordinate system.
+ Args:
+ poses: Poses in the transformed space
+ applied_transform: Transform matrix applied in the data processing step
+ applied_scale: Scale used in the data processing step
+ camera_convention: Camera system convention used for the transformed poses
+ Returns:
+ Original poses
+ """
+ output_poses = torch.cat(
+ (
+ poses,
+ torch.tensor([[[0, 0, 0, 1]]], dtype=poses.dtype, device=poses.device).repeat_interleave(len(poses), 0),
+ ),
+ 1,
+ )
+ output_poses[..., :3, 3] /= applied_scale
+ inv_transform = torch.linalg.inv(
+ torch.cat(
+ (
+ applied_transform,
+ torch.tensor([[0, 0, 0, 1]], dtype=applied_transform.dtype, device=applied_transform.device),
+ ),
+ 0,
+ )
+ )
+ output_poses = torch.einsum("ij,bjk->bik", inv_transform, output_poses)
+ if camera_convention == "opencv":
+ output_poses[..., 0:3, 1:3] *= -1
+ elif camera_convention == "opengl":
+ pass
+ else:
+ raise ValueError(f"Camera convention {camera_convention} is not supported.")
+ return output_poses[:, :3]
diff --git a/nerfstudio/data/dataparsers/blender_dataparser.py b/nerfstudio/data/dataparsers/blender_dataparser.py
index f1044e826..b365f95cb 100644
--- a/nerfstudio/data/dataparsers/blender_dataparser.py
+++ b/nerfstudio/data/dataparsers/blender_dataparser.py
@@ -77,7 +77,7 @@ class Blender(DataParser):
poses.append(np.array(frame["transform_matrix"]))
poses = np.array(poses).astype(np.float32)
- img_0 = imageio.imread(image_filenames[0])
+ img_0 = imageio.v2.imread(image_filenames[0])
image_height, image_width = img_0.shape[:2]
camera_angle_x = float(meta["camera_angle_x"])
focal_length = 0.5 * image_width / np.tan(0.5 * camera_angle_x)
diff --git a/nerfstudio/data/dataparsers/dnerf_dataparser.py b/nerfstudio/data/dataparsers/dnerf_dataparser.py
index c26621e92..d7411b4c6 100644
--- a/nerfstudio/data/dataparsers/dnerf_dataparser.py
+++ b/nerfstudio/data/dataparsers/dnerf_dataparser.py
@@ -53,6 +53,7 @@ class DNeRF(DataParser):
"""DNeRF Dataset"""
config: DNeRFDataParserConfig
+ includes_time: bool = True
def __init__(self, config: DNeRFDataParserConfig):
super().__init__(config=config)
diff --git a/nerfstudio/data/dataparsers/dycheck_dataparser.py b/nerfstudio/data/dataparsers/dycheck_dataparser.py
index 92cca35ff..7ddf051e1 100644
--- a/nerfstudio/data/dataparsers/dycheck_dataparser.py
+++ b/nerfstudio/data/dataparsers/dycheck_dataparser.py
@@ -202,6 +202,7 @@ class Dycheck(DataParser):
"""Dycheck (https://arxiv.org/abs/2210.13445) Dataset `iphone` subset"""
config: DycheckDataParserConfig
+ includes_time: bool = True
def __init__(self, config: DycheckDataParserConfig):
super().__init__(config=config)
diff --git a/nerfstudio/data/dataparsers/instant_ngp_dataparser.py b/nerfstudio/data/dataparsers/instant_ngp_dataparser.py
index 2fdc2df85..8b4bf724c 100644
--- a/nerfstudio/data/dataparsers/instant_ngp_dataparser.py
+++ b/nerfstudio/data/dataparsers/instant_ngp_dataparser.py
@@ -65,6 +65,7 @@ class InstantNGP(DataParser):
data_dir = self.config.data
image_filenames = []
+ mask_filenames = []
poses = []
num_skipped_image_filenames = 0
for frame in meta["frames"]:
@@ -87,6 +88,9 @@ class InstantNGP(DataParser):
meta["h"] = h
image_filenames.append(fname)
poses.append(np.array(frame["transform_matrix"]))
+ if "mask_path" in frame:
+ mask_fname = data_dir / Path(frame["mask_path"])
+ mask_filenames.append(mask_fname)
if num_skipped_image_filenames >= 0:
CONSOLE.print(f"Skipping {num_skipped_image_filenames} files in dataset split {split}.")
assert (
@@ -144,6 +148,7 @@ class InstantNGP(DataParser):
image_filenames=image_filenames,
cameras=cameras,
scene_box=scene_box,
+ mask_filenames=mask_filenames if len(mask_filenames) > 0 else None,
dataparser_scale=self.config.scene_scale,
)
diff --git a/nerfstudio/data/dataparsers/nerfosr_dataparser.py b/nerfstudio/data/dataparsers/nerfosr_dataparser.py
new file mode 100644
index 000000000..97f430e1a
--- /dev/null
+++ b/nerfstudio/data/dataparsers/nerfosr_dataparser.py
@@ -0,0 +1,235 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+""" Data parser for NeRF-OSR datasets
+
+ Presented in the paper: https://4dqv.mpi-inf.mpg.de/NeRF-OSR/
+
+"""
+
+from __future__ import annotations
+
+import glob
+import os
+from dataclasses import dataclass, field
+from pathlib import Path
+from typing import List, Literal, Tuple, Type
+
+import numpy as np
+import torch
+from rich.console import Console
+
+from nerfstudio.cameras import camera_utils
+from nerfstudio.cameras.cameras import Cameras, CameraType
+from nerfstudio.data.dataparsers.base_dataparser import (
+ DataParser,
+ DataParserConfig,
+ DataparserOutputs,
+)
+from nerfstudio.data.scene_box import SceneBox
+
+CONSOLE = Console(width=120)
+
+
+def _find_files(directory: str, exts: List[str]):
+ """Find all files in a directory that have a certain file extension.
+
+ Args:
+ directory : The directory to search for files.
+ exts : A list of file extensions to search for. Each file extension should be in the form '*.ext'.
+
+ Returns:
+ A list of file paths for all the files that were found. The list is sorted alphabetically.
+ """
+ if os.path.isdir(directory):
+ # types should be ['*.png', '*.jpg', '*.JPG', '*.PNG']
+ files_grabbed = []
+ for ext in exts:
+ files_grabbed.extend(glob.glob(os.path.join(directory, ext)))
+ if len(files_grabbed) > 0:
+ files_grabbed = sorted(files_grabbed)
+ return files_grabbed
+ return []
+
+
+def _parse_osm_txt(filename: str):
+ """Parse a text file containing numbers and return a 4x4 numpy array of float32 values.
+
+ Args:
+ filename : a file containing numbers in a 4x4 matrix.
+
+ Returns:
+ A numpy array of shape [4, 4] containing the numbers from the file.
+ """
+ assert os.path.isfile(filename)
+ with open(filename, encoding="UTF-8") as f:
+ nums = f.read().split()
+ return np.array([float(x) for x in nums]).reshape([4, 4]).astype(np.float32)
+
+
+def get_camera_params(
+ scene_dir: str, split: Literal["train", "validation", "test"]
+) -> Tuple[torch.Tensor, torch.Tensor, int]:
+ """Load camera intrinsic and extrinsic parameters for a given scene split.
+
+ Args"
+ scene_dir : The directory containing the scene data.
+ split : The split for which to load the camera parameters.
+
+ Returns
+ A tuple containing the intrinsic parameters (as a torch.Tensor of shape [N, 4, 4]),
+ the camera-to-world matrices (as a torch.Tensor of shape [N, 4, 4]), and the number of cameras (N).
+ """
+ split_dir = f"{scene_dir}/{split}"
+
+ # camera parameters files
+ intrinsics_files = _find_files(f"{split_dir}/intrinsics", exts=["*.txt"])
+ pose_files = _find_files(f"{split_dir}/pose", exts=["*.txt"])
+
+ num_cams = len(pose_files)
+
+ intrinsics = []
+ camera_to_worlds = []
+ for i in range(num_cams):
+ intrinsics.append(_parse_osm_txt(intrinsics_files[i]))
+
+ pose = _parse_osm_txt(pose_files[i])
+
+ # convert from COLMAP/OpenCV to nerfstudio camera (OpenGL/Blender)
+ pose[0:3, 1:3] *= -1
+
+ camera_to_worlds.append(pose)
+
+ intrinsics = torch.from_numpy(np.stack(intrinsics).astype(np.float32)) # [N, 4, 4]
+ camera_to_worlds = torch.from_numpy(np.stack(camera_to_worlds).astype(np.float32)) # [N, 4, 4]
+
+ return intrinsics, camera_to_worlds, num_cams
+
+
+@dataclass
+class NeRFOSRDataParserConfig(DataParserConfig):
+ """Nerfstudio dataset config"""
+
+ _target: Type = field(default_factory=lambda: NeRFOSR)
+ """target class to instantiate"""
+ data: Path = Path("data/NeRF-OSR/Data/")
+ """Directory specifying location of data."""
+ scene: str = "stjacob"
+ """Which scene to load"""
+ scene_scale: float = 1.0
+ """How much to scale the region of interest by."""
+ scale_factor: float = 1.0
+ """How much to scale the camera origins by."""
+ use_masks: bool = False
+ """Whether to use masks."""
+ orientation_method: Literal["pca", "up", "vertical", "none"] = "vertical"
+ """The method to use for orientation."""
+ center_method: Literal["poses", "focus", "none"] = "focus"
+ """The method to use for centering."""
+ auto_scale_poses: bool = True
+ """Whether to automatically scale the poses to fit in +/- 1 bounding box."""
+
+
+@dataclass
+class NeRFOSR(DataParser):
+ """NeRFOSR Dataparser
+ Presented in the paper: https://4dqv.mpi-inf.mpg.de/NeRF-OSR/
+
+ Some of this code comes from https://github.com/r00tman/NeRF-OSR/blob/main/data_loader_split.py
+
+ Source data convention is:
+ camera coordinate system: x-->right, y-->down, z-->scene (opencv/colmap convention)
+ poses is camera-to-world
+ masks are 0 for dynamic content, 255 for static content
+ """
+
+ config: NeRFOSRDataParserConfig
+
+ def _generate_dataparser_outputs(self, split="train"):
+ data = self.config.data
+ scene = self.config.scene
+ split = "validation" if split == "val" else split
+
+ if scene == "trevi":
+ scene_dir = f"{data}/{scene}/final_clean"
+ split_dir = f"{data}/{scene}/final_clean/{split}"
+ else:
+ scene_dir = f"{data}/{scene}/final"
+ split_dir = f"{data}/{scene}/final/{split}"
+
+ # get all split cam params
+ intrinsics_train, camera_to_worlds_train, n_train = get_camera_params(scene_dir, "train")
+ intrinsics_val, camera_to_worlds_val, n_val = get_camera_params(scene_dir, "validation")
+ intrinsics_test, camera_to_worlds_test, _ = get_camera_params(scene_dir, "test")
+
+ # combine all cam params
+ intrinsics = torch.cat([intrinsics_train, intrinsics_val, intrinsics_test], dim=0)
+ camera_to_worlds = torch.cat([camera_to_worlds_train, camera_to_worlds_val, camera_to_worlds_test], dim=0)
+
+ camera_to_worlds, _ = camera_utils.auto_orient_and_center_poses(
+ camera_to_worlds,
+ method=self.config.orientation_method,
+ center_method=self.config.center_method,
+ )
+
+ # Scale poses
+ scale_factor = 1.0
+ if self.config.auto_scale_poses:
+ scale_factor /= torch.max(torch.abs(camera_to_worlds[:, :3, 3]))
+
+ camera_to_worlds[:, :3, 3] *= scale_factor * self.config.scale_factor
+
+ if split == "train":
+ camera_to_worlds = camera_to_worlds[:n_train]
+ intrinsics = intrinsics[:n_train]
+ elif split == "validation":
+ camera_to_worlds = camera_to_worlds[n_train : n_train + n_val]
+ intrinsics = intrinsics[n_train : n_train + n_val]
+ elif split == "test":
+ camera_to_worlds = camera_to_worlds[n_train + n_val :]
+ intrinsics = intrinsics[n_train + n_val :]
+
+ cameras = Cameras(
+ camera_to_worlds=camera_to_worlds[:, :3, :4],
+ fx=intrinsics[:, 0, 0],
+ fy=intrinsics[:, 1, 1],
+ cx=intrinsics[:, 0, 2],
+ cy=intrinsics[:, 1, 2],
+ camera_type=CameraType.PERSPECTIVE,
+ )
+
+ # in x,y,z order
+ # assumes that the scene is centered at the origin
+ aabb_scale = self.config.scene_scale
+ scene_box = SceneBox(
+ aabb=torch.tensor(
+ [[-aabb_scale, -aabb_scale, -aabb_scale], [aabb_scale, aabb_scale, aabb_scale]], dtype=torch.float32
+ )
+ )
+
+ # --- images ---
+ image_filenames = _find_files(f"{split_dir}/rgb", exts=["*.png", "*.jpg", "*.JPG", "*.PNG"])
+
+ # --- masks ---
+ mask_filenames = []
+ if self.config.use_masks:
+ mask_filenames = _find_files(f"{split_dir}/mask", exts=["*.png", "*.jpg", "*.JPG", "*.PNG"])
+
+ dataparser_outputs = DataparserOutputs(
+ image_filenames=image_filenames,
+ cameras=cameras,
+ scene_box=scene_box,
+ mask_filenames=mask_filenames if len(mask_filenames) > 0 else None,
+ dataparser_scale=self.config.scale_factor,
+ )
+ return dataparser_outputs
diff --git a/nerfstudio/data/dataparsers/nerfstudio_dataparser.py b/nerfstudio/data/dataparsers/nerfstudio_dataparser.py
index 4a74cd961..d88bf46e7 100644
--- a/nerfstudio/data/dataparsers/nerfstudio_dataparser.py
+++ b/nerfstudio/data/dataparsers/nerfstudio_dataparser.py
@@ -18,13 +18,12 @@ from __future__ import annotations
import math
from dataclasses import dataclass, field
from pathlib import Path, PurePath
-from typing import Optional, Type
+from typing import Literal, Optional, Type
import numpy as np
import torch
from PIL import Image
from rich.console import Console
-from typing_extensions import Literal
from nerfstudio.cameras import camera_utils
from nerfstudio.cameras.cameras import CAMERA_MODEL_TO_TYPE, Cameras, CameraType
@@ -46,7 +45,11 @@ class NerfstudioDataParserConfig(DataParserConfig):
_target: Type = field(default_factory=lambda: Nerfstudio)
"""target class to instantiate"""
+<<<<<<< HEAD
data: Path = Path("data/nerfstudio")
+=======
+ data: Path = Path()
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
"""Directory or explicit json file path specifying location of data."""
scale_factor: float = 1.0
"""How much to scale the camera origins by."""
@@ -76,6 +79,8 @@ class Nerfstudio(DataParser):
def _generate_dataparser_outputs(self, split="train"):
# pylint: disable=too-many-statements
+ assert self.config.data.exists(), f"Data directory {self.config.data} does not exist."
+
if self.config.data.suffix == ".json":
meta = load_from_json(self.config.data)
data_dir = self.config.data.parent
diff --git a/nerfstudio/data/dataparsers/nuscenes_dataparser.py b/nerfstudio/data/dataparsers/nuscenes_dataparser.py
index 6b35cf356..99b75a214 100644
--- a/nerfstudio/data/dataparsers/nuscenes_dataparser.py
+++ b/nerfstudio/data/dataparsers/nuscenes_dataparser.py
@@ -17,13 +17,12 @@ import math
import os
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Optional, Tuple, Type
+from typing import Literal, Optional, Tuple, Type
import numpy as np
import pyquaternion
import torch
from nuscenes.nuscenes import NuScenes as NuScenesDatabase
-from typing_extensions import Literal
from nerfstudio.cameras.cameras import Cameras, CameraType
from nerfstudio.data.dataparsers.base_dataparser import (
@@ -56,7 +55,7 @@ class NuScenesDataParserConfig(DataParserConfig):
Each clip was recorded with a suite of sensors including 6 surround cameras.
It also includes 3D cuboid annotations around objects.
We optionally use these cuboids to mask dynamic objects by specifying the mask_dir flag.
- To create these masks use scripts/datasets/process_nuscenes_masks.py.
+ To create these masks use nerfstudio/scripts/datasets/process_nuscenes_masks.py.
"""
_target: Type = field(default_factory=lambda: NuScenes)
diff --git a/nerfstudio/data/dataparsers/phototourism_dataparser.py b/nerfstudio/data/dataparsers/phototourism_dataparser.py
index e5a88e10e..8b6049c64 100644
--- a/nerfstudio/data/dataparsers/phototourism_dataparser.py
+++ b/nerfstudio/data/dataparsers/phototourism_dataparser.py
@@ -18,12 +18,11 @@ from __future__ import annotations
import math
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Type
+from typing import Literal, Type
import numpy as np
import torch
from rich.progress import Console
-from typing_extensions import Literal
from nerfstudio.cameras import camera_utils
from nerfstudio.cameras.cameras import Cameras, CameraType
@@ -136,8 +135,8 @@ class Phototourism(DataParser):
) # equally spaced training images starting and ending at 0 and num_images-1
i_eval = np.setdiff1d(i_all, i_train) # eval images are the remaining images
i_all = torch.tensor(i_all)
- i_train = torch.tensor(i_train)
- i_eval = torch.tensor(i_eval)
+ i_train = torch.tensor(i_train, dtype=torch.long)
+ i_eval = torch.tensor(i_eval, dtype=torch.long)
assert len(i_eval) == num_eval_images
if split == "train":
indices = i_train
diff --git a/nerfstudio/data/dataparsers/scannet_dataparser.py b/nerfstudio/data/dataparsers/scannet_dataparser.py
index d5a787799..eb0493926 100644
--- a/nerfstudio/data/dataparsers/scannet_dataparser.py
+++ b/nerfstudio/data/dataparsers/scannet_dataparser.py
@@ -16,7 +16,7 @@
import math
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Type
+from typing import Literal, Type
import cv2
import numpy as np
@@ -39,10 +39,14 @@ class ScanNetDataParserConfig(DataParserConfig):
ScanNet dataset (https://www.scan-net.org/) is a large-scale 3D dataset of indoor scenes.
This dataparser assumes that the dense stream was extracted from .sens files.
Expected structure of scene directory:
- - color/
- - depth/
- - intrinsic/
- - pose/
+
+ .. code-block:: text
+
+ root/
+ ├── color/
+ ├── depth/
+ ├── intrinsic/
+ ├── pose/
"""
_target: Type = field(default_factory=lambda: ScanNet)
diff --git a/nerfstudio/data/dataparsers/sdfstudio_dataparser.py b/nerfstudio/data/dataparsers/sdfstudio_dataparser.py
index 9b692c65b..97c7a299d 100644
--- a/nerfstudio/data/dataparsers/sdfstudio_dataparser.py
+++ b/nerfstudio/data/dataparsers/sdfstudio_dataparser.py
@@ -51,11 +51,11 @@ class SDFStudioDataParserConfig(DataParserConfig):
scene_scale: float = 2.0
"""
Sets the bounding cube to have edge length of this size.
- The longest dimension of the Friends axis-aligned bbox will be scaled to this value.
+ The longest dimension of the axis-aligned bbox will be scaled to this value.
"""
skip_every_for_val_split: int = 1
"""sub sampling validation images"""
- auto_orient: bool = False
+ auto_orient: bool = True
@dataclass
@@ -141,8 +141,8 @@ class SDFStudio(DataParser):
# TODO supports downsample
# cameras.rescale_output_resolution(scaling_factor=1.0 / self.config.downscale_factor)
-
- assert meta["has_mono_prior"] == self.config.include_mono_prior, f"no mono prior in {self.config.data}"
+ if self.config.include_mono_prior:
+ assert meta["has_mono_prior"], f"no mono prior in {self.config.data}"
dataparser_outputs = DataparserOutputs(
image_filenames=image_filenames,
diff --git a/nerfstudio/data/dataparsers/sitcoms3d_dataparser.py b/nerfstudio/data/dataparsers/sitcoms3d_dataparser.py
index b6906ce22..6dfc8896b 100644
--- a/nerfstudio/data/dataparsers/sitcoms3d_dataparser.py
+++ b/nerfstudio/data/dataparsers/sitcoms3d_dataparser.py
@@ -65,7 +65,6 @@ class Sitcoms3D(DataParser):
config: Sitcoms3DDataParserConfig
def _generate_dataparser_outputs(self, split="train"): # pylint: disable=unused-argument,too-many-statements
-
cameras_json = load_from_json(self.config.data / "cameras.json")
frames = cameras_json["frames"]
bbox = torch.tensor(cameras_json["bbox"])
diff --git a/nerfstudio/data/pixel_samplers.py b/nerfstudio/data/pixel_samplers.py
index 244498df8..74374f381 100644
--- a/nerfstudio/data/pixel_samplers.py
+++ b/nerfstudio/data/pixel_samplers.py
@@ -96,11 +96,12 @@ class PixelSampler: # pylint: disable=too-few-public-methods
indices = self.sample_method(num_rays_per_batch, num_images, image_height, image_width, device=device)
c, y, x = (i.flatten() for i in torch.split(indices, 1, dim=-1))
+ c, y, x = c.cpu(), y.cpu(), x.cpu()
collated_batch = {
key: value[c, y, x] for key, value in batch.items() if key != "image_idx" and value is not None
}
- assert collated_batch["image"].shape == (num_rays_per_batch, 3), collated_batch["image"].shape
+ assert collated_batch["image"].shape[0] == num_rays_per_batch
# Needed to correct the random indices to their actual camera idx locations.
indices[:, 0] = batch["image_idx"][c]
@@ -136,7 +137,6 @@ class PixelSampler: # pylint: disable=too-few-public-methods
if "mask" in batch:
num_rays_in_batch = num_rays_per_batch // num_images
for i in range(num_images):
-
image_height, image_width, _ = batch["image"][i].shape
if i == num_images - 1:
@@ -171,7 +171,7 @@ class PixelSampler: # pylint: disable=too-few-public-methods
collated_batch["image"] = torch.cat(all_images, dim=0)
- assert collated_batch["image"].shape == (num_rays_per_batch, 3), collated_batch["image"].shape
+ assert collated_batch["image"].shape[0] == num_rays_per_batch
# Needed to correct the random indices to their actual camera idx locations.
indices[:, 0] = batch["image_idx"][c]
@@ -221,7 +221,6 @@ class EquirectangularPixelSampler(PixelSampler): # pylint: disable=too-few-publ
mask: Optional[TensorType] = None,
device: Union[torch.device, str] = "cpu",
) -> TensorType["batch_size", 3]:
-
if isinstance(mask, torch.Tensor):
# Note: if there is a mask, sampling reduces back to uniform sampling, which gives more
# sampling weight to the poles of the image than the equators.
@@ -229,7 +228,6 @@ class EquirectangularPixelSampler(PixelSampler): # pylint: disable=too-few-publ
indices = super().sample_method(batch_size, num_images, image_height, image_width, mask=mask, device=device)
else:
-
# We sample theta uniformly in [0, 2*pi]
# We sample phi in [0, pi] according to the PDF f(phi) = sin(phi) / 2.
# This is done by inverse transform sampling.
@@ -279,7 +277,6 @@ class PatchPixelSampler(PixelSampler): # pylint: disable=too-few-public-methods
mask: Optional[TensorType] = None,
device: Union[torch.device, str] = "cpu",
) -> TensorType["batch_size", 3]:
-
if mask:
# Note: if there is a mask, sampling reduces back to uniform sampling
indices = super().sample_method(batch_size, num_images, image_height, image_width, mask=mask, device=device)
diff --git a/nerfstudio/data/scene_box.py b/nerfstudio/data/scene_box.py
index e28761e29..e513a1428 100644
--- a/nerfstudio/data/scene_box.py
+++ b/nerfstudio/data/scene_box.py
@@ -17,7 +17,7 @@ Dataset input structures.
"""
from dataclasses import dataclass
-from typing import Dict, Union
+from typing import Union
import torch
from torchtyping import TensorType
@@ -64,21 +64,6 @@ class SceneBox:
normalized_positions = (positions - aabb[0]) / aabb_lengths
return normalized_positions
- def to_json(self) -> Dict:
- """Returns a json object from the Python object."""
- return {"type": "aabb", "min_point": self.aabb[0].tolist(), "max_point": self.aabb[1].tolist()}
-
- @staticmethod
- def from_json(json_: Dict) -> "SceneBox":
- """Returns the an instance of SceneBox from a json dictionary.
-
- Args:
- json_: the json dictionary containing scene box information
- """
- assert json_["type"] == "aabb"
- aabb = torch.tensor([json_[0], json_[1]])
- return SceneBox(aabb=aabb)
-
@staticmethod
def from_camera_poses(poses: TensorType[..., 3, 4], scale_factor: float) -> "SceneBox":
"""Returns the instance of SceneBox that fully envelopes a set of poses
diff --git a/nerfstudio/data/utils/dataloaders.py b/nerfstudio/data/utils/dataloaders.py
index 23d712d7e..aa30407ea 100644
--- a/nerfstudio/data/utils/dataloaders.py
+++ b/nerfstudio/data/utils/dataloaders.py
@@ -225,30 +225,16 @@ class FixedIndicesEvalDataloader(EvalDataloader):
class RandIndicesEvalDataloader(EvalDataloader):
"""Dataloader that returns random images.
-
Args:
input_dataset: InputDataset to load data from
device: Device to load data to
"""
- def __init__(
- self,
- input_dataset: InputDataset,
- device: Union[torch.device, str] = "cpu",
- **kwargs,
- ):
- super().__init__(input_dataset, device, **kwargs)
- self.count = 0
-
def __iter__(self):
- self.count = 0
return self
def __next__(self):
- if self.count < 1:
- image_indices = range(self.cameras.size)
- image_idx = random.choice(image_indices)
- ray_bundle, batch = self.get_data_from_image_idx(image_idx)
- self.count += 1
- return ray_bundle, batch
- raise StopIteration
+ # choose a random image index
+ image_idx = random.randint(0, len(self.cameras) - 1)
+ ray_bundle, batch = self.get_data_from_image_idx(image_idx)
+ return ray_bundle, batch
diff --git a/nerfstudio/data/utils/nerfstudio_collate.py b/nerfstudio/data/utils/nerfstudio_collate.py
index ffcd989b4..91774343a 100644
--- a/nerfstudio/data/utils/nerfstudio_collate.py
+++ b/nerfstudio/data/utils/nerfstudio_collate.py
@@ -23,7 +23,6 @@ from typing import Callable, Dict, Union
import torch
import torch.utils.data
-from torch._six import string_classes
from nerfstudio.cameras.cameras import Cameras
@@ -119,7 +118,7 @@ def nerfstudio_collate(
return torch.tensor(batch, dtype=torch.float64)
elif isinstance(elem, int):
return torch.tensor(batch)
- elif isinstance(elem, string_classes):
+ elif isinstance(elem, (str, bytes)):
return batch
elif isinstance(elem, collections.abc.Mapping):
try:
diff --git a/nerfstudio/engine/schedulers.py b/nerfstudio/engine/schedulers.py
index 48a656650..a67e2c697 100644
--- a/nerfstudio/engine/schedulers.py
+++ b/nerfstudio/engine/schedulers.py
@@ -18,11 +18,10 @@
from abc import abstractmethod
from dataclasses import dataclass, field
-from typing import Optional, Type
+from typing import Literal, Optional, Tuple, Type
import numpy as np
from torch.optim import Optimizer, lr_scheduler
-from typing_extensions import Literal
from nerfstudio.configs.base_config import InstantiateConfig
@@ -56,6 +55,34 @@ class Scheduler:
"""
+@dataclass
+class MultiStepSchedulerConfig(SchedulerConfig):
+ """Config for multi step scheduler where lr decays by gamma every milestone"""
+
+ _target: Type = field(default_factory=lambda: MultiStepScheduler)
+ """target class to instantiate"""
+ max_steps: int = 1000000
+ """The maximum number of steps."""
+ gamma: float = 0.33
+ """The learning rate decay factor."""
+ milestones: Tuple[int, ...] = (500000, 750000, 900000)
+ """The milestone steps at which to decay the learning rate."""
+
+
+class MultiStepScheduler(Scheduler):
+ """Multi step scheduler where lr decays by gamma every milestone"""
+
+ config: MultiStepSchedulerConfig
+
+ def get_scheduler(self, optimizer: Optimizer, lr_init: float) -> lr_scheduler._LRScheduler:
+ scheduler = lr_scheduler.MultiStepLR(
+ optimizer=optimizer,
+ milestones=self.config.milestones,
+ gamma=self.config.gamma,
+ )
+ return scheduler
+
+
@dataclass
class ExponentialDecaySchedulerConfig(SchedulerConfig):
"""Config for exponential decay scheduler with warmup"""
@@ -111,7 +138,11 @@ class ExponentialDecayScheduler(Scheduler):
@dataclass
class CosineDecaySchedulerConfig(SchedulerConfig):
+<<<<<<< HEAD
"""Basic scheduler config with self-defined exponential decay schedule"""
+=======
+ """Config for cosine decay schedule"""
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
_target: Type = field(default_factory=lambda: CosineDecayScheduler)
"""target class to instantiate"""
@@ -124,7 +155,11 @@ class CosineDecaySchedulerConfig(SchedulerConfig):
class CosineDecayScheduler(Scheduler):
+<<<<<<< HEAD
"""Starts with a flat lr schedule until it reaches N epochs then applies a given scheduler"""
+=======
+ """Cosine decay scheduler with linear warmup"""
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
config: CosineDecaySchedulerConfig
diff --git a/nerfstudio/engine/trainer.py b/nerfstudio/engine/trainer.py
index 97ff9244a..ae36d2326 100644
--- a/nerfstudio/engine/trainer.py
+++ b/nerfstudio/engine/trainer.py
@@ -23,12 +23,15 @@ import os
import time
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Dict, List, Optional, Tuple, Type, Union
+from threading import Lock
+from typing import Dict, List, Literal, Optional, Tuple, Type, Union
import torch
+from rich import box, style
from rich.console import Console
+from rich.panel import Panel
+from rich.table import Table
from torch.cuda.amp.grad_scaler import GradScaler
-from typing_extensions import Literal
from nerfstudio.configs.experiment_config import ExperimentConfig
from nerfstudio.engine.callbacks import (
@@ -46,7 +49,7 @@ from nerfstudio.utils.decorators import (
)
from nerfstudio.utils.misc import step_check
from nerfstudio.utils.writer import EventName, TimeWriter
-from nerfstudio.viewer.server import viewer_utils
+from nerfstudio.viewer.server.viewer_state import ViewerState
CONSOLE = Console(width=120)
@@ -74,6 +77,8 @@ class TrainerConfig(ExperimentConfig):
"""Maximum number of iterations to run."""
mixed_precision: bool = False
"""Whether or not to use mixed precision for training."""
+ use_grad_scaler: bool = False
+ """Use gradient scaler even if the automatic mixed precision is disabled."""
save_only_latest_checkpoint: bool = True
"""Whether to only save the latest checkpoint or all checkpoints."""
# optional parameters if we want to resume training
@@ -83,6 +88,8 @@ class TrainerConfig(ExperimentConfig):
"""Optionally specify model step to load from; if none, will find most recent model in load_dir."""
load_config: Optional[Path] = None
"""Path to config YAML file."""
+ load_checkpoint: Optional[Path] = None
+ """Path to checkpoint file."""
log_gradients: bool = False
"""Optionally log gradients during training"""
@@ -103,6 +110,7 @@ class Trainer:
pipeline: The pipeline object.
optimizers: The optimizers object.
callbacks: The callbacks object.
+ training_state: Current model training state.
"""
pipeline: VanillaPipeline
@@ -110,17 +118,21 @@ class Trainer:
callbacks: List[TrainingCallback]
def __init__(self, config: TrainerConfig, local_rank: int = 0, world_size: int = 1) -> None:
+ self.train_lock = Lock()
self.config = config
self.local_rank = local_rank
self.world_size = world_size
self.device: TORCH_DEVICE = "cpu" if world_size == 0 else f"cuda:{local_rank}"
self.mixed_precision: bool = self.config.mixed_precision
+ self.use_grad_scaler: bool = self.mixed_precision or self.config.use_grad_scaler
+ self.training_state: Literal["training", "paused", "completed"] = "training"
+
if self.device == "cpu":
self.mixed_precision = False
CONSOLE.print("Mixed precision is disabled for CPU training.")
self._start_step: int = 0
# optimizers
- self.grad_scaler = GradScaler(enabled=self.mixed_precision)
+ self.grad_scaler = GradScaler(enabled=self.use_grad_scaler)
self.base_dir: Path = config.get_base_dir()
# directory to save checkpoints
@@ -147,6 +159,24 @@ class Trainer:
)
self.optimizers = self.setup_optimizers()
+ # set up viewer if enabled
+ viewer_log_path = self.base_dir / self.config.viewer.relative_log_filename
+ self.viewer_state, banner_messages = None, None
+ if self.config.is_viewer_enabled() and self.local_rank == 0:
+ datapath = self.config.data
+ if datapath is None:
+ datapath = self.base_dir
+ self.viewer_state = ViewerState(
+ self.config.viewer,
+ log_filename=viewer_log_path,
+ datapath=datapath,
+ pipeline=self.pipeline,
+ trainer=self,
+ train_lock=self.train_lock,
+ )
+ banner_messages = [f"Viewer at: {self.viewer_state.viewer_url}"]
+ self._check_viewer_warnings()
+
self._load_checkpoint()
self.callbacks = self.pipeline.get_training_callbacks(
@@ -157,27 +187,20 @@ class Trainer:
)
)
- # set up viewer if enabled
- viewer_log_path = self.base_dir / self.config.viewer.relative_log_filename
- self.viewer_state, banner_messages = None, None
- if self.config.is_viewer_enabled() and self.local_rank == 0:
- datapath = self.pipeline.datamanager.get_datapath()
- if datapath is None:
- datapath = self.base_dir
- self.viewer_state, banner_messages = viewer_utils.setup_viewer(
- self.config.viewer, log_filename=viewer_log_path, datapath=datapath
- )
- self._check_viewer_warnings()
# set up writers/profilers if enabled
writer_log_path = self.base_dir / self.config.logging.relative_log_dir
writer.setup_event_writer(
- self.config.is_wandb_enabled(), self.config.is_tensorboard_enabled(), log_dir=writer_log_path
+ self.config.is_wandb_enabled(),
+ self.config.is_tensorboard_enabled(),
+ log_dir=writer_log_path,
+ experiment_name=self.config.experiment_name,
+ project_name=self.config.project_name,
)
writer.setup_local_writer(
self.config.logging, max_iter=self.config.max_num_iterations, banner_messages=banner_messages
)
writer.put_config(name="config", config_dict=dataclasses.asdict(self.config), step=0)
- profiler.setup_profiler(self.config.logging)
+ profiler.setup_profiler(self.config.logging, writer_log_path)
def setup_optimizers(self) -> Optimizers:
"""Helper to set up the optimizers
@@ -210,21 +233,26 @@ class Trainer:
num_iterations = self.config.max_num_iterations
step = 0
for step in range(self._start_step, self._start_step + num_iterations):
- with TimeWriter(writer, EventName.ITER_TRAIN_TIME, step=step) as train_t:
- self.pipeline.train()
+ while self.training_state == "paused":
+ time.sleep(0.01)
+ with self.train_lock:
+ with TimeWriter(writer, EventName.ITER_TRAIN_TIME, step=step) as train_t:
+ self.pipeline.train()
- # training callbacks before the training iteration
- for callback in self.callbacks:
- callback.run_callback_at_location(
- step, location=TrainingCallbackLocation.BEFORE_TRAIN_ITERATION
- )
+ # training callbacks before the training iteration
+ for callback in self.callbacks:
+ callback.run_callback_at_location(
+ step, location=TrainingCallbackLocation.BEFORE_TRAIN_ITERATION
+ )
- # time the forward pass
- loss, loss_dict, metrics_dict = self.train_iteration(step)
+ # time the forward pass
+ loss, loss_dict, metrics_dict = self.train_iteration(step)
- # training callbacks after the training iteration
- for callback in self.callbacks:
- callback.run_callback_at_location(step, location=TrainingCallbackLocation.AFTER_TRAIN_ITERATION)
+ # training callbacks after the training iteration
+ for callback in self.callbacks:
+ callback.run_callback_at_location(
+ step, location=TrainingCallbackLocation.AFTER_TRAIN_ITERATION
+ )
# Skip the first two steps to avoid skewed timings that break the viewer rendering speed estimate.
if step > 1:
@@ -242,6 +270,14 @@ class Trainer:
writer.put_scalar(name="Train Loss", scalar=loss, step=step)
writer.put_dict(name="Train Loss Dict", scalar_dict=loss_dict, step=step)
writer.put_dict(name="Train Metrics Dict", scalar_dict=metrics_dict, step=step)
+ # The actual memory allocated by Pytorch. This is likely less than the amount
+ # shown in nvidia-smi since some unused memory can be held by the caching
+ # allocator and some context needs to be created on GPU. See Memory management
+ # (https://pytorch.org/docs/stable/notes/cuda.html#cuda-memory-management)
+ # for more details about GPU memory management.
+ writer.put_scalar(
+ name="GPU Memory (MB)", scalar=torch.cuda.max_memory_allocated() / (1024**2), step=step
+ )
# Do not perform evaluation if there are no validation images
if self.pipeline.datamanager.eval_dataset:
@@ -258,18 +294,18 @@ class Trainer:
# write out any remaining events (e.g., total train time)
writer.write_out_storage()
- CONSOLE.rule()
- CONSOLE.print("[bold green]:tada: :tada: :tada: Training Finished :tada: :tada: :tada:", justify="center")
- if not self.config.viewer.quit_on_train_completion:
- CONSOLE.print("Use ctrl+c to quit", justify="center")
- self._always_render(step)
+ table = Table(
+ title=None,
+ show_header=False,
+ box=box.MINIMAL,
+ title_style=style.Style(bold=True),
+ )
+ table.add_row("Config File", str(self.config.get_base_dir() / "config.yml"))
+ table.add_row("Checkpoint Directory", str(self.checkpoint_dir))
+ CONSOLE.print(Panel(table, title="[bold][green]:tada: Training Finished :tada:[/bold]", expand=False))
- @check_main_thread
- def _always_render(self, step: int) -> None:
- if self.viewer_state is not None:
- while True:
- self.viewer_state.vis["renderingState/isTraining"].write(False)
- self._update_viewer_state(step)
+ if not self.config.viewer.quit_on_train_completion:
+ self._train_complete_viewer()
@check_main_thread
def _check_viewer_warnings(self) -> None:
@@ -291,10 +327,8 @@ class Trainer:
assert self.viewer_state and self.pipeline.datamanager.train_dataset
self.viewer_state.init_scene(
dataset=self.pipeline.datamanager.train_dataset,
- start_train=self.config.viewer.start_train,
+ train_state="training",
)
- if not self.config.viewer.start_train:
- self._always_render(self._start_step)
@check_viewer_enabled
def _update_viewer_state(self, step: int) -> None:
@@ -305,16 +339,26 @@ class Trainer:
step: current train step
"""
assert self.viewer_state is not None
- with TimeWriter(writer, EventName.ITER_VIS_TIME, step=step) as _:
- num_rays_per_batch: int = self.pipeline.datamanager.get_train_rays_per_batch()
- try:
- self.viewer_state.update_scene(self, step, self.pipeline.model, num_rays_per_batch)
- except RuntimeError:
- time.sleep(0.03) # sleep to allow buffer to reset
- assert self.viewer_state.vis is not None
- self.viewer_state.vis["renderingState/log_errors"].write(
- "Error: GPU out of memory. Reduce resolution to prevent viewer from crashing."
- )
+ num_rays_per_batch: int = self.pipeline.datamanager.get_train_rays_per_batch()
+ try:
+ self.viewer_state.update_scene(step, num_rays_per_batch)
+ except RuntimeError:
+ time.sleep(0.03) # sleep to allow buffer to reset
+ CONSOLE.log("Viewer failed. Continuing training.")
+
+ @check_viewer_enabled
+ def _train_complete_viewer(self) -> None:
+ """Let the viewer know that the training is complete"""
+ assert self.viewer_state is not None
+ self.training_state = "completed"
+ try:
+ self.viewer_state.training_complete()
+ except RuntimeError:
+ time.sleep(0.03) # sleep to allow buffer to reset
+ CONSOLE.log("Viewer failed. Continuing training.")
+ CONSOLE.print("Use ctrl+c to quit", justify="center")
+ while True:
+ time.sleep(0.01)
@check_viewer_enabled
def _update_viewer_rays_per_sec(self, train_t: TimeWriter, vis_t: TimeWriter, step: int) -> None:
@@ -336,10 +380,11 @@ class Trainer:
def _load_checkpoint(self) -> None:
"""Helper function to load pipeline and optimizer from prespecified checkpoint"""
load_dir: Path = self.config.load_dir
+ load_checkpoint: Path = self.config.load_checkpoint
if load_dir is not None:
load_step = self.config.load_step
if load_step is None:
- print("Loading latest checkpoint from load_dir")
+ print("Loading latest Nerfstudio checkpoint from load_dir...")
# NOTE: this is specific to the checkpoint name format
load_step = sorted(int(x[x.find("-") + 1 : x.find(".")]) for x in os.listdir(load_dir))[-1]
load_path: Path = load_dir / f"step-{load_step:09d}.ckpt"
@@ -350,9 +395,18 @@ class Trainer:
self.pipeline.load_pipeline(loaded_state["pipeline"], loaded_state["step"])
self.optimizers.load_optimizers(loaded_state["optimizers"])
self.grad_scaler.load_state_dict(loaded_state["scalers"])
- CONSOLE.print(f"done loading checkpoint from {load_path}")
+ CONSOLE.print(f"Done loading Nerfstudio checkpoint from {load_path}")
+ elif load_checkpoint is not None:
+ assert load_checkpoint.exists(), f"Checkpoint {load_checkpoint} does not exist"
+ loaded_state = torch.load(load_checkpoint, map_location="cpu")
+ self._start_step = loaded_state["step"] + 1
+ # load the checkpoints for pipeline, optimizers, and gradient scalar
+ self.pipeline.load_pipeline(loaded_state["pipeline"], loaded_state["step"])
+ self.optimizers.load_optimizers(loaded_state["optimizers"])
+ self.grad_scaler.load_state_dict(loaded_state["scalers"])
+ CONSOLE.print(f"Done loading Nerfstudio checkpoint from {load_checkpoint}")
else:
- CONSOLE.print("No checkpoints to load, training from scratch")
+ CONSOLE.print("No Nerfstudio checkpoint to load, so training from scratch.")
@check_main_thread
def save_checkpoint(self, step: int) -> None:
@@ -391,8 +445,10 @@ class Trainer:
Args:
step: Current training step.
"""
+
self.optimizers.zero_grad_all()
cpu_or_cuda_str: str = self.device.split(":")[0]
+
with torch.autocast(device_type=cpu_or_cuda_str, enabled=self.mixed_precision):
_, loss_dict, metrics_dict = self.pipeline.get_train_loss_dict(step=step)
loss = functools.reduce(torch.add, loss_dict.values())
@@ -410,8 +466,11 @@ class Trainer:
metrics_dict["Gradients/Total"] = total_grad
+ scale = self.grad_scaler.get_scale()
self.grad_scaler.update()
- self.optimizers.scheduler_step_all(step)
+ # If the gradient scaler is decreased, no optimization step is performed so we should not step the scheduler.
+ if scale <= self.grad_scaler.get_scale():
+ self.optimizers.scheduler_step_all(step)
# Merging loss and metrics dict into a single output.
return loss, loss_dict, metrics_dict
diff --git a/nerfstudio/exporter/marching_cubes.py b/nerfstudio/exporter/marching_cubes.py
new file mode 100644
index 000000000..a88dc9017
--- /dev/null
+++ b/nerfstudio/exporter/marching_cubes.py
@@ -0,0 +1,252 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+This module implements the Marching Cubes algorithm for extracting
+isosurfaces
+"""
+
+from typing import Callable, List, Tuple, Union
+
+import numpy as np
+import torch
+import trimesh
+from skimage import measure
+from torchtyping import TensorType
+
+avg_pool_3d = torch.nn.AvgPool3d(2, stride=2)
+upsample = torch.nn.Upsample(scale_factor=2, mode="nearest")
+
+
+def create_point_pyramid(
+ points: TensorType[3, "height", "width", "depth"]
+) -> List[TensorType[3, "height", "width", "depth"]]:
+ """
+ Create a point pyramid for multi-resolution evaluation.
+
+ Args:
+ points: A torch tensor containing 3D points.
+
+ Returns:
+ A list of torch tensors representing points at different resolutions.
+ """
+ points_pyramid = [points]
+ for _ in range(3):
+ points = avg_pool_3d(points[None])[0]
+ points_pyramid.append(points)
+ points_pyramid = points_pyramid[::-1]
+ return points_pyramid
+
+
+def evaluate_sdf(sdf: Callable, points: TensorType["batch", 3]) -> TensorType["batch"]:
+ """
+ Evaluate a signed distance function (SDF) for a batch of points.
+
+ Args:
+ sdf: A callable function that takes a tensor of size (N, 3) containing
+ 3D points and returns a tensor of size (N,) with the SDF values.
+ points: A torch tensor containing 3D points.
+
+ Returns:
+ A torch tensor with the SDF values evaluated at the given points.
+ """
+ z = []
+ for _, pnts in enumerate(torch.split(points, 100000, dim=0)):
+ z.append(sdf(pnts))
+ z = torch.cat(z, axis=0)
+ return z
+
+
+def evaluate_multiresolution_sdf(
+ evaluate: Callable,
+ points_pyramid: List[TensorType[3, "height", "width", "depth"]],
+ coarse_mask: Union[TensorType[1, 1, "height", "width", "depth"], None],
+ x_max: float,
+ x_min: float,
+ crop_n: int,
+) -> TensorType["batch"]:
+ """
+ Evaluate SDF values using a multi-resolution approach with a given point pyramid.
+
+ Args:
+ evaluate: A callable function to evaluate SDF values at given points.
+ points_pyramid: A list of torch tensors representing points at different resolutions.
+ coarse_mask: A binary mask tensor indicating regions of the bounding box where the SDF
+ is expected to have a zero-crossing.
+ x_max: The maximum x-coordinate of the bounding box.
+ x_min: The minimum x-coordinate of the bounding box.
+ crop_n: The resolution of the grid used to sample the SDF.
+
+ Returns:
+ A torch tensor with the SDF values evaluated at the given points.
+ """
+ mask = None
+ threshold = 2 * (x_max - x_min) / crop_n * 8
+ for pid, pts in enumerate(points_pyramid):
+ coarse_n = pts.shape[-1]
+ pts = pts.reshape(3, -1).permute(1, 0).contiguous()
+
+ if mask is None:
+ # Only evaluate SDF
+ if coarse_mask is not None:
+ pts_sdf = torch.ones_like(pts[:, 1])
+ valid_mask = torch.nn.functional.grid_sample(coarse_mask, pts[None, None, None])[0, 0, 0, 0] > 0
+ if valid_mask.any():
+ pts_sdf[valid_mask] = evaluate(pts[valid_mask].contiguous())
+ else:
+ pts_sdf = evaluate(pts)
+ else:
+ mask = mask.reshape(-1)
+ pts_to_eval = pts[mask]
+
+ if pts_to_eval.shape[0] > 0:
+ pts_sdf_eval = evaluate(pts_to_eval.contiguous())
+ pts_sdf[mask] = pts_sdf_eval
+
+ if pid < 3:
+ # Update mask
+ mask = torch.abs(pts_sdf) < threshold
+ mask = mask.reshape(coarse_n, coarse_n, coarse_n)[None, None]
+ mask = upsample(mask.float()).bool()
+
+ pts_sdf = pts_sdf.reshape(coarse_n, coarse_n, coarse_n)[None, None]
+ pts_sdf = upsample(pts_sdf)
+ pts_sdf = pts_sdf.reshape(-1)
+
+ threshold /= 2.0
+ return pts_sdf
+
+
+@torch.no_grad()
+def generate_mesh_with_multires_marching_cubes(
+ geometry_callable_field: Callable,
+ resolution: int = 512,
+ bounding_box_min: Tuple[float, float, float] = (-1.0, -1.0, -1.0),
+ bounding_box_max: Tuple[float, float, float] = (1.0, 1.0, 1.0),
+ isosurface_threshold: float = 0.0,
+ coarse_mask: Union[None, TensorType["height", "width", "depth"]] = None,
+) -> trimesh.Trimesh:
+ """
+ Computes the isosurface of a signed distance function (SDF) defined by the
+ callable `sdf` in a given bounding box with a specified resolution. The SDF
+ is sampled at a set of points within a regular grid, and the marching cubes
+ algorithm is used to generate a mesh that approximates the isosurface at a
+ specified isovalue `level`.
+
+ Args:
+ sdf: A callable function that takes as input a tensor of size
+ (N, 3) containing 3D points, and returns a tensor of size (N,) containing
+ the signed distance function evaluated at those points.
+ output_path: The output directory where the resulting mesh will be saved.
+ resolution: The resolution of the grid used to sample the SDF.
+ bounding_box_min: The minimum coordinates of the bounding box in which the SDF
+ will be evaluated.
+ bounding_box_max: The maximum coordinates of the bounding box in which the SDF
+ will be evaluated.
+ isosurface_threshold: The isovalue at which to approximate the isosurface.
+ coarse_mask: A binary mask tensor of size ("height", "width", "depth") that indicates the regions
+ of the bounding box where the SDF is expected to have a zero-crossing. If
+ provided, the algorithm first evaluates the SDF at the coarse voxels where
+ the mask is True, and then refines the evaluation within these voxels using
+ a multi-scale approach. If None, evaluates the SDF at all points in the
+ bounding box.
+ Returns:
+ A torch tensor with the SDF values evaluated at the given points.
+ """
+ # Check if resolution is divisible by 512
+ assert (
+ resolution % 512 == 0
+ ), f"""resolution must be divisible by 512, got {resolution}.
+ This is important because the algorithm uses a multi-resolution approach
+ to evaluate the SDF where the mimimum resolution is 512."""
+ # Prepare coarse mask if provided
+ if coarse_mask is not None:
+ coarse_mask = coarse_mask.permute(2, 1, 0)[None, None].cuda().float()
+
+ # Initialize variables
+ crop_n = 512
+ N = resolution // crop_n
+ grid_min = bounding_box_min
+ grid_max = bounding_box_max
+ xs = np.linspace(grid_min[0], grid_max[0], N + 1)
+ ys = np.linspace(grid_min[1], grid_max[1], N + 1)
+ zs = np.linspace(grid_min[2], grid_max[2], N + 1)
+
+ # Initialize meshes list
+ meshes = []
+
+ # Iterate over the grid
+ for i in range(N):
+ for j in range(N):
+ for k in range(N):
+ # Calculate grid cell boundaries
+ x_min, x_max = xs[i], xs[i + 1]
+ y_min, y_max = ys[j], ys[j + 1]
+ z_min, z_max = zs[k], zs[k + 1]
+
+ # Create point grid
+ x = np.linspace(x_min, x_max, crop_n)
+ y = np.linspace(y_min, y_max, crop_n)
+ z = np.linspace(z_min, z_max, crop_n)
+ xx, yy, zz = np.meshgrid(x, y, z, indexing="ij")
+ points = torch.tensor(np.vstack([xx.ravel(), yy.ravel(), zz.ravel()]).T, dtype=torch.float).cuda()
+
+ # Function to evaluate SDF for a batch of points
+ def evaluate(points: torch.Tensor) -> torch.Tensor:
+ return evaluate_sdf(geometry_callable_field, points)
+
+ # Construct point pyramids
+ points = points.reshape(crop_n, crop_n, crop_n, 3).permute(3, 0, 1, 2)
+ if coarse_mask is not None:
+ points_tmp = points.permute(1, 2, 3, 0)[None].cuda()
+ current_mask = torch.nn.functional.grid_sample(coarse_mask, points_tmp)
+ current_mask = (current_mask > 0.0).cpu().numpy()[0, 0]
+ else:
+ current_mask = None
+
+ # Create point pyramid for multi-resolution evaluation
+ points_pyramid = create_point_pyramid(points)
+
+ # Evaluate SDF using multi-resolution approach and mask
+ pts_sdf = evaluate_multiresolution_sdf(evaluate, points_pyramid, coarse_mask, x_max, x_min, crop_n)
+
+ z = pts_sdf.detach().cpu().numpy()
+
+ # Skip if no surface found
+ if current_mask is not None:
+ valid_z = z.reshape(crop_n, crop_n, crop_n)[current_mask]
+ if valid_z.shape[0] <= 0 or (
+ np.min(valid_z) > isosurface_threshold or np.max(valid_z) < isosurface_threshold
+ ):
+ continue
+
+ if not (np.min(z) > isosurface_threshold or np.max(z) < isosurface_threshold):
+ z = z.astype(np.float32)
+ verts, faces, normals, _ = measure.marching_cubes(
+ volume=z.reshape(crop_n, crop_n, crop_n),
+ level=isosurface_threshold,
+ spacing=(
+ (x_max - x_min) / (crop_n - 1),
+ (y_max - y_min) / (crop_n - 1),
+ (z_max - z_min) / (crop_n - 1),
+ ),
+ mask=current_mask,
+ )
+ verts = verts + np.array([x_min, y_min, z_min])
+
+ meshcrop = trimesh.Trimesh(verts, faces, normals)
+ meshes.append(meshcrop)
+
+ combined_mesh: trimesh.Trimesh = trimesh.util.concatenate(meshes)
+ return combined_mesh
diff --git a/nerfstudio/exporter/texture_utils.py b/nerfstudio/exporter/texture_utils.py
index 4001d1c60..9c0bb0ee0 100644
--- a/nerfstudio/exporter/texture_utils.py
+++ b/nerfstudio/exporter/texture_utils.py
@@ -22,7 +22,7 @@ from __future__ import annotations
import math
from pathlib import Path
-from typing import Optional, Tuple, Union
+from typing import Literal, Optional, Tuple, Union
import mediapy as media
import numpy as np
@@ -30,7 +30,6 @@ import torch
import xatlas
from rich.console import Console
from torchtyping import TensorType
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.exporter.exporter_utils import Mesh
@@ -401,6 +400,7 @@ def export_textured_mesh(
camera_indices = torch.zeros_like(origins[..., 0:1])
nears = torch.zeros_like(origins[..., 0:1])
fars = torch.ones_like(origins[..., 0:1]) * raylen
+ directions_norm = torch.ones_like(origins[..., 0:1]) # for surface model
camera_ray_bundle = RayBundle(
origins=origins,
directions=directions,
@@ -408,6 +408,7 @@ def export_textured_mesh(
camera_indices=camera_indices,
nears=nears,
fars=fars,
+ metadata={"directions_norm": directions_norm},
)
CONSOLE.print("Creating texture image by rendering with NeRF...")
diff --git a/nerfstudio/field_components/encodings.py b/nerfstudio/field_components/encodings.py
index f77c17f4d..21dacbd0e 100644
--- a/nerfstudio/field_components/encodings.py
+++ b/nerfstudio/field_components/encodings.py
@@ -16,15 +16,15 @@
Encoding functions
"""
+import itertools
from abc import abstractmethod
-from typing import Optional
+from typing import Literal, Optional, Sequence
import numpy as np
import torch
import torch.nn.functional as F
from torch import nn
from torchtyping import TensorType
-from typing_extensions import Literal
from nerfstudio.field_components.base_field_component import FieldComponent
from nerfstudio.utils.math import components_from_spherical_harmonics, expected_sin
@@ -140,9 +140,9 @@ class NeRFEncoding(Encoding):
Returns:
Output values will be between -1 and 1
"""
- in_tensor = 2 * torch.pi * in_tensor # scale to [0, 2pi]
+ scaled_in_tensor = 2 * torch.pi * in_tensor # scale to [0, 2pi]
freqs = 2 ** torch.linspace(self.min_freq, self.max_freq, self.num_frequencies).to(in_tensor.device)
- scaled_inputs = in_tensor[..., None] * freqs # [..., "input_dim", "num_scales"]
+ scaled_inputs = scaled_in_tensor[..., None] * freqs # [..., "input_dim", "num_scales"]
scaled_inputs = scaled_inputs.view(*scaled_inputs.shape[:-2], -1) # [..., "input_dim" * "num_scales"]
if covs is None:
@@ -200,8 +200,8 @@ class RFFEncoding(Encoding):
Returns:
Output values will be between -1 and 1
"""
- in_tensor = 2 * torch.pi * in_tensor # scale to [0, 2pi]
- scaled_inputs = in_tensor @ self.b_matrix # [..., "num_frequencies"]
+ scaled_in_tensor = 2 * torch.pi * in_tensor # scale to [0, 2pi]
+ scaled_inputs = scaled_in_tensor @ self.b_matrix # [..., "num_frequencies"]
if covs is None:
encoded_inputs = torch.sin(torch.cat([scaled_inputs, scaled_inputs + torch.pi / 2.0], dim=-1))
@@ -242,7 +242,6 @@ class HashEncoding(Encoding):
implementation: Literal["tcnn", "torch"] = "tcnn",
interpolation: Optional[Literal["Nearest", "Linear", "Smoothstep"]] = None,
) -> None:
-
super().__init__(in_dim=3)
self.num_levels = num_levels
self.features_per_level = features_per_level
@@ -557,6 +556,87 @@ class TriplaneEncoding(Encoding):
self.resolution = resolution
+class KPlanesEncoding(Encoding):
+ """Learned K-Planes encoding
+
+ A plane encoding supporting both 3D and 4D coordinates. With 3D coordinates this is similar to
+ :class:`TriplaneEncoding`. With 4D coordinates, the encoding at point ``[i,j,k,q]`` is
+ a n-dimensional vector computed as the elementwise product of 6 n-dimensional vectors at
+ ``planes[i,j]``, ``planes[i,k]``, ``planes[i,q]``, ``planes[j,k]``, ``planes[j,q]``,
+ ``planes[k,q]``.
+
+ Unlike :class:`TriplaneEncoding` this class supports different resolution along each axis.
+
+ This will return a tensor of shape (bs:..., num_components)
+
+ Args:
+ resolution: Resolution of the grid. Can be a sequence of 3 or 4 integers.
+ num_components: The number of scalar planes to use (ie: output feature size)
+ init_a: The lower-bound of the uniform distribution used to initialize the spatial planes
+ init_b: The upper-bound of the uniform distribution used to initialize the spatial planes
+ reduce: Whether to use the element-wise product of the planes or the sum
+ """
+
+ def __init__(
+ self,
+ resolution: Sequence[int] = (128, 128, 128),
+ num_components: int = 64,
+ init_a: float = 0.1,
+ init_b: float = 0.5,
+ reduce: Literal["sum", "product"] = "product",
+ ) -> None:
+ super().__init__(in_dim=len(resolution))
+
+ self.resolution = resolution
+ self.num_components = num_components
+ self.reduce = reduce
+ if self.in_dim not in {3, 4}:
+ raise ValueError(
+ f"The dimension of coordinates must be either 3 (static scenes) "
+ f"or 4 (dynamic scenes). Found resolution with {self.in_dim} dimensions."
+ )
+ has_time_planes = self.in_dim == 4
+
+ self.coo_combs = list(itertools.combinations(range(self.in_dim), 2))
+ # Unlike the Triplane encoding, we use a parameter list instead of batching all planes
+ # together to support uneven resolutions (especially useful for time).
+ # Dynamic models (in_dim == 4) will have 6 planes:
+ # (y, x), (z, x), (t, x), (z, y), (t, y), (t, z)
+ # static models (in_dim == 3) will only have the 1st, 2nd and 4th planes.
+ self.plane_coefs = nn.ParameterList()
+ for coo_comb in self.coo_combs:
+ new_plane_coef = nn.Parameter(
+ torch.empty([self.num_components] + [self.resolution[cc] for cc in coo_comb[::-1]])
+ )
+ if has_time_planes and 3 in coo_comb: # Time planes initialized to 1
+ nn.init.ones_(new_plane_coef)
+ else:
+ nn.init.uniform_(new_plane_coef, a=init_a, b=init_b)
+ self.plane_coefs.append(new_plane_coef)
+
+ def get_out_dim(self) -> int:
+ return self.num_components
+
+ def forward(self, in_tensor: TensorType["bs":..., "input_dim"]) -> TensorType["bs":..., "output_dim"]:
+ """Sample features from this encoder. Expects ``in_tensor`` to be in range [-1, 1]"""
+ original_shape = in_tensor.shape
+
+ output = 1.0 if self.reduce == "product" else 0.0 # identity for corresponding op
+ for ci, coo_comb in enumerate(self.coo_combs):
+ grid = self.plane_coefs[ci].unsqueeze(0) # [1, feature_dim, reso1, reso2]
+ coords = in_tensor[..., coo_comb].view(1, 1, -1, 2) # [1, 1, flattened_bs, 2]
+ interp = F.grid_sample(
+ grid, coords, align_corners=True, padding_mode="border"
+ ) # [1, output_dim, 1, flattened_bs]
+ interp = interp.view(self.num_components, -1).T # [flattened_bs, output_dim]
+ if self.reduce == "product":
+ output = output * interp
+ else:
+ output = output + interp
+
+ return output.reshape(*original_shape[:-1], self.num_components)
+
+
class SHEncoding(Encoding):
"""Spherical harmonic encoding
diff --git a/nerfstudio/field_components/field_heads.py b/nerfstudio/field_components/field_heads.py
index a5d699a31..e9a893994 100644
--- a/nerfstudio/field_components/field_heads.py
+++ b/nerfstudio/field_components/field_heads.py
@@ -60,7 +60,6 @@ class FieldHead(FieldComponent):
in_dim: Optional[int] = None,
activation: Optional[Union[nn.Module, Callable]] = None,
) -> None:
-
super().__init__()
self.out_dim = out_dim
self.activation = activation
@@ -132,7 +131,6 @@ class SHFieldHead(FieldHead):
def __init__(
self, in_dim: Optional[int] = None, levels: int = 3, channels: int = 3, activation: Optional[nn.Module] = None
) -> None:
-
out_dim = channels * levels**2
super().__init__(in_dim=in_dim, out_dim=out_dim, field_head_name=FieldHeadNames.SH, activation=activation)
diff --git a/nerfstudio/field_components/mlp.py b/nerfstudio/field_components/mlp.py
index 545f32564..8cc5a73b6 100644
--- a/nerfstudio/field_components/mlp.py
+++ b/nerfstudio/field_components/mlp.py
@@ -46,7 +46,6 @@ class MLP(FieldComponent):
activation: Optional[nn.Module] = nn.ReLU(),
out_activation: Optional[nn.Module] = None,
) -> None:
-
super().__init__()
self.in_dim = in_dim
assert self.in_dim > 0
diff --git a/nerfstudio/field_components/spatial_distortions.py b/nerfstudio/field_components/spatial_distortions.py
index 02da548a3..da32b4595 100644
--- a/nerfstudio/field_components/spatial_distortions.py
+++ b/nerfstudio/field_components/spatial_distortions.py
@@ -51,7 +51,7 @@ class SceneContraction(SpatialDistortion):
\\end{cases}
If the order is not specified, we use the Frobenius norm, this will contract the space to a sphere of
- radius 1. If the order is L_inf (order=float("inf")), we will contract the space to a cube of side length 2.
+ radius 2. If the order is L_inf (order=float("inf")), we will contract the space to a cube of side length 4.
If using voxel based encodings such as the Hash encoder, we recommend using the L_inf norm.
Args:
diff --git a/nerfstudio/fields/instant_ngp_field.py b/nerfstudio/fields/instant_ngp_field.py
index d1b3e2fa7..e8917423d 100644
--- a/nerfstudio/fields/instant_ngp_field.py
+++ b/nerfstudio/fields/instant_ngp_field.py
@@ -21,7 +21,6 @@ from typing import Dict, Optional, Tuple
import numpy as np
import torch
-from nerfacc import ContractionType, contract
from torch.nn.parameter import Parameter
from torchtyping import TensorType
@@ -30,6 +29,13 @@ from nerfstudio.data.scene_box import SceneBox
from nerfstudio.field_components.activations import trunc_exp
from nerfstudio.field_components.embedding import Embedding
from nerfstudio.field_components.field_heads import FieldHeadNames
+<<<<<<< HEAD
+=======
+from nerfstudio.field_components.spatial_distortions import (
+ SceneContraction,
+ SpatialDistortion,
+)
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
from nerfstudio.fields.base_field import Field, shift_directions_for_tcnn
try:
@@ -69,16 +75,19 @@ class TCNNInstantNGPField(Field):
use_appearance_embedding: Optional[bool] = False,
num_images: Optional[int] = None,
appearance_embedding_dim: int = 32,
- contraction_type: ContractionType = ContractionType.UN_BOUNDED_SPHERE,
num_levels: int = 16,
log2_hashmap_size: int = 19,
max_res: int = 2048,
+<<<<<<< HEAD
+=======
+ spatial_distortion: Optional[SpatialDistortion] = SceneContraction(),
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
) -> None:
super().__init__()
self.aabb = Parameter(aabb, requires_grad=False)
self.geo_feat_dim = geo_feat_dim
- self.contraction_type = contraction_type
+ self.spatial_distortion = spatial_distortion
self.use_appearance_embedding = use_appearance_embedding
if use_appearance_embedding:
@@ -88,7 +97,12 @@ class TCNNInstantNGPField(Field):
# TODO: set this properly based on the aabb
base_res: int = 16
+<<<<<<< HEAD
per_level_scale = np.exp((np.log(max_res) - np.log(base_res)) / (num_levels - 1))
+=======
+ features_per_level: int = 2
+ growth_factor = np.exp((np.log(max_res) - np.log(base_res)) / (num_levels - 1))
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
self.direction_encoding = tcnn.Encoding(
n_input_dims=3,
@@ -104,10 +118,14 @@ class TCNNInstantNGPField(Field):
encoding_config={
"otype": "HashGrid",
"n_levels": num_levels,
- "n_features_per_level": 2,
+ "n_features_per_level": features_per_level,
"log2_hashmap_size": log2_hashmap_size,
"base_resolution": base_res,
+<<<<<<< HEAD
"per_level_scale": per_level_scale,
+=======
+ "per_level_scale": growth_factor,
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
},
network_config={
"otype": "FullyFusedMLP",
@@ -134,9 +152,16 @@ class TCNNInstantNGPField(Field):
)
def get_density(self, ray_samples: RaySamples) -> Tuple[TensorType, TensorType]:
- positions = ray_samples.frustums.get_positions()
+ if self.spatial_distortion is not None:
+ positions = ray_samples.frustums.get_positions()
+ positions = self.spatial_distortion(positions)
+ positions = (positions + 2.0) / 4.0
+ else:
+ positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
+ # Make sure the tcnn gets inputs between 0 and 1.
+ selector = ((positions > 0.0) & (positions < 1.0)).all(dim=-1)
+ positions = positions * selector[..., None]
positions_flat = positions.view(-1, 3)
- positions_flat = contract(x=positions_flat, roi=self.aabb, type=self.contraction_type)
h = self.mlp_base(positions_flat).view(*ray_samples.frustums.shape, -1)
density_before_activation, base_mlp_out = torch.split(h, [1, self.geo_feat_dim], dim=-1)
@@ -145,20 +170,21 @@ class TCNNInstantNGPField(Field):
# softplus, because it enables high post-activation (float32) density outputs
# from smaller internal (float16) parameters.
density = trunc_exp(density_before_activation.to(positions))
+ density = density * selector[..., None]
return density, base_mlp_out
def get_outputs(
self, ray_samples: RaySamples, density_embedding: Optional[TensorType] = None
) -> Dict[FieldHeadNames, TensorType]:
+<<<<<<< HEAD
+=======
+ assert density_embedding is not None
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
directions = shift_directions_for_tcnn(ray_samples.frustums.directions)
directions_flat = directions.view(-1, 3)
-
d = self.direction_encoding(directions_flat)
- if density_embedding is None:
- positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
- h = torch.cat([d, positions.view(-1, 3)], dim=-1)
- else:
- h = torch.cat([d, density_embedding.view(-1, self.geo_feat_dim)], dim=-1)
+
+ h = torch.cat([d, density_embedding.view(-1, self.geo_feat_dim)], dim=-1)
if self.use_appearance_embedding:
if ray_samples.camera_indices is None:
@@ -183,20 +209,5 @@ class TCNNInstantNGPField(Field):
step_size: the step size to use for the opacity evaluation.
"""
density = self.density_fn(positions)
- ## TODO: We should scale step size based on the distortion. Currently it uses too much memory.
- # aabb_min, aabb_max = self.aabb[0], self.aabb[1]
- # if self.contraction_type is not ContractionType.AABB:
- # x = (positions - aabb_min) / (aabb_max - aabb_min)
- # x = x * 2 - 1 # aabb is at [-1, 1]
- # mag = x.norm(dim=-1, keepdim=True)
- # mask = mag.squeeze(-1) > 1
-
- # dev = (2 * mag - 1) / mag**2 + 2 * x**2 * (1 / mag**3 - (2 * mag - 1) / mag**4)
- # dev[~mask] = 1.0
- # dev = torch.clamp(dev, min=1e-6)
- # step_size = step_size / dev.norm(dim=-1, keepdim=True)
- # else:
- # step_size = step_size * (aabb_max - aabb_min)
-
opacity = density * step_size
return opacity
diff --git a/nerfstudio/fields/nerfacto_field.py b/nerfstudio/fields/nerfacto_field.py
index de0fd7c7d..3f3953558 100644
--- a/nerfstudio/fields/nerfacto_field.py
+++ b/nerfstudio/fields/nerfacto_field.py
@@ -103,7 +103,7 @@ class TCNNNerfactoField(Field):
pass_semantic_gradients: bool = False,
use_pred_normals: bool = False,
use_average_appearance_embedding: bool = False,
- spatial_distortion: SpatialDistortion = None,
+ spatial_distortion: Optional[SpatialDistortion] = None,
) -> None:
super().__init__()
@@ -381,8 +381,8 @@ class TorchNerfactoField(Field):
positions = self.spatial_distortion(positions)
else:
positions = ray_samples.frustums.get_positions()
- encoded_xyz = self.position_encoding(positions)
- base_mlp_out = self.mlp_base(encoded_xyz)
+ encoded_xyz = self.position_encoding(positions.view(-1, 3)).to(torch.float32)
+ base_mlp_out = self.mlp_base(encoded_xyz).view(*ray_samples.frustums.shape, -1)
density = self.field_output_density(base_mlp_out)
return density, base_mlp_out
@@ -404,18 +404,20 @@ class TorchNerfactoField(Field):
outputs = {}
for field_head in self.field_heads:
- encoded_dir = self.direction_encoding(ray_samples.frustums.directions)
+ directions = shift_directions_for_tcnn(ray_samples.frustums.directions)
+ directions_flat = directions.view(-1, 3)
+ encoded_dir = self.direction_encoding(directions_flat)
mlp_out = self.mlp_head(
torch.cat(
[
- encoded_dir,
- density_embedding, # type:ignore
+ encoded_dir.view(-1, self.direction_encoding.get_out_dim()),
+ density_embedding.view(-1, self.mlp_base.get_out_dim()), # type:ignore
embedded_appearance.view(-1, self.appearance_embedding_dim),
],
dim=-1, # type:ignore
)
)
- outputs[field_head.field_head_name] = field_head(mlp_out)
+ outputs[field_head.field_head_name] = field_head(mlp_out).view(*outputs_shape, -1).to(directions)
return outputs
diff --git a/nerfstudio/fields/nerfplayer_ngp_field.py b/nerfstudio/fields/nerfplayer_ngp_field.py
index 2952a4369..914a59820 100644
--- a/nerfstudio/fields/nerfplayer_ngp_field.py
+++ b/nerfstudio/fields/nerfplayer_ngp_field.py
@@ -20,7 +20,6 @@ NeRFPlayer (https://arxiv.org/abs/2210.15947) field implementations with Instant
from typing import Dict, Optional, Tuple
import torch
-from nerfacc import ContractionType, contract
from torch.nn.parameter import Parameter
from torchtyping import TensorType
@@ -29,6 +28,10 @@ from nerfstudio.data.scene_box import SceneBox
from nerfstudio.field_components.activations import trunc_exp
from nerfstudio.field_components.embedding import Embedding
from nerfstudio.field_components.field_heads import FieldHeadNames
+from nerfstudio.field_components.spatial_distortions import (
+ SceneContraction,
+ SpatialDistortion,
+)
from nerfstudio.field_components.temporal_grid import TemporalGridEncoder
from nerfstudio.fields.base_field import Field, shift_directions_for_tcnn
@@ -82,13 +85,13 @@ class NerfplayerNGPField(Field):
disable_viewing_dependent: bool = False,
num_images: Optional[int] = None,
appearance_embedding_dim: int = 32,
- contraction_type: ContractionType = ContractionType.UN_BOUNDED_SPHERE,
+ spatial_distortion: Optional[SpatialDistortion] = SceneContraction(),
) -> None:
super().__init__()
self.aabb = Parameter(aabb, requires_grad=False)
self.geo_feat_dim = geo_feat_dim
- self.contraction_type = contraction_type
+ self.spatial_distortion = spatial_distortion
self.use_appearance_embedding = use_appearance_embedding
if use_appearance_embedding:
@@ -144,9 +147,16 @@ class NerfplayerNGPField(Field):
)
def get_density(self, ray_samples: RaySamples) -> Tuple[TensorType, TensorType]:
- positions = ray_samples.frustums.get_positions()
+ if self.spatial_distortion is not None:
+ positions = ray_samples.frustums.get_positions()
+ positions = self.spatial_distortion(positions)
+ positions = (positions + 2.0) / 4.0
+ else:
+ positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
+ # Make sure the tcnn gets inputs between 0 and 1.
+ selector = ((positions > 0.0) & (positions < 1.0)).all(dim=-1)
+ positions = positions * selector[..., None]
positions_flat = positions.view(-1, 3)
- positions_flat = contract(x=positions_flat, roi=self.aabb, type=self.contraction_type)
assert ray_samples.times is not None, "Time should be included in the input for NeRFPlayer"
times_flat = ray_samples.times.view(-1, 1)
@@ -158,28 +168,25 @@ class NerfplayerNGPField(Field):
# softplus, because it enables high post-activation (float32) density outputs
# from smaller internal (float16) parameters.
density = trunc_exp(density_before_activation.to(positions))
+ density = density * selector[..., None]
return density, base_mlp_out
def get_outputs(
self, ray_samples: RaySamples, density_embedding: Optional[TensorType] = None
) -> Dict[FieldHeadNames, TensorType]:
+<<<<<<< HEAD
+=======
+ assert density_embedding is not None
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
directions = shift_directions_for_tcnn(ray_samples.frustums.directions)
directions_flat = directions.view(-1, 3)
if self.direction_encoding is not None:
d = self.direction_encoding(directions_flat)
- if density_embedding is None:
- positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
- h = torch.cat([d, positions.view(-1, 3)], dim=-1)
- else:
- h = torch.cat([d, density_embedding.view(-1, self.geo_feat_dim)], dim=-1)
+ h = torch.cat([d, density_embedding.view(-1, self.geo_feat_dim)], dim=-1)
else:
# viewing direction is disabled
- if density_embedding is None:
- positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
- h = positions.view(-1, 3)
- else:
- h = density_embedding.view(-1, self.geo_feat_dim)
+ h = density_embedding.view(-1, self.geo_feat_dim)
if self.use_appearance_embedding:
if ray_samples.camera_indices is None:
diff --git a/nerfstudio/fields/sdf_field.py b/nerfstudio/fields/sdf_field.py
index e9fd10cb8..2a67ef30e 100644
--- a/nerfstudio/fields/sdf_field.py
+++ b/nerfstudio/fields/sdf_field.py
@@ -18,7 +18,11 @@ a signed distance function (SDF) for surface representation is used to help with
"""
from dataclasses import dataclass, field
+<<<<<<< HEAD
from typing import Dict, Optional, Type
+=======
+from typing import Dict, Literal, Optional, Type
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
import numpy as np
import torch
@@ -26,7 +30,10 @@ import torch.nn.functional as F
from torch import nn
from torch.nn.parameter import Parameter
from torchtyping import TensorType
+<<<<<<< HEAD
from typing_extensions import Literal
+=======
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
from nerfstudio.cameras.rays import RaySamples
from nerfstudio.field_components.embedding import Embedding
@@ -80,6 +87,7 @@ class SDFFieldConfig(FieldConfig):
appearance_embedding_dim: int = 32
"""Dimension of appearance embedding"""
use_appearance_embedding: bool = False
+<<<<<<< HEAD
"""Dimension of appearance embedding"""
bias: float = 0.8
"""sphere size of geometric initializaion"""
@@ -87,6 +95,15 @@ class SDFFieldConfig(FieldConfig):
"""Whether to use geometric initialization"""
inside_outside: bool = True
"""whether to revert signed distance value, set to True for indoor scene"""
+=======
+ """Whether to use appearance embedding"""
+ bias: float = 0.8
+ """Sphere size of geometric initialization"""
+ geometric_init: bool = True
+ """Whether to use geometric initialization"""
+ inside_outside: bool = True
+ """Whether to revert signed distance value, set to True for indoor scene"""
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
weight_norm: bool = True
"""Whether to use weight norm for linear layer"""
use_grid_feature: bool = False
@@ -257,8 +274,13 @@ class SDFField(Field):
"""forward the geonetwork"""
if self.use_grid_feature:
positions = self.spatial_distortion(inputs)
+<<<<<<< HEAD
positions = (positions + 1.0) / 2.0
+=======
+ # map range [-2, 2] to [0, 1]
+ positions = (positions + 2.0) / 4.0
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
feature = self.encoding(positions)
else:
feature = torch.zeros_like(inputs[:, :1].repeat(1, self.encoding.n_output_dims))
diff --git a/nerfstudio/model_components/losses.py b/nerfstudio/model_components/losses.py
index 174c131cc..43fbbd271 100644
--- a/nerfstudio/model_components/losses.py
+++ b/nerfstudio/model_components/losses.py
@@ -16,11 +16,11 @@
Collection of Losses.
"""
from enum import Enum
+from typing import Literal
import torch
from torch import nn
from torchtyping import TensorType
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RaySamples
from nerfstudio.utils.math import masked_reduction, normalized_depth_scale_and_shift
@@ -338,7 +338,7 @@ class MiDaSMSELoss(nn.Module):
def __init__(self, reduction_type: Literal["image", "batch"] = "batch"):
super().__init__()
- self.reduction_type = reduction_type
+ self.reduction_type: Literal["image", "batch"] = reduction_type
# reduction here is different from the image/batch-based reduction. This is either "mean" or "sum"
self.mse_loss = MSELoss(reduction="none")
@@ -485,3 +485,20 @@ class ScaleAndShiftInvariantLoss(nn.Module):
return self.__prediction_ssi
prediction_ssi = property(__get_prediction_ssi)
+
+
+def tv_loss(grids: TensorType["grids", "feature_dim", "row", "column"]) -> TensorType[()]:
+ """
+ https://github.com/apchenstu/TensoRF/blob/4ec894dc1341a2201fe13ae428631b58458f105d/utils.py#L139
+
+ Args:
+ grids: stacks of explicit feature grids (stacked at dim 0)
+ Returns:
+ average total variation loss for neighbor rows and columns.
+ """
+ number_of_grids = grids.shape[0]
+ h_tv_count = grids[:, :, 1:, :].shape[1] * grids[:, :, 1:, :].shape[2] * grids[:, :, 1:, :].shape[3]
+ w_tv_count = grids[:, :, :, 1:].shape[1] * grids[:, :, :, 1:].shape[2] * grids[:, :, :, 1:].shape[3]
+ h_tv = torch.pow((grids[:, :, 1:, :] - grids[:, :, :-1, :]), 2).sum()
+ w_tv = torch.pow((grids[:, :, :, 1:] - grids[:, :, :, :-1]), 2).sum()
+ return 2 * (h_tv / h_tv_count + w_tv / w_tv_count) / number_of_grids
diff --git a/nerfstudio/model_components/ray_samplers.py b/nerfstudio/model_components/ray_samplers.py
index d6cb080c6..39a5c0047 100644
--- a/nerfstudio/model_components/ray_samplers.py
+++ b/nerfstudio/model_components/ray_samplers.py
@@ -19,9 +19,8 @@ Collection of sampling strategies
from abc import abstractmethod
from typing import Callable, List, Optional, Tuple, Union
-import nerfacc
import torch
-from nerfacc import OccupancyGrid
+from nerfacc import OccGridEstimator
from torch import nn
from torchtyping import TensorType
@@ -382,24 +381,21 @@ class VolumetricSampler(Sampler):
def __init__(
self,
- occupancy_grid: Optional[OccupancyGrid] = None,
+ occupancy_grid: OccGridEstimator,
density_fn: Optional[Callable[[TensorType[..., 3]], TensorType[..., 1]]] = None,
- scene_aabb: Optional[TensorType[2, 3]] = None,
) -> None:
-
super().__init__()
- self.scene_aabb = scene_aabb
+ assert occupancy_grid is not None
self.density_fn = density_fn
self.occupancy_grid = occupancy_grid
- if self.scene_aabb is not None:
- self.scene_aabb = self.scene_aabb.to("cuda").flatten()
- def get_sigma_fn(self, origins, directions) -> Optional[Callable]:
+ def get_sigma_fn(self, origins, directions, times=None) -> Optional[Callable]:
"""Returns a function that returns the density of a point.
Args:
origins: Origins of rays
directions: Directions of rays
+ times: Times at which rays are sampled
Returns:
Function that returns the density of a point or None if a density function is not provided.
"""
@@ -412,8 +408,10 @@ class VolumetricSampler(Sampler):
def sigma_fn(t_starts, t_ends, ray_indices):
t_origins = origins[ray_indices]
t_dirs = directions[ray_indices]
- positions = t_origins + t_dirs * (t_starts + t_ends) / 2.0
- return density_fn(positions)
+ positions = t_origins + t_dirs * (t_starts + t_ends)[:, None] / 2.0
+ if times is None:
+ return density_fn(positions).squeeze(-1)
+ return density_fn(positions, times[ray_indices]).squeeze(-1)
return sigma_fn
@@ -429,6 +427,7 @@ class VolumetricSampler(Sampler):
render_step_size: float,
near_plane: float = 0.0,
far_plane: Optional[float] = None,
+ alpha_thre: float = 0.01,
cone_angle: float = 0.0,
) -> Tuple[RaySamples, TensorType["total_samples",]]:
"""Generate ray samples in a bounding box.
@@ -438,6 +437,7 @@ class VolumetricSampler(Sampler):
render_step_size: Minimum step size to use for rendering
near_plane: Near plane for raymarching
far_plane: Far plane for raymarching
+ alpha_thre: Opacity threshold skipping samples.
cone_angle: Cone angle for raymarching, set to 0 for uniform marching.
Returns:
@@ -448,6 +448,7 @@ class VolumetricSampler(Sampler):
rays_o = ray_bundle.origins.contiguous()
rays_d = ray_bundle.directions.contiguous()
+ times = ray_bundle.times
if ray_bundle.nears is not None and ray_bundle.fars is not None:
t_min = ray_bundle.nears.contiguous().reshape(-1)
@@ -457,34 +458,33 @@ class VolumetricSampler(Sampler):
t_min = None
t_max = None
+ if far_plane is None:
+ far_plane = 1e10
+
if ray_bundle.camera_indices is not None:
camera_indices = ray_bundle.camera_indices.contiguous()
else:
camera_indices = None
-
- ray_indices, starts, ends = nerfacc.ray_marching(
+ ray_indices, starts, ends = self.occupancy_grid.sampling(
rays_o=rays_o,
rays_d=rays_d,
t_min=t_min,
t_max=t_max,
- scene_aabb=self.scene_aabb,
- grid=self.occupancy_grid,
- # this is a workaround - using density causes crash and damage quality. should be fixed
- sigma_fn=None, # self.get_sigma_fn(rays_o, rays_d),
+ sigma_fn=self.get_sigma_fn(rays_o, rays_d, times),
render_step_size=render_step_size,
near_plane=near_plane,
far_plane=far_plane,
stratified=self.training,
cone_angle=cone_angle,
- alpha_thre=1e-2,
+ alpha_thre=alpha_thre,
)
num_samples = starts.shape[0]
if num_samples == 0:
# create a single fake sample and update packed_info accordingly
# this says the last ray in packed_info has 1 sample, which starts and ends at 1
ray_indices = torch.zeros((1,), dtype=torch.long, device=rays_o.device)
- starts = torch.ones((1, 1), dtype=starts.dtype, device=rays_o.device)
- ends = torch.ones((1, 1), dtype=ends.dtype, device=rays_o.device)
+ starts = torch.ones((1,), dtype=starts.dtype, device=rays_o.device)
+ ends = torch.ones((1,), dtype=ends.dtype, device=rays_o.device)
origins = rays_o[ray_indices]
dirs = rays_d[ray_indices]
@@ -496,8 +496,8 @@ class VolumetricSampler(Sampler):
frustums=Frustums(
origins=origins,
directions=dirs,
- starts=starts,
- ends=ends,
+ starts=starts[..., None],
+ ends=ends[..., None],
pixel_area=zeros,
),
camera_indices=camera_indices,
@@ -645,6 +645,10 @@ class NeuSSampler(Sampler):
# Start with uniform sampling
if ray_samples is None:
ray_samples = self.uniform_sampler(ray_bundle, num_samples=self.num_samples)
+<<<<<<< HEAD
+=======
+ assert ray_samples is not None
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
total_iters = 0
sorted_index = None
@@ -653,7 +657,10 @@ class NeuSSampler(Sampler):
base_variance = self.base_variance
while total_iters < self.num_upsample_steps:
+<<<<<<< HEAD
+=======
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
with torch.no_grad():
new_sdf = sdf_fn(new_samples)
@@ -701,6 +708,10 @@ class NeuSSampler(Sampler):
"""
batch_size = ray_samples.shape[0]
prev_sdf, next_sdf = sdf[:, :-1], sdf[:, 1:]
+<<<<<<< HEAD
+=======
+ assert ray_samples.deltas is not None
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
deltas = ray_samples.deltas[:, :-1, 0]
mid_sdf = (prev_sdf + next_sdf) * 0.5
cos_val = (next_sdf - prev_sdf) / (deltas + 1e-5)
@@ -742,6 +753,12 @@ class NeuSSampler(Sampler):
ray_samples_2 : ray_samples to merge
"""
+<<<<<<< HEAD
+=======
+ assert ray_samples_1.spacing_starts is not None and ray_samples_2.spacing_starts is not None
+ assert ray_samples_1.spacing_ends is not None and ray_samples_2.spacing_ends is not None
+ assert ray_samples_1.spacing_to_euclidean_fn is not None
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
starts_1 = ray_samples_1.spacing_starts[..., 0]
starts_2 = ray_samples_2.spacing_starts[..., 0]
diff --git a/nerfstudio/model_components/renderers.py b/nerfstudio/model_components/renderers.py
index 5e488bc35..5deafad74 100644
--- a/nerfstudio/model_components/renderers.py
+++ b/nerfstudio/model_components/renderers.py
@@ -28,13 +28,12 @@ Example:
"""
import contextlib
import math
-from typing import Generator, Optional, Union
+from typing import Generator, Literal, Optional, Union
import nerfacc
import torch
from torch import nn
from torchtyping import TensorType
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RaySamples
from nerfstudio.utils import colors
@@ -91,8 +90,12 @@ class RGBRenderer(nn.Module):
# Necessary for packed samples from volumetric ray sampler
if background_color == "last_sample":
raise NotImplementedError("Background color 'last_sample' not implemented for packed samples.")
- comp_rgb = nerfacc.accumulate_along_rays(weights, ray_indices, rgb, num_rays)
- accumulated_weight = nerfacc.accumulate_along_rays(weights, ray_indices, None, num_rays)
+ comp_rgb = nerfacc.accumulate_along_rays(
+ weights[..., 0], values=rgb, ray_indices=ray_indices, n_rays=num_rays
+ )
+ accumulated_weight = nerfacc.accumulate_along_rays(
+ weights[..., 0], values=None, ray_indices=ray_indices, n_rays=num_rays
+ )
else:
comp_rgb = torch.sum(weights * rgb, dim=-2)
accumulated_weight = torch.sum(weights, dim=-2)
@@ -180,7 +183,7 @@ class SHRenderer(nn.Module):
components = components_from_spherical_harmonics(levels=levels, directions=directions)
rgb = sh * components[..., None, :] # [..., num_samples, 3, sh_components]
- rgb = torch.sum(sh, dim=-1) + 0.5 # [..., num_samples, 3]
+ rgb = torch.sum(rgb, dim=-1) # [..., num_samples, 3]
if self.activation is not None:
rgb = self.activation(rgb)
@@ -217,7 +220,9 @@ class AccumulationRenderer(nn.Module):
if ray_indices is not None and num_rays is not None:
# Necessary for packed samples from volumetric ray sampler
- accumulation = nerfacc.accumulate_along_rays(weights, ray_indices, None, num_rays)
+ accumulation = nerfacc.accumulate_along_rays(
+ weights[..., 0], values=None, ray_indices=ray_indices, n_rays=num_rays
+ )
else:
accumulation = torch.sum(weights, dim=-2)
return accumulation
@@ -274,8 +279,12 @@ class DepthRenderer(nn.Module):
if ray_indices is not None and num_rays is not None:
# Necessary for packed samples from volumetric ray sampler
- depth = nerfacc.accumulate_along_rays(weights, ray_indices, steps, num_rays)
- accumulation = nerfacc.accumulate_along_rays(weights, ray_indices, None, num_rays)
+ depth = nerfacc.accumulate_along_rays(
+ weights[..., 0], values=steps, ray_indices=ray_indices, n_rays=num_rays
+ )
+ accumulation = nerfacc.accumulate_along_rays(
+ weights[..., 0], values=None, ray_indices=ray_indices, n_rays=num_rays
+ )
depth = depth / (accumulation + eps)
else:
depth = torch.sum(weights * steps, dim=-2) / (torch.sum(weights, -2) + eps)
diff --git a/nerfstudio/models/base_model.py b/nerfstudio/models/base_model.py
index 58de64f95..5b0ffa522 100644
--- a/nerfstudio/models/base_model.py
+++ b/nerfstudio/models/base_model.py
@@ -103,6 +103,7 @@ class Model(nn.Module):
# NOTE: call `super().populate_modules()` in subclasses
if self.config.enable_collider:
+ assert self.config.collider_params is not None
self.collider = NearFarCollider(
near_plane=self.config.collider_params["near_plane"], far_plane=self.config.collider_params["far_plane"]
)
@@ -178,12 +179,12 @@ class Model(nn.Module):
ray_bundle = camera_ray_bundle.get_row_major_sliced_ray_bundle(start_idx, end_idx)
outputs = self.forward(ray_bundle=ray_bundle)
for output_name, output in outputs.items(): # type: ignore
+ if not torch.is_tensor(output):
+ # TODO: handle lists of tensors as well
+ continue
outputs_lists[output_name].append(output)
outputs = {}
for output_name, outputs_list in outputs_lists.items():
- if not torch.is_tensor(outputs_list[0]):
- # TODO: handle lists of tensors as well
- continue
outputs[output_name] = torch.cat(outputs_list).view(image_height, image_width, -1) # type: ignore
return outputs
diff --git a/nerfstudio/models/base_surface_model.py b/nerfstudio/models/base_surface_model.py
index c83a07032..a6a1d8384 100644
--- a/nerfstudio/models/base_surface_model.py
+++ b/nerfstudio/models/base_surface_model.py
@@ -20,7 +20,11 @@ from __future__ import annotations
from abc import abstractmethod
from dataclasses import dataclass, field
+<<<<<<< HEAD
from typing import Dict, List, Tuple, Type
+=======
+from typing import Dict, List, Literal, Tuple, Type
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
import torch
import torch.nn.functional as F
@@ -28,7 +32,10 @@ from torch.nn import Parameter
from torchmetrics import PeakSignalNoiseRatio
from torchmetrics.functional import structural_similarity_index_measure
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
+<<<<<<< HEAD
from typing_extensions import Literal
+=======
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.field_components.encodings import NeRFEncoding
diff --git a/nerfstudio/models/instant_ngp.py b/nerfstudio/models/instant_ngp.py
index 2bdf85b6a..079ae10e0 100644
--- a/nerfstudio/models/instant_ngp.py
+++ b/nerfstudio/models/instant_ngp.py
@@ -19,16 +19,14 @@ Implementation of Instant NGP.
from __future__ import annotations
from dataclasses import dataclass, field
-from typing import Dict, List, Optional, Tuple, Type
+from typing import Dict, List, Literal, Optional, Tuple, Type
import nerfacc
import torch
-from nerfacc import ContractionType
from torch.nn import Parameter
from torchmetrics import PeakSignalNoiseRatio
from torchmetrics.functional import structural_similarity_index_measure
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.engine.callbacks import (
@@ -37,7 +35,8 @@ from nerfstudio.engine.callbacks import (
TrainingCallbackLocation,
)
from nerfstudio.field_components.field_heads import FieldHeadNames
-from nerfstudio.fields.instant_ngp_field import TCNNInstantNGPField
+from nerfstudio.field_components.spatial_distortions import SceneContraction
+from nerfstudio.fields.nerfacto_field import TCNNNerfactoField
from nerfstudio.model_components.losses import MSELoss
from nerfstudio.model_components.ray_samplers import VolumetricSampler
from nerfstudio.model_components.renderers import (
@@ -61,19 +60,27 @@ class InstantNGPModelConfig(ModelConfig):
"""Whether to create a scene collider to filter rays."""
collider_params: Optional[Dict[str, float]] = None
"""Instant NGP doesn't use a collider."""
- max_num_samples_per_ray: int = 24
- """Number of samples in field evaluation."""
grid_resolution: int = 128
"""Resolution of the grid used for the field."""
+<<<<<<< HEAD
+=======
+ grid_levels: int = 4
+ """Levels of the grid used for the field."""
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
max_res: int = 2048
"""Maximum resolution of the hashmap for the base mlp."""
log2_hashmap_size: int = 19
"""Size of the hashmap for the base mlp"""
+<<<<<<< HEAD
contraction_type: ContractionType = ContractionType.UN_BOUNDED_SPHERE
"""Contraction type used for spatial deformation of the field."""
+=======
+ alpha_thre: float = 0.01
+ """Threshold for opacity skipping."""
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
cone_angle: float = 0.004
"""Should be set to 0.0 for blender scenes but 1./256 for real scenes."""
- render_step_size: float = 0.01
+ render_step_size: Optional[float] = None
"""Minimum step size for rendering."""
near_plane: float = 0.05
"""How far along ray to start sampling."""
@@ -83,6 +90,8 @@ class InstantNGPModelConfig(ModelConfig):
"""Whether to use an appearance embedding."""
background_color: Literal["random", "black", "white"] = "random"
"""The color that is given to untrained areas."""
+ disable_scene_contraction: bool = False
+ """Whether to disable scene contraction or not."""
class NGPModel(Model):
@@ -93,7 +102,7 @@ class NGPModel(Model):
"""
config: InstantNGPModelConfig
- field: TCNNInstantNGPField
+ field: TCNNNerfactoField
def __init__(self, config: InstantNGPModelConfig, **kwargs) -> None:
super().__init__(config=config, **kwargs)
@@ -102,28 +111,36 @@ class NGPModel(Model):
"""Set the fields and modules."""
super().populate_modules()
- self.field = TCNNInstantNGPField(
+ if self.config.disable_scene_contraction:
+ scene_contraction = None
+ else:
+ scene_contraction = SceneContraction(order=float("inf"))
+
+ self.field = TCNNNerfactoField(
aabb=self.scene_box.aabb,
- contraction_type=self.config.contraction_type,
- use_appearance_embedding=self.config.use_appearance_embedding,
num_images=self.num_train_data,
log2_hashmap_size=self.config.log2_hashmap_size,
max_res=self.config.max_res,
+<<<<<<< HEAD
+=======
+ spatial_distortion=scene_contraction,
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
)
self.scene_aabb = Parameter(self.scene_box.aabb.flatten(), requires_grad=False)
- # Occupancy Grid
- self.occupancy_grid = nerfacc.OccupancyGrid(
+ if self.config.render_step_size is None:
+ # auto step size: ~1000 samples in the base level grid
+ self.config.render_step_size = ((self.scene_aabb[3:] - self.scene_aabb[:3]) ** 2).sum().sqrt().item() / 1000
+ # Occupancy Grid.
+ self.occupancy_grid = nerfacc.OccGridEstimator(
roi_aabb=self.scene_aabb,
resolution=self.config.grid_resolution,
- contraction_type=self.config.contraction_type,
+ levels=self.config.grid_levels,
)
# Sampler
- vol_sampler_aabb = self.scene_box.aabb if self.config.contraction_type == ContractionType.AABB else None
self.sampler = VolumetricSampler(
- scene_aabb=vol_sampler_aabb,
occupancy_grid=self.occupancy_grid,
density_fn=self.field.density_fn,
)
@@ -145,11 +162,9 @@ class NGPModel(Model):
self, training_callback_attributes: TrainingCallbackAttributes
) -> List[TrainingCallback]:
def update_occupancy_grid(step: int):
- # TODO: needs to get access to the sampler, on how the step size is determinated at each x. See
- # https://github.com/KAIR-BAIR/nerfacc/blob/127223b11401125a9fce5ce269bb0546ee4de6e8/examples/train_ngp_nerf.py#L190-L213
- self.occupancy_grid.every_n_step(
+ self.occupancy_grid.update_every_n_steps(
step=step,
- occ_eval_fn=lambda x: self.field.get_opacity(x, self.config.render_step_size),
+ occ_eval_fn=lambda x: self.field.density_fn(x) * self.config.render_step_size,
)
return [
@@ -177,6 +192,7 @@ class NGPModel(Model):
near_plane=self.config.near_plane,
far_plane=self.config.far_plane,
render_step_size=self.config.render_step_size,
+ alpha_thre=self.config.alpha_thre,
cone_angle=self.config.cone_angle,
)
@@ -185,11 +201,12 @@ class NGPModel(Model):
# accumulation
packed_info = nerfacc.pack_info(ray_indices, num_rays)
weights = nerfacc.render_weight_from_density(
+ t_starts=ray_samples.frustums.starts[..., 0],
+ t_ends=ray_samples.frustums.ends[..., 0],
+ sigmas=field_outputs[FieldHeadNames.DENSITY][..., 0],
packed_info=packed_info,
- sigmas=field_outputs[FieldHeadNames.DENSITY],
- t_starts=ray_samples.frustums.starts,
- t_ends=ray_samples.frustums.ends,
- )
+ )[0]
+ weights = weights[..., None]
rgb = self.renderer_rgb(
rgb=field_outputs[FieldHeadNames.RGB],
@@ -201,13 +218,11 @@ class NGPModel(Model):
weights=weights, ray_samples=ray_samples, ray_indices=ray_indices, num_rays=num_rays
)
accumulation = self.renderer_accumulation(weights=weights, ray_indices=ray_indices, num_rays=num_rays)
- alive_ray_mask = accumulation.squeeze(-1) > 0
outputs = {
"rgb": rgb,
"accumulation": accumulation,
"depth": depth,
- "alive_ray_mask": alive_ray_mask, # the rays we kept from sampler
"num_samples_per_ray": packed_info[:, 1],
}
return outputs
@@ -221,15 +236,13 @@ class NGPModel(Model):
def get_loss_dict(self, outputs, batch, metrics_dict=None):
image = batch["image"].to(self.device)
- mask = outputs["alive_ray_mask"]
- rgb_loss = self.rgb_loss(image[mask], outputs["rgb"][mask])
+ rgb_loss = self.rgb_loss(image, outputs["rgb"])
loss_dict = {"rgb_loss": rgb_loss}
return loss_dict
def get_image_metrics_and_images(
self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
-
image = batch["image"].to(self.device)
rgb = outputs["rgb"]
acc = colormaps.apply_colormap(outputs["accumulation"])
@@ -237,12 +250,10 @@ class NGPModel(Model):
outputs["depth"],
accumulation=outputs["accumulation"],
)
- alive_ray_mask = colormaps.apply_colormap(outputs["alive_ray_mask"])
combined_rgb = torch.cat([image, rgb], dim=1)
combined_acc = torch.cat([acc], dim=1)
combined_depth = torch.cat([depth], dim=1)
- combined_alive_ray_mask = torch.cat([alive_ray_mask], dim=1)
# Switch images from [H, W, C] to [1, C, H, W] for metrics computations
image = torch.moveaxis(image, -1, 0)[None, ...]
@@ -260,7 +271,6 @@ class NGPModel(Model):
"img": combined_rgb,
"accumulation": combined_acc,
"depth": combined_depth,
- "alive_ray_mask": combined_alive_ray_mask,
}
return metrics_dict, images_dict
diff --git a/nerfstudio/models/mipnerf.py b/nerfstudio/models/mipnerf.py
index 31a337d02..0fae0bdac 100644
--- a/nerfstudio/models/mipnerf.py
+++ b/nerfstudio/models/mipnerf.py
@@ -96,7 +96,6 @@ class MipNerfModel(Model):
return param_groups
def get_outputs(self, ray_bundle: RayBundle):
-
if self.field is None:
raise ValueError("populate_fields() must be called before get_outputs")
diff --git a/nerfstudio/models/nerfacto.py b/nerfstudio/models/nerfacto.py
index 53173640a..0a7583ebe 100644
--- a/nerfstudio/models/nerfacto.py
+++ b/nerfstudio/models/nerfacto.py
@@ -19,7 +19,7 @@ NeRF implementation that combines many recent advancements.
from __future__ import annotations
from dataclasses import dataclass, field
-from typing import Dict, List, Tuple, Type
+from typing import Dict, List, Literal, Tuple, Type
import numpy as np
import torch
@@ -27,7 +27,6 @@ from torch.nn import Parameter
from torchmetrics import PeakSignalNoiseRatio
from torchmetrics.functional import structural_similarity_index_measure
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.engine.callbacks import (
diff --git a/nerfstudio/models/nerfplayer_nerfacto.py b/nerfstudio/models/nerfplayer_nerfacto.py
index e10b3cad2..245d3bac2 100644
--- a/nerfstudio/models/nerfplayer_nerfacto.py
+++ b/nerfstudio/models/nerfplayer_nerfacto.py
@@ -20,14 +20,13 @@ from __future__ import annotations
import functools
from dataclasses import dataclass, field
-from typing import Dict, List, Type
+from typing import Dict, List, Literal, Type
import numpy as np
import torch
from torchmetrics import PeakSignalNoiseRatio
from torchmetrics.functional import structural_similarity_index_measure
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.field_components.field_heads import FieldHeadNames
diff --git a/nerfstudio/models/nerfplayer_ngp.py b/nerfstudio/models/nerfplayer_ngp.py
index 09f68d67f..59390d908 100644
--- a/nerfstudio/models/nerfplayer_ngp.py
+++ b/nerfstudio/models/nerfplayer_ngp.py
@@ -19,19 +19,23 @@ Implementation of NeRFPlayer (https://arxiv.org/abs/2210.15947) with InstantNGP
from __future__ import annotations
from dataclasses import dataclass, field
-from typing import Type
+from typing import List, Literal, Type
import nerfacc
import torch
-from nerfacc import ContractionType
from torch.nn import Parameter
from torchmetrics import PeakSignalNoiseRatio
from torchmetrics.functional import structural_similarity_index_measure
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RayBundle
+from nerfstudio.engine.callbacks import (
+ TrainingCallback,
+ TrainingCallbackAttributes,
+ TrainingCallbackLocation,
+)
from nerfstudio.field_components.field_heads import FieldHeadNames
+from nerfstudio.field_components.spatial_distortions import SceneContraction
from nerfstudio.fields.nerfplayer_ngp_field import NerfplayerNGPField
from nerfstudio.model_components.losses import MSELoss
from nerfstudio.model_components.ray_samplers import VolumetricSampler
@@ -80,6 +84,8 @@ class NerfplayerNGPModelConfig(InstantNGPModelConfig):
"""The training background color that is given to untrained areas."""
disable_viewing_dependent: bool = True
"""Disable viewing dependent effects."""
+ disable_scene_contraction: bool = False
+ """Whether to disable scene contraction or not."""
class NerfplayerNGPModel(NGPModel):
@@ -96,9 +102,13 @@ class NerfplayerNGPModel(NGPModel):
"""Set the fields and modules."""
Model.populate_modules(self)
+ if self.config.disable_scene_contraction:
+ scene_contraction = None
+ else:
+ scene_contraction = SceneContraction(order=float("inf"))
+
self.field = NerfplayerNGPField(
aabb=self.scene_box.aabb,
- contraction_type=self.config.contraction_type,
use_appearance_embedding=self.config.use_appearance_embedding,
num_images=self.num_train_data,
temporal_dim=self.config.temporal_dim,
@@ -107,21 +117,20 @@ class NerfplayerNGPModel(NGPModel):
log2_hashmap_size=self.config.log2_hashmap_size,
base_resolution=self.config.base_resolution,
disable_viewing_dependent=self.config.disable_viewing_dependent,
+ spatial_distortion=scene_contraction,
)
self.scene_aabb = Parameter(self.scene_box.aabb.flatten(), requires_grad=False)
# Occupancy Grid
- self.occupancy_grid = nerfacc.OccupancyGrid(
+ self.occupancy_grid = nerfacc.OccGridEstimator(
roi_aabb=self.scene_aabb,
resolution=self.config.grid_resolution,
- contraction_type=self.config.contraction_type,
+ levels=self.config.grid_levels,
)
# Sampler
- vol_sampler_aabb = self.scene_box.aabb if self.config.contraction_type == ContractionType.AABB else None
self.sampler = VolumetricSampler(
- scene_aabb=vol_sampler_aabb,
occupancy_grid=self.occupancy_grid,
density_fn=self.field.density_fn,
) # need to update the density_fn later during forward (for input time)
@@ -140,11 +149,26 @@ class NerfplayerNGPModel(NGPModel):
self.lpips = LearnedPerceptualImagePatchSimilarity(normalize=True)
self.temporal_distortion = True # for viewer
+ def get_training_callbacks(
+ self, training_callback_attributes: TrainingCallbackAttributes
+ ) -> List[TrainingCallback]:
+ def update_occupancy_grid(step: int):
+ self.occupancy_grid.update_every_n_steps(
+ step=step,
+ occ_eval_fn=lambda x: self.field.get_opacity(x, self.config.render_step_size),
+ )
+
+ return [
+ TrainingCallback(
+ where_to_run=[TrainingCallbackLocation.BEFORE_TRAIN_ITERATION],
+ update_every_num_iters=1,
+ func=update_occupancy_grid,
+ ),
+ ]
+
def get_outputs(self, ray_bundle: RayBundle):
num_rays = len(ray_bundle)
- # update the density_fn of the sampler so that the density is time aware
- self.sampler.density_fn = lambda x: self.field.density_fn(x, ray_bundle.times)
with torch.no_grad():
ray_samples, ray_indices = self.sampler(
ray_bundle=ray_bundle,
@@ -152,6 +176,7 @@ class NerfplayerNGPModel(NGPModel):
far_plane=self.config.far_plane,
render_step_size=self.config.render_step_size,
cone_angle=self.config.cone_angle,
+ alpha_thre=self.config.alpha_thre,
)
field_outputs = self.field(ray_samples)
@@ -160,10 +185,11 @@ class NerfplayerNGPModel(NGPModel):
packed_info = nerfacc.pack_info(ray_indices, num_rays)
weights = nerfacc.render_weight_from_density(
packed_info=packed_info,
- sigmas=field_outputs[FieldHeadNames.DENSITY],
- t_starts=ray_samples.frustums.starts,
- t_ends=ray_samples.frustums.ends,
- )
+ sigmas=field_outputs[FieldHeadNames.DENSITY][..., 0],
+ t_starts=ray_samples.frustums.starts[..., 0],
+ t_ends=ray_samples.frustums.ends[..., 0],
+ )[0]
+ weights = weights[..., None]
# update bgcolor in the renderer; usually random color for training and fixed color for inference
if self.training:
@@ -180,13 +206,11 @@ class NerfplayerNGPModel(NGPModel):
weights=weights, ray_samples=ray_samples, ray_indices=ray_indices, num_rays=num_rays
)
accumulation = self.renderer_accumulation(weights=weights, ray_indices=ray_indices, num_rays=num_rays)
- alive_ray_mask = accumulation.squeeze(-1) > 0
outputs = {
"rgb": rgb,
"accumulation": accumulation,
"depth": depth,
- "alive_ray_mask": alive_ray_mask, # the rays we kept from sampler
"num_samples_per_ray": packed_info[:, 1],
}
# adding them to outputs for calculating losses
@@ -199,10 +223,9 @@ class NerfplayerNGPModel(NGPModel):
def get_loss_dict(self, outputs, batch, metrics_dict=None):
image = batch["image"].to(self.device)
- mask = outputs["alive_ray_mask"]
- rgb_loss = self.rgb_loss(image[mask], outputs["rgb"][mask])
+ rgb_loss = self.rgb_loss(image, outputs["rgb"])
loss_dict = {"rgb_loss": rgb_loss}
- if "depth_image" in batch.keys() and self.config.depth_weight > 0:
+ if "depth_image" in batch.keys() and self.config.depth_weight > 0 and self.training:
mask = batch["depth_image"] != 0
# First we calculate the depth value, just like most of the papers.
loss_dict["depth_loss"] = (outputs["depth"][mask] - batch["depth_image"][mask]).abs().mean()
@@ -228,6 +251,6 @@ class NerfplayerNGPModel(NGPModel):
density_min_mask = (gt_depth_packed - steps > margin) & (gt_depth_packed != 0)
loss_dict["depth_loss"] += (outputs["sigmas"][density_min_mask[..., 0]].pow(2)).mean() * 1e-2
loss_dict["depth_loss"] *= self.config.depth_weight
- if self.config.temporal_tv_weight > 0:
+ if self.config.temporal_tv_weight > 0 and self.training:
loss_dict["temporal_tv_loss"] = self.config.temporal_tv_weight * self.field.mlp_base.get_temporal_tv_loss()
return loss_dict
diff --git a/nerfstudio/models/neus_facto.py b/nerfstudio/models/neus_facto.py
new file mode 100644
index 000000000..554f0d90f
--- /dev/null
+++ b/nerfstudio/models/neus_facto.py
@@ -0,0 +1,222 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Implementation of NeuS similar to nerfacto where proposal sampler is used.
+Based on SDFStudio https://github.com/autonomousvision/sdfstudio/
+"""
+
+from __future__ import annotations
+
+from dataclasses import dataclass, field
+from typing import Any, Dict, List, Optional, Tuple, Type
+
+import numpy as np
+import torch
+from torch.nn import Parameter
+
+from nerfstudio.cameras.rays import RayBundle
+from nerfstudio.engine.callbacks import (
+ TrainingCallback,
+ TrainingCallbackAttributes,
+ TrainingCallbackLocation,
+)
+from nerfstudio.field_components.field_heads import FieldHeadNames
+from nerfstudio.fields.density_fields import HashMLPDensityField
+from nerfstudio.model_components.losses import interlevel_loss
+from nerfstudio.model_components.ray_samplers import (
+ ProposalNetworkSampler,
+ UniformSampler,
+)
+from nerfstudio.models.neus import NeuSModel, NeuSModelConfig
+from nerfstudio.utils import colormaps
+
+
+@dataclass
+class NeuSFactoModelConfig(NeuSModelConfig):
+ """NeusFacto Model Config"""
+
+ _target: Type = field(default_factory=lambda: NeuSFactoModel)
+ num_proposal_samples_per_ray: Tuple[int, int] = (256, 96)
+ """Number of samples per ray for the proposal network."""
+ num_neus_samples_per_ray: int = 48
+ """Number of samples per ray for the nerf network."""
+ proposal_update_every: int = 5
+ """Sample every n steps after the warmup"""
+ proposal_warmup: int = 5000
+ """Scales n from 1 to proposal_update_every over this many steps"""
+ num_proposal_iterations: int = 2
+ """Number of proposal network iterations."""
+ use_same_proposal_network: bool = False
+ """Use the same proposal network. Otherwise use different ones."""
+ proposal_net_args_list: List[Dict] = field(
+ default_factory=lambda: [
+ {"hidden_dim": 16, "log2_hashmap_size": 17, "num_levels": 5, "max_res": 64},
+ {"hidden_dim": 16, "log2_hashmap_size": 17, "num_levels": 5, "max_res": 256},
+ ]
+ )
+ """Arguments for the proposal density fields."""
+ interlevel_loss_mult: float = 1.0
+ """Proposal loss multiplier."""
+ use_proposal_weight_anneal: bool = True
+ """Whether to use proposal weight annealing."""
+ proposal_weights_anneal_slope: float = 10.0
+ """Slope of the annealing function for the proposal weights."""
+ proposal_weights_anneal_max_num_iters: int = 1000
+ """Max num iterations for the annealing function."""
+ use_single_jitter: bool = True
+ """Whether use single jitter or not for the proposal networks."""
+
+
+class NeuSFactoModel(NeuSModel):
+ """NeuSFactoModel extends NeuSModel for a more efficient sampling strategy.
+
+ The model improves the rendering speed and quality by incorporating a learning-based
+ proposal distribution to guide the sampling process.(similar to mipnerf-360)
+
+ Args:
+ config: NeuS configuration to instantiate model
+ """
+
+ config: NeuSFactoModelConfig
+
+ def populate_modules(self):
+ """Instantiate modules and fields, including proposal networks."""
+ super().populate_modules()
+
+ self.density_fns = []
+ num_prop_nets = self.config.num_proposal_iterations
+ # Build the proposal network(s)
+ self.proposal_networks = torch.nn.ModuleList()
+ if self.config.use_same_proposal_network:
+ assert len(self.config.proposal_net_args_list) == 1, "Only one proposal network is allowed."
+ prop_net_args = self.config.proposal_net_args_list[0]
+ network = HashMLPDensityField(
+ self.scene_box.aabb, spatial_distortion=self.scene_contraction, **prop_net_args
+ )
+ self.proposal_networks.append(network)
+ self.density_fns.extend([network.density_fn for _ in range(num_prop_nets)])
+ else:
+ for i in range(num_prop_nets):
+ prop_net_args = self.config.proposal_net_args_list[min(i, len(self.config.proposal_net_args_list) - 1)]
+ network = HashMLPDensityField(
+ self.scene_box.aabb,
+ spatial_distortion=self.scene_contraction,
+ **prop_net_args,
+ )
+ self.proposal_networks.append(network)
+ self.density_fns.extend([network.density_fn for network in self.proposal_networks])
+
+ # update proposal network every iterations
+ update_schedule = lambda step: -1
+
+ initial_sampler = UniformSampler(single_jitter=self.config.use_single_jitter)
+ self.proposal_sampler = ProposalNetworkSampler(
+ num_nerf_samples_per_ray=self.config.num_neus_samples_per_ray,
+ num_proposal_samples_per_ray=self.config.num_proposal_samples_per_ray,
+ num_proposal_network_iterations=self.config.num_proposal_iterations,
+ single_jitter=self.config.use_single_jitter,
+ update_sched=update_schedule,
+ initial_sampler=initial_sampler,
+ )
+
+ def get_param_groups(self) -> Dict[str, List[Parameter]]:
+ """Return a dictionary with the parameters of the proposal networks."""
+ param_groups = super().get_param_groups()
+ param_groups["proposal_networks"] = list(self.proposal_networks.parameters())
+ return param_groups
+
+ def get_training_callbacks(
+ self, training_callback_attributes: TrainingCallbackAttributes
+ ) -> List[TrainingCallback]:
+ callbacks = super().get_training_callbacks(training_callback_attributes)
+
+ if self.config.use_proposal_weight_anneal:
+ # anneal the weights of the proposal network before doing PDF sampling
+ N = self.config.proposal_weights_anneal_max_num_iters
+
+ def set_anneal(step: int):
+ # https://arxiv.org/pdf/2111.12077.pdf eq. 18
+ train_frac = np.clip(step / N, 0, 1)
+ bias = lambda x, b: (b * x) / ((b - 1) * x + 1)
+ anneal = bias(train_frac, self.config.proposal_weights_anneal_slope)
+ self.proposal_sampler.set_anneal(anneal)
+
+ callbacks.append(
+ TrainingCallback(
+ where_to_run=[TrainingCallbackLocation.BEFORE_TRAIN_ITERATION],
+ update_every_num_iters=1,
+ func=set_anneal,
+ )
+ )
+ callbacks.append(
+ TrainingCallback(
+ where_to_run=[TrainingCallbackLocation.AFTER_TRAIN_ITERATION],
+ update_every_num_iters=1,
+ func=self.proposal_sampler.step_cb,
+ )
+ )
+
+ return callbacks
+
+ def sample_and_forward_field(self, ray_bundle: RayBundle) -> Dict[str, Any]:
+ """Sample rays using proposal networks and compute the corresponding field outputs."""
+ ray_samples, weights_list, ray_samples_list = self.proposal_sampler(ray_bundle, density_fns=self.density_fns)
+
+ field_outputs = self.field(ray_samples, return_alphas=True)
+ weights, transmittance = ray_samples.get_weights_and_transmittance_from_alphas(
+ field_outputs[FieldHeadNames.ALPHA]
+ )
+ bg_transmittance = transmittance[:, -1, :]
+
+ weights_list.append(weights)
+ ray_samples_list.append(ray_samples)
+
+ samples_and_field_outputs = {
+ "ray_samples": ray_samples,
+ "field_outputs": field_outputs,
+ "weights": weights,
+ "bg_transmittance": bg_transmittance,
+ "weights_list": weights_list,
+ "ray_samples_list": ray_samples_list,
+ }
+ return samples_and_field_outputs
+
+ def get_loss_dict(
+ self, outputs: Dict[str, Any], batch: Dict[str, Any], metrics_dict: Optional[Dict[str, Any]] = None
+ ) -> Dict[str, Any]:
+ """Compute the loss dictionary, including interlevel loss for proposal networks."""
+ loss_dict = super().get_loss_dict(outputs, batch, metrics_dict)
+
+ if self.training:
+ loss_dict["interlevel_loss"] = self.config.interlevel_loss_mult * interlevel_loss(
+ outputs["weights_list"], outputs["ray_samples_list"]
+ )
+
+ return loss_dict
+
+ def get_image_metrics_and_images(
+ self, outputs: Dict[str, Any], batch: Dict[str, Any]
+ ) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
+ """Compute image metrics and images, including the proposal depth for each iteration."""
+ metrics_dict, images_dict = super().get_image_metrics_and_images(outputs, batch)
+ for i in range(self.config.num_proposal_iterations):
+ key = f"prop_depth_{i}"
+ prop_depth_i = colormaps.apply_depth_colormap(
+ outputs[key],
+ accumulation=outputs["accumulation"],
+ )
+ images_dict[key] = prop_depth_i
+
+ return metrics_dict, images_dict
diff --git a/nerfstudio/models/semantic_nerfw.py b/nerfstudio/models/semantic_nerfw.py
index 4324e1eeb..c36b2d21c 100644
--- a/nerfstudio/models/semantic_nerfw.py
+++ b/nerfstudio/models/semantic_nerfw.py
@@ -258,7 +258,6 @@ class SemanticNerfWModel(Model):
def get_image_metrics_and_images(
self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
-
image = batch["image"].to(self.device)
rgb = outputs["rgb"]
rgb = torch.clamp(rgb, min=0, max=1)
diff --git a/nerfstudio/models/tensorf.py b/nerfstudio/models/tensorf.py
index 3b27354d1..109c117fb 100644
--- a/nerfstudio/models/tensorf.py
+++ b/nerfstudio/models/tensorf.py
@@ -19,7 +19,7 @@ TensorRF implementation.
from __future__ import annotations
from dataclasses import dataclass, field
-from typing import Dict, List, Tuple, Type
+from typing import Dict, List, Literal, Tuple, Type
import numpy as np
import torch
@@ -27,7 +27,6 @@ from torch.nn import Parameter
from torchmetrics import PeakSignalNoiseRatio
from torchmetrics.functional import structural_similarity_index_measure
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
-from typing_extensions import Literal
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.configs.config_utils import to_immutable_dict
@@ -44,7 +43,7 @@ from nerfstudio.field_components.encodings import (
)
from nerfstudio.field_components.field_heads import FieldHeadNames
from nerfstudio.fields.tensorf_field import TensoRFField
-from nerfstudio.model_components.losses import MSELoss
+from nerfstudio.model_components.losses import MSELoss, tv_loss
from nerfstudio.model_components.ray_samplers import PDFSampler, UniformSampler
from nerfstudio.model_components.renderers import (
AccumulationRenderer,
@@ -68,10 +67,19 @@ class TensoRFModelConfig(ModelConfig):
"""final render resolution"""
upsampling_iters: Tuple[int, ...] = (2000, 3000, 4000, 5500, 7000)
"""specifies a list of iteration step numbers to perform upsampling"""
- loss_coefficients: Dict[str, float] = to_immutable_dict({"rgb_loss": 1.0})
+ loss_coefficients: Dict[str, float] = to_immutable_dict(
+ {
+ "rgb_loss": 1.0,
+ "tv_reg_density": 1e-3,
+ "tv_reg_color": 1e-4,
+ "l1_reg": 5e-4,
+ }
+ )
"""Loss specific weights."""
- num_samples: int = 256
+ num_samples: int = 50
"""Number of samples in field evaluation"""
+ num_uniform_samples: int = 200
+ """Number of samples in density evaluation"""
num_den_components: int = 16
"""Number of components in density encoding"""
num_color_components: int = 48
@@ -79,6 +87,8 @@ class TensoRFModelConfig(ModelConfig):
appearance_dim: int = 27
"""Number of channels for color encoding"""
tensorf_encoding: Literal["triplane", "vm", "cp"] = "vm"
+ regularization: Literal["none", "l1", "tv"] = "l1"
+ """Regularization method used in tensorf paper"""
class TensoRFModel(Model):
@@ -88,6 +98,8 @@ class TensoRFModel(Model):
config: TensoRF configuration to instantiate model
"""
+ config: TensoRFModelConfig
+
def __init__(
self,
config: TensoRFModelConfig,
@@ -116,7 +128,6 @@ class TensoRFModel(Model):
def get_training_callbacks(
self, training_callback_attributes: TrainingCallbackAttributes
) -> List[TrainingCallback]:
-
# the callback that we want to run every X iterations after the training iteration
def reinitialize_optimizer(
self, training_callback_attributes: TrainingCallbackAttributes, step: int # pylint: disable=unused-argument
@@ -219,8 +230,8 @@ class TensoRFModel(Model):
)
# samplers
- self.sampler_uniform = UniformSampler(num_samples=self.config.num_samples, single_jitter=True)
- self.sampler_pdf = PDFSampler(num_samples=self.config.num_samples // 2, single_jitter=True)
+ self.sampler_uniform = UniformSampler(num_samples=self.config.num_uniform_samples, single_jitter=True)
+ self.sampler_pdf = PDFSampler(num_samples=self.config.num_samples, single_jitter=True, include_original=False)
# renderers
self.renderer_rgb = RGBRenderer(background_color=colors.WHITE)
@@ -239,6 +250,10 @@ class TensoRFModel(Model):
if self.config.enable_collider:
self.collider = AABBBoxCollider(scene_box=self.scene_box)
+ # regularizations
+ if self.config.tensorf_encoding == "cp" and self.config.regularization == "tv":
+ raise RuntimeError("TV reg not supported for CP decomposition")
+
def get_param_groups(self) -> Dict[str, List[Parameter]]:
param_groups = {}
@@ -293,6 +308,20 @@ class TensoRFModel(Model):
rgb_loss = self.rgb_loss(image, outputs["rgb"])
loss_dict = {"rgb_loss": rgb_loss}
+
+ if self.config.regularization == "l1":
+ l1_parameters = []
+ for parameter in self.field.density_encoding.parameters():
+ l1_parameters.append(parameter.view(-1))
+ loss_dict["l1_reg"] = torch.abs(torch.cat(l1_parameters)).mean()
+ elif self.config.regularization == "tv":
+ loss_dict["tv_reg_density"] = tv_loss(self.field.density_encoding.plane_coef)
+ loss_dict["tv_reg_color"] = tv_loss(self.field.color_encoding.plane_coef)
+ elif self.config.regularization == "none":
+ pass
+ else:
+ raise ValueError(f"Regularization {self.config.regularization} not supported")
+
loss_dict = misc.scale_dict(loss_dict, self.config.loss_coefficients)
return loss_dict
@@ -302,6 +331,7 @@ class TensoRFModel(Model):
image = batch["image"].to(outputs["rgb"].device)
rgb = outputs["rgb"]
acc = colormaps.apply_colormap(outputs["accumulation"])
+ assert self.config.collider_params is not None
depth = colormaps.apply_depth_colormap(
outputs["depth"],
accumulation=outputs["accumulation"],
diff --git a/nerfstudio/models/vanilla_nerf.py b/nerfstudio/models/vanilla_nerf.py
index 53e838891..e9c74e93d 100644
--- a/nerfstudio/models/vanilla_nerf.py
+++ b/nerfstudio/models/vanilla_nerf.py
@@ -135,7 +135,6 @@ class NeRFModel(Model):
return param_groups
def get_outputs(self, ray_bundle: RayBundle):
-
if self.field_coarse is None or self.field_fine is None:
raise ValueError("populate_fields() must be called before get_outputs")
@@ -201,6 +200,7 @@ class NeRFModel(Model):
rgb_fine = outputs["rgb_fine"]
acc_coarse = colormaps.apply_colormap(outputs["accumulation_coarse"])
acc_fine = colormaps.apply_colormap(outputs["accumulation_fine"])
+ assert self.config.collider_params is not None
depth_coarse = colormaps.apply_depth_colormap(
outputs["depth_coarse"],
accumulation=outputs["accumulation_coarse"],
diff --git a/nerfstudio/pipelines/base_pipeline.py b/nerfstudio/pipelines/base_pipeline.py
index 22405f60c..22a45dfd3 100644
--- a/nerfstudio/pipelines/base_pipeline.py
+++ b/nerfstudio/pipelines/base_pipeline.py
@@ -21,7 +21,7 @@ import typing
from abc import abstractmethod
from dataclasses import dataclass, field
from time import time
-from typing import Any, Dict, List, Mapping, Optional, Type, Union, cast
+from typing import Any, Dict, List, Literal, Mapping, Optional, Type, Union, cast
import torch
import torch.distributed as dist
@@ -36,7 +36,6 @@ from torch import nn
from torch.cuda.amp.grad_scaler import GradScaler
from torch.nn import Parameter
from torch.nn.parallel import DistributedDataParallel as DDP
-from typing_extensions import Literal
from nerfstudio.configs import base_config as cfg
from nerfstudio.data.datamanagers.base_datamanager import (
@@ -96,7 +95,11 @@ class Pipeline(nn.Module):
datamanager: DataManager
_model: Model
+<<<<<<< HEAD
generative: bool
+=======
+ world_size: int
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
@property
def model(self):
@@ -109,9 +112,26 @@ class Pipeline(nn.Module):
return self.model.device
def load_state_dict(self, state_dict: Mapping[str, Any], strict: bool = True):
+<<<<<<< HEAD
model_state = {key[len("_model.") :]: value for key, value in state_dict.items() if key.startswith("_model.")}
+=======
+ is_ddp_model_state = True
+ model_state = {}
+ for key, value in state_dict.items():
+ if key.startswith("_model."):
+ # remove the "_model." prefix from key
+ model_state[key[len("_model.") :]] = value
+ # make sure that the "module." prefix comes from DDP,
+ # rather than an attribute of the model named "module"
+ if not key.startswith("_model.module."):
+ is_ddp_model_state = False
+ # remove "module." prefix added by DDP
+ if is_ddp_model_state:
+ model_state = {key[len("module.") :]: value for key, value in model_state.items()}
+
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
pipeline_state = {key: value for key, value in state_dict.items() if not key.startswith("_model.")}
- self._model.load_state_dict(model_state, strict=strict)
+ self.model.load_state_dict(model_state, strict=strict)
super().load_state_dict(pipeline_state, strict=False)
@profiler.time_function
@@ -205,6 +225,7 @@ class VanillaPipelineConfig(cfg.InstantiateConfig):
class VanillaPipeline(Pipeline):
"""The pipeline class for the vanilla nerf setup of multiple cameras for one or a few scenes.
+ Args:
config: configuration to instantiate pipeline
device: location to place model and data
test_mode:
@@ -379,7 +400,11 @@ class VanillaPipeline(Pipeline):
state = {
(key[len("module.") :] if key.startswith("module.") else key): value for key, value in loaded_state.items()
}
+<<<<<<< HEAD
self._model.update_to_step(step)
+=======
+ self.model.update_to_step(step)
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
self.load_state_dict(state, strict=True)
def get_training_callbacks(
diff --git a/nerfstudio/pipelines/dynamic_batch.py b/nerfstudio/pipelines/dynamic_batch.py
index 36536eef2..cddfa7841 100644
--- a/nerfstudio/pipelines/dynamic_batch.py
+++ b/nerfstudio/pipelines/dynamic_batch.py
@@ -17,11 +17,17 @@ A pipeline that dynamically chooses the number of rays to sample.
"""
from dataclasses import dataclass, field
+<<<<<<< HEAD
from typing import Optional, Type
import torch
from torch.cuda.amp.grad_scaler import GradScaler
from typing_extensions import Literal
+=======
+from typing import Literal, Type
+
+import torch
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
from nerfstudio.data.datamanagers.base_datamanager import VanillaDataManager
from nerfstudio.pipelines.base_pipeline import VanillaPipeline, VanillaPipelineConfig
diff --git a/nerfstudio/plugins/registry.py b/nerfstudio/plugins/registry.py
index 9e7a61c8d..15eb1779d 100644
--- a/nerfstudio/plugins/registry.py
+++ b/nerfstudio/plugins/registry.py
@@ -16,6 +16,8 @@
Module that keeps all registered plugins and allows for plugin discovery.
"""
+import importlib
+import os
import sys
import typing as t
@@ -34,6 +36,7 @@ CONSOLE = Console(width=120)
def discover_methods() -> t.Tuple[t.Dict[str, TrainerConfig], t.Dict[str, str]]:
"""
Discovers all methods registered using the `nerfstudio.method_configs` entrypoint.
+ And also methods in the NERFSTUDIO_METHOD_CONFIGS environment variable.
"""
methods = {}
descriptions = {}
@@ -48,4 +51,22 @@ def discover_methods() -> t.Tuple[t.Dict[str, TrainerConfig], t.Dict[str, str]]:
specification = t.cast(MethodSpecification, specification)
methods[specification.config.method_name] = specification.config
descriptions[specification.config.method_name] = specification.description
+
+ if "NERFSTUDIO_METHOD_CONFIGS" in os.environ:
+ try:
+ strings = os.environ["NERFSTUDIO_METHOD_CONFIGS"].split(",")
+ for definition in strings:
+ if not definition:
+ continue
+ name, path = definition.split("=")
+ CONSOLE.print(f"[bold green]Info: Loading method {name} from environment variable")
+ module, config_name = path.split(":")
+ method_config = getattr(importlib.import_module(module), config_name)
+ assert isinstance(method_config, MethodSpecification)
+ methods[name] = method_config.config
+ descriptions[name] = method_config.description
+ except Exception: # pylint: disable=broad-except
+ CONSOLE.print_exception()
+ CONSOLE.print("[bold red]Error: Could not load methods from environment variable NERFSTUDIO_METHOD_CONFIGS")
+
return methods, descriptions
diff --git a/nerfstudio/process_data/base_converter_to_nerfstudio_dataset.py b/nerfstudio/process_data/base_converter_to_nerfstudio_dataset.py
new file mode 100644
index 000000000..a1578cc05
--- /dev/null
+++ b/nerfstudio/process_data/base_converter_to_nerfstudio_dataset.py
@@ -0,0 +1,46 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Base class to process images or video into a nerfstudio dataset
+"""
+
+from abc import ABC, abstractmethod
+from dataclasses import dataclass
+from pathlib import Path
+
+
+@dataclass
+class BaseConverterToNerfstudioDataset(ABC):
+ """Base class to process images or video into a nerfstudio dataset"""
+
+ data: Path
+ """Path the data, either a video file or a directory of images."""
+ output_dir: Path
+ """Path to the output directory."""
+ verbose: bool = False
+ """If True, print extra logging."""
+
+ def __post_init__(self) -> None:
+ self.output_dir.mkdir(parents=True, exist_ok=True)
+ self.image_dir.mkdir(parents=True, exist_ok=True)
+
+ @property
+ def image_dir(self) -> Path: # pylint: disable=missing-function-docstring
+ return self.output_dir / "images"
+
+ @abstractmethod
+ def main(self) -> None:
+ """This method implements the conversion logic for each type of data"""
+ raise NotImplementedError("the main method for conversion needs to be implemented")
diff --git a/nerfstudio/process_data/colmap_converter_to_nerfstudio_dataset.py b/nerfstudio/process_data/colmap_converter_to_nerfstudio_dataset.py
new file mode 100644
index 000000000..93a123d93
--- /dev/null
+++ b/nerfstudio/process_data/colmap_converter_to_nerfstudio_dataset.py
@@ -0,0 +1,231 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Base class to processes a video or image sequence to a nerfstudio compatible dataset."""
+
+from dataclasses import dataclass
+from pathlib import Path
+from typing import Dict, List, Literal, Optional, Tuple
+
+from rich.console import Console
+
+from nerfstudio.process_data import colmap_utils, hloc_utils, process_data_utils
+from nerfstudio.process_data.base_converter_to_nerfstudio_dataset import (
+ BaseConverterToNerfstudioDataset,
+)
+from nerfstudio.process_data.process_data_utils import CAMERA_MODELS
+from nerfstudio.utils import install_checks
+
+CONSOLE = Console(width=120)
+
+
+@dataclass
+class ColmapConverterToNerfstudioDataset(BaseConverterToNerfstudioDataset):
+ """Base class to process images or video into a nerfstudio dataset using colmap"""
+
+ camera_type: Literal["perspective", "fisheye", "equirectangular"] = "perspective"
+ """Camera model to use."""
+ matching_method: Literal["exhaustive", "sequential", "vocab_tree"] = "vocab_tree"
+ """Feature matching method to use. Vocab tree is recommended for a balance of speed
+ and accuracy. Exhaustive is slower but more accurate. Sequential is faster but
+ should only be used for videos."""
+ sfm_tool: Literal["any", "colmap", "hloc"] = "any"
+ """Structure from motion tool to use. Colmap will use sift features, hloc can use
+ many modern methods such as superpoint features and superglue matcher"""
+ refine_pixsfm: bool = False
+ """If True, runs refinement using Pixel Perfect SFM.
+ Only works with hloc sfm_tool"""
+ feature_type: Literal[
+ "any",
+ "sift",
+ "superpoint",
+ "superpoint_aachen",
+ "superpoint_max",
+ "superpoint_inloc",
+ "r2d2",
+ "d2net-ss",
+ "sosnet",
+ "disk",
+ ] = "any"
+ """Type of feature to use."""
+ matcher_type: Literal[
+ "any",
+ "NN",
+ "superglue",
+ "superglue-fast",
+ "NN-superpoint",
+ "NN-ratio",
+ "NN-mutual",
+ "adalam",
+ ] = "any"
+ """Matching algorithm."""
+ num_downscales: int = 3
+ """Number of times to downscale the images. Downscales by 2 each time. For example a value of 3 will downscale the
+ images by 2x, 4x, and 8x."""
+ skip_colmap: bool = False
+ """If True, skips COLMAP and generates transforms.json if possible."""
+ skip_image_processing: bool = False
+ """If True, skips copying and downscaling of images and only runs COLMAP if possible and enabled"""
+ colmap_model_path: Path = Path("colmap/sparse/0")
+ """Optionally sets the path of the colmap model. Used only when --skip-colmap is set to True. The path is relative
+ to the output directory.
+ """
+ colmap_cmd: str = "colmap"
+ """How to call the COLMAP executable."""
+ images_per_equirect: Literal[8, 14] = 8
+ """Number of samples per image to take from each equirectangular image.
+ Used only when camera-type is equirectangular.
+ """
+ crop_factor: Tuple[float, float, float, float] = (0.0, 0.0, 0.0, 0.0)
+ """Portion of the image to crop. All values should be in [0,1]. (top, bottom, left, right)"""
+ crop_bottom: float = 0.0
+ """Portion of the image to crop from the bottom.
+ Can be used instead of `crop-factor 0.0 [num] 0.0 0.0` Should be in [0,1].
+ """
+ gpu: bool = True
+ """If True, use GPU."""
+ use_sfm_depth: bool = False
+ """If True, export and use depth maps induced from SfM points."""
+ include_depth_debug: bool = False
+ """If --use-sfm-depth and this flag is True, also export debug images showing Sf overlaid upon input images."""
+
+ @staticmethod
+ def default_colmap_path() -> Path: # pylint: disable=missing-function-docstring
+ return Path("colmap/sparse/0")
+
+ @property
+ def absolute_colmap_model_path(self) -> Path: # pylint: disable=missing-function-docstring
+ return self.output_dir / self.colmap_model_path
+
+ @property
+ def absolute_colmap_path(self) -> Path: # pylint: disable=missing-function-docstring
+ return self.output_dir / "colmap"
+
+ def _save_transforms(
+ self,
+ num_frames: int,
+ image_id_to_depth_path: Optional[Dict[int, Path]] = None,
+ camera_mask_path: Optional[Path] = None,
+ image_rename_map: Optional[Dict[str, str]] = None,
+ ) -> List[str]:
+ """Save colmap transforms into the output folder
+
+ Args:
+ image_id_to_depth_path: When including sfm-based depth, embed these depth file paths in the exported json
+ image_rename_map: Use these image names instead of the names embedded in the COLMAP db
+ """
+ summary_log = []
+ if (self.absolute_colmap_model_path / "cameras.bin").exists():
+ with CONSOLE.status("[bold yellow]Saving results to transforms.json", spinner="balloon"):
+ num_matched_frames = colmap_utils.colmap_to_json(
+ recon_dir=self.absolute_colmap_model_path,
+ output_dir=self.output_dir,
+ image_id_to_depth_path=image_id_to_depth_path,
+ camera_mask_path=camera_mask_path,
+ image_rename_map=image_rename_map,
+ )
+ summary_log.append(f"Colmap matched {num_matched_frames} images")
+ summary_log.append(colmap_utils.get_matching_summary(num_frames, num_matched_frames))
+
+ else:
+ CONSOLE.log(
+ "[bold yellow]Warning: Could not find existing COLMAP results. " "Not generating transforms.json"
+ )
+ return summary_log
+
+ def _export_depth(self) -> Tuple[Optional[Dict[int, Path]], List[str]]:
+ """If SFM is used for creating depth image, this method will create the depth images from image in
+ `self.image_dir`.
+
+ Returns:
+ Depth file paths indexed by COLMAP image id, logs
+ """
+ summary_log = []
+ if self.use_sfm_depth:
+ depth_dir = self.output_dir / "depth"
+ depth_dir.mkdir(parents=True, exist_ok=True)
+ image_id_to_depth_path = colmap_utils.create_sfm_depth(
+ recon_dir=self.output_dir / self.default_colmap_path(),
+ output_dir=depth_dir,
+ include_depth_debug=self.include_depth_debug,
+ input_images_dir=self.image_dir,
+ verbose=self.verbose,
+ )
+ summary_log.append(
+ process_data_utils.downscale_images(
+ depth_dir,
+ self.num_downscales,
+ folder_name="depths",
+ nearest_neighbor=True,
+ verbose=self.verbose,
+ )
+ )
+ return image_id_to_depth_path, summary_log
+ return None, summary_log
+
+ def _run_colmap(self, mask_path: Optional[Path] = None):
+ """
+ Args:
+ mask_path: Path to the camera mask. Defaults to None.
+ """
+ self.absolute_colmap_path.mkdir(parents=True, exist_ok=True)
+
+ (
+ sfm_tool,
+ feature_type,
+ matcher_type,
+ ) = process_data_utils.find_tool_feature_matcher_combination(
+ self.sfm_tool, self.feature_type, self.matcher_type
+ )
+ # check that sfm_tool is hloc if using refine_pixsfm
+ if self.refine_pixsfm:
+ assert sfm_tool == "hloc", "refine_pixsfm only works with sfm_tool hloc"
+
+ if sfm_tool == "colmap":
+ colmap_utils.run_colmap(
+ image_dir=self.image_dir,
+ colmap_dir=self.absolute_colmap_path,
+ camera_model=CAMERA_MODELS[self.camera_type],
+ camera_mask_path=mask_path,
+ gpu=self.gpu,
+ verbose=self.verbose,
+ matching_method=self.matching_method,
+ colmap_cmd=self.colmap_cmd,
+ )
+ elif sfm_tool == "hloc":
+ if mask_path is not None:
+ raise RuntimeError("Cannot use a mask with hloc. Please remove the cropping options " "and try again.")
+ hloc_utils.run_hloc(
+ image_dir=self.image_dir,
+ colmap_dir=self.absolute_colmap_path,
+ camera_model=CAMERA_MODELS[self.camera_type],
+ verbose=self.verbose,
+ matching_method=self.matching_method,
+ feature_type=feature_type,
+ matcher_type=matcher_type,
+ refine_pixsfm=self.refine_pixsfm,
+ )
+ else:
+ raise RuntimeError("Invalid combination of sfm_tool, feature_type, and matcher_type, " "exiting")
+
+ def __post_init__(self) -> None:
+ super().__post_init__()
+ install_checks.check_ffmpeg_installed()
+ install_checks.check_colmap_installed()
+
+ if self.crop_bottom < 0.0 or self.crop_bottom > 1:
+ raise RuntimeError("crop_bottom must be set between 0 and 1.")
+
+ if self.crop_bottom > 0.0:
+ self.crop_factor = (0.0, self.crop_bottom, 0.0, 0.0)
diff --git a/nerfstudio/process_data/colmap_utils.py b/nerfstudio/process_data/colmap_utils.py
index 859222441..690080771 100644
--- a/nerfstudio/process_data/colmap_utils.py
+++ b/nerfstudio/process_data/colmap_utils.py
@@ -13,12 +13,12 @@
# limitations under the License.
"""
-Tools supporting the execution of COLMAP and preparation of COLMAP-based datasets for nerstudio training.
+Tools supporting the execution of COLMAP and preparation of COLMAP-based datasets for nerfstudio training.
"""
import json
from pathlib import Path
-from typing import Any, Dict, Optional
+from typing import Any, Dict, Literal, Optional
import appdirs
import cv2
@@ -27,7 +27,6 @@ import requests
import torch
from rich.console import Console
from rich.progress import track
-from typing_extensions import Literal
# TODO(1480) use pycolmap instead of colmap_parsing_utils
# import pycolmap
@@ -55,7 +54,7 @@ def get_colmap_version(colmap_cmd: str, default_version=3.8) -> float:
Returns:
The version of COLMAP.
"""
- output = run_command(colmap_cmd, verbose=False)
+ output = run_command(f"{colmap_cmd} -h", verbose=False)
assert output is not None
for line in output.split("\n"):
if line.startswith("COLMAP"):
@@ -115,9 +114,7 @@ def run_colmap(
colmap_version = get_colmap_version(colmap_cmd)
colmap_database_path = colmap_dir / "database.db"
- if colmap_database_path.exists():
- # Can't use missing_ok argument because of Python 3.7 compatibility.
- colmap_database_path.unlink()
+ colmap_database_path.unlink(missing_ok=True)
# Feature extraction
feature_extractor_cmd = [
diff --git a/nerfstudio/process_data/hloc_utils.py b/nerfstudio/process_data/hloc_utils.py
index 0aec2376e..90354c3bc 100644
--- a/nerfstudio/process_data/hloc_utils.py
+++ b/nerfstudio/process_data/hloc_utils.py
@@ -21,9 +21,9 @@ Requires hloc module from : https://github.com/cvg/Hierarchical-Localization
import sys
from pathlib import Path
+from typing import Literal
from rich.console import Console
-from typing_extensions import Literal
from nerfstudio.process_data.process_data_utils import CameraModel
@@ -75,6 +75,11 @@ def run_hloc(
camera_model: Camera model to use.
gpu: If True, use GPU.
verbose: If True, logs the output of the command.
+ matching_method: Method to use for matching images.
+ feature_type: Type of visual features to use.
+ matcher_type: Type of feature matcher to use.
+ num_matched: Number of image pairs for loc.
+ refine_pixsfm: If True, refine the reconstruction using pixel-perfect-sfm.
"""
if not _HAS_HLOC:
CONSOLE.print(
@@ -112,7 +117,17 @@ def run_hloc(
camera_model=camera_model.value
)
if refine_pixsfm:
+<<<<<<< HEAD
sfm = PixSfM({"dense_features": {"max_edge": 1024}})
+=======
+ sfm = PixSfM(
+ conf={
+ "dense_features": {"use_cache": True},
+ "KA": {"dense_features": {"use_cache": True}, "max_kps_per_problem": 1000},
+ "BA": {"strategy": "costmaps"},
+ }
+ )
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
refined, _ = sfm.reconstruction(
sfm_dir,
image_dir,
diff --git a/nerfstudio/process_data/images_to_nerfstudio_dataset.py b/nerfstudio/process_data/images_to_nerfstudio_dataset.py
new file mode 100644
index 000000000..dc6163816
--- /dev/null
+++ b/nerfstudio/process_data/images_to_nerfstudio_dataset.py
@@ -0,0 +1,107 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Processes an image sequence to a nerfstudio compatible dataset."""
+
+from dataclasses import dataclass
+from typing import Optional
+
+from rich.console import Console
+
+from nerfstudio.process_data import equirect_utils, process_data_utils
+from nerfstudio.process_data.colmap_converter_to_nerfstudio_dataset import (
+ ColmapConverterToNerfstudioDataset,
+)
+
+CONSOLE = Console(width=120)
+
+
+@dataclass
+class ImagesToNerfstudioDataset(ColmapConverterToNerfstudioDataset):
+ """Process images into a nerfstudio dataset.
+
+ 1. Scales images to a specified size.
+ 2. Calculates the camera poses for each image using `COLMAP `_.
+ """
+
+ def main(self) -> None: # pylint: disable=R0915
+ """Process images into a nerfstudio dataset."""
+
+ # pylint: disable=too-many-statements
+ require_cameras_exist = False
+ if self.colmap_model_path != ColmapConverterToNerfstudioDataset.default_colmap_path():
+ if not self.skip_colmap:
+ raise RuntimeError("The --colmap-model-path can only be used when --skip-colmap is not set.")
+ if not (self.output_dir / self.colmap_model_path).exists():
+ raise RuntimeError(f"The colmap-model-path {self.output_dir / self.colmap_model_path} does not exist.")
+ require_cameras_exist = True
+
+ image_rename_map: Optional[dict[str, str]] = None
+
+ # Generate planar projections if equirectangular
+ if self.camera_type == "equirectangular":
+ pers_size = equirect_utils.compute_resolution_from_equirect(self.data, self.images_per_equirect)
+ CONSOLE.log(f"Generating {self.images_per_equirect} {pers_size} sized images per equirectangular image")
+ self.data = equirect_utils.generate_planar_projections_from_equirectangular(
+ self.data, pers_size, self.images_per_equirect, crop_factor=self.crop_factor
+ )
+ self.camera_type = "perspective"
+
+ summary_log = []
+
+ # Copy and downscale images
+ if not self.skip_image_processing:
+ # Copy images to output directory
+ image_rename_map_paths = process_data_utils.copy_images(
+ self.data, image_dir=self.image_dir, crop_factor=self.crop_factor, verbose=self.verbose
+ )
+ image_rename_map = dict((a.name, b.name) for a, b in image_rename_map_paths.items())
+ num_frames = len(image_rename_map)
+ summary_log.append(f"Starting with {num_frames} images")
+
+ # Downscale images
+ summary_log.append(
+ process_data_utils.downscale_images(self.image_dir, self.num_downscales, verbose=self.verbose)
+ )
+ else:
+ num_frames = len(process_data_utils.list_images(self.data))
+ if num_frames == 0:
+ raise RuntimeError("No usable images in the data folder.")
+ summary_log.append(f"Starting with {num_frames} images")
+
+ # Run COLMAP
+ if not self.skip_colmap:
+ require_cameras_exist = True
+ self._run_colmap()
+ # Colmap uses renamed images
+ image_rename_map = None
+
+ # Export depth maps
+ image_id_to_depth_path, log_tmp = self._export_depth()
+ summary_log += log_tmp
+
+ if require_cameras_exist and not (self.absolute_colmap_model_path / "cameras.bin").exists():
+ raise RuntimeError(f"Could not find existing COLMAP results ({self.colmap_model_path / 'cameras.bin'}).")
+
+ summary_log += self._save_transforms(
+ num_frames,
+ image_id_to_depth_path,
+ None,
+ image_rename_map,
+ )
+
+ CONSOLE.log("[bold green]:tada: :tada: :tada: All DONE :tada: :tada: :tada:")
+
+ for summary in summary_log:
+ CONSOLE.log(summary)
diff --git a/nerfstudio/process_data/insta360_utils.py b/nerfstudio/process_data/insta360_utils.py
deleted file mode 100644
index 56e554e01..000000000
--- a/nerfstudio/process_data/insta360_utils.py
+++ /dev/null
@@ -1,190 +0,0 @@
-# Copyright 2022 The Nerfstudio Team. All rights reserved.
-#
-# Licensed under the Apache License, Version 2.0 (the "License");
-# you may not use this file except in compliance with the License.
-# You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-"""Helper utils for processing insta360 data."""
-
-import sys
-from pathlib import Path
-from typing import List, Tuple
-
-from rich.console import Console
-
-from nerfstudio.process_data.process_data_utils import get_num_frames_in_video
-from nerfstudio.utils.rich_utils import status
-from nerfstudio.utils.scripts import run_command
-
-CONSOLE = Console(width=120)
-
-
-def get_insta360_filenames(data: Path) -> Tuple[Path, Path]:
- """Returns the filenames of the Insta360 videos from a single video file.
-
- Example input name: VID_20220212_070353_00_003.insv
-
- Args:
- data: Path to a Insta360 file.
-
- Returns:
- The filenames of the Insta360 videios.
- """
- if data.suffix != ".insv":
- raise ValueError("The input file must be an .insv file.")
- file_parts = data.stem.split("_")
-
- stem_back = f"VID_{file_parts[1]}_{file_parts[2]}_00_{file_parts[4]}.insv"
- stem_front = f"VID_{file_parts[1]}_{file_parts[2]}_10_{file_parts[4]}.insv"
-
- filename_back = data.parent / stem_back
- filename_front = data.parent / stem_front
-
- return filename_back, filename_front
-
-
-def convert_insta360_to_images(
- video_front: Path,
- video_back: Path,
- image_dir: Path,
- num_frames_target: int,
- crop_percentage: float = 0.7,
- verbose: bool = False,
-) -> Tuple[List[str], int]:
- """Converts a video into a sequence of images.
-
- Args:
- video_front: Path to the front video.
- video_back: Path to the back video.
- output_dir: Path to the output directory.
- num_frames_target: Number of frames to extract.
- crop_percentage: Percentage used to calculate the cropped dimensions of extracted frames. Currently used to crop
- out the curved portions of the fish-eye lens.
- verbose: If True, logs the output of the command.
- Returns:
- A tuple containing summary of the conversion and the number of extracted frames.
- """
-
- with status(msg="Converting video to images...", spinner="bouncingBall", verbose=verbose):
- # delete existing images in folder
- for img in image_dir.glob("*.png"):
- if verbose:
- CONSOLE.log(f"Deleting {img}")
- img.unlink()
-
- num_frames_front = get_num_frames_in_video(video_front)
- num_frames_back = get_num_frames_in_video(video_back)
- if num_frames_front == 0:
- CONSOLE.print(f"[bold red]Error: Video has no frames: {video_front}")
- sys.exit(1)
- if num_frames_back == 0:
- CONSOLE.print(f"[bold red]Error: Video has no frames: {video_front}")
- sys.exit(1)
-
- spacing = num_frames_front // (num_frames_target // 2)
- vf_cmds = []
- if spacing > 1:
- vf_cmds = [f"thumbnail={spacing}", "setpts=N/TB"]
- else:
- CONSOLE.print("[bold red]Can't satisfy requested number of frames. Extracting all frames.")
-
- vf_cmds.append(f"crop=iw*{crop_percentage}:ih*{crop_percentage}")
-
- front_vf_cmds = vf_cmds + ["transpose=2"]
- back_vf_cmds = vf_cmds + ["transpose=1"]
-
- front_ffmpeg_cmd = f"ffmpeg -i {video_front} -vf {','.join(front_vf_cmds)} -r 1 {image_dir / 'frame_%05d.png'}"
- back_ffmpeg_cmd = (
- f"ffmpeg -i {video_back} -vf {','.join(back_vf_cmds)} -r 1 {image_dir / 'back_frame_%05d.png'}"
- )
-
- run_command(front_ffmpeg_cmd, verbose=verbose)
- run_command(back_ffmpeg_cmd, verbose=verbose)
-
- num_extracted_front_frames = len(list(image_dir.glob("frame*.png")))
- for i, img in enumerate(image_dir.glob("back_frame_*.png")):
- img.rename(image_dir / f"frame_{i+1+num_extracted_front_frames:05d}.png")
-
- num_final_frames = len(list(image_dir.glob("*.png")))
- summary_log = []
- summary_log.append(f"Starting with {num_frames_front + num_frames_back} video frames")
- summary_log.append(f"We extracted {num_final_frames} images")
- CONSOLE.log("[bold green]:tada: Done converting insta360 to images.")
-
- return summary_log, num_final_frames
-
-
-def convert_insta360_single_file_to_images(
- video: Path,
- image_dir: Path,
- num_frames_target: int,
- crop_percentage: float = 0.7,
- verbose: bool = False,
-) -> Tuple[List[str], int]:
- """Converts a video into a sequence of images.
-
- Args:
- video: Path to the video.
- output_dir: Path to the output directory.
- num_frames_target: Number of frames to extract.
- crop_percentage: Percentage used to calculate the cropped dimensions of extracted frames. Currently used to crop
- out the curved portions of the fish-eye lens.
- verbose: If True, logs the output of the command.
- Returns:
- A tuple containing summary of the conversion and the number of extracted frames.
- """
-
- with status(msg="Converting video to images...", spinner="bouncingBall", verbose=verbose):
- # delete existing images in folder
- for img in image_dir.glob("*.png"):
- if verbose:
- CONSOLE.log(f"Deleting {img}")
- img.unlink()
-
- num_frames = get_num_frames_in_video(video)
- if num_frames == 0:
- CONSOLE.print(f"[bold red]Error: Video has no frames: {video}")
- sys.exit(1)
-
- spacing = num_frames // (num_frames_target // 2)
- vf_cmds = []
- if spacing > 1:
- vf_cmds = [f"thumbnail={spacing}", "setpts=N/TB"]
- else:
- CONSOLE.print("[bold red]Can't satisfy requested number of frames. Extracting all frames.")
-
- vf_cmds_back = vf_cmds.copy()
- vf_cmds_front = vf_cmds.copy()
-
- vf_cmds_back.append(
- f"crop=ih*{crop_percentage}:ih*{crop_percentage}:ih*{crop_percentage}/4:ih*{crop_percentage}/4"
- )
- vf_cmds_front.append(
- f"crop=ih*{crop_percentage}:ih*{crop_percentage}:iw/2+ih*{crop_percentage/4}:ih*{crop_percentage/4}"
- )
-
- front_ffmpeg_cmd = f"ffmpeg -i {video} -vf {','.join(vf_cmds_front)} -r 1 {image_dir / 'frame_%05d.png'}"
- back_ffmpeg_cmd = f"ffmpeg -i {video} -vf {','.join(vf_cmds_back)} -r 1 {image_dir / 'back_frame_%05d.png'}"
-
- run_command(back_ffmpeg_cmd, verbose=verbose)
- run_command(front_ffmpeg_cmd, verbose=verbose)
-
- num_extracted_frames = len(list(image_dir.glob("frame*.png")))
- for i, img in enumerate(image_dir.glob("back_frame_*.png")):
- img.rename(image_dir / f"frame_{i+1+num_extracted_frames:05d}.png")
-
- num_final_frames = len(list(image_dir.glob("*.png")))
- summary_log = []
- summary_log.append(f"Starting with {num_frames} video frames")
- summary_log.append(f"We extracted {num_final_frames} images")
- CONSOLE.log("[bold green]:tada: Done converting insta360 to images.")
-
- return summary_log, num_final_frames
diff --git a/nerfstudio/process_data/metashape_utils.py b/nerfstudio/process_data/metashape_utils.py
index 17d7771e8..4e0b1a680 100644
--- a/nerfstudio/process_data/metashape_utils.py
+++ b/nerfstudio/process_data/metashape_utils.py
@@ -27,7 +27,7 @@ from nerfstudio.process_data.process_data_utils import CAMERA_MODELS
CONSOLE = Console(width=120)
-def _find_distortion_param(calib_xml: ET.Element, param_name: str):
+def _find_param(calib_xml: ET.Element, param_name: str):
param = calib_xml.find(param_name)
if param is not None:
return float(param.text) # type: ignore
@@ -61,35 +61,84 @@ def metashape_to_json( # pylint: disable=too-many-statements
if sensors is None:
raise ValueError("No sensors found")
- calibrated_sensors = [sensor for sensor in sensors if sensor.find("calibration")]
- if len(calibrated_sensors) != 1:
- raise ValueError("Only one sensor is supported for now")
-
- sensor = calibrated_sensors[0]
-
+ calibrated_sensors = [
+ sensor for sensor in sensors if sensor.get("type") == "spherical" or sensor.find("calibration")
+ ]
+ if not calibrated_sensors:
+ raise ValueError("No calibrated sensor found in Metashape XML")
+ sensor_type = [s.get("type") for s in calibrated_sensors]
+ if sensor_type.count(sensor_type[0]) != len(sensor_type):
+ raise ValueError(
+ "All Metashape sensors do not have the same sensor type. "
+ "nerfstudio does not support per-frame camera_model."
+ )
data = {}
+ if sensor_type[0] == "frame":
+ data["camera_model"] = CAMERA_MODELS["perspective"].value
+ elif sensor_type[0] == "fisheye":
+ data["camera_model"] = CAMERA_MODELS["fisheye"].value
+ elif sensor_type[0] == "spherical":
+ data["camera_model"] = CAMERA_MODELS["equirectangular"].value
+ else:
+ # Cylindrical and RPC sensor types are not supported
+ raise ValueError(f"Unsupported Metashape sensor type '{sensor_type[0]}'")
- assert sensor is not None, "Sensor not found in Metashape XML"
- resolution = sensor.find("resolution")
- assert resolution is not None, "Resolution not found in Metashape xml"
- data["w"] = int(resolution.get("width")) # type: ignore
- data["h"] = int(resolution.get("height")) # type: ignore
+ sensor_dict = {}
+ for sensor in calibrated_sensors:
+ s = {}
+ resolution = sensor.find("resolution")
+ assert resolution is not None, "Resolution not found in Metashape xml"
+ s["w"] = int(resolution.get("width")) # type: ignore
+ s["h"] = int(resolution.get("height")) # type: ignore
- calib = sensor.find("calibration")
- assert calib is not None, "Calibration not found in Metashape xml"
- data["fl_x"] = float(calib.find("f").text) # type: ignore
- data["fl_y"] = float(calib.find("f").text) # type: ignore
- data["cx"] = float(calib.find("cx").text) + data["w"] / 2.0 # type: ignore
- data["cy"] = float(calib.find("cy").text) + data["h"] / 2.0 # type: ignore
+ calib = sensor.find("calibration")
+ if calib is None:
+ assert sensor_type[0] == "spherical", "Only spherical sensors should have no intrinsics"
+ s["fl_x"] = s["w"] / 2.0
+ s["fl_y"] = s["h"]
+ s["cx"] = s["w"] / 2.0
+ s["cy"] = s["h"] / 2.0
+ else:
+ f = calib.find("f")
+ assert f is not None, "Focal length not found in Metashape xml"
+ s["fl_x"] = s["fl_y"] = float(f.text) # type: ignore
+ s["cx"] = _find_param(calib, "cx") + s["w"] / 2.0 # type: ignore
+ s["cy"] = _find_param(calib, "cy") + s["h"] / 2.0 # type: ignore
- data["k1"] = _find_distortion_param(calib, "k1")
- data["k2"] = _find_distortion_param(calib, "k2")
- data["k3"] = _find_distortion_param(calib, "k3")
- data["k4"] = _find_distortion_param(calib, "k4")
- data["p1"] = _find_distortion_param(calib, "p1")
- data["p2"] = _find_distortion_param(calib, "p2")
+ s["k1"] = _find_param(calib, "k1")
+ s["k2"] = _find_param(calib, "k2")
+ s["k3"] = _find_param(calib, "k3")
+ s["k4"] = _find_param(calib, "k4")
+ s["p1"] = _find_param(calib, "p1")
+ s["p2"] = _find_param(calib, "p2")
- data["camera_model"] = CAMERA_MODELS["perspective"].value
+ sensor_dict[sensor.get("id")] = s
+
+ components = chunk.find("components")
+ component_dict = {}
+ for component in components:
+ transform = component.find("transform")
+ if transform is not None:
+ rotation = transform.find("rotation")
+ if rotation is None:
+ r = np.eye(3)
+ else:
+ r = np.array([float(x) for x in rotation.text.split()]).reshape((3, 3))
+ translation = transform.find("translation")
+ if translation is None:
+ t = np.zeros(3)
+ else:
+ t = np.array([float(x) for x in translation.text.split()])
+ scale = transform.find("scale")
+ if scale is None:
+ s = 1.0
+ else:
+ s = float(scale.text)
+
+ m = np.eye(4)
+ m[:3, :3] = r
+ m[:3, 3] = t / s
+ component_dict[component.get("id")] = m
frames = []
cameras = chunk.find("cameras")
@@ -97,33 +146,36 @@ def metashape_to_json( # pylint: disable=too-many-statements
num_skipped = 0
for camera in cameras:
frame = {}
- # Labels sometimes have a file extension. We remove it for consistency.
- camera_label = camera.get("label").split(".")[0] # type: ignore
+ camera_label = camera.get("label")
if camera_label not in image_filename_map:
- continue
+ # Labels sometimes have a file extension. Try without the extension.
+ # (maybe it's just a '.' in the image name)
+ camera_label = camera_label.split(".")[0] # type: ignore
+ if camera_label not in image_filename_map:
+ continue
frame["file_path"] = image_filename_map[camera_label].as_posix()
- if camera.get("sensor_id") != sensor.get("id"):
+ sensor_id = camera.get("sensor_id")
+ if sensor_id not in sensor_dict:
# this should only happen when we have a sensor that doesn't have calibration
if verbose:
CONSOLE.print(f"Missing sensor calibration for {camera.get('label')}, Skipping")
num_skipped += 1
continue
+ # Add all sensor parameters to this frame.
+ frame.update(sensor_dict[sensor_id])
if camera.find("transform") is None:
if verbose:
CONSOLE.print(f"Missing transforms data for {camera.get('label')}, Skipping")
num_skipped += 1
continue
- t = [float(x) for x in camera.find("transform").text.split()] # type: ignore
- transform = np.array(
- [
- [t[8], -t[9], -t[10], t[11]],
- [t[0], -t[1], -t[2], t[3]],
- [t[4], -t[5], -t[6], t[7]],
- [t[12], -t[13], -t[14], t[15]],
- ]
- )
+ transform = np.array([float(x) for x in camera.find("transform").text.split()]).reshape((4, 4))
+ component_id = camera.get("component_id")
+ if component_id in component_dict:
+ transform = component_dict[component_id] @ transform
+ transform = transform[[2, 0, 1, 3], :]
+ transform[:, 1:3] *= -1
frame["transform_matrix"] = transform.tolist()
frames.append(frame)
diff --git a/nerfstudio/process_data/process_data_utils.py b/nerfstudio/process_data/process_data_utils.py
index a73127fcb..b47562ca5 100644
--- a/nerfstudio/process_data/process_data_utils.py
+++ b/nerfstudio/process_data/process_data_utils.py
@@ -14,17 +14,17 @@
"""Helper utils for processing data into the nerfstudio format."""
+import math
import os
import shutil
import sys
from enum import Enum
from pathlib import Path
-from typing import List, Optional, Tuple
+from typing import List, Literal, Optional, OrderedDict, Tuple
import cv2
import numpy as np
from rich.console import Console
-from typing_extensions import Literal, OrderedDict
from nerfstudio.utils.rich_utils import status
from nerfstudio.utils.scripts import run_command
@@ -38,12 +38,13 @@ class CameraModel(Enum):
OPENCV = "OPENCV"
OPENCV_FISHEYE = "OPENCV_FISHEYE"
+ EQUIRECTANGULAR = "EQUIRECTANGULAR"
CAMERA_MODELS = {
"perspective": CameraModel.OPENCV,
"fisheye": CameraModel.OPENCV_FISHEYE,
- "equirectangular": CameraModel.OPENCV,
+ "equirectangular": CameraModel.EQUIRECTANGULAR,
}
@@ -141,7 +142,7 @@ def convert_video_to_images(
if num_frames == 0:
CONSOLE.print(f"[bold red]Error: Video has no frames: {video_path}")
sys.exit(1)
- print("Number of frames in video:", num_frames)
+ CONSOLE.print("Number of frames in video:", num_frames)
out_filename = image_dir / "frame_%05d.png"
ffmpeg_cmd = f'ffmpeg -i "{video_path}"'
@@ -157,9 +158,18 @@ def convert_video_to_images(
spacing = num_frames // num_frames_target
if spacing > 1:
ffmpeg_cmd += f" -vf thumbnail={spacing},setpts=N/TB{crop_cmd} -r 1"
+<<<<<<< HEAD
else:
CONSOLE.print("[bold red]Can't satisfy requested number of frames. Extracting all frames.")
ffmpeg_cmd += f" -pix_fmt bgr8 -vf {crop_cmd[1:]}"
+=======
+ CONSOLE.print("Number of frames to extract:", math.ceil(num_frames / spacing))
+ else:
+ CONSOLE.print("[bold red]Can't satisfy requested number of frames. Extracting all frames.")
+ ffmpeg_cmd += " -pix_fmt bgr8"
+ if crop_cmd != "":
+ ffmpeg_cmd += f" -vf {crop_cmd[1:]}"
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
ffmpeg_cmd += f" {out_filename}"
run_command(ffmpeg_cmd, verbose=verbose)
diff --git a/nerfstudio/process_data/realitycapture_utils.py b/nerfstudio/process_data/realitycapture_utils.py
index 7bc73e132..918aa84a5 100644
--- a/nerfstudio/process_data/realitycapture_utils.py
+++ b/nerfstudio/process_data/realitycapture_utils.py
@@ -12,7 +12,7 @@
# See the License for the specific language governing permissions and
# limitations under the License.
-"""Helper utils for processing polycam data into the nerfstudio format."""
+"""Helper utils for processing reality capture data into the nerfstudio format."""
import csv
import json
@@ -59,27 +59,21 @@ def realitycapture_to_json(
for column, value in row.items():
cameras.setdefault(column, []).append(value)
- for name in cameras["#name"]:
- camera_label = name.split(".")[0]
- if camera_label in image_filename_map:
- img = np.array(Image.open(output_dir / image_filename_map[camera_label]))
- break
-
- height, width, _ = img.shape
-
- data["h"] = int(height)
- data["w"] = int(width)
-
missing_image_data = 0
for i, name in enumerate(cameras["#name"]):
- basename = name.split(".")[0]
+ basename = name.rpartition(".")[0]
if basename not in image_filename_map:
if verbose:
CONSOLE.print(f"Missing image for camera data {basename}, Skipping")
missing_image_data += 1
continue
+
frame = {}
+ img = np.array(Image.open(output_dir / image_filename_map[basename]))
+ height, width, _ = img.shape
+ frame["h"] = int(height)
+ frame["w"] = int(width)
frame["file_path"] = image_filename_map[basename].as_posix()
frame["fl_x"] = float(cameras["f"][i]) * max(width, height) / 36
frame["fl_y"] = float(cameras["f"][i]) * max(width, height) / 36
diff --git a/nerfstudio/process_data/video_to_nerfstudio_dataset.py b/nerfstudio/process_data/video_to_nerfstudio_dataset.py
new file mode 100644
index 000000000..f8054ff42
--- /dev/null
+++ b/nerfstudio/process_data/video_to_nerfstudio_dataset.py
@@ -0,0 +1,124 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Processes a video to a nerfstudio compatible dataset."""
+
+import shutil
+from dataclasses import dataclass
+
+from rich.console import Console
+
+from nerfstudio.process_data import equirect_utils, process_data_utils
+from nerfstudio.process_data.colmap_converter_to_nerfstudio_dataset import (
+ ColmapConverterToNerfstudioDataset,
+)
+
+CONSOLE = Console(width=120)
+
+
+@dataclass
+class VideoToNerfstudioDataset(ColmapConverterToNerfstudioDataset):
+ """Process videos into a nerfstudio dataset.
+
+ This script does the following:
+
+ 1. Converts the video into images.
+ 2. Scales images to a specified size.
+ 3. Calculates the camera poses for each image using `COLMAP `_.
+ """
+
+ num_frames_target: int = 300
+ """Target number of frames to use for the dataset, results may not be exact."""
+ percent_radius_crop: float = 1.0
+ """Create circle crop mask. The radius is the percent of the image diagonal."""
+
+ def main(self) -> None: # pylint: disable=R0915
+ """Process video into a nerfstudio dataset."""
+
+ summary_log = []
+ # Convert video to images
+ if self.camera_type == "equirectangular":
+ # create temp images folder to store the equirect and perspective images
+ temp_image_dir = self.output_dir / "temp_images"
+ temp_image_dir.mkdir(parents=True, exist_ok=True)
+ summary_log, num_extracted_frames = process_data_utils.convert_video_to_images(
+ self.data,
+ image_dir=temp_image_dir,
+ num_frames_target=self.num_frames_target,
+ crop_factor=(0.0, 0.0, 0.0, 0.0),
+ verbose=self.verbose,
+ )
+ else:
+ summary_log, num_extracted_frames = process_data_utils.convert_video_to_images(
+ self.data,
+ image_dir=self.image_dir,
+ num_frames_target=self.num_frames_target,
+ crop_factor=self.crop_factor,
+ verbose=self.verbose,
+ )
+
+ # Generate planar projections if equirectangular
+ if self.camera_type == "equirectangular":
+ perspective_image_size = equirect_utils.compute_resolution_from_equirect(
+ self.output_dir / "temp_images", self.images_per_equirect
+ )
+
+ equirect_utils.generate_planar_projections_from_equirectangular(
+ self.output_dir / "temp_images",
+ perspective_image_size,
+ self.images_per_equirect,
+ crop_factor=self.crop_factor,
+ )
+
+ # copy the perspective images to the image directory
+ process_data_utils.copy_images(
+ self.output_dir / "temp_images" / "planar_projections",
+ image_dir=self.output_dir / "images",
+ verbose=False,
+ )
+
+ # remove the temp_images folder
+ shutil.rmtree(self.output_dir / "temp_images", ignore_errors=True)
+
+ self.camera_type = "perspective"
+
+ # # Create mask
+ mask_path = process_data_utils.save_mask(
+ image_dir=self.image_dir,
+ num_downscales=self.num_downscales,
+ crop_factor=(0.0, 0.0, 0.0, 0.0),
+ percent_radius=self.percent_radius_crop,
+ )
+ if mask_path is not None:
+ summary_log.append(f"Saved mask to {mask_path}")
+
+ # # Downscale images
+ summary_log.append(
+ process_data_utils.downscale_images(self.image_dir, self.num_downscales, verbose=self.verbose)
+ )
+
+ # Run Colmap
+ if not self.skip_colmap:
+ self._run_colmap(mask_path)
+
+ # Export depth maps
+ image_id_to_depth_path, log_tmp = self._export_depth()
+ summary_log += log_tmp
+
+ summary_log += self._save_transforms(num_extracted_frames, image_id_to_depth_path, mask_path)
+
+ CONSOLE.log("[bold green]:tada: :tada: :tada: All DONE :tada: :tada: :tada:")
+
+ for summary in summary_log:
+ CONSOLE.log(summary)
diff --git a/nerfstudio/scripts/__init__.py b/nerfstudio/scripts/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/scripts/benchmarking/launch_eval_blender.sh b/nerfstudio/scripts/benchmarking/launch_eval_blender.sh
similarity index 100%
rename from scripts/benchmarking/launch_eval_blender.sh
rename to nerfstudio/scripts/benchmarking/launch_eval_blender.sh
diff --git a/scripts/benchmarking/launch_train_blender.sh b/nerfstudio/scripts/benchmarking/launch_train_blender.sh
similarity index 100%
rename from scripts/benchmarking/launch_train_blender.sh
rename to nerfstudio/scripts/benchmarking/launch_train_blender.sh
diff --git a/nerfstudio/scripts/blender/__init__.py b/nerfstudio/scripts/blender/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/blender/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/scripts/blender/nerfstudio_blender.py b/nerfstudio/scripts/blender/nerfstudio_blender.py
similarity index 94%
rename from scripts/blender/nerfstudio_blender.py
rename to nerfstudio/scripts/blender/nerfstudio_blender.py
index dee0b4ab3..6a416e369 100644
--- a/scripts/blender/nerfstudio_blender.py
+++ b/nerfstudio/scripts/blender/nerfstudio_blender.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
"""
nerfstudio_blender.py
"""
@@ -141,7 +155,6 @@ class CreateJSONCameraPath(bpy.types.Operator):
keyframe_list = []
for i, transformed_camera_path_mat_val in enumerate(self.transformed_camera_path_mat):
-
curr_properties = (
'[["FOV",'
+ str(self.fov_list[i])
@@ -361,7 +374,7 @@ class NerfstudioBgPanel(bpy.types.Panel): # pylint: disable=too-few-public-meth
self.layout.label(text="Camera path for Nerfstudio")
col = self.layout.column()
- for (prop_name, _) in INPUT_PROPERTIES:
+ for prop_name, _ in INPUT_PROPERTIES:
row = col.row()
row.prop(context.scene, prop_name)
@@ -385,7 +398,7 @@ class NerfstudioInputPanel(bpy.types.Panel): # pylint: disable=too-few-public-m
self.layout.label(text="Create Blender Camera From Nerfstudio JSON")
col = self.layout.column()
- for (prop_name, _) in INPUT_PROPERTIES_NS_CAMERA:
+ for prop_name, _ in INPUT_PROPERTIES_NS_CAMERA:
row = col.row()
row.prop(context.scene, prop_name)
@@ -425,10 +438,10 @@ OBJ_PROPERTIES = ["NeRF", "RenderCamera"]
def register():
"""Register classes for UI panel."""
- for (prop_name, prop_value) in INPUT_PROPERTIES:
+ for prop_name, prop_value in INPUT_PROPERTIES:
setattr(bpy.types.Scene, prop_name, prop_value)
- for (prop_name, prop_value) in INPUT_PROPERTIES_NS_CAMERA:
+ for prop_name, prop_value in INPUT_PROPERTIES_NS_CAMERA:
setattr(bpy.types.Scene, prop_name, prop_value)
bpy.types.Scene.NeRF = bpy.props.PointerProperty(type=bpy.types.Object)
@@ -440,10 +453,10 @@ def register():
def unregister():
"""Unregister classes for UI panel."""
- for (prop_name, _) in INPUT_PROPERTIES:
+ for prop_name, _ in INPUT_PROPERTIES:
delattr(bpy.types.Scene, prop_name)
- for (prop_name, _) in INPUT_PROPERTIES_NS_CAMERA:
+ for prop_name, _ in INPUT_PROPERTIES_NS_CAMERA:
delattr(bpy.types.Scene, prop_name)
del bpy.types.Scene.NeRF
diff --git a/scripts/completions/.gitignore b/nerfstudio/scripts/completions/.gitignore
similarity index 100%
rename from scripts/completions/.gitignore
rename to nerfstudio/scripts/completions/.gitignore
diff --git a/nerfstudio/scripts/completions/__init__.py b/nerfstudio/scripts/completions/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/completions/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/scripts/completions/install.py b/nerfstudio/scripts/completions/install.py
similarity index 94%
rename from scripts/completions/install.py
rename to nerfstudio/scripts/completions/install.py
index 98e67fea2..cba1d672b 100644
--- a/scripts/completions/install.py
+++ b/nerfstudio/scripts/completions/install.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
#!/usr/bin/env python
"""Configuration script for setting up tab completion for nerfstudio in bash and zsh."""
@@ -10,13 +24,13 @@ import shutil
import stat
import subprocess
import sys
-from typing import List, Optional, Union
+from typing import List, Literal, Optional, Union
+from typing import get_args as typing_get_args
import tyro
from rich.console import Console
from rich.prompt import Confirm
-from typing_extensions import Literal, assert_never
-from typing_extensions import get_args as typing_get_args
+from typing_extensions import assert_never
if sys.version_info < (3, 10):
import importlib_metadata
@@ -31,6 +45,7 @@ HEADER_LINE = "# Source nerfstudio autocompletions."
def _get_all_entry_points() -> List[str]:
+ # TODO: we should filter out entrypoints that are not tyro CLIs.
entry_points = importlib_metadata.distribution("nerfstudio").entry_points
return [x.name for x in entry_points]
@@ -399,3 +414,6 @@ def entrypoint():
if __name__ == "__main__":
entrypoint()
+
+# For sphinx docs
+get_parser_fn = lambda: tyro.extras.get_parser(main) # noqa
diff --git a/scripts/completions/setup.bash b/nerfstudio/scripts/completions/setup.bash
similarity index 100%
rename from scripts/completions/setup.bash
rename to nerfstudio/scripts/completions/setup.bash
diff --git a/scripts/completions/setup.zsh b/nerfstudio/scripts/completions/setup.zsh
similarity index 100%
rename from scripts/completions/setup.zsh
rename to nerfstudio/scripts/completions/setup.zsh
diff --git a/scripts/datasets/process_nuscenes_masks.py b/nerfstudio/scripts/datasets/process_nuscenes_masks.py
similarity index 87%
rename from scripts/datasets/process_nuscenes_masks.py
rename to nerfstudio/scripts/datasets/process_nuscenes_masks.py
index cb9328f95..748a27fd2 100644
--- a/scripts/datasets/process_nuscenes_masks.py
+++ b/nerfstudio/scripts/datasets/process_nuscenes_masks.py
@@ -1,7 +1,21 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
import os
from dataclasses import dataclass
from pathlib import Path
-from typing import Tuple
+from typing import Literal, Tuple
import cv2
import numpy as np
@@ -10,7 +24,6 @@ from nuscenes.nuscenes import NuScenes as NuScenesDatabase
from nuscenes.utils.data_classes import Box
from nuscenes.utils.geometry_utils import BoxVisibility, view_points
from tqdm import tqdm
-from typing_extensions import Literal
@dataclass
@@ -79,8 +92,11 @@ class ProcessNuScenesMasks:
# Instead use BoxVisibility.NONE and make sure to rasterize box faces correctly
mask = np.ones((900, 1600), dtype=np.uint8)
- for box in boxes:
+ # If is backcam, mask the truck of the ego vehicle
+ if camera == "CAM_BACK":
+ mask[-100:] = 0
+ for box in boxes:
# Dont mask out static objects (static in all frames)
instance_token = nusc.get("sample_annotation", box.token)["instance_token"]
if not instances_is_dynamic[instance_token]:
diff --git a/nerfstudio/scripts/docs/__init__.py b/nerfstudio/scripts/docs/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/docs/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/scripts/docs/add_nb_tags.py b/nerfstudio/scripts/docs/add_nb_tags.py
similarity index 78%
rename from scripts/docs/add_nb_tags.py
rename to nerfstudio/scripts/docs/add_nb_tags.py
index 4a7d97fe0..a110e0d76 100644
--- a/scripts/docs/add_nb_tags.py
+++ b/nerfstudio/scripts/docs/add_nb_tags.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
"""Helper that add tags to notebooks based on cell comments."""
import sys
@@ -60,7 +74,8 @@ def main(check: bool = False):
if incorrect_metadata:
if check:
CONSOLE.print(
- f"[bold yellow]{ipath} has incorrect metadata. Call `python scripts.docs.add_nb_tags.py` to add it."
+ f"[bold yellow]{ipath} has incorrect metadata. "
+ "Call `python nerfstudio.scripts.docs.add_nb_tags.py` to add it."
)
any_missing = True
else:
diff --git a/scripts/docs/build_docs.py b/nerfstudio/scripts/docs/build_docs.py
similarity index 66%
rename from scripts/docs/build_docs.py
rename to nerfstudio/scripts/docs/build_docs.py
index cb31e54b3..1959220a1 100644
--- a/scripts/docs/build_docs.py
+++ b/nerfstudio/scripts/docs/build_docs.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
#!/usr/bin/env python
"""Simple yaml debugger"""
import subprocess
@@ -32,7 +46,7 @@ def main(clean_cache: bool = False):
"""
CONSOLE.print("[green]Adding notebook documentation metadata")
- run_command("python scripts/docs/add_nb_tags.py")
+ run_command("python nerfstudio/scripts/docs/add_nb_tags.py")
# Add checks for building documentation
CONSOLE.print("[green]Building Documentation")
diff --git a/nerfstudio/scripts/downloads/__init__.py b/nerfstudio/scripts/downloads/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/downloads/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/scripts/downloads/download_data.py b/nerfstudio/scripts/downloads/download_data.py
similarity index 81%
rename from scripts/downloads/download_data.py
rename to nerfstudio/scripts/downloads/download_data.py
index 3339b50bc..d97dd659b 100644
--- a/scripts/downloads/download_data.py
+++ b/nerfstudio/scripts/downloads/download_data.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
"""Download datasets and specific captures from the datasets."""
from __future__ import annotations
@@ -359,6 +373,65 @@ class SDFstudioDemoDownload(DatasetDownload):
os.remove(download_path)
+# pylint: disable=line-too-long
+nerfosr_downloads = {
+ "europa": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=europa&downloadStartSecret=0k2r95c1fdej",
+ "lk2": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=lk2&downloadStartSecret=w8kuvjzmchc",
+ "lwp": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=lwp&downloadStartSecret=gtnc4vmkcjq",
+ "rathaus": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=rathaus&downloadStartSecret=7372aewy6rr",
+ "schloss": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=schloss&downloadStartSecret=y8t00nqx0h",
+ "st": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=st&downloadStartSecret=kl9ptuxe8v",
+ "stjacob": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=stjacob&downloadStartSecret=sntsim6ebvm",
+ "stjohann": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=stjohann&downloadStartSecret=g80ug1fsbmh",
+ "trevi": "https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk/download?path=%2FData&files=trevi&downloadStartSecret=ot1483bigjm",
+ "all": None,
+}
+
+
+NeRFOSRCaptureName = tyro.extras.literal_type_from_choices(nerfosr_downloads.keys())
+
+
+@dataclass
+class NeRFOSRDownload(DatasetDownload):
+ """Download the NeRF-OSR dataset."""
+
+ capture_name: NeRFOSRCaptureName = "europa"
+
+ def download(self, save_dir: Path):
+ """Download the NeRF-OSR dataset: https://nextcloud.mpi-klsb.mpg.de/index.php/s/mGXYKpD8raQ8nMk"""
+
+ if self.capture_name == "all":
+ for capture_name in nerfosr_downloads:
+ if capture_name != "all":
+ NeRFOSRDownload(capture_name=capture_name).download(save_dir)
+ return
+
+ assert (
+ self.capture_name in nerfosr_downloads
+ ), f"Capture name {self.capture_name} not found in {nerfosr_downloads.keys()}"
+ url = nerfosr_downloads[self.capture_name]
+ target_path = str(save_dir / f"NeRF-OSR/Data/{self.capture_name}")
+ os.makedirs(target_path, exist_ok=True)
+ download_path = Path(f"{target_path}.zip")
+ tmp_path = str(save_dir / ".temp")
+ shutil.rmtree(tmp_path, ignore_errors=True)
+ os.makedirs(tmp_path, exist_ok=True)
+
+ os.system(f"curl -L '{url}' > {download_path}")
+
+ # Extract the zip file
+ with zipfile.ZipFile(download_path, "r") as zip_ref:
+ zip_ref.extractall(tmp_path)
+
+ inner_folders = os.listdir(tmp_path)
+ assert len(inner_folders) == 1, "There is more than one folder inside this zip file."
+ folder = os.path.join(tmp_path, inner_folders[0])
+ shutil.rmtree(target_path)
+ shutil.move(folder, target_path)
+ shutil.rmtree(tmp_path)
+ os.remove(download_path)
+
+
Commands = Union[
Annotated[BlenderDownload, tyro.conf.subcommand(name="blender")],
Annotated[Sitcoms3DDownload, tyro.conf.subcommand(name="sitcoms3d")],
@@ -367,6 +440,7 @@ Commands = Union[
Annotated[DNerfDownload, tyro.conf.subcommand(name="dnerf")],
Annotated[PhototourismDownload, tyro.conf.subcommand(name="phototourism")],
Annotated[SDFstudioDemoDownload, tyro.conf.subcommand(name="sdfstudio")],
+ Annotated[NeRFOSRDownload, tyro.conf.subcommand(name="nerfosr")],
]
diff --git a/scripts/eval.py b/nerfstudio/scripts/eval.py
similarity index 68%
rename from scripts/eval.py
rename to nerfstudio/scripts/eval.py
index e9ba12f78..517da3179 100644
--- a/scripts/eval.py
+++ b/nerfstudio/scripts/eval.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
#!/usr/bin/env python
"""
eval.py
@@ -27,7 +41,7 @@ class ComputePSNR:
def main(self) -> None:
"""Main function."""
- config, pipeline, checkpoint_path = eval_setup(self.load_config)
+ config, pipeline, checkpoint_path, _ = eval_setup(self.load_config)
assert self.output_path.suffix == ".json"
metrics_dict = pipeline.get_average_eval_image_metrics()
self.output_path.parent.mkdir(parents=True, exist_ok=True)
diff --git a/scripts/exporter.py b/nerfstudio/scripts/exporter.py
similarity index 79%
rename from scripts/exporter.py
rename to nerfstudio/scripts/exporter.py
index cd18aa354..dfca20637 100644
--- a/scripts/exporter.py
+++ b/nerfstudio/scripts/exporter.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
"""
Script for exporting NeRF into other formats.
"""
@@ -27,6 +41,9 @@ from nerfstudio.exporter.exporter_utils import (
generate_point_cloud,
get_mesh_from_filename,
)
+from nerfstudio.exporter.marching_cubes import (
+ generate_mesh_with_multires_marching_cubes,
+)
from nerfstudio.pipelines.base_pipeline import Pipeline, VanillaPipeline
from nerfstudio.utils.eval_utils import eval_setup
@@ -74,7 +91,7 @@ class ExportPointCloud(Exporter):
if not self.output_dir.exists():
self.output_dir.mkdir(parents=True)
- _, pipeline, _ = eval_setup(self.load_config)
+ _, pipeline, _, _ = eval_setup(self.load_config)
# Increase the batchsize to speed up the evaluation.
pipeline.datamanager.train_pixel_sampler.num_rays_per_batch = self.num_rays_per_batch
@@ -144,7 +161,7 @@ class ExportTSDFMesh(Exporter):
if not self.output_dir.exists():
self.output_dir.mkdir(parents=True)
- _, pipeline, _ = eval_setup(self.load_config)
+ _, pipeline, _, _ = eval_setup(self.load_config)
tsdf_utils.export_tsdf_mesh(
pipeline,
@@ -250,7 +267,7 @@ class ExportPoissonMesh(Exporter):
if not self.output_dir.exists():
self.output_dir.mkdir(parents=True)
- _, pipeline, _ = eval_setup(self.load_config)
+ _, pipeline, _, _ = eval_setup(self.load_config)
self.validate_pipeline(pipeline)
# Increase the batchsize to speed up the evaluation.
@@ -313,14 +330,68 @@ class ExportPoissonMesh(Exporter):
@dataclass
class ExportMarchingCubesMesh(Exporter):
- """
- NOT YET IMPLEMENTED
- Export a mesh using marching cubes.
- """
+ """Export a mesh using marching cubes."""
+
+ isosurface_threshold: float = 0.0
+ """The isosurface threshold for extraction. For SDF based methods the surface is the zero level set."""
+ resolution: int = 1024
+ """Marching cube resolution."""
+ simplify_mesh: bool = False
+ """Whether to simplify the mesh."""
+ bounding_box_min: Tuple[float, float, float] = (-1.0, -1.0, -1.0)
+ """Minimum of the bounding box."""
+ bounding_box_max: Tuple[float, float, float] = (1.0, 1.0, 1.0)
+ """Maximum of the bounding box."""
+ px_per_uv_triangle: int = 4
+ """Number of pixels per UV triangle."""
+ unwrap_method: Literal["xatlas", "custom"] = "xatlas"
+ """The method to use for unwrapping the mesh."""
+ num_pixels_per_side: int = 2048
+ """If using xatlas for unwrapping, the pixels per side of the texture image."""
+ target_num_faces: Optional[int] = 50000
+ """Target number of faces for the mesh to texture."""
def main(self) -> None:
- """Export mesh"""
- raise NotImplementedError("Marching cubes not implemented yet.")
+ """Main function."""
+ if not self.output_dir.exists():
+ self.output_dir.mkdir(parents=True)
+
+ _, pipeline, _, _ = eval_setup(self.load_config)
+
+ # TODO: Make this work with Density Field
+ assert hasattr(pipeline.model.config, "sdf_field"), "Model must have an SDF field."
+
+ CONSOLE.print("Extracting mesh with marching cubes... which may take a while")
+
+ assert (
+ self.resolution % 512 == 0
+ ), f"""resolution must be divisible by 512, got {self.resolution}.
+ This is important because the algorithm uses a multi-resolution approach
+ to evaluate the SDF where the mimimum resolution is 512."""
+
+ # Extract mesh using marching cubes for sdf at a multi-scale resolution.
+ multi_res_mesh = generate_mesh_with_multires_marching_cubes(
+ geometry_callable_field=lambda x: pipeline.model.field.forward_geonetwork(x)[:, 0].contiguous(),
+ resolution=self.resolution,
+ bounding_box_min=self.bounding_box_min,
+ bounding_box_max=self.bounding_box_max,
+ isosurface_threshold=self.isosurface_threshold,
+ coarse_mask=None,
+ )
+ filename = self.output_dir / "sdf_marching_cubes_mesh.ply"
+ multi_res_mesh.export(filename)
+
+ # load the mesh from the marching cubes export
+ mesh = get_mesh_from_filename(str(filename), target_num_faces=self.target_num_faces)
+ CONSOLE.print("Texturing mesh with NeRF...")
+ texture_utils.export_textured_mesh(
+ mesh,
+ pipeline,
+ self.output_dir,
+ px_per_uv_triangle=self.px_per_uv_triangle if self.unwrap_method == "custom" else None,
+ unwrap_method=self.unwrap_method,
+ num_pixels_per_side=self.num_pixels_per_side,
+ )
@dataclass
@@ -334,7 +405,7 @@ class ExportCameraPoses(Exporter):
if not self.output_dir.exists():
self.output_dir.mkdir(parents=True)
- _, pipeline, _ = eval_setup(self.load_config)
+ _, pipeline, _, _ = eval_setup(self.load_config)
assert isinstance(pipeline, VanillaPipeline)
train_frames, eval_frames = collect_camera_poses(pipeline)
diff --git a/nerfstudio/scripts/generative/__init__.py b/nerfstudio/scripts/generative/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/generative/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/scripts/generative/trace_stable_diffusion.py b/nerfstudio/scripts/generative/trace_stable_diffusion.py
similarity index 84%
rename from scripts/generative/trace_stable_diffusion.py
rename to nerfstudio/scripts/generative/trace_stable_diffusion.py
index eee069eb3..3a426cb2c 100644
--- a/scripts/generative/trace_stable_diffusion.py
+++ b/nerfstudio/scripts/generative/trace_stable_diffusion.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
"""Trace Stable Diffusion UNet for speed improvement"""
import functools
diff --git a/nerfstudio/scripts/github/__init__.py b/nerfstudio/scripts/github/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/github/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/scripts/github/run_actions.py b/nerfstudio/scripts/github/run_actions.py
similarity index 81%
rename from scripts/github/run_actions.py
rename to nerfstudio/scripts/github/run_actions.py
index 19179725c..8f5bb7ce1 100644
--- a/scripts/github/run_actions.py
+++ b/nerfstudio/scripts/github/run_actions.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
#!/usr/bin/env python
"""Simple yaml debugger"""
import subprocess
@@ -57,7 +71,9 @@ def run_github_actions_file(filename: str, continue_on_fail: bool = False):
# Add checks for building documentation
CONSOLE.line()
CONSOLE.rule("[bold green]Adding notebook documentation metadata")
- success = success and run_command("python scripts/docs/add_nb_tags.py", continue_on_fail=continue_on_fail)
+ success = success and run_command(
+ "python nerfstudio/scripts/docs/add_nb_tags.py", continue_on_fail=continue_on_fail
+ )
CONSOLE.line()
CONSOLE.rule("[bold green]Building Documentation")
success = success and run_command("cd docs/; make html SPHINXOPTS='-W;'", continue_on_fail=continue_on_fail)
diff --git a/scripts/licensing/copyright.txt b/nerfstudio/scripts/licensing/copyright.txt
similarity index 100%
rename from scripts/licensing/copyright.txt
rename to nerfstudio/scripts/licensing/copyright.txt
diff --git a/scripts/licensing/license_headers.sh b/nerfstudio/scripts/licensing/license_headers.sh
similarity index 80%
rename from scripts/licensing/license_headers.sh
rename to nerfstudio/scripts/licensing/license_headers.sh
index 36482085c..286d7ffb1 100755
--- a/scripts/licensing/license_headers.sh
+++ b/nerfstudio/scripts/licensing/license_headers.sh
@@ -27,7 +27,7 @@ do
echo "$i missing copyright header"
check_failed=true
else
- cat scripts/licensing/copyright.txt $i >$i.new && mv $i.new $i
+ cat nerfstudio/scripts/licensing/copyright.txt $i >$i.new && mv $i.new $i
echo "Adding license header to $i."
fi
added_headers=true
@@ -36,7 +36,7 @@ done
if [ "$check_failed" = true ];
then
- echo "Run '.scripts/licensing/license_headers.sh to add missing headers.'"
+ echo "Run '.nerfstudio/scripts/licensing/license_headers.sh to add missing headers.'"
exit 1
fi
diff --git a/nerfstudio/scripts/process_data.py b/nerfstudio/scripts/process_data.py
new file mode 100644
index 000000000..4c2f3829b
--- /dev/null
+++ b/nerfstudio/scripts/process_data.py
@@ -0,0 +1,419 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+#!/usr/bin/env python
+"""Processes a video or image sequence to a nerfstudio compatible dataset."""
+
+
+import sys
+import zipfile
+from dataclasses import dataclass
+from pathlib import Path
+from typing import Union
+
+import numpy as np
+import tyro
+from rich.console import Console
+from typing_extensions import Annotated
+
+from nerfstudio.process_data import (
+ metashape_utils,
+ polycam_utils,
+ process_data_utils,
+ realitycapture_utils,
+ record3d_utils,
+)
+from nerfstudio.process_data.colmap_converter_to_nerfstudio_dataset import (
+ BaseConverterToNerfstudioDataset,
+)
+from nerfstudio.process_data.images_to_nerfstudio_dataset import (
+ ImagesToNerfstudioDataset,
+)
+from nerfstudio.process_data.video_to_nerfstudio_dataset import VideoToNerfstudioDataset
+
+CONSOLE = Console(width=120)
+
+
+@dataclass
+class ProcessRecord3D(BaseConverterToNerfstudioDataset):
+ """Process Record3D data into a nerfstudio dataset.
+
+ This script does the following:
+
+ 1. Scales images to a specified size.
+ 2. Converts Record3D poses into the nerfstudio format.
+ """
+
+ num_downscales: int = 3
+ """Number of times to downscale the images. Downscales by 2 each time. For example a value of 3
+ will downscale the images by 2x, 4x, and 8x."""
+ max_dataset_size: int = 300
+ """Max number of images to train on. If the dataset has more, images will be sampled approximately evenly. If -1,
+ use all images."""
+
+ def main(self) -> None:
+ """Process images into a nerfstudio dataset."""
+
+ self.output_dir.mkdir(parents=True, exist_ok=True)
+ image_dir = self.output_dir / "images"
+ image_dir.mkdir(parents=True, exist_ok=True)
+
+ summary_log = []
+
+ record3d_image_dir = self.data / "rgb"
+
+ if not record3d_image_dir.exists():
+ raise ValueError(f"Image directory {record3d_image_dir} doesn't exist")
+
+ record3d_image_filenames = []
+ for f in record3d_image_dir.iterdir():
+ if f.stem.isdigit(): # removes possible duplicate images (for example, 123(3).jpg)
+ if f.suffix.lower() in [".jpg", ".jpeg", ".png", ".tif", ".tiff"]:
+ record3d_image_filenames.append(f)
+
+ record3d_image_filenames = sorted(record3d_image_filenames, key=lambda fn: int(fn.stem))
+ num_images = len(record3d_image_filenames)
+ idx = np.arange(num_images)
+ if self.max_dataset_size != -1 and num_images > self.max_dataset_size:
+ idx = np.round(np.linspace(0, num_images - 1, self.max_dataset_size)).astype(int)
+
+ record3d_image_filenames = list(np.array(record3d_image_filenames)[idx])
+ # Copy images to output directory
+ copied_image_paths = process_data_utils.copy_images_list(
+ record3d_image_filenames, image_dir=image_dir, verbose=self.verbose
+ )
+ num_frames = len(copied_image_paths)
+
+ copied_image_paths = [Path("images/" + copied_image_path.name) for copied_image_path in copied_image_paths]
+ summary_log.append(f"Used {num_frames} images out of {num_images} total")
+ if self.max_dataset_size > 0:
+ summary_log.append(
+ "To change the size of the dataset add the argument [yellow]--max_dataset_size[/yellow] to "
+ f"larger than the current value ({self.max_dataset_size}), or -1 to use all images."
+ )
+
+ # Downscale images
+ summary_log.append(process_data_utils.downscale_images(image_dir, self.num_downscales, verbose=self.verbose))
+
+ metadata_path = self.data / "metadata.json"
+ record3d_utils.record3d_to_json(copied_image_paths, metadata_path, self.output_dir, indices=idx)
+ CONSOLE.rule("[bold green]:tada: :tada: :tada: All DONE :tada: :tada: :tada:")
+
+ for summary in summary_log:
+ CONSOLE.print(summary, justify="center")
+ CONSOLE.rule()
+
+
+@dataclass
+class ProcessPolycam(BaseConverterToNerfstudioDataset):
+ """Process Polycam data into a nerfstudio dataset.
+
+ To capture data, use the Polycam app on an iPhone or iPad with LiDAR. The capture must be in LiDAR or ROOM mode.
+ Developer mode must be enabled in the app settings, this will enable a raw data export option in the export menus.
+ The exported data folder is used as the input to this script.
+
+ This script does the following:
+
+ 1. Scales images to a specified size.
+ 2. Converts Polycam poses into the nerfstudio format.
+ """
+
+ num_downscales: int = 3
+ """Number of times to downscale the images. Downscales by 2 each time. For example a value of 3
+ will downscale the images by 2x, 4x, and 8x."""
+ use_uncorrected_images: bool = False
+ """If True, use the raw images from the polycam export. If False, use the corrected images."""
+ max_dataset_size: int = 600
+ """Max number of images to train on. If the dataset has more, images will be sampled approximately evenly. If -1,
+ use all images."""
+ min_blur_score: float = 25
+ """Minimum blur score to use an image. If the blur score is below this value, the image will be skipped."""
+ crop_border_pixels: int = 15
+ """Number of pixels to crop from each border of the image. Useful as borders may be black due to undistortion."""
+ use_depth: bool = False
+ """If True, processes the generated depth maps from Polycam"""
+
+ def main(self) -> None:
+ """Process images into a nerfstudio dataset."""
+
+ self.output_dir.mkdir(parents=True, exist_ok=True)
+ image_dir = self.output_dir / "images"
+ image_dir.mkdir(parents=True, exist_ok=True)
+
+ summary_log = []
+
+ if self.data.suffix == ".zip":
+ with zipfile.ZipFile(self.data, "r") as zip_ref:
+ zip_ref.extractall(self.output_dir)
+ extracted_folder = zip_ref.namelist()[0].split("/")[0]
+ self.data = self.output_dir / extracted_folder
+
+ if (self.data / "keyframes" / "corrected_images").exists() and not self.use_uncorrected_images:
+ polycam_image_dir = self.data / "keyframes" / "corrected_images"
+ polycam_cameras_dir = self.data / "keyframes" / "corrected_cameras"
+ else:
+ polycam_image_dir = self.data / "keyframes" / "images"
+ polycam_cameras_dir = self.data / "keyframes" / "cameras"
+ if not self.use_uncorrected_images:
+ CONSOLE.print("[bold yellow]Corrected images not found, using raw images.")
+
+ if not polycam_image_dir.exists():
+ raise ValueError(f"Image directory {polycam_image_dir} doesn't exist")
+
+ if not (self.data / "keyframes" / "depth").exists():
+ depth_dir = self.data / "keyframes" / "depth"
+ raise ValueError(f"Depth map directory {depth_dir} doesn't exist")
+
+ (image_processing_log, polycam_image_filenames) = polycam_utils.process_images(
+ polycam_image_dir,
+ image_dir,
+ crop_border_pixels=self.crop_border_pixels,
+ max_dataset_size=self.max_dataset_size,
+ num_downscales=self.num_downscales,
+ verbose=self.verbose,
+ )
+
+ summary_log.extend(image_processing_log)
+
+ polycam_depth_filenames = []
+ if self.use_depth:
+ polycam_depth_image_dir = self.data / "keyframes" / "depth"
+ depth_dir = self.output_dir / "depth"
+ depth_dir.mkdir(parents=True, exist_ok=True)
+ (depth_processing_log, polycam_depth_filenames) = polycam_utils.process_depth_maps(
+ polycam_depth_image_dir,
+ depth_dir,
+ num_processed_images=len(polycam_image_filenames),
+ crop_border_pixels=self.crop_border_pixels,
+ max_dataset_size=self.max_dataset_size,
+ num_downscales=self.num_downscales,
+ verbose=self.verbose,
+ )
+ summary_log.extend(depth_processing_log)
+
+ summary_log.extend(
+ polycam_utils.polycam_to_json(
+ image_filenames=polycam_image_filenames,
+ depth_filenames=polycam_depth_filenames,
+ cameras_dir=polycam_cameras_dir,
+ output_dir=self.output_dir,
+ min_blur_score=self.min_blur_score,
+ crop_border_pixels=self.crop_border_pixels,
+ )
+ )
+
+ CONSOLE.rule("[bold green]:tada: :tada: :tada: All DONE :tada: :tada: :tada:")
+
+ for summary in summary_log:
+ CONSOLE.print(summary, justify="center")
+ CONSOLE.rule()
+
+
+@dataclass
+class _NoDefaultProcessMetashape:
+ """Private class to order the parameters of ProcessMetashape in the right order for default values."""
+
+ xml: Path
+ """Path to the Metashape xml file."""
+
+
+@dataclass
+class ProcessMetashape(BaseConverterToNerfstudioDataset, _NoDefaultProcessMetashape):
+ """Process Metashape data into a nerfstudio dataset.
+
+ This script assumes that cameras have been aligned using Metashape. After alignment, it is necessary to export the
+ camera poses as a `.xml` file. This option can be found under `File > Export > Export Cameras`.
+
+ This script does the following:
+
+ 1. Scales images to a specified size.
+ 2. Converts Metashape poses into the nerfstudio format.
+ """
+
+ num_downscales: int = 3
+ """Number of times to downscale the images. Downscales by 2 each time. For example a value of 3
+ will downscale the images by 2x, 4x, and 8x."""
+ max_dataset_size: int = 600
+ """Max number of images to train on. If the dataset has more, images will be sampled approximately evenly. If -1,
+ use all images."""
+
+ def main(self) -> None:
+ """Process images into a nerfstudio dataset."""
+
+ if self.xml.suffix != ".xml":
+ raise ValueError(f"XML file {self.xml} must have a .xml extension")
+ if not self.xml.exists:
+ raise ValueError(f"XML file {self.xml} doesn't exist")
+
+ self.output_dir.mkdir(parents=True, exist_ok=True)
+ image_dir = self.output_dir / "images"
+ image_dir.mkdir(parents=True, exist_ok=True)
+
+ summary_log = []
+
+ # Copy images to output directory
+ image_filenames, num_orig_images = process_data_utils.get_image_filenames(self.data, self.max_dataset_size)
+ copied_image_paths = process_data_utils.copy_images_list(
+ image_filenames,
+ image_dir=image_dir,
+ verbose=self.verbose,
+ )
+ num_frames = len(copied_image_paths)
+
+ copied_image_paths = [Path("images/" + copied_image_path.name) for copied_image_path in copied_image_paths]
+ original_names = [image_path.stem for image_path in image_filenames]
+ image_filename_map = dict(zip(original_names, copied_image_paths))
+
+ if self.max_dataset_size > 0 and num_frames != num_orig_images:
+ summary_log.append(f"Started with {num_frames} images out of {num_orig_images} total")
+ summary_log.append(
+ "To change the size of the dataset add the argument [yellow]--max_dataset_size[/yellow] to "
+ f"larger than the current value ({self.max_dataset_size}), or -1 to use all images."
+ )
+ else:
+ summary_log.append(f"Started with {num_frames} images")
+
+ # Downscale images
+ summary_log.append(process_data_utils.downscale_images(image_dir, self.num_downscales, verbose=self.verbose))
+
+ # Save json
+ if num_frames == 0:
+ CONSOLE.print("[bold red]No images found, exiting")
+ sys.exit(1)
+ summary_log.extend(
+ metashape_utils.metashape_to_json(
+ image_filename_map=image_filename_map,
+ xml_filename=self.xml,
+ output_dir=self.output_dir,
+ verbose=self.verbose,
+ )
+ )
+
+ CONSOLE.rule("[bold green]:tada: :tada: :tada: All DONE :tada: :tada: :tada:")
+
+ for summary in summary_log:
+ CONSOLE.print(summary, justify="center")
+ CONSOLE.rule()
+
+
+@dataclass
+class _NoDefaultProcessRealityCapture:
+ """Private class to order the parameters of ProcessRealityCapture in the right order for default values."""
+
+ csv: Path
+ """Path to the RealityCapture cameras CSV file."""
+
+
+@dataclass
+class ProcessRealityCapture(BaseConverterToNerfstudioDataset, _NoDefaultProcessRealityCapture):
+ """Process RealityCapture data into a nerfstudio dataset.
+
+ This script assumes that cameras have been aligned using RealityCapture. After alignment, it is necessary to
+ export the camera poses as a `.csv` file using the `Internal/External camera parameters` option.
+
+ This script does the following:
+
+ 1. Scales images to a specified size.
+ 2. Converts RealityCapture poses into the nerfstudio format.
+ """
+
+ num_downscales: int = 3
+ """Number of times to downscale the images. Downscales by 2 each time. For example a value of 3
+ will downscale the images by 2x, 4x, and 8x."""
+ max_dataset_size: int = 600
+ """Max number of images to train on. If the dataset has more, images will be sampled approximately evenly. If -1,
+ use all images."""
+
+ def main(self) -> None:
+ """Process images into a nerfstudio dataset."""
+
+ if self.csv.suffix != ".csv":
+ raise ValueError(f"CSV file {self.csv} must have a .csv extension")
+ if not self.csv.exists:
+ raise ValueError(f"CSV file {self.csv} doesn't exist")
+
+ self.output_dir.mkdir(parents=True, exist_ok=True)
+ image_dir = self.output_dir / "images"
+ image_dir.mkdir(parents=True, exist_ok=True)
+
+ summary_log = []
+
+ # Copy images to output directory
+ image_filenames, num_orig_images = process_data_utils.get_image_filenames(self.data, self.max_dataset_size)
+ copied_image_paths = process_data_utils.copy_images_list(
+ image_filenames,
+ image_dir=image_dir,
+ verbose=self.verbose,
+ )
+ num_frames = len(copied_image_paths)
+
+ copied_image_paths = [Path("images/" + copied_image_path.name) for copied_image_path in copied_image_paths]
+ original_names = [image_path.stem for image_path in image_filenames]
+ image_filename_map = dict(zip(original_names, copied_image_paths))
+
+ if self.max_dataset_size > 0 and num_frames != num_orig_images:
+ summary_log.append(f"Started with {num_frames} images out of {num_orig_images} total")
+ summary_log.append(
+ "To change the size of the dataset add the argument [yellow]--max_dataset_size[/yellow] to "
+ f"larger than the current value ({self.max_dataset_size}), or -1 to use all images."
+ )
+ else:
+ summary_log.append(f"Started with {num_frames} images")
+
+ # Downscale images
+ summary_log.append(process_data_utils.downscale_images(image_dir, self.num_downscales, verbose=self.verbose))
+
+ # Save json
+ if num_frames == 0:
+ CONSOLE.print("[bold red]No images found, exiting")
+ sys.exit(1)
+ summary_log.extend(
+ realitycapture_utils.realitycapture_to_json(
+ image_filename_map=image_filename_map,
+ csv_filename=self.csv,
+ output_dir=self.output_dir,
+ )
+ )
+
+ CONSOLE.rule("[bold green]:tada: :tada: :tada: All DONE :tada: :tada: :tada:")
+
+ for summary in summary_log:
+ CONSOLE.print(summary, justify="center")
+ CONSOLE.rule()
+
+
+Commands = Union[
+ Annotated[ImagesToNerfstudioDataset, tyro.conf.subcommand(name="images")],
+ Annotated[VideoToNerfstudioDataset, tyro.conf.subcommand(name="video")],
+ Annotated[ProcessPolycam, tyro.conf.subcommand(name="polycam")],
+ Annotated[ProcessMetashape, tyro.conf.subcommand(name="metashape")],
+ Annotated[ProcessRealityCapture, tyro.conf.subcommand(name="realitycapture")],
+ Annotated[ProcessRecord3D, tyro.conf.subcommand(name="record3d")],
+]
+
+
+def entrypoint():
+ """Entrypoint for use with pyproject scripts."""
+ tyro.extras.set_accent_color("bright_yellow")
+ try:
+ tyro.cli(Commands).main()
+ except RuntimeError as e:
+ CONSOLE.log("[bold red]" + e.args[0])
+
+
+if __name__ == "__main__":
+ entrypoint()
+
+# For sphinx docs
+get_parser_fn = lambda: tyro.extras.get_parser(Commands) # type: ignore
diff --git a/scripts/render.py b/nerfstudio/scripts/render.py
similarity index 87%
rename from scripts/render.py
rename to nerfstudio/scripts/render.py
index ce2f79dc2..ae6937380 100644
--- a/scripts/render.py
+++ b/nerfstudio/scripts/render.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
#!/usr/bin/env python
"""
render.py
@@ -11,13 +25,15 @@ import sys
from contextlib import ExitStack
from dataclasses import dataclass, field
from pathlib import Path
-from typing import Any, Dict, List, Optional
+from typing import Any, Dict, List, Literal, Optional
import mediapy as media
import numpy as np
import torch
import tyro
+from rich import box, style
from rich.console import Console
+from rich.panel import Panel
from rich.progress import (
BarColumn,
Progress,
@@ -25,8 +41,9 @@ from rich.progress import (
TextColumn,
TimeRemainingColumn,
)
+from rich.table import Table
from torchtyping import TensorType
-from typing_extensions import Literal, assert_never
+from typing_extensions import assert_never
from nerfstudio.cameras.camera_paths import (
get_interpolated_camera_path,
@@ -37,7 +54,7 @@ from nerfstudio.cameras.cameras import Cameras, CameraType
from nerfstudio.data.scene_box import SceneBox
from nerfstudio.model_components import renderers
from nerfstudio.pipelines.base_pipeline import Pipeline
-from nerfstudio.utils import install_checks
+from nerfstudio.utils import colormaps, install_checks
from nerfstudio.utils.eval_utils import eval_setup
from nerfstudio.utils.rich_utils import ItersPerSecColumn
@@ -54,6 +71,7 @@ def _render_trajectory_video(
seconds: float = 5.0,
output_format: Literal["images", "video"] = "video",
camera_type: CameraType = CameraType.PERSPECTIVE,
+ colormap_options: colormaps.ColormapOptions = colormaps.ColormapOptions(),
) -> None:
"""Helper function to create a video of the spiral trajectory.
@@ -67,6 +85,7 @@ def _render_trajectory_video(
seconds: Length of output video.
output_format: How to save output data.
camera_type: Camera projection format type.
+ colormap_options: Options for colormap.
"""
CONSOLE.print("[bold green]Creating trajectory " + output_format)
cameras.rescale_output_resolution(rendered_resolution_scaling_factor)
@@ -80,8 +99,8 @@ def _render_trajectory_video(
ItersPerSecColumn(suffix="fps"),
TimeRemainingColumn(elapsed_when_finished=True, compact=True),
)
+ output_image_dir = output_filename.parent / output_filename.stem
if output_format == "images":
- output_image_dir = output_filename.parent / output_filename.stem
output_image_dir.mkdir(parents=True, exist_ok=True)
if output_format == "video":
# make the folder if it doesn't exist
@@ -123,9 +142,15 @@ def _render_trajectory_video(
f"Please set --rendered_output_name to one of: {outputs.keys()}", justify="center"
)
sys.exit(1)
- output_image = outputs[rendered_output_name].cpu().numpy()
- if output_image.shape[-1] == 1:
- output_image = np.concatenate((output_image,) * 3, axis=-1)
+ output_image = outputs[rendered_output_name]
+ output_image = (
+ colormaps.apply_colormap(
+ image=output_image,
+ colormap_options=colormap_options,
+ )
+ .cpu()
+ .numpy()
+ )
render_image.append(output_image)
render_image = np.concatenate(render_image, axis=1)
if output_format == "images":
@@ -143,9 +168,19 @@ def _render_trajectory_video(
)
writer.add_image(render_image)
+ table = Table(
+ title=None,
+ show_header=False,
+ box=box.MINIMAL,
+ title_style=style.Style(bold=True),
+ )
if output_format == "video":
if camera_type == CameraType.EQUIRECTANGULAR:
insert_spherical_metadata_into_file(output_filename)
+ table.add_row("Video", str(output_filename))
+ else:
+ table.add_row("Images", str(output_image_dir))
+ CONSOLE.print(Panel(table, title="[bold][green]:tada: Render Complete :tada:[/bold]", expand=False))
def insert_spherical_metadata_into_file(
@@ -280,10 +315,12 @@ class RenderTrajectory:
"""Number of interpolation steps between eval dataset cameras."""
eval_num_rays_per_chunk: Optional[int] = None
"""Specifies number of rays per chunk during eval."""
+ colormap_options: colormaps.ColormapOptions = colormaps.ColormapOptions()
+ """Colormap options."""
def main(self) -> None:
"""Main function."""
- _, pipeline, _ = eval_setup(
+ _, pipeline, _, _ = eval_setup(
self.load_config,
eval_num_rays_per_chunk=self.eval_num_rays_per_chunk,
test_mode="test" if self.traj in ["spiral", "interpolate"] else "inference",
@@ -332,6 +369,7 @@ class RenderTrajectory:
seconds=seconds,
output_format=self.output_format,
camera_type=camera_type,
+ colormap_options=self.colormap_options,
)
diff --git a/scripts/texture.py b/nerfstudio/scripts/texture.py
similarity index 75%
rename from scripts/texture.py
rename to nerfstudio/scripts/texture.py
index 702242ef2..98f26b846 100644
--- a/scripts/texture.py
+++ b/nerfstudio/scripts/texture.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
"""
Script to texture an existing mesh file.
"""
@@ -6,11 +20,10 @@ from __future__ import annotations
from dataclasses import dataclass
from pathlib import Path
-from typing import Optional
+from typing import Literal, Optional
import tyro
from rich.console import Console
-from typing_extensions import Literal
from nerfstudio.exporter import texture_utils
from nerfstudio.exporter.exporter_utils import get_mesh_from_filename
@@ -51,7 +64,7 @@ class TextureMesh:
mesh = get_mesh_from_filename(str(self.input_mesh_filename), target_num_faces=self.target_num_faces)
# load the Pipeline
- _, pipeline, _ = eval_setup(self.load_config, test_mode="inference")
+ _, pipeline, _, _ = eval_setup(self.load_config, test_mode="inference")
# texture the mesh with NeRF and export to a mesh.obj file
# and a material and texture file
diff --git a/scripts/train.py b/nerfstudio/scripts/train.py
similarity index 93%
rename from scripts/train.py
rename to nerfstudio/scripts/train.py
index bb3887133..84a3ebfd3 100644
--- a/scripts/train.py
+++ b/nerfstudio/scripts/train.py
@@ -1,3 +1,17 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
#!/usr/bin/env python
"""Train a radiance field with nerfstudio.
For real captures, we recommend using the [bright_yellow]nerfacto[/bright_yellow] model.
diff --git a/nerfstudio/scripts/viewer/__init__.py b/nerfstudio/scripts/viewer/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/scripts/viewer/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/nerfstudio/scripts/viewer/run_viewer.py b/nerfstudio/scripts/viewer/run_viewer.py
new file mode 100644
index 000000000..62abe8941
--- /dev/null
+++ b/nerfstudio/scripts/viewer/run_viewer.py
@@ -0,0 +1,122 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+#!/usr/bin/env python
+"""
+Starts viewer in eval mode.
+"""
+from __future__ import annotations
+
+import time
+from dataclasses import dataclass, field, fields
+from pathlib import Path
+
+import tyro
+from rich.console import Console
+
+from nerfstudio.configs.base_config import ViewerConfig
+from nerfstudio.engine.trainer import TrainerConfig
+from nerfstudio.pipelines.base_pipeline import Pipeline
+from nerfstudio.utils import writer
+from nerfstudio.utils.eval_utils import eval_setup
+from nerfstudio.viewer.server.viewer_state import ViewerState
+
+CONSOLE = Console(width=120)
+
+
+@dataclass
+class ViewerConfigWithoutNumRays(ViewerConfig):
+ """Configuration for viewer instantiation"""
+
+ num_rays_per_chunk: tyro.conf.Suppress[int] = -1
+
+ def as_viewer_config(self):
+ """Converts the instance to ViewerConfig"""
+ return ViewerConfig(**{x.name: getattr(self, x.name) for x in fields(self)})
+
+
+@dataclass
+class RunViewer:
+ """Load a checkpoint and start the viewer."""
+
+ load_config: Path
+ """Path to config YAML file."""
+ viewer: ViewerConfigWithoutNumRays = field(default_factory=ViewerConfigWithoutNumRays)
+ """Viewer configuration"""
+
+ def main(self) -> None:
+ """Main function."""
+ config, pipeline, _, step = eval_setup(
+ self.load_config,
+ eval_num_rays_per_chunk=None,
+ test_mode="test",
+ )
+ num_rays_per_chunk = config.viewer.num_rays_per_chunk
+ assert self.viewer.num_rays_per_chunk == -1
+ config.vis = "viewer"
+ config.viewer = self.viewer.as_viewer_config()
+ config.viewer.num_rays_per_chunk = num_rays_per_chunk
+
+ _start_viewer(config, pipeline, step)
+
+ def save_checkpoint(self, *args, **kwargs):
+ """
+ Mock method because we pass this instance to viewer_state.update_scene
+ """
+
+
+def _start_viewer(config: TrainerConfig, pipeline: Pipeline, step: int):
+ """Starts the viewer
+
+ Args:
+ config: Configuration of pipeline to load
+ pipeline: Pipeline instance of which to load weights
+ step: Step at which the pipeline was saved
+ """
+ base_dir = config.get_base_dir()
+ viewer_log_path = base_dir / config.viewer.relative_log_filename
+ viewer_state = ViewerState(
+ config.viewer,
+ log_filename=viewer_log_path,
+ datapath=pipeline.datamanager.get_datapath(),
+ pipeline=pipeline,
+ )
+ banner_messages = [f"Viewer at: {viewer_state.viewer_url}"]
+
+ # We don't need logging, but writer.GLOBAL_BUFFER needs to be populated
+ config.logging.local_writer.enable = False
+ writer.setup_local_writer(config.logging, max_iter=config.max_num_iterations, banner_messages=banner_messages)
+
+ assert viewer_state and pipeline.datamanager.train_dataset
+ viewer_state.init_scene(
+ dataset=pipeline.datamanager.train_dataset,
+ train_state="completed",
+ )
+ viewer_state.viser_server.set_training_state("completed")
+ viewer_state.update_scene(step=step)
+ while True:
+ time.sleep(0.01)
+
+
+def entrypoint():
+ """Entrypoint for use with pyproject scripts."""
+ tyro.extras.set_accent_color("bright_yellow")
+ tyro.cli(RunViewer).main()
+
+
+if __name__ == "__main__":
+ entrypoint()
+
+# For sphinx docs
+get_parser_fn = lambda: tyro.extras.get_parser(RunViewer) # noqa
diff --git a/nerfstudio/scripts/viewer/sync_viser_message_defs.py b/nerfstudio/scripts/viewer/sync_viser_message_defs.py
new file mode 100644
index 000000000..c693db288
--- /dev/null
+++ b/nerfstudio/scripts/viewer/sync_viser_message_defs.py
@@ -0,0 +1,68 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Generate viser message definitions for TypeScript, by parsing Python dataclasses."""
+import json
+import pathlib
+from datetime import datetime
+
+import tyro
+from viser.infra import generate_typescript_interfaces
+
+from nerfstudio.viewer.viser import NerfstudioMessage
+
+
+def main() -> None:
+ """Generate viser message definitions for TypeScript, by parsing Python dataclasses."""
+
+ # Generate typescript source.
+ defs = generate_typescript_interfaces(NerfstudioMessage)
+
+ # Write to file.
+ # Three parents from nerfstudio/scripts/viewer/sync_viser_message_defs.py:
+ # - nerfstudio/scripts/viewer/
+ # - nerfstudio/scripts/
+ # - nerfstudio/
+ target_path = pathlib.Path(__file__).absolute().parent.parent.parent / pathlib.Path(
+ "nerfstudio/viewer/app/src/modules/WebSocket/ViserMessages.tsx"
+ )
+ assert target_path.exists()
+
+ old_defs = target_path.read_text(encoding="utf_8")
+
+ if old_defs != defs:
+ target_path.write_text(defs, encoding="utf_8")
+
+ with open("nerfstudio/viewer/app/package.json", "r", encoding="utf_8") as f:
+ data = json.load(f)
+
+ now = datetime.now()
+ data["version"] = now.strftime("%y-%m-%d") + "-0"
+
+ with open("nerfstudio/viewer/app/package.json", "w", encoding="utf_8") as f:
+ json.dump(data, f, indent=2)
+ print(f"Wrote updates to {target_path}")
+ print(f"Current viewer version is now {data['version']}")
+ else:
+ print("No update to messages.")
+
+
+def entrypoint() -> None:
+ """Entrypoint for use with pyproject scripts."""
+ # All entrypoints must currently be tyro CLIs.
+ tyro.cli(main)
+
+
+if __name__ == "__main__":
+ entrypoint()
diff --git a/nerfstudio/utils/colormaps.py b/nerfstudio/utils/colormaps.py
index aae1b2a92..a9eb6fc8b 100644
--- a/nerfstudio/utils/colormaps.py
+++ b/nerfstudio/utils/colormaps.py
@@ -14,27 +14,91 @@
""" Helper functions for visualizing outputs """
-from typing import Optional
+from dataclasses import dataclass
+from typing import Literal, Optional
+import matplotlib
import torch
-from matplotlib import cm
from torchtyping import TensorType
from nerfstudio.utils import colors
+Colormaps = Literal["default", "turbo", "viridis", "magma", "inferno", "cividis"]
-def apply_colormap(image: TensorType["bs":..., 1], cmap="viridis") -> TensorType["bs":..., "rgb":3]:
+
+@dataclass
+class ColormapOptions:
+ """Options for colormap"""
+
+ colormap: Colormaps = "default"
+ """ The colormap to use """
+ normalize: bool = False
+ """ Whether to normalize the input tensor image """
+ colormap_min: float = 0
+ """ Minimum value for the output colormap """
+ colormap_max: float = 1
+ """ Maximum value for the output colormap """
+ invert: bool = False
+ """ Whether to invert the output colormap """
+
+
+def apply_colormap(
+ image: TensorType["bs":..., 1],
+ colormap_options: ColormapOptions = ColormapOptions(),
+ eps: float = 1e-9,
+) -> TensorType["bs":..., "rgb":3]:
+ """
+ Applies a colormap to a tensor image. Currently only supports 1 and 3 channel inputs
+
+ Args:
+ image: Input tensor image.
+ eps: Epsilon value for numerical stability.
+
+ Returns:
+ Tensor with the colormap applied.
+ """
+
+ # default for rgb images
+ if image.shape[-1] == 3:
+ return image
+
+ # rendering depth outputs
+ if image.shape[-1] == 1 and torch.is_floating_point(image):
+ output = image
+ if colormap_options.normalize:
+ output = output - torch.min(output)
+ output = output / (torch.max(output) + eps)
+ output = (
+ output * (colormap_options.colormap_max - colormap_options.colormap_min) + colormap_options.colormap_min
+ )
+ output = torch.clip(output, 0, 1)
+ if colormap_options.invert:
+ output = 1 - output
+ return apply_float_colormap(output, colormap=colormap_options.colormap)
+
+ # rendering boolean outputs
+ if image.dtype == torch.bool:
+ return apply_boolean_colormap(image)
+
+ raise NotImplementedError
+
+
+def apply_float_colormap(
+ image: TensorType["bs":..., 1], colormap: Colormaps = "viridis"
+) -> TensorType["bs":..., "rgb":3]:
"""Convert single channel to a color image.
Args:
image: Single channel image.
- cmap: Colormap for image.
+ colormap: Colormap for image.
Returns:
TensorType: Colored image with colors in [0, 1]
"""
+ if colormap == "default":
+ colormap = "turbo"
- colormap = cm.get_cmap(cmap)
+ colormap = matplotlib.colormaps[colormap]
colormap = torch.tensor(colormap.colors).to(image.device) # type: ignore
image = torch.nan_to_num(image, 0)
image_long = (image * 255).long()
@@ -50,7 +114,7 @@ def apply_depth_colormap(
accumulation: Optional[TensorType["bs":..., 1]] = None,
near_plane: Optional[float] = None,
far_plane: Optional[float] = None,
- cmap="turbo",
+ colormap_options: ColormapOptions = ColormapOptions(),
) -> TensorType["bs":..., "rgb":3]:
"""Converts a depth image to color for easier analysis.
@@ -59,7 +123,7 @@ def apply_depth_colormap(
accumulation: Ray accumulation used for masking vis.
near_plane: Closest depth to consider. If None, use min image value.
far_plane: Furthest depth to consider. If None, use max image value.
- cmap: Colormap to apply.
+ colormap: Colormap to apply.
Returns:
Colored depth image with colors in [0, 1]
@@ -72,7 +136,7 @@ def apply_depth_colormap(
depth = torch.clip(depth, 0, 1)
# depth = torch.nan_to_num(depth, nan=0.0) # TODO(ethan): remove this
- colored_image = apply_colormap(depth, cmap=cmap)
+ colored_image = apply_colormap(depth, colormap_options=colormap_options)
if accumulation is not None:
colored_image = colored_image * accumulation + (1 - accumulation)
diff --git a/nerfstudio/utils/decorators.py b/nerfstudio/utils/decorators.py
index 6f92ac679..356369f82 100644
--- a/nerfstudio/utils/decorators.py
+++ b/nerfstudio/utils/decorators.py
@@ -42,7 +42,7 @@ def check_profiler_enabled(func: Callable) -> Callable:
def wrapper(self, *args, **kwargs):
ret = None
- if self.config.enable_profiler:
+ if self.config.profiler != "none":
ret = func(self, *args, **kwargs)
return ret
diff --git a/nerfstudio/utils/eval_utils.py b/nerfstudio/utils/eval_utils.py
index 3431b20a3..5b35c33ff 100644
--- a/nerfstudio/utils/eval_utils.py
+++ b/nerfstudio/utils/eval_utils.py
@@ -20,12 +20,11 @@ from __future__ import annotations
import os
import sys
from pathlib import Path
-from typing import Optional, Tuple
+from typing import Literal, Optional, Tuple
import torch
import yaml
from rich.console import Console
-from typing_extensions import Literal
from nerfstudio.engine.trainer import TrainerConfig
from nerfstudio.pipelines.base_pipeline import Pipeline
@@ -33,13 +32,15 @@ from nerfstudio.pipelines.base_pipeline import Pipeline
CONSOLE = Console(width=120)
-def eval_load_checkpoint(config: TrainerConfig, pipeline: Pipeline) -> Path:
+def eval_load_checkpoint(config: TrainerConfig, pipeline: Pipeline) -> Tuple[Path, int]:
## TODO: ideally eventually want to get this to be the same as whatever is used to load train checkpoint too
"""Helper function to load checkpointed pipeline
Args:
config (DictConfig): Configuration of pipeline to load
pipeline (Pipeline): Pipeline instance of which to load weights
+ Returns:
+ A tuple of the path to the loaded checkpoint and the step at which it was saved.
"""
assert config.load_dir is not None
if config.load_step is None:
@@ -61,14 +62,14 @@ def eval_load_checkpoint(config: TrainerConfig, pipeline: Pipeline) -> Path:
loaded_state = torch.load(load_path, map_location="cpu")
pipeline.load_pipeline(loaded_state["pipeline"], loaded_state["step"])
CONSOLE.print(f":white_check_mark: Done loading checkpoint from {load_path}")
- return load_path
+ return load_path, load_step
def eval_setup(
config_path: Path,
eval_num_rays_per_chunk: Optional[int] = None,
test_mode: Literal["test", "val", "inference"] = "test",
-) -> Tuple[TrainerConfig, Pipeline, Path]:
+) -> Tuple[TrainerConfig, Pipeline, Path, int]:
"""Shared setup for loading a saved pipeline for evaluation.
Args:
@@ -81,7 +82,7 @@ def eval_setup(
Returns:
- Loaded config, pipeline module, and corresponding checkpoint.
+ Loaded config, pipeline module, corresponding checkpoint, and step
"""
# load save config
config = yaml.load(config_path.read_text(), Loader=yaml.Loader)
@@ -102,6 +103,6 @@ def eval_setup(
pipeline.eval()
# load checkpointed information
- checkpoint_path = eval_load_checkpoint(config, pipeline)
+ checkpoint_path, step = eval_load_checkpoint(config, pipeline)
- return config, pipeline, checkpoint_path
+ return config, pipeline, checkpoint_path, step
diff --git a/nerfstudio/utils/math.py b/nerfstudio/utils/math.py
index f54b6509a..924556597 100644
--- a/nerfstudio/utils/math.py
+++ b/nerfstudio/utils/math.py
@@ -15,13 +15,10 @@
""" Math Helper Functions """
from dataclasses import dataclass
-from typing import Tuple
+from typing import Literal, Tuple
import torch
from torchtyping import TensorType
-from typing_extensions import Literal
-
-_USE_NERFACC = True
def components_from_spherical_harmonics(levels: int, directions: TensorType[..., 3]) -> TensorType[..., "components"]:
@@ -198,7 +195,7 @@ def expected_sin(x_means: torch.Tensor, x_vars: torch.Tensor) -> torch.Tensor:
@torch.jit.script
-def _intersect_aabb(
+def intersect_aabb(
origins: torch.Tensor,
directions: torch.Tensor,
aabb: torch.Tensor,
@@ -238,40 +235,6 @@ def _intersect_aabb(
return t_min, t_max
-def intersect_aabb(
- origins: TensorType["N", 3],
- directions: TensorType["N", 3],
- aabb: TensorType[6],
-) -> Tuple[TensorType["N"], TensorType["N"]]:
- """
- Implementation of ray intersection with AABB box
-
- Args:
- origins: 3d positions
- directions: Normalized directions
- aabb: array of aabb box in the form of [x_min, y_min, z_min, x_max, y_max, z_max]
- max_bound: Maximum value of t_max
- invalid_value: Value to return in case of no intersection
-
- Returns:
- t_min, t_max - two tensors of shapes N representing distance of intersection from the origin.
- """
-
- global _USE_NERFACC # pylint: disable=global-statement
- if _USE_NERFACC:
- try:
- import nerfacc # pylint: disable=import-outside-toplevel
-
- t_min, t_max = nerfacc.ray_aabb_intersect(origins, directions, aabb)
- except: # pylint: disable=bare-except
- t_min, t_max = _intersect_aabb(origins, directions, aabb, max_bound=1e10, invalid_value=1e10)
- _USE_NERFACC = False
- else:
- t_min, t_max = _intersect_aabb(origins, directions, aabb, max_bound=1e10, invalid_value=1e10)
-
- return t_min, t_max
-
-
def safe_normalize(
vectors: TensorType["batch_dim":..., "N"],
eps: float = 1e-10,
diff --git a/nerfstudio/utils/profiler.py b/nerfstudio/utils/profiler.py
index c1fc96dcb..5d5599de6 100644
--- a/nerfstudio/utils/profiler.py
+++ b/nerfstudio/utils/profiler.py
@@ -17,10 +17,17 @@ Profiler base class and functionality
"""
from __future__ import annotations
+import functools
+import os
import time
-from typing import Callable
+import typing
+from collections import deque
+from contextlib import ContextDecorator, contextmanager
+from pathlib import Path
+from typing import Callable, Dict, List, Optional, Tuple, Union
from rich.console import Console
+from torch.profiler import ProfilerActivity, profile, record_function
from nerfstudio.configs import base_config as cfg
from nerfstudio.utils import comms
@@ -33,32 +40,124 @@ from nerfstudio.utils.decorators import (
CONSOLE = Console(width=120)
PROFILER = []
+PYTORCH_PROFILER = None
-def time_function(func: Callable) -> Callable:
- """Decorator: time a function call"""
+class time_function(ContextDecorator): # pylint: disable=invalid-name
+ """Decorator/Context manager: time a function call or a block of code"""
- def wrapper(*args, **kwargs):
- start = time.time()
- ret = func(*args, **kwargs)
+ def __init__(self, name: Union[str, Callable]):
+ # NOTE: This is a workaround for the fact that the __new__ method of a ContextDecorator
+ # is not picked up by VSCode intellisense
+ self.name: str = typing.cast(str, name)
+ self.start = None
+ self._profiler_contexts = deque()
+ self._function_call_args: Optional[Tuple[Tuple, Dict]] = None
+
+ def __new__(cls, func: Union[str, Callable]):
+ instance = super().__new__(cls)
+ if isinstance(func, str):
+ instance.__init__(func)
+ return instance
+ if callable(func):
+ instance.__init__(func.__qualname__)
+ return instance(func)
+ raise ValueError(f"Argument func of type {type(func)} is not a string or a callable.")
+
+ def __enter__(self):
+ self.start = time.time()
+ if PYTORCH_PROFILER is not None:
+ args, kwargs = tuple(), {}
+ if self._function_call_args is not None:
+ args, kwargs = self._function_call_args
+ ctx = PYTORCH_PROFILER.record_function(self.name, *args, **kwargs)
+ ctx.__enter__() # pylint: disable=no-member
+ self._profiler_contexts.append(ctx)
+ if self._function_call_args is None:
+ ctx = record_function(self.name)
+ ctx.__enter__()
+ self._profiler_contexts.append(ctx)
+
+ def __exit__(self, *args, **kwargs):
+ while self._profiler_contexts:
+ context = self._profiler_contexts.pop()
+ context.__exit__(*args, **kwargs)
if PROFILER:
- class_str = func.__qualname__
- PROFILER[0].update_time(class_str, start, time.time())
- return ret
+ PROFILER[0].update_time(self.name, self.start, time.time())
- return wrapper
+ def __call__(self, func: Callable):
+ @functools.wraps(func)
+ def inner(*args, **kwargs):
+ self._function_call_args = (args, kwargs)
+ with self:
+ out = func(*args, **kwargs)
+ self._function_call_args = None
+ return out
+
+ return inner
def flush_profiler(config: cfg.LoggingConfig):
"""Method that checks if profiler is enabled before flushing"""
- if config.enable_profiler and PROFILER:
+ if config.profiler != "none" and PROFILER:
PROFILER[0].print_profile()
-def setup_profiler(config: cfg.LoggingConfig):
+def setup_profiler(config: cfg.LoggingConfig, log_dir: Path):
"""Initialization of profilers"""
+ global PYTORCH_PROFILER # pylint: disable=global-statement
if comms.is_main_process():
PROFILER.append(Profiler(config))
+ if config.profiler == "pytorch":
+ PYTORCH_PROFILER = PytorchProfiler(log_dir)
+
+
+class PytorchProfiler: # pylint: disable=too-few-public-methods
+ """
+ Wrapper for Pytorch Profiler
+ """
+
+ def __init__(self, output_path: Path, trace_steps: Optional[List[int]] = None):
+ self.output_path = output_path / "profiler_traces"
+ if trace_steps is None:
+ # Some arbitrary steps which likely do not overlap with steps usually chosen to run callbacks
+ trace_steps = [12, 17]
+ self.trace_steps = trace_steps
+
+ @contextmanager
+ def record_function(self, function: str, *args, **_kwargs):
+ """
+ Context manager that records a function call and saves the trace to a json file.
+ Traced functions are: train_iteration, eval_iteration
+ """
+ if function.endswith("train_iteration") or function.endswith("eval_iteration"):
+ step = args[1]
+ assert isinstance(step, int)
+ assert len(args) == 2
+ stage = function.split(".")[-1].split("_")[0]
+ if step in self.trace_steps:
+ launch_kernel_blocking = self.trace_steps.index(step) % 2 == 0
+ backup_lb_var = ""
+ if launch_kernel_blocking:
+ backup_lb_var = os.environ.get("CUDA_LAUNCH_BLOCKING", "")
+ os.environ["CUDA_LAUNCH_BLOCKING"] = "1"
+ with profile(
+ activities=[ProfilerActivity.CPU, ProfilerActivity.CUDA],
+ record_shapes=True,
+ with_stack=True,
+ profile_memory=True,
+ ) as prof:
+ yield None
+ if launch_kernel_blocking:
+ os.environ["CUDA_LAUNCH_BLOCKING"] = backup_lb_var
+ self.output_path.mkdir(parents=True, exist_ok=True)
+ prof.export_chrome_trace(
+ str(self.output_path / f"trace_{stage}_{step}{'_blocking' if launch_kernel_blocking else ''}.json")
+ )
+ return
+ # Functions are recorded automatically
+ yield None
+ return
@decorate_all([check_profiler_enabled, check_main_thread])
diff --git a/nerfstudio/utils/writer.py b/nerfstudio/utils/writer.py
index 720d1d449..d996a7f36 100644
--- a/nerfstudio/utils/writer.py
+++ b/nerfstudio/utils/writer.py
@@ -18,6 +18,7 @@ Generic Writer class
from __future__ import annotations
import enum
+import os
from abc import abstractmethod
from pathlib import Path
from time import time
@@ -46,7 +47,6 @@ class EventName(enum.Enum):
ITER_TRAIN_TIME = "Train Iter (time)"
TOTAL_TRAIN_TIME = "Train Total (time)"
- ITER_VIS_TIME = "Viewer Rendering (time)"
ETA = "ETA (time)"
TRAIN_RAYS_PER_SEC = "Train Rays / Sec"
TEST_RAYS_PER_SEC = "Test Rays / Sec"
@@ -187,10 +187,22 @@ def setup_local_writer(config: cfg.LoggingConfig, max_iter: int, banner_messages
GLOBAL_BUFFER["events"] = {}
-@check_main_thread
-def setup_event_writer(is_wandb_enabled: bool, is_tensorboard_enabled: bool, log_dir: Path) -> None:
- """Initialization of all event writers specified in config
+def is_initialized():
+ """
+ Returns True after setup_local_writer was called
+ """
+ return "events" in GLOBAL_BUFFER
+
+@check_main_thread
+def setup_event_writer(
+ is_wandb_enabled: bool,
+ is_tensorboard_enabled: bool,
+ log_dir: Path,
+ experiment_name: str,
+ project_name: str = "nerfstudio-project",
+) -> None:
+ """Initialization of all event writers specified in config
Args:
config: configuration to instantiate loggers
max_iter: maximum number of train iterations
@@ -198,7 +210,7 @@ def setup_event_writer(is_wandb_enabled: bool, is_tensorboard_enabled: bool, log
"""
using_event_writer = False
if is_wandb_enabled:
- curr_writer = WandbWriter(log_dir=log_dir)
+ curr_writer = WandbWriter(log_dir=log_dir, experiment_name=experiment_name, project_name=project_name)
EVENT_WRITERS.append(curr_writer)
using_event_writer = True
if is_tensorboard_enabled:
@@ -268,7 +280,7 @@ class TimeWriter:
def __exit__(self, *args):
self.duration = time() - self.start
update_step = self.step is not None
- if self.write:
+ if self.write and is_initialized():
self.writer.put_time(
name=self.name,
duration=self.duration,
@@ -282,8 +294,13 @@ class TimeWriter:
class WandbWriter(Writer):
"""WandDB Writer Class"""
- def __init__(self, log_dir: Path):
- wandb.init(project="nerfstudio-project", dir=str(log_dir), reinit=True)
+ def __init__(self, log_dir: Path, experiment_name: str, project_name: str = "nerfstudio-project"):
+ wandb.init(
+ project=os.environ.get("WANDB_PROJECT", project_name),
+ dir=os.environ.get("WANDB_DIR", str(log_dir)),
+ name=os.environ.get("WANDB_NAME", experiment_name),
+ reinit=True,
+ )
def write_image(self, name: str, image: TensorType["H", "W", "C"], step: int) -> None:
image = torch.permute(image, (2, 0, 1))
diff --git a/nerfstudio/viewer/app/.eslintrc.json b/nerfstudio/viewer/app/.eslintrc.json
index ecb608b57..f219c3898 100644
--- a/nerfstudio/viewer/app/.eslintrc.json
+++ b/nerfstudio/viewer/app/.eslintrc.json
@@ -4,10 +4,12 @@
"es2021": true
},
"extends": [
+ "react-app",
"eslint:recommended",
"plugin:react/recommended",
"airbnb",
- "prettier"
+ "prettier",
+ "plugin:import/typescript"
],
"parser": "@typescript-eslint/parser",
"parserOptions": {
@@ -27,6 +29,20 @@
"prefer-destructuring": "off",
"react/destructuring-assignment": "off",
"react/prop-types": 0,
- "unused-imports/no-unused-imports-ts": 2
+ "react/jsx-filename-extension": [
+ 2,
+ { "extensions": [".js", ".jsx", ".ts", ".tsx"] }
+ ],
+ "unused-imports/no-unused-imports-ts": 2,
+ "import/extensions": [
+ "error",
+ "ignorePackages",
+ {
+ "js": "never",
+ "jsx": "never",
+ "ts": "never",
+ "tsx": "never"
+ }
+ ]
}
}
diff --git a/nerfstudio/viewer/app/package.json b/nerfstudio/viewer/app/package.json
index 3525ebd86..4d159c41e 100644
--- a/nerfstudio/viewer/app/package.json
+++ b/nerfstudio/viewer/app/package.json
@@ -1,7 +1,11 @@
{
"name": "viewer",
"homepage": ".",
+<<<<<<< HEAD
"version": "23-03-9-0",
+=======
+ "version": "23-05-01-0",
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
"private": true,
"dependencies": {
"@emotion/react": "^11.10.4",
@@ -15,6 +19,7 @@
"@testing-library/jest-dom": "^5.16.4",
"@testing-library/react": "^13.3.0",
"@testing-library/user-event": "^14.2.0",
+ "await-lock": "^2.2.2",
"camera-controls": "^1.37.2",
"classnames": "^2.3.1",
"dat.gui": "^0.7.9",
@@ -22,8 +27,10 @@
"eslint-config-prettier": "^8.5.0",
"eslint-plugin-unused-imports": "^2.0.0",
"leva": "^0.9.29",
+ "lodash": "^4.17.21",
"meshline": "^2.0.4",
"msgpack-lite": "^0.1.26",
+ "msgpackr": "^1.8.5",
"prop-types": "^15.8.1",
"re-resizable": "^6.9.9",
"react": "^18.1.0",
@@ -77,10 +84,17 @@
"eslint-plugin-react-hooks": "^4.3.0",
"prettier": "2.7.1",
"react-scripts": "^5.0.1",
- "typescript": "^4.7.3",
+ "typescript": "^5.0.3",
"wait-on": "^6.0.1"
},
"resolutions": {
- "nth-check": "^2.0.1"
+ "babel-loader": "^9.1.2",
+ "json5": "^2.2.3",
+ "loader-utils": "^3.2.1",
+ "nth-check": "^2.0.1",
+ "@pmmmwh/react-refresh-webpack-plugin": "^0.5.10",
+ "recursive-readdir": "^2.2.3",
+ "resolve-url-loader": "^5.0.0",
+ "yaml": "^2.2.2"
}
-}
+}
\ No newline at end of file
diff --git a/nerfstudio/viewer/app/run_deploy.py b/nerfstudio/viewer/app/run_deploy.py
index 03fd86465..99d5f47a9 100644
--- a/nerfstudio/viewer/app/run_deploy.py
+++ b/nerfstudio/viewer/app/run_deploy.py
@@ -119,7 +119,6 @@ def main(
# update the symlink of latest
if branch_name == "main":
-
# move the build folder to the correct location
run_cmd(f"""ssh {host} 'rm -rf {remote_folder}/{version}'""")
run_cmd(f"""ssh {host} 'cp -R /home/eweb0124/build {remote_folder}/{version}'""")
diff --git a/nerfstudio/viewer/app/src/App.jsx b/nerfstudio/viewer/app/src/App.jsx
index 1d2987107..fd42a37f9 100644
--- a/nerfstudio/viewer/app/src/App.jsx
+++ b/nerfstudio/viewer/app/src/App.jsx
@@ -1,14 +1,11 @@
import { CssBaseline, ThemeProvider } from '@mui/material';
import React from 'react';
-import {
- SceneTreeWebSocketListener,
- get_scene_tree,
-} from './modules/Scene/Scene';
+import { get_scene_tree } from './modules/Scene/Scene';
import Banner from './modules/Banner';
import { BasicTabs } from './modules/SidePanel/SidePanel';
import ViewerWindow from './modules/ViewerWindow/ViewerWindow';
-import { appTheme } from './themes/theme.ts';
+import { appTheme } from './themes/theme';
export default function App() {
// The scene tree won't rerender but it will listen to changes
@@ -20,8 +17,6 @@ export default function App() {
- {/* Listens for websocket 'write' messages and updates the redux store. */}
-
{/* The banner at the top of the page. */}

 +
 -
 -
 +
 +
 -
- - Note: This may not give ideal results if the mesh is not very clear or occludes other objects in the scene. If this is the case, you can hide the mesh from the render instead by clicking the camera button in the Outliner next to its name.
-
 + - In object properties, select "Shadow Catcher". This makes the representation invisible in the render, but all shadows cast on it will render. You may have to switch to the cycles renderer to see the shadow catcher option.
+
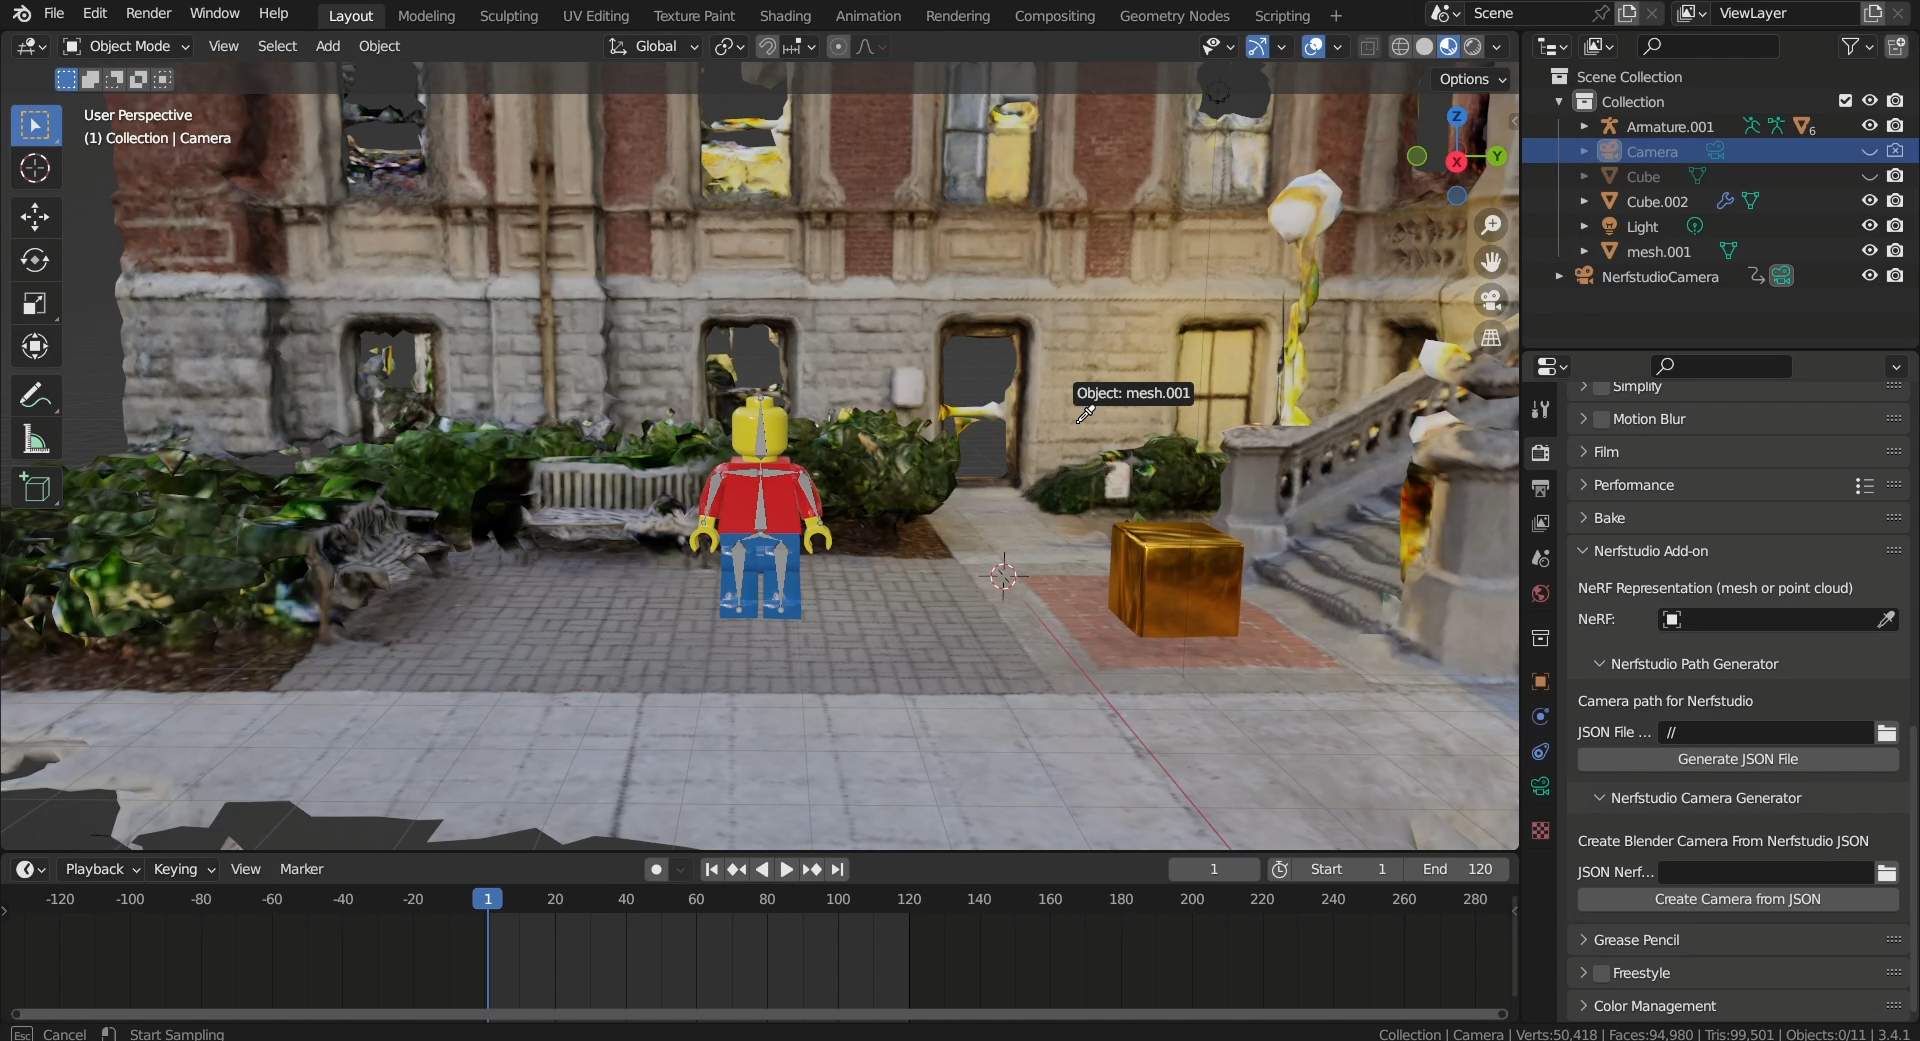 -
+
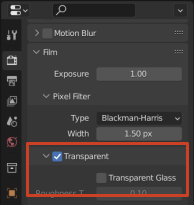 +
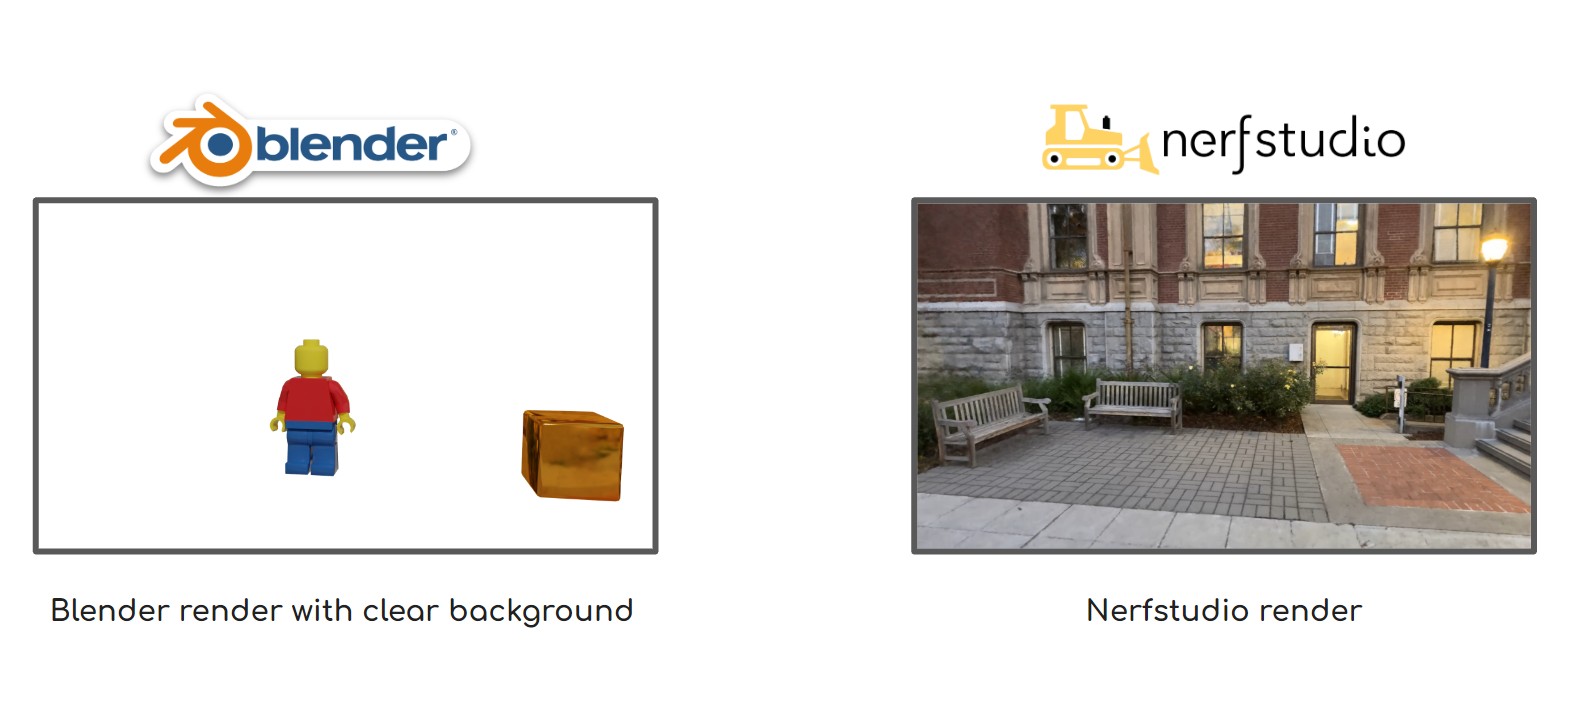 +
 +- You can also apply an environment texture to the Blender scene by using Nerfstudio to render an equirectangular image (360 image) of the NeRF from a place in the scene.
+- The settings for the Blender equirectangular camera are: "Panoramic" camera type and panorama type of "Equirectangular".
+
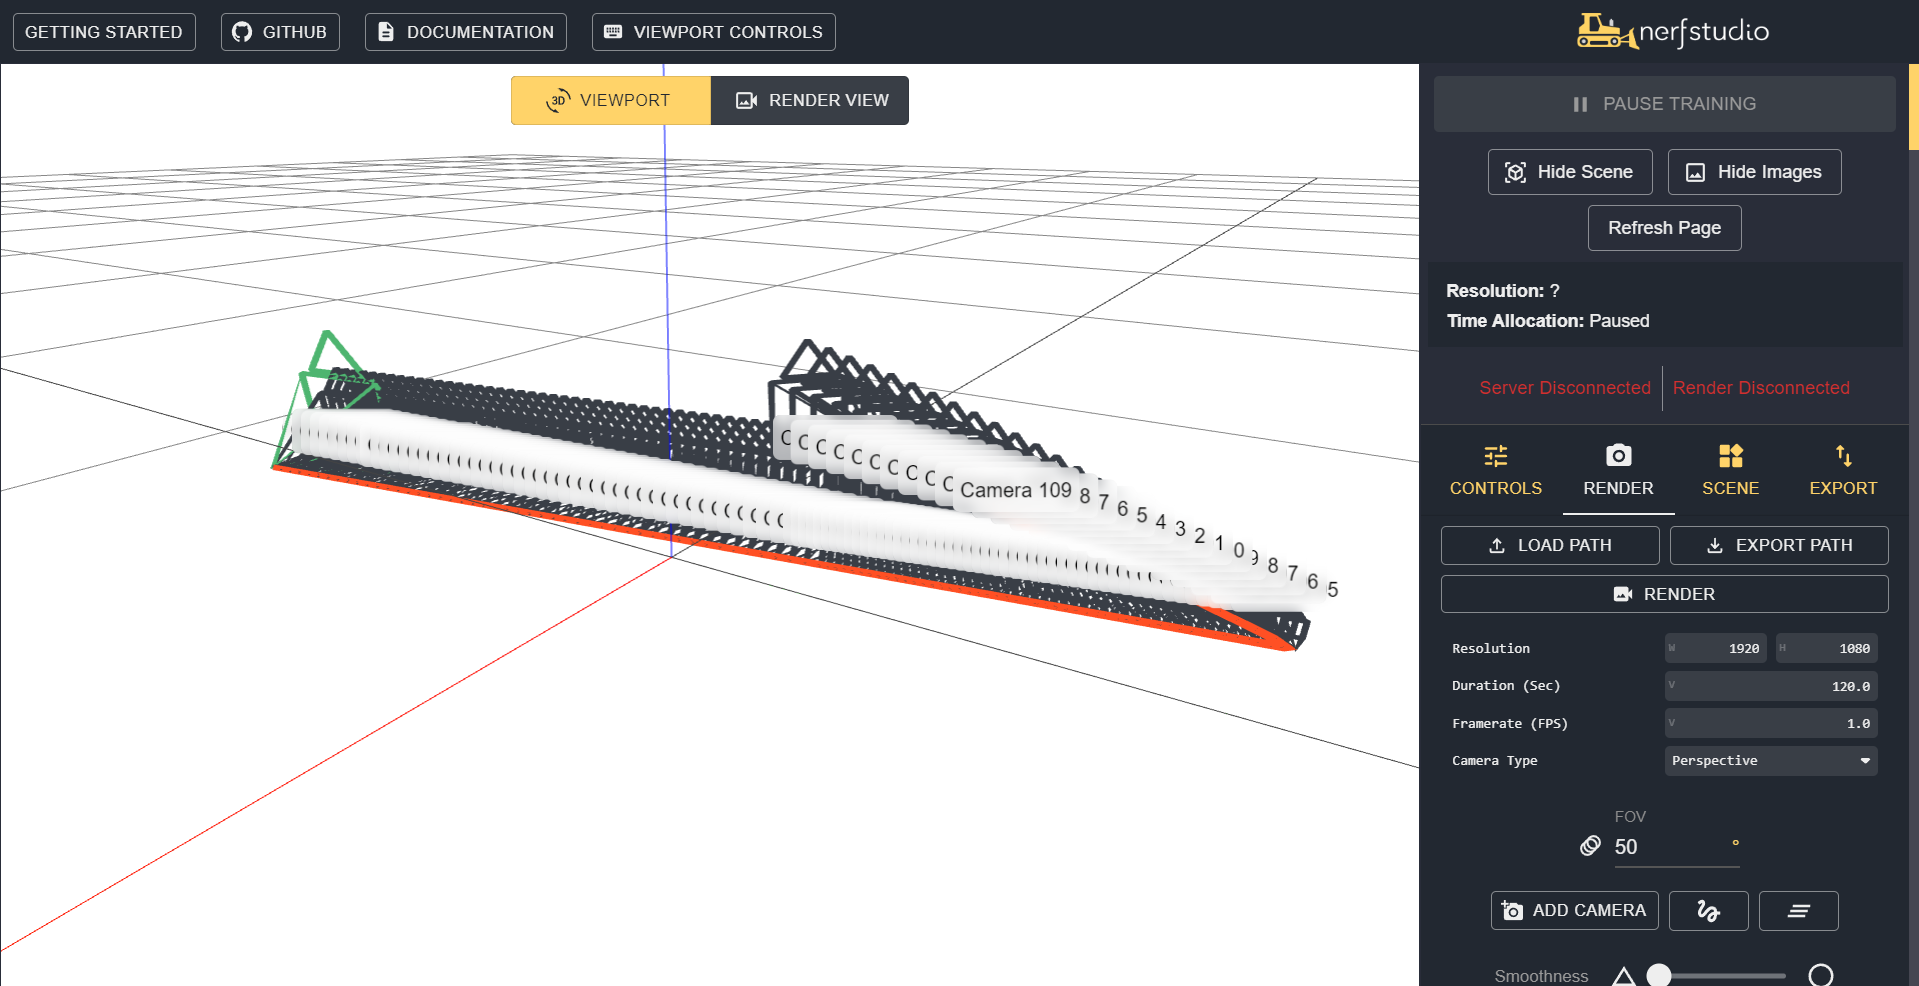 +
 -
1. Expand the "Nerfstudio Camera Generator" tab in the panel. After inputting the NeRF representation, select the JSON Nerfstudio file and click "Create Camera from JSON"
2. A new camera named "NerfstudioCamera" should appear in the viewport with the camera path and FOV of the input file. This camera's type will match the Nerfstudio input file, except fisheye cameras.
@@ -103,13 +125,97 @@ First install [Blender](https://www.blender.org/). The python file add-on can be
- Scale of the camera is not keyframed from the Nerfstudio camera path.
- This newly created camera has a sensor fit of "Vertical"
+## Compositing NeRF Objects in NeRF Environments
+
+You can composite NeRF objects into a scene with a NeRF background by rendering the cropped NeRF object along with an accumulation render as an alpha mask and compositing that over the background NeRF render.
+
+
 +
 +
 +
 +
 +
 +
 +
 +
 +
+### LERF Optimization
+
+LERF optimizes a dense, multi-scale language 3D field by volume rendering CLIP embeddings along training rays, supervising these embeddings with multi-scale CLIP features across multi-view training images.
+
+Inspired by Distilled Feature Fields (DFF), we use DINO features to regularize CLIP features. This leads to qualitative improvements in object boundaries, as CLIP embeddings in 3D can be sensitive to floaters and regions with few views.
+
+After optimization, LERF can extract 3D relevancy maps for language queries interactively in real-time.
+
+
 +
+### Visualizing relevancy for text queries
+
+Set the "Output Render" type to `relevancy_0`, and enter the text query in the "LERF Positives" textbox (see image). The output render will show the 3D relevancy map for the query. View the [project page](https://lerf.io) for more examples and details about the relevancy map normalization.
+
+
 +
 +<<<<<<< HEAD
This obscene mesh of human is obviously not helpful in training a nerf so we can remove it by cropping the bottom 20% of the image. This can be done by using the `--crop-factor 0 0.2 0 0` argument.
+=======
+The pixels representing the distorted hand and head are obviously not useful in training a nerf so we can remove it by cropping the bottom 20% of the image. This can be done by using the `--crop-factor 0 0.2 0 0` argument.
+
+If cropping only needs to be done from the bottom, you can use the `--crop-bottom [num]` argument which would be the same as doing `--crop-factor 0.0 [num] 0.0 0.0`
+>>>>>>> b1ddb9e695b789fae47e0f760a5c7f59f25af0bb
diff --git a/docs/quickstart/export_geometry.md b/docs/quickstart/export_geometry.md
index 28d29fc54..2ffd51895 100644
--- a/docs/quickstart/export_geometry.md
+++ b/docs/quickstart/export_geometry.md
@@ -19,7 +19,6 @@ Poisson surface reconstruction gives the highest quality meshes. See the steps b
> **Note:**
> This will only work with a Model that computes or predicts normals, e.g., nerfacto.
-
1. Train nerfacto with network settings that predict normals.
```bash
@@ -51,7 +50,7 @@ ns-export --help
Say you want to simplify and/or smooth a mesh offline, and then you want to texture it with NeRF. You can do that with the following command. It will work for any mesh filetypes that [PyMeshLab](https://pymeshlab.readthedocs.io/en/latest/) can support, for example a `.ply`.
```python
-python scripts/texture.py --load-config CONFIG.yml --input-mesh-filename FILENAME --output-dir OUTPUT_DIR
+python nerfstudio/scripts/texture.py --load-config CONFIG.yml --input-mesh-filename FILENAME --output-dir OUTPUT_DIR
```
## Dependencies
diff --git a/docs/quickstart/first_nerf.md b/docs/quickstart/first_nerf.md
index 73e40a9d8..1d71fac49 100644
--- a/docs/quickstart/first_nerf.md
+++ b/docs/quickstart/first_nerf.md
@@ -38,8 +38,6 @@ It is possible to load a pretrained model by running
ns-train nerfacto --data data/nerfstudio/poster --load-dir {outputs/.../nerfstudio_models}
```
-This will automatically start training. If you do not want it to train, add `--viewer.start-train False` to your training command.
-
## Visualize existing run
Given a pretrained model checkpoint, you can start the viewer by running
@@ -98,9 +96,9 @@ ns-train nerfacto