diff --git a/docs/quickstart/custom_dataset.md b/docs/quickstart/custom_dataset.md
index ebd77a5f5..decc968cf 100644
--- a/docs/quickstart/custom_dataset.md
+++ b/docs/quickstart/custom_dataset.md
@@ -346,3 +346,49 @@ The `crop-factor` argument is optional but often very helpful. This is because e
The pixels representing the distorted hand and head are obviously not useful in training a nerf so we can remove it by cropping the bottom 20% of the image. This can be done by using the `--crop-factor 0 0.2 0 0` argument.
If cropping only needs to be done from the bottom, you can use the `--crop-bottom [num]` argument which would be the same as doing `--crop-factor 0.0 [num] 0.0 0.0`
+
+## 🥽 Render Omni-directional Stereo (360 VR)
+
+Stereo equirectangular rendering for VR video is supported as omni-directional stereo video and image rendering. This outputs two equirectangular renders vertically stacked, one for each eye. Omni-directional stereo (ODS) is a method to render VR 3D 360 videos, and may introduce slight depth distortions for close objects. For additional information on how ODS works, refer to this [writeup](https://developers.google.com/vr/jump/rendering-ods-content.pdf).
+
+
+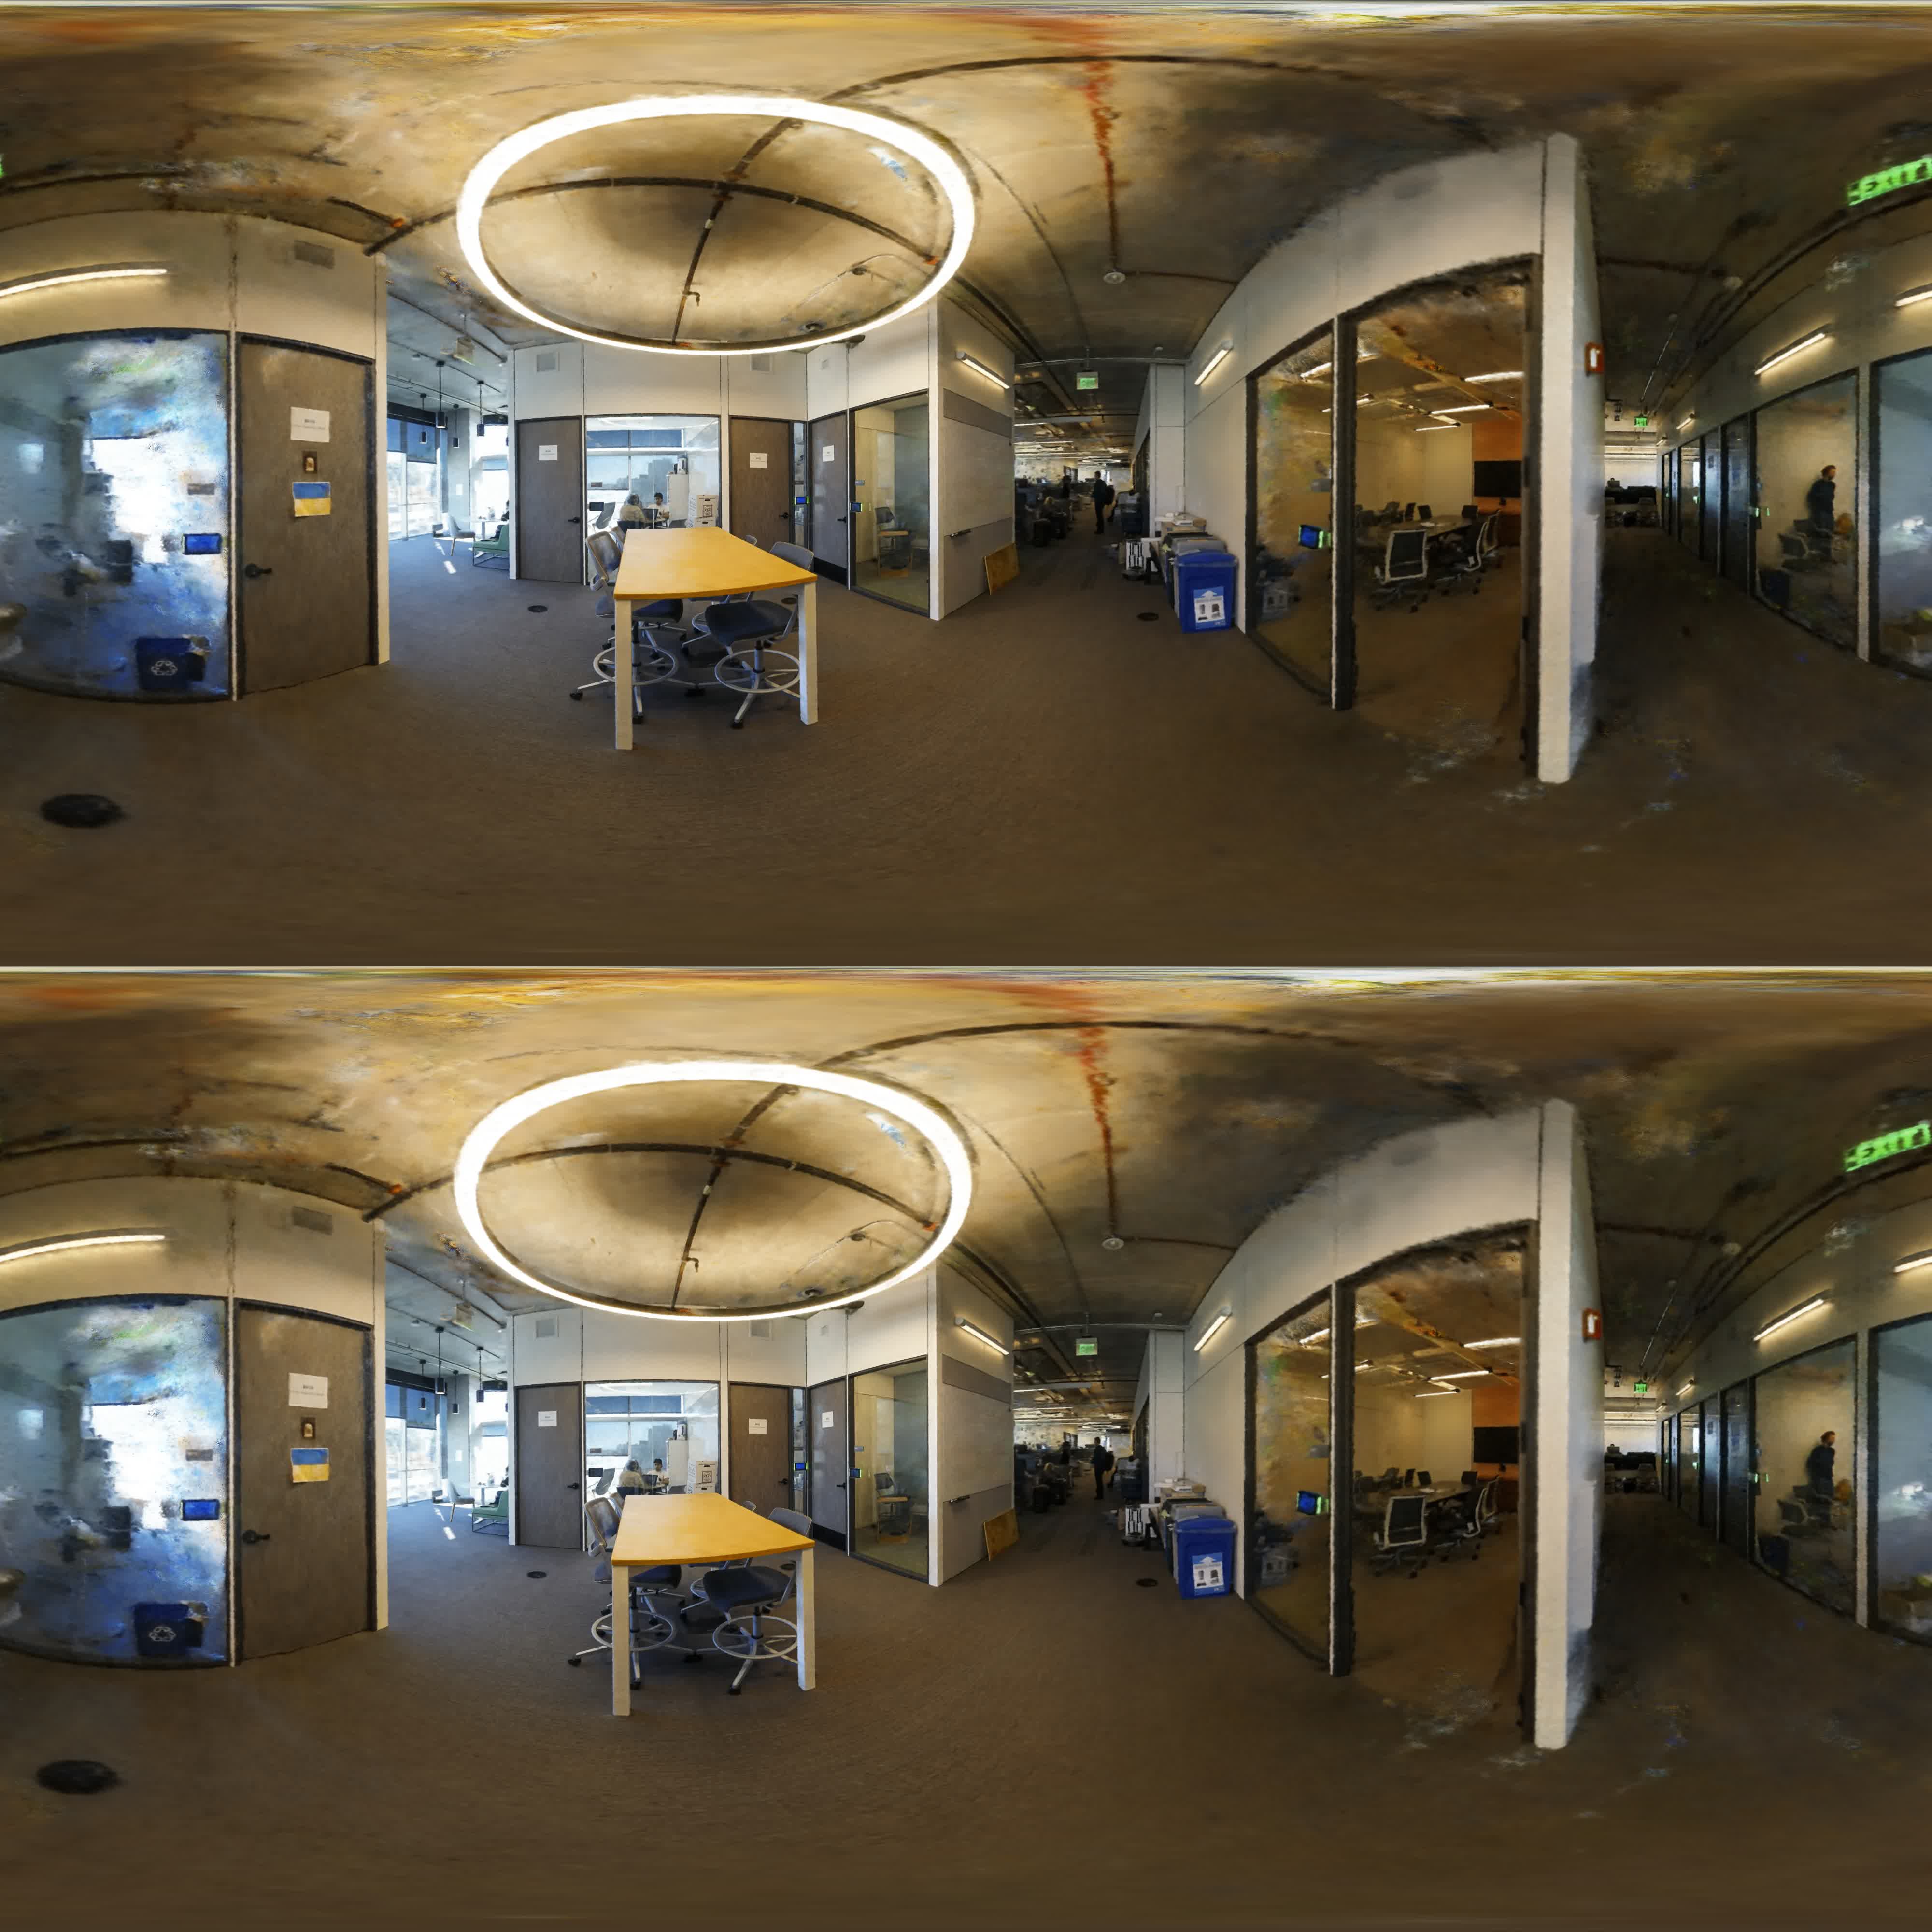 +
+
+To render in ODS it is essential to adjust the NeRF to have an approximately true-to-life real world scale (adjustable in the camera path) to ensure that the scene depth and IPD (distance between the eyes) is appropriate for the render to be viewable in VR. You can adjust the scene scale with the [Blender Add-on](https://docs.nerf.studio/en/latest/extensions/blender_addon.html) by appropriately scaling a point cloud representation of the NeRF.
+Results may be unviewable if the scale is not set appropriately. The IPD is set at 64mm by default but only is accurate when the NeRF scene is true to scale.
+
+For good quality renders, it is recommended to render at 4096x2048 per eye, or 2048x1024 per eye. Render resolutions must be specified in the camera path in a 2:1 aspect ratio. The final stacked render output will automatically be constructed as 1:1.
+
+:::{admonition} Note
+:class: info
+If you are rendering an image sequence, it is recommended to render as png instead of jpeg, since the png will appear clearer. However, file sizes can be significantly larger with png.
+:::
+
+To render with the ODS camera:
+1. Use the Nerfstudio Blender Add-on to set the scale of the NeRF scene and create the camera path
+ - Export a point cloud representation of the NeRF
+ - Import the point cloud representation in Blender and enable the Blender Add-on
+ - Create a reference object such as a cube which may be 1x1x1 meter. You could also create a cylinder and scale it to an appropriate height of a viewer.
+ - Now scale the point cloud representation accordingly to match the reference object. This is to ensure that the NeRF scene is scaled as close to real life.
+ - To place the camera at the correct height from the ground in the scene, you create a cylinder representing the viewer vertically scaled to the viewer’s height, and place the camera at eye level.
+ - Animate the camera movement as needed
+ - Create the camera path JSON file with the Nerfstudio Blender Add-on
+2. Edit the JSON camera path file
+ - Open the camera path JSON file and specify the `camera_type` as `omnidirectional`
+ - Specify the `render_height` and `render_width` to the resolution of a single eye. The width:height aspect ratio must be 2:1. Recommended resolutions are 4096x2048 or 2048x1024.
+ - Save the camera path and render the NeRF
+
+
 +
+
+:::{admonition} Note
+:class: info
+If the depth of the scene is unviewable and looks too close or expanded when viewing the render in VR, the scale of the NeRF may be set too small. If there is almost no discernible depth, the scale of the NeRF may be too large. Getting the right scale may take some experimentation, so it is recommended to either render at a much lower resolution or just one frame to ensure the depth and render is viewable in the VR headset.
+:::
+
+### Additional Notes
+- Rendering with ODS can take significantly longer than traditional renders due to higher resolutions and needing to render a left and right eye view for each frame. Render times may grow exponentially with larger resolutions.
+- When rendering ODS content, Nerfstudio will first render the left eye, then the right eye, and finally vertically stack the renders. During this process, Nerfstudio will create a temporary folder to store the left and right eye renders and delete this folder once the final renders are stacked.
+- If rendering content where the camera is stationary for many frames, it is recommended to only render once at that position and extend the time in a video editor since ODS renders can take a lot of time to render.
+- It is recommended to render a preliminary render at a much lower resolution or frame rate to test and ensure that the depth and camera position look accurate in VR.
diff --git a/nerfstudio/cameras/camera_paths.py b/nerfstudio/cameras/camera_paths.py
index dc3d3dfa7..50d417f92 100644
--- a/nerfstudio/cameras/camera_paths.py
+++ b/nerfstudio/cameras/camera_paths.py
@@ -139,6 +139,8 @@ def get_path_from_json(camera_path: Dict[str, Any]) -> Cameras:
camera_type = CameraType.FISHEYE
elif camera_path["camera_type"] == "equirectangular":
camera_type = CameraType.EQUIRECTANGULAR
+ elif camera_path["camera_type"].lower() == "omnidirectional":
+ camera_type = CameraType.OMNIDIRECTIONALSTEREO_L
else:
camera_type = CameraType.PERSPECTIVE
@@ -149,7 +151,11 @@ def get_path_from_json(camera_path: Dict[str, Any]) -> Cameras:
# pose
c2w = torch.tensor(camera["camera_to_world"]).view(4, 4)[:3]
c2ws.append(c2w)
- if camera_type == CameraType.EQUIRECTANGULAR:
+ if (
+ camera_type == CameraType.EQUIRECTANGULAR
+ or camera_type == CameraType.OMNIDIRECTIONALSTEREO_L
+ or camera_type == CameraType.OMNIDIRECTIONALSTEREO_R
+ ):
fxs.append(image_width / 2)
fys.append(image_height)
else:
diff --git a/nerfstudio/cameras/cameras.py b/nerfstudio/cameras/cameras.py
index 33ca498aa..51d299882 100644
--- a/nerfstudio/cameras/cameras.py
+++ b/nerfstudio/cameras/cameras.py
@@ -19,7 +19,7 @@ import base64
import math
from dataclasses import dataclass
from enum import Enum, auto
-from typing import Dict, List, Optional, Tuple, Union
+from typing import Dict, List, Literal, Optional, Tuple, Union
import cv2
import torch
@@ -44,6 +44,8 @@ class CameraType(Enum):
PERSPECTIVE = auto()
FISHEYE = auto()
EQUIRECTANGULAR = auto()
+ OMNIDIRECTIONALSTEREO_L = auto()
+ OMNIDIRECTIONALSTEREO_R = auto()
CAMERA_MODEL_TO_TYPE = {
@@ -54,6 +56,8 @@ CAMERA_MODEL_TO_TYPE = {
"OPENCV": CameraType.PERSPECTIVE,
"OPENCV_FISHEYE": CameraType.FISHEYE,
"EQUIRECTANGULAR": CameraType.EQUIRECTANGULAR,
+ "OMNIDIRECTIONALSTEREO_L": CameraType.OMNIDIRECTIONALSTEREO_L,
+ "OMNIDIRECTIONALSTEREO_R": CameraType.OMNIDIRECTIONALSTEREO_R,
}
@@ -643,48 +647,120 @@ class Cameras(TensorDataclass):
# directions_stack[2] is the direction for ray in camera coordinates offset by 1 in y
cam_types = torch.unique(self.camera_type, sorted=False)
directions_stack = torch.empty((3,) + num_rays_shape + (3,), device=self.device)
- if CameraType.PERSPECTIVE.value in cam_types:
- mask = (self.camera_type[true_indices] == CameraType.PERSPECTIVE.value).squeeze(-1) # (num_rays)
+
+ c2w = self.camera_to_worlds[true_indices]
+ assert c2w.shape == num_rays_shape + (3, 4)
+
+ def _compute_rays_for_omnidirectional_stereo(
+ eye: Literal["left", "right"]
+ ) -> Tuple[Float[Tensor, "num_rays_shape 3"], Float[Tensor, "3 num_rays_shape 3"]]:
+ """Compute the rays for an omnidirectional stereo camera
+
+ Args:
+ eye: Which eye to compute rays for.
+
+ Returns:
+ A tuple containing the origins and the directions of the rays.
+ """
+ # Directions calculated similarly to equirectangular
+ ods_cam_type = (
+ CameraType.OMNIDIRECTIONALSTEREO_R.value if eye == "right" else CameraType.OMNIDIRECTIONALSTEREO_L.value
+ )
+ mask = (self.camera_type[true_indices] == ods_cam_type).squeeze(-1)
mask = torch.stack([mask, mask, mask], dim=0)
- directions_stack[..., 0][mask] = torch.masked_select(coord_stack[..., 0], mask).float()
- directions_stack[..., 1][mask] = torch.masked_select(coord_stack[..., 1], mask).float()
- directions_stack[..., 2][mask] = -1.0
-
- if CameraType.FISHEYE.value in cam_types:
- mask = (self.camera_type[true_indices] == CameraType.FISHEYE.value).squeeze(-1) # (num_rays)
- mask = torch.stack([mask, mask, mask], dim=0)
-
- theta = torch.sqrt(torch.sum(coord_stack**2, dim=-1))
- theta = torch.clip(theta, 0.0, math.pi)
-
- sin_theta = torch.sin(theta)
-
- directions_stack[..., 0][mask] = torch.masked_select(coord_stack[..., 0] * sin_theta / theta, mask).float()
- directions_stack[..., 1][mask] = torch.masked_select(coord_stack[..., 1] * sin_theta / theta, mask).float()
- directions_stack[..., 2][mask] = -torch.masked_select(torch.cos(theta), mask).float()
-
- if CameraType.EQUIRECTANGULAR.value in cam_types:
- mask = (self.camera_type[true_indices] == CameraType.EQUIRECTANGULAR.value).squeeze(-1) # (num_rays)
- mask = torch.stack([mask, mask, mask], dim=0)
-
- # For equirect, fx = fy = height = width/2
- # Then coord[..., 0] goes from -1 to 1 and coord[..., 1] goes from -1/2 to 1/2
- theta = -torch.pi * coord_stack[..., 0] # minus sign for right-handed
+ theta = -torch.pi * coord_stack[..., 0]
phi = torch.pi * (0.5 - coord_stack[..., 1])
- # use spherical in local camera coordinates (+y up, x=0 and z<0 is theta=0)
+
directions_stack[..., 0][mask] = torch.masked_select(-torch.sin(theta) * torch.sin(phi), mask).float()
directions_stack[..., 1][mask] = torch.masked_select(torch.cos(phi), mask).float()
directions_stack[..., 2][mask] = torch.masked_select(-torch.cos(theta) * torch.sin(phi), mask).float()
- for value in cam_types:
- if value not in [CameraType.PERSPECTIVE.value, CameraType.FISHEYE.value, CameraType.EQUIRECTANGULAR.value]:
- raise ValueError(f"Camera type {value} not supported.")
+ vr_ipd = 0.064 # IPD in meters (note: scale of NeRF must be true to life and can be adjusted with the Blender add-on)
+ isRightEye = 1 if eye == "right" else -1
+
+ # find ODS camera position
+ c2w = self.camera_to_worlds[true_indices]
+ assert c2w.shape == num_rays_shape + (3, 4)
+ transposedC2W = c2w[0][0].t()
+ ods_cam_position = transposedC2W[3].repeat(c2w.shape[1], 1)
+
+ rotation = c2w[..., :3, :3]
+
+ ods_theta = -torch.pi * ((x - cx) / fx)[0]
+
+ # local axes of ODS camera
+ ods_x_axis = torch.tensor([1, 0, 0], device=c2w.device)
+ ods_z_axis = torch.tensor([0, 0, -1], device=c2w.device)
+
+ # circle of ODS ray origins
+ ods_origins_circle = (
+ ods_cam_position
+ + isRightEye * (vr_ipd / 2.0) * (ods_x_axis.repeat(c2w.shape[1], 1)) * (torch.cos(ods_theta))[:, None]
+ + isRightEye * (vr_ipd / 2.0) * (ods_z_axis.repeat(c2w.shape[1], 1)) * (torch.sin(ods_theta))[:, None]
+ )
+
+ # rotate origins to match the camera rotation
+ for i in range(ods_origins_circle.shape[0]):
+ ods_origins_circle[i] = rotation[0][0] @ ods_origins_circle[i] + ods_cam_position[0]
+ ods_origins_circle = ods_origins_circle.unsqueeze(0).repeat(c2w.shape[0], 1, 1)
+
+ # assign final camera origins
+ c2w[..., :3, 3] = ods_origins_circle
+
+ return ods_origins_circle, directions_stack
+
+ for cam in cam_types:
+ if CameraType.PERSPECTIVE.value in cam_types:
+ mask = (self.camera_type[true_indices] == CameraType.PERSPECTIVE.value).squeeze(-1) # (num_rays)
+ mask = torch.stack([mask, mask, mask], dim=0)
+ directions_stack[..., 0][mask] = torch.masked_select(coord_stack[..., 0], mask).float()
+ directions_stack[..., 1][mask] = torch.masked_select(coord_stack[..., 1], mask).float()
+ directions_stack[..., 2][mask] = -1.0
+
+ elif CameraType.FISHEYE.value in cam_types:
+ mask = (self.camera_type[true_indices] == CameraType.FISHEYE.value).squeeze(-1) # (num_rays)
+ mask = torch.stack([mask, mask, mask], dim=0)
+
+ theta = torch.sqrt(torch.sum(coord_stack**2, dim=-1))
+ theta = torch.clip(theta, 0.0, math.pi)
+
+ sin_theta = torch.sin(theta)
+
+ directions_stack[..., 0][mask] = torch.masked_select(
+ coord_stack[..., 0] * sin_theta / theta, mask
+ ).float()
+ directions_stack[..., 1][mask] = torch.masked_select(
+ coord_stack[..., 1] * sin_theta / theta, mask
+ ).float()
+ directions_stack[..., 2][mask] = -torch.masked_select(torch.cos(theta), mask).float()
+
+ elif CameraType.EQUIRECTANGULAR.value in cam_types:
+ mask = (self.camera_type[true_indices] == CameraType.EQUIRECTANGULAR.value).squeeze(-1) # (num_rays)
+ mask = torch.stack([mask, mask, mask], dim=0)
+
+ # For equirect, fx = fy = height = width/2
+ # Then coord[..., 0] goes from -1 to 1 and coord[..., 1] goes from -1/2 to 1/2
+ theta = -torch.pi * coord_stack[..., 0] # minus sign for right-handed
+ phi = torch.pi * (0.5 - coord_stack[..., 1])
+ # use spherical in local camera coordinates (+y up, x=0 and z<0 is theta=0)
+ directions_stack[..., 0][mask] = torch.masked_select(-torch.sin(theta) * torch.sin(phi), mask).float()
+ directions_stack[..., 1][mask] = torch.masked_select(torch.cos(phi), mask).float()
+ directions_stack[..., 2][mask] = torch.masked_select(-torch.cos(theta) * torch.sin(phi), mask).float()
+
+ elif CameraType.OMNIDIRECTIONALSTEREO_L.value in cam_types:
+ ods_origins_circle, directions_stack = _compute_rays_for_omnidirectional_stereo("left")
+ # assign final camera origins
+ c2w[..., :3, 3] = ods_origins_circle
+
+ elif CameraType.OMNIDIRECTIONALSTEREO_R.value in cam_types:
+ ods_origins_circle, directions_stack = _compute_rays_for_omnidirectional_stereo("right")
+ # assign final camera origins
+ c2w[..., :3, 3] = ods_origins_circle
+ else:
+ raise ValueError(f"Camera type {cam} not supported.")
assert directions_stack.shape == (3,) + num_rays_shape + (3,)
- c2w = self.camera_to_worlds[true_indices]
- assert c2w.shape == num_rays_shape + (3, 4)
-
if camera_opt_to_camera is not None:
c2w = pose_utils.multiply(c2w, camera_opt_to_camera)
rotation = c2w[..., :3, :3] # (..., 3, 3)
diff --git a/nerfstudio/configs/base_config.py b/nerfstudio/configs/base_config.py
index e167ce567..4f1d82238 100644
--- a/nerfstudio/configs/base_config.py
+++ b/nerfstudio/configs/base_config.py
@@ -64,14 +64,16 @@ class MachineConfig(PrintableConfig):
seed: int = 42
"""random seed initialization"""
- num_gpus: int = 1
- """total number of gpus available for train/eval"""
+ num_devices: int = 1
+ """total number of devices (e.g., gpus) available for train/eval"""
num_machines: int = 1
"""total number of distributed machines available (for DDP)"""
machine_rank: int = 0
"""current machine's rank (for DDP)"""
dist_url: str = "auto"
"""distributed connection point (for DDP)"""
+ device_type: Literal["cpu", "cuda", "mps"] = "cuda"
+ """device type to use for training"""
@dataclass
diff --git a/nerfstudio/engine/trainer.py b/nerfstudio/engine/trainer.py
index e856c32ba..e587e373f 100644
--- a/nerfstudio/engine/trainer.py
+++ b/nerfstudio/engine/trainer.py
@@ -33,25 +33,17 @@ from rich.table import Table
from torch.cuda.amp.grad_scaler import GradScaler
from nerfstudio.configs.experiment_config import ExperimentConfig
-from nerfstudio.engine.callbacks import (
- TrainingCallback,
- TrainingCallbackAttributes,
- TrainingCallbackLocation,
-)
+from nerfstudio.engine.callbacks import TrainingCallback, TrainingCallbackAttributes, TrainingCallbackLocation
from nerfstudio.data.datamanagers.base_datamanager import VanillaDataManager
from nerfstudio.engine.optimizers import Optimizers
from nerfstudio.pipelines.base_pipeline import VanillaPipeline
from nerfstudio.utils import profiler, writer
-from nerfstudio.utils.decorators import (
- check_eval_enabled,
- check_main_thread,
- check_viewer_enabled,
-)
+from nerfstudio.utils.decorators import check_eval_enabled, check_main_thread, check_viewer_enabled
from nerfstudio.utils.misc import step_check
from nerfstudio.utils.rich_utils import CONSOLE
from nerfstudio.utils.writer import EventName, TimeWriter
from nerfstudio.viewer.server.viewer_state import ViewerState
-from nerfstudio.viewer_beta.viewer_state import ViewerState as ViewerBetaState
+from nerfstudio.viewer_beta.viewer import Viewer as ViewerBetaState
TRAIN_INTERATION_OUTPUT = Tuple[torch.Tensor, Dict[str, torch.Tensor], Dict[str, torch.Tensor]]
TORCH_DEVICE = str
@@ -120,7 +112,9 @@ class Trainer:
self.config = config
self.local_rank = local_rank
self.world_size = world_size
- self.device: TORCH_DEVICE = "cpu" if world_size == 0 else f"cuda:{local_rank}"
+ self.device: TORCH_DEVICE = config.machine.device_type
+ if self.device == "cuda":
+ self.device += f":{local_rank}"
self.mixed_precision: bool = self.config.mixed_precision
self.use_grad_scaler: bool = self.mixed_precision or self.config.use_grad_scaler
self.training_state: Literal["training", "paused", "completed"] = "training"
@@ -462,9 +456,10 @@ class Trainer:
"""
self.optimizers.zero_grad_all()
- cpu_or_cuda_str: str = self.device.split(":")[0]
- with torch.autocast(device_type=cpu_or_cuda_str, enabled=self.mixed_precision):
+ device_type: str = self.device.split(":")[0] if "cuda" in self.device else "cpu"
+
+ with torch.autocast(device_type=device_type, enabled=self.mixed_precision):
_, loss_dict, metrics_dict = self.pipeline.get_train_loss_dict(step=step)
loss = functools.reduce(torch.add, loss_dict.values())
self.grad_scaler.scale(loss).backward() # type: ignore
diff --git a/nerfstudio/field_components/encodings.py b/nerfstudio/field_components/encodings.py
index 71d3e4a6c..48ec17556 100644
--- a/nerfstudio/field_components/encodings.py
+++ b/nerfstudio/field_components/encodings.py
@@ -109,7 +109,13 @@ class NeRFEncoding(Encoding):
"""
def __init__(
- self, in_dim: int, num_frequencies: int, min_freq_exp: float, max_freq_exp: float, include_input: bool = False
+ self,
+ in_dim: int,
+ num_frequencies: int,
+ min_freq_exp: float,
+ max_freq_exp: float,
+ include_input: bool = False,
+ implementation: Literal["tcnn", "torch"] = "torch",
) -> None:
super().__init__(in_dim)
@@ -118,6 +124,18 @@ class NeRFEncoding(Encoding):
self.max_freq = max_freq_exp
self.include_input = include_input
+ self.tcnn_encoding = None
+ if implementation == "tcnn" and not TCNN_EXISTS:
+ print_tcnn_speed_warning("NeRFEncoding")
+ elif implementation == "tcnn":
+ encoding_config = {"otype": "Frequency", "n_frequencies": num_frequencies}
+ assert min_freq_exp == 0, "tcnn only supports min_freq_exp = 0"
+ assert max_freq_exp == num_frequencies - 1, "tcnn only supports max_freq_exp = num_frequencies - 1"
+ self.tcnn_encoding = tcnn.Encoding(
+ n_input_dims=in_dim,
+ encoding_config=encoding_config,
+ )
+
def get_out_dim(self) -> int:
if self.in_dim is None:
raise ValueError("Input dimension has not been set")
@@ -126,7 +144,7 @@ class NeRFEncoding(Encoding):
out_dim += self.in_dim
return out_dim
- def forward(
+ def pytorch_fwd(
self,
in_tensor: Float[Tensor, "*bs input_dim"],
covs: Optional[Float[Tensor, "*bs input_dim input_dim"]] = None,
@@ -158,6 +176,13 @@ class NeRFEncoding(Encoding):
encoded_inputs = torch.cat([encoded_inputs, in_tensor], dim=-1)
return encoded_inputs
+ def forward(
+ self, in_tensor: Float[Tensor, "*bs input_dim"], covs: Optional[Float[Tensor, "*bs input_dim input_dim"]] = None
+ ) -> Float[Tensor, "*bs output_dim"]:
+ if self.tcnn_encoding is not None:
+ return self.tcnn_encoding(in_tensor)
+ return self.pytorch_fwd(in_tensor, covs)
+
class RFFEncoding(Encoding):
"""Random Fourier Feature encoding. Supports integrated encodings.
@@ -239,7 +264,7 @@ class HashEncoding(Encoding):
log2_hashmap_size: int = 19,
features_per_level: int = 2,
hash_init_scale: float = 0.001,
- implementation: Literal["tcnn", "torch"] = "tcnn",
+ implementation: Literal["tcnn", "torch"] = "torch",
interpolation: Optional[Literal["Nearest", "Linear", "Smoothstep"]] = None,
) -> None:
super().__init__(in_dim=3)
@@ -258,7 +283,7 @@ class HashEncoding(Encoding):
self.hash_table = nn.Parameter(self.hash_table)
self.tcnn_encoding = None
- if not TCNN_EXISTS and implementation == "tcnn":
+ if implementation == "tcnn" and not TCNN_EXISTS:
print_tcnn_speed_warning("HashEncoding")
elif implementation == "tcnn":
encoding_config = {
@@ -277,7 +302,7 @@ class HashEncoding(Encoding):
encoding_config=encoding_config,
)
- if not TCNN_EXISTS or self.tcnn_encoding is None:
+ if self.tcnn_encoding is None:
assert (
interpolation is None or interpolation == "Linear"
), f"interpolation '{interpolation}' is not supported for torch encoding backend"
@@ -348,7 +373,7 @@ class HashEncoding(Encoding):
return torch.flatten(encoded_value, start_dim=-2, end_dim=-1) # [..., num_levels * features_per_level]
def forward(self, in_tensor: Float[Tensor, "*bs input_dim"]) -> Float[Tensor, "*bs output_dim"]:
- if TCNN_EXISTS and self.tcnn_encoding is not None:
+ if self.tcnn_encoding is not None:
return self.tcnn_encoding(in_tensor)
return self.pytorch_fwd(in_tensor)
@@ -647,7 +672,7 @@ class SHEncoding(Encoding):
levels: Number of spherical harmonic levels to encode.
"""
- def __init__(self, levels: int = 4) -> None:
+ def __init__(self, levels: int = 4, implementation: Literal["tcnn", "torch"] = "torch") -> None:
super().__init__(in_dim=3)
if levels <= 0 or levels > 4:
@@ -655,9 +680,28 @@ class SHEncoding(Encoding):
self.levels = levels
+ self.tcnn_encoding = None
+ if implementation == "tcnn" and not TCNN_EXISTS:
+ print_tcnn_speed_warning("SHEncoding")
+ elif implementation == "tcnn":
+ encoding_config = {
+ "otype": "SphericalHarmonics",
+ "degree": levels,
+ }
+ self.tcnn_encoding = tcnn.Encoding(
+ n_input_dims=3,
+ encoding_config=encoding_config,
+ )
+
def get_out_dim(self) -> int:
return self.levels**2
@torch.no_grad()
- def forward(self, in_tensor: Float[Tensor, "*bs input_dim"]) -> Float[Tensor, "*bs output_dim"]:
+ def pytorch_fwd(self, in_tensor: Float[Tensor, "*bs input_dim"]) -> Float[Tensor, "*bs output_dim"]:
+ """Forward pass using pytorch. Significantly slower than TCNN implementation."""
return components_from_spherical_harmonics(levels=self.levels, directions=in_tensor)
+
+ def forward(self, in_tensor: Float[Tensor, "*bs input_dim"]) -> Float[Tensor, "*bs output_dim"]:
+ if self.tcnn_encoding is not None:
+ return self.tcnn_encoding(in_tensor)
+ return self.pytorch_fwd(in_tensor)
diff --git a/nerfstudio/field_components/mlp.py b/nerfstudio/field_components/mlp.py
index c51ed5f3b..2d766e233 100644
--- a/nerfstudio/field_components/mlp.py
+++ b/nerfstudio/field_components/mlp.py
@@ -15,13 +15,51 @@
"""
Multi Layer Perceptron
"""
-from typing import Optional, Set, Tuple
+from typing import Literal, Optional, Set, Tuple, Union
import torch
from jaxtyping import Float
from torch import Tensor, nn
from nerfstudio.field_components.base_field_component import FieldComponent
+from nerfstudio.utils.printing import print_tcnn_speed_warning
+
+from nerfstudio.utils.rich_utils import CONSOLE
+
+try:
+ import tinycudann as tcnn
+
+ TCNN_EXISTS = True
+except ModuleNotFoundError:
+ TCNN_EXISTS = False
+
+
+def activation_to_tcnn_string(activation: Union[nn.Module, None]) -> str:
+ """Converts a torch.nn activation function to a string that can be used to
+ initialize a TCNN activation function.
+
+ Args:
+ activation: torch.nn activation function
+ Returns:
+ str: TCNN activation function string
+ """
+
+ if isinstance(activation, nn.ReLU):
+ return "ReLU"
+ if isinstance(activation, nn.LeakyReLU):
+ return "Leaky ReLU"
+ if isinstance(activation, nn.Sigmoid):
+ return "Sigmoid"
+ if isinstance(activation, nn.Softplus):
+ return "Softplus"
+ if isinstance(activation, nn.Tanh):
+ return "Tanh"
+ if isinstance(activation, type(None)):
+ return "None"
+ tcnn_documentation_url = "https://github.com/NVlabs/tiny-cuda-nn/blob/master/DOCUMENTATION.md#activation-functions"
+ raise ValueError(
+ f"TCNN activation {activation} not supported for now.\nSee {tcnn_documentation_url} for TCNN documentation."
+ )
class MLP(FieldComponent):
@@ -45,6 +83,7 @@ class MLP(FieldComponent):
skip_connections: Optional[Tuple[int]] = None,
activation: Optional[nn.Module] = nn.ReLU(),
out_activation: Optional[nn.Module] = None,
+ implementation: Literal["tcnn", "torch"] = "torch",
) -> None:
super().__init__()
self.in_dim = in_dim
@@ -57,7 +96,43 @@ class MLP(FieldComponent):
self.activation = activation
self.out_activation = out_activation
self.net = None
- self.build_nn_modules()
+
+ self.tcnn_encoding = None
+ if implementation == "torch":
+ self.build_nn_modules()
+ elif implementation == "tcnn" and not TCNN_EXISTS:
+ print_tcnn_speed_warning("MLP")
+ elif implementation == "tcnn":
+ activation_str = activation_to_tcnn_string(activation)
+ output_activation_str = activation_to_tcnn_string(out_activation)
+ if layer_width in [16, 32, 64, 128]:
+ network_config = {
+ "otype": "FullyFusedMLP",
+ "activation": activation_str,
+ "output_activation": output_activation_str,
+ "n_neurons": layer_width,
+ "n_hidden_layers": num_layers - 1,
+ }
+ else:
+ CONSOLE.line()
+ CONSOLE.print("[bold yellow]WARNING: Using slower TCNN CutlassMLP instead of TCNN FullyFusedMLP")
+ CONSOLE.print(
+ "[bold yellow]Use layer width of 16, 32, 64, or 128 to use the faster TCNN FullyFusedMLP."
+ )
+ CONSOLE.line()
+ network_config = {
+ "otype": "CutlassMLP",
+ "activation": activation_str,
+ "output_activation": output_activation_str,
+ "n_neurons": layer_width,
+ "n_hidden_layers": num_layers - 1,
+ }
+
+ self.tcnn_encoding = tcnn.Network(
+ n_input_dims=in_dim,
+ n_output_dims=out_dim,
+ network_config=network_config,
+ )
def build_nn_modules(self) -> None:
"""Initialize multi-layer perceptron."""
@@ -76,7 +151,7 @@ class MLP(FieldComponent):
layers.append(nn.Linear(self.layer_width, self.out_dim))
self.layers = nn.ModuleList(layers)
- def forward(self, in_tensor: Float[Tensor, "*bs in_dim"]) -> Float[Tensor, "*bs out_dim"]:
+ def pytorch_fwd(self, in_tensor: Float[Tensor, "*bs in_dim"]) -> Float[Tensor, "*bs out_dim"]:
"""Process input with a multilayer perceptron.
Args:
@@ -96,3 +171,8 @@ class MLP(FieldComponent):
if self.out_activation is not None:
x = self.out_activation(x)
return x
+
+ def forward(self, in_tensor: Float[Tensor, "*bs in_dim"]) -> Float[Tensor, "*bs out_dim"]:
+ if self.tcnn_encoding is not None:
+ return self.tcnn_encoding(in_tensor)
+ return self.pytorch_fwd(in_tensor)
diff --git a/nerfstudio/fields/density_fields.py b/nerfstudio/fields/density_fields.py
index 47eec223a..75fc5dc78 100644
--- a/nerfstudio/fields/density_fields.py
+++ b/nerfstudio/fields/density_fields.py
@@ -17,24 +17,19 @@ Proposal network field.
"""
-from typing import Optional, Tuple
+from typing import Literal, Optional, Tuple
-import numpy as np
import torch
-from torch import Tensor
+from torch import Tensor, nn
from nerfstudio.cameras.rays import RaySamples
from nerfstudio.data.scene_box import SceneBox
from nerfstudio.field_components.activations import trunc_exp
+from nerfstudio.field_components.encodings import HashEncoding
+from nerfstudio.field_components.mlp import MLP
from nerfstudio.field_components.spatial_distortions import SpatialDistortion
from nerfstudio.fields.base_field import Field
-try:
- import tinycudann as tcnn
-except ImportError:
- # tinycudann module doesn't exist
- pass
-
class HashMLPDensityField(Field):
"""A lightweight density field module.
@@ -61,45 +56,39 @@ class HashMLPDensityField(Field):
base_res: int = 16,
log2_hashmap_size: int = 18,
features_per_level: int = 2,
+ implementation: Literal["tcnn", "torch"] = "torch",
) -> None:
super().__init__()
self.register_buffer("aabb", aabb)
self.spatial_distortion = spatial_distortion
self.use_linear = use_linear
- growth_factor = np.exp((np.log(max_res) - np.log(base_res)) / (num_levels - 1))
self.register_buffer("max_res", torch.tensor(max_res))
self.register_buffer("num_levels", torch.tensor(num_levels))
self.register_buffer("log2_hashmap_size", torch.tensor(log2_hashmap_size))
- config = {
- "encoding": {
- "otype": "HashGrid",
- "n_levels": num_levels,
- "n_features_per_level": features_per_level,
- "log2_hashmap_size": log2_hashmap_size,
- "base_resolution": base_res,
- "per_level_scale": growth_factor,
- },
- "network": {
- "otype": "FullyFusedMLP",
- "activation": "ReLU",
- "output_activation": "None",
- "n_neurons": hidden_dim,
- "n_hidden_layers": num_layers - 1,
- },
- }
+ self.encoding = HashEncoding(
+ num_levels=num_levels,
+ min_res=base_res,
+ max_res=max_res,
+ log2_hashmap_size=log2_hashmap_size,
+ features_per_level=features_per_level,
+ implementation=implementation,
+ )
if not self.use_linear:
- self.mlp_base = tcnn.NetworkWithInputEncoding(
- n_input_dims=3,
- n_output_dims=1,
- encoding_config=config["encoding"],
- network_config=config["network"],
+ network = MLP(
+ in_dim=self.encoding.get_out_dim(),
+ num_layers=num_layers,
+ layer_width=hidden_dim,
+ out_dim=1,
+ activation=nn.ReLU(),
+ out_activation=None,
+ implementation=implementation,
)
+ self.mlp_base = torch.nn.Sequential(self.encoding, network)
else:
- self.encoding = tcnn.Encoding(n_input_dims=3, encoding_config=config["encoding"])
- self.linear = torch.nn.Linear(self.encoding.n_output_dims, 1)
+ self.linear = torch.nn.Linear(self.encoding.get_out_dim(), 1)
def get_density(self, ray_samples: RaySamples) -> Tuple[Tensor, None]:
if self.spatial_distortion is not None:
diff --git a/nerfstudio/fields/instant_ngp_field.py b/nerfstudio/fields/instant_ngp_field.py
index 3941e7ec9..63b01eff6 100644
--- a/nerfstudio/fields/instant_ngp_field.py
+++ b/nerfstudio/fields/instant_ngp_field.py
@@ -60,6 +60,7 @@ class TCNNInstantNGPField(Field):
num_levels: number of levels of the hashmap for the base mlp
log2_hashmap_size: size of the hashmap for the base mlp
max_res: maximum resolution of the hashmap for the base mlp
+ mode: which implementation to use for the field
"""
def __init__(
diff --git a/nerfstudio/fields/nerfacto_field.py b/nerfstudio/fields/nerfacto_field.py
index e828ac664..898d344d3 100644
--- a/nerfstudio/fields/nerfacto_field.py
+++ b/nerfstudio/fields/nerfacto_field.py
@@ -17,44 +17,30 @@ Field for compound nerf model, adds scene contraction and image embeddings to in
"""
-from typing import Dict, Optional, Tuple, Type
+from typing import Dict, Literal, Optional, Tuple
-import numpy as np
import torch
from torch import Tensor, nn
-from torch.nn.parameter import Parameter
from nerfstudio.cameras.rays import RaySamples
from nerfstudio.data.scene_box import SceneBox
from nerfstudio.field_components.activations import trunc_exp
from nerfstudio.field_components.embedding import Embedding
-from nerfstudio.field_components.encodings import Encoding, HashEncoding, SHEncoding
+from nerfstudio.field_components.encodings import HashEncoding, NeRFEncoding, SHEncoding
from nerfstudio.field_components.field_heads import (
- DensityFieldHead,
- FieldHead,
FieldHeadNames,
PredNormalsFieldHead,
- RGBFieldHead,
SemanticFieldHead,
TransientDensityFieldHead,
TransientRGBFieldHead,
UncertaintyFieldHead,
)
from nerfstudio.field_components.mlp import MLP
-from nerfstudio.field_components.spatial_distortions import (
- SceneContraction,
- SpatialDistortion,
-)
+from nerfstudio.field_components.spatial_distortions import SpatialDistortion
from nerfstudio.fields.base_field import Field, shift_directions_for_tcnn
-try:
- import tinycudann as tcnn
-except ModuleNotFoundError:
- # tinycudann module doesn't exist
- pass
-
-class TCNNNerfactoField(Field):
+class NerfactoField(Field):
"""Compound Field that uses TCNN
Args:
@@ -105,6 +91,7 @@ class TCNNNerfactoField(Field):
use_pred_normals: bool = False,
use_average_appearance_embedding: bool = False,
spatial_distortion: Optional[SpatialDistortion] = None,
+ implementation: Literal["tcnn", "torch"] = "tcnn",
) -> None:
super().__init__()
@@ -127,102 +114,88 @@ class TCNNNerfactoField(Field):
base_res: int = 16
features_per_level: int = 2
- growth_factor = np.exp((np.log(max_res) - np.log(base_res)) / (num_levels - 1))
- self.direction_encoding = tcnn.Encoding(
- n_input_dims=3,
- encoding_config={
- "otype": "SphericalHarmonics",
- "degree": 4,
- },
+ self.direction_encoding = SHEncoding(
+ levels=4,
+ implementation=implementation,
)
- self.position_encoding = tcnn.Encoding(
- n_input_dims=3,
- encoding_config={"otype": "Frequency", "n_frequencies": 2},
+ self.position_encoding = NeRFEncoding(
+ in_dim=3, num_frequencies=2, min_freq_exp=0, max_freq_exp=2 - 1, implementation=implementation
)
- self.mlp_base = tcnn.NetworkWithInputEncoding(
- n_input_dims=3,
- n_output_dims=1 + self.geo_feat_dim,
- encoding_config={
- "otype": "HashGrid",
- "n_levels": num_levels,
- "n_features_per_level": features_per_level,
- "log2_hashmap_size": log2_hashmap_size,
- "base_resolution": base_res,
- "per_level_scale": growth_factor,
- },
- network_config={
- "otype": "FullyFusedMLP",
- "activation": "ReLU",
- "output_activation": "None",
- "n_neurons": hidden_dim,
- "n_hidden_layers": num_layers - 1,
- },
+ encoder = HashEncoding(
+ num_levels=num_levels,
+ min_res=base_res,
+ max_res=max_res,
+ log2_hashmap_size=log2_hashmap_size,
+ features_per_level=features_per_level,
+ implementation=implementation,
)
+ network = MLP(
+ in_dim=encoder.get_out_dim(),
+ num_layers=num_layers,
+ layer_width=hidden_dim,
+ out_dim=1 + self.geo_feat_dim,
+ activation=nn.ReLU(),
+ out_activation=None,
+ implementation=implementation,
+ )
+ self.mlp_base = torch.nn.Sequential(encoder, network)
# transients
if self.use_transient_embedding:
self.transient_embedding_dim = transient_embedding_dim
self.embedding_transient = Embedding(self.num_images, self.transient_embedding_dim)
- self.mlp_transient = tcnn.Network(
- n_input_dims=self.geo_feat_dim + self.transient_embedding_dim,
- n_output_dims=hidden_dim_transient,
- network_config={
- "otype": "FullyFusedMLP",
- "activation": "ReLU",
- "output_activation": "None",
- "n_neurons": hidden_dim_transient,
- "n_hidden_layers": num_layers_transient - 1,
- },
+ self.mlp_transient = MLP(
+ in_dim=self.geo_feat_dim + self.transient_embedding_dim,
+ num_layers=num_layers_transient,
+ layer_width=hidden_dim_transient,
+ out_dim=hidden_dim_transient,
+ activation=nn.ReLU(),
+ out_activation=None,
+ implementation=implementation,
)
- self.field_head_transient_uncertainty = UncertaintyFieldHead(in_dim=self.mlp_transient.n_output_dims)
- self.field_head_transient_rgb = TransientRGBFieldHead(in_dim=self.mlp_transient.n_output_dims)
- self.field_head_transient_density = TransientDensityFieldHead(in_dim=self.mlp_transient.n_output_dims)
+ self.field_head_transient_uncertainty = UncertaintyFieldHead(in_dim=self.mlp_transient.get_out_dim())
+ self.field_head_transient_rgb = TransientRGBFieldHead(in_dim=self.mlp_transient.get_out_dim())
+ self.field_head_transient_density = TransientDensityFieldHead(in_dim=self.mlp_transient.get_out_dim())
# semantics
if self.use_semantics:
- self.mlp_semantics = tcnn.Network(
- n_input_dims=self.geo_feat_dim,
- n_output_dims=hidden_dim_transient,
- network_config={
- "otype": "FullyFusedMLP",
- "activation": "ReLU",
- "output_activation": "None",
- "n_neurons": 64,
- "n_hidden_layers": 1,
- },
+ self.mlp_semantics = MLP(
+ in_dim=self.geo_feat_dim,
+ num_layers=2,
+ layer_width=64,
+ out_dim=hidden_dim_transient,
+ activation=nn.ReLU(),
+ out_activation=None,
+ implementation=implementation,
)
self.field_head_semantics = SemanticFieldHead(
- in_dim=self.mlp_semantics.n_output_dims, num_classes=num_semantic_classes
+ in_dim=self.mlp_semantics.get_out_dim(), num_classes=num_semantic_classes
)
# predicted normals
if self.use_pred_normals:
- self.mlp_pred_normals = tcnn.Network(
- n_input_dims=self.geo_feat_dim + self.position_encoding.n_output_dims,
- n_output_dims=hidden_dim_transient,
- network_config={
- "otype": "FullyFusedMLP",
- "activation": "ReLU",
- "output_activation": "None",
- "n_neurons": 64,
- "n_hidden_layers": 2,
- },
+ self.mlp_pred_normals = MLP(
+ in_dim=self.geo_feat_dim + self.position_encoding.get_out_dim(),
+ num_layers=3,
+ layer_width=64,
+ out_dim=hidden_dim_transient,
+ activation=nn.ReLU(),
+ out_activation=None,
+ implementation=implementation,
)
- self.field_head_pred_normals = PredNormalsFieldHead(in_dim=self.mlp_pred_normals.n_output_dims)
+ self.field_head_pred_normals = PredNormalsFieldHead(in_dim=self.mlp_pred_normals.get_out_dim())
- self.mlp_head = tcnn.Network(
- n_input_dims=self.direction_encoding.n_output_dims + self.geo_feat_dim + self.appearance_embedding_dim,
- n_output_dims=3,
- network_config={
- "otype": "FullyFusedMLP",
- "activation": "ReLU",
- "output_activation": "Sigmoid",
- "n_neurons": hidden_dim_color,
- "n_hidden_layers": num_layers_color - 1,
- },
+ self.mlp_head = MLP(
+ in_dim=self.direction_encoding.get_out_dim() + self.geo_feat_dim + self.appearance_embedding_dim,
+ num_layers=num_layers_color,
+ layer_width=hidden_dim_color,
+ out_dim=3,
+ activation=nn.ReLU(),
+ out_activation=nn.Sigmoid(),
+ implementation=implementation,
)
def get_density(self, ray_samples: RaySamples) -> Tuple[Tensor, Tensor]:
@@ -324,102 +297,3 @@ class TCNNNerfactoField(Field):
outputs.update({FieldHeadNames.RGB: rgb})
return outputs
-
-
-class TorchNerfactoField(Field):
- """
- PyTorch implementation of the compound field.
- """
-
- def __init__(
- self,
- aabb: Tensor,
- num_images: int,
- position_encoding: Encoding = HashEncoding(),
- direction_encoding: Encoding = SHEncoding(),
- base_mlp_num_layers: int = 3,
- base_mlp_layer_width: int = 64,
- head_mlp_num_layers: int = 2,
- head_mlp_layer_width: int = 32,
- appearance_embedding_dim: int = 40,
- skip_connections: Tuple = (4,),
- field_heads: Tuple[FieldHead] = (RGBFieldHead(),),
- spatial_distortion: SpatialDistortion = SceneContraction(),
- ) -> None:
- super().__init__()
- self.aabb = Parameter(aabb, requires_grad=False)
- self.spatial_distortion = spatial_distortion
- self.num_images = num_images
- self.appearance_embedding_dim = appearance_embedding_dim
- self.embedding_appearance = Embedding(self.num_images, self.appearance_embedding_dim)
-
- self.position_encoding = position_encoding
- self.direction_encoding = direction_encoding
-
- self.mlp_base = MLP(
- in_dim=self.position_encoding.get_out_dim(),
- num_layers=base_mlp_num_layers,
- layer_width=base_mlp_layer_width,
- skip_connections=skip_connections,
- out_activation=nn.ReLU(),
- )
-
- self.mlp_head = MLP(
- in_dim=self.mlp_base.get_out_dim() + self.direction_encoding.get_out_dim() + self.appearance_embedding_dim,
- num_layers=head_mlp_num_layers,
- layer_width=head_mlp_layer_width,
- out_activation=nn.ReLU(),
- )
-
- self.field_output_density = DensityFieldHead(in_dim=self.mlp_base.get_out_dim())
- self.field_heads = nn.ModuleList(field_heads)
- for field_head in self.field_heads:
- field_head.set_in_dim(self.mlp_head.get_out_dim()) # type: ignore
-
- def get_density(self, ray_samples: RaySamples) -> Tuple[Tensor, Tensor]:
- if self.spatial_distortion is not None:
- positions = ray_samples.frustums.get_positions()
- positions = self.spatial_distortion(positions)
- else:
- positions = ray_samples.frustums.get_positions()
- encoded_xyz = self.position_encoding(positions.view(-1, 3)).to(torch.float32)
- base_mlp_out = self.mlp_base(encoded_xyz).view(*ray_samples.frustums.shape, -1)
- density = self.field_output_density(base_mlp_out)
- return density, base_mlp_out
-
- def get_outputs(
- self, ray_samples: RaySamples, density_embedding: Optional[Tensor] = None
- ) -> Dict[FieldHeadNames, Tensor]:
- outputs_shape = ray_samples.frustums.directions.shape[:-1]
-
- if ray_samples.camera_indices is None:
- raise AttributeError("Camera indices are not provided.")
- camera_indices = ray_samples.camera_indices.squeeze()
- if self.training:
- embedded_appearance = self.embedding_appearance(camera_indices)
- else:
- embedded_appearance = torch.zeros(
- (*outputs_shape, self.appearance_embedding_dim),
- device=ray_samples.frustums.directions.device,
- )
-
- outputs = {}
- for field_head in self.field_heads:
- directions = shift_directions_for_tcnn(ray_samples.frustums.directions)
- directions_flat = directions.view(-1, 3)
- encoded_dir = self.direction_encoding(directions_flat)
- mlp_out = self.mlp_head(
- torch.cat(
- [
- encoded_dir.view(-1, self.direction_encoding.get_out_dim()),
- density_embedding.view(-1, self.mlp_base.get_out_dim()), # type:ignore
- embedded_appearance.view(-1, self.appearance_embedding_dim),
- ],
- dim=-1, # type:ignore
- )
- )
- outputs[field_head.field_head_name] = field_head(mlp_out).view(*outputs_shape, -1).to(directions)
- return outputs
-
-
-field_implementation_to_class: Dict[str, Type[Field]] = {"tcnn": TCNNNerfactoField, "torch": TorchNerfactoField}
diff --git a/nerfstudio/model_components/losses.py b/nerfstudio/model_components/losses.py
index cd589cad3..604f306e6 100644
--- a/nerfstudio/model_components/losses.py
+++ b/nerfstudio/model_components/losses.py
@@ -77,9 +77,9 @@ def outer(
def lossfun_outer(
- t: Float[Tensor, "*batch num_samples+1"],
+ t: Float[Tensor, "*batch num_samples_1"],
w: Float[Tensor, "*batch num_samples"],
- t_env: Float[Tensor, "*batch num_samples+1"],
+ t_env: Float[Tensor, "*batch num_samples_1"],
w_env: Float[Tensor, "*batch num_samples"],
):
"""
diff --git a/nerfstudio/model_components/ray_samplers.py b/nerfstudio/model_components/ray_samplers.py
index 59d6d7b82..c0b4b883d 100644
--- a/nerfstudio/model_components/ray_samplers.py
+++ b/nerfstudio/model_components/ray_samplers.py
@@ -17,7 +17,7 @@ Collection of sampling strategies
"""
from abc import abstractmethod
-from typing import Callable, List, Optional, Protocol, Tuple, Union
+from typing import Any, Callable, List, Optional, Protocol, Tuple, Union
import torch
from jaxtyping import Float
@@ -42,10 +42,10 @@ class Sampler(nn.Module):
self.num_samples = num_samples
@abstractmethod
- def generate_ray_samples(self) -> RaySamples:
+ def generate_ray_samples(self) -> Any:
"""Generate Ray Samples"""
- def forward(self, *args, **kwargs) -> RaySamples:
+ def forward(self, *args, **kwargs) -> Any:
"""Generate ray samples"""
return self.generate_ray_samples(*args, **kwargs)
diff --git a/nerfstudio/models/base_model.py b/nerfstudio/models/base_model.py
index e63a3960b..6f31c3b30 100644
--- a/nerfstudio/models/base_model.py
+++ b/nerfstudio/models/base_model.py
@@ -21,7 +21,7 @@ from __future__ import annotations
from abc import abstractmethod
from collections import defaultdict
from dataclasses import dataclass, field
-from typing import Any, Dict, List, Optional, Tuple, Type
+from typing import Any, Dict, List, Optional, Tuple, Type, Union
import torch
from torch import nn
@@ -117,7 +117,7 @@ class Model(nn.Module):
"""
@abstractmethod
- def get_outputs(self, ray_bundle: RayBundle) -> Dict[str, torch.Tensor]:
+ def get_outputs(self, ray_bundle: RayBundle) -> Dict[str, Union[torch.Tensor, List]]:
"""Takes in a Ray Bundle and returns a dictionary of outputs.
Args:
@@ -128,7 +128,7 @@ class Model(nn.Module):
Outputs of model. (ie. rendered colors)
"""
- def forward(self, ray_bundle: RayBundle) -> Dict[str, torch.Tensor]:
+ def forward(self, ray_bundle: RayBundle) -> Dict[str, Union[torch.Tensor, List]]:
"""Run forward starting with a ray bundle. This outputs different things depending on the configuration
of the model and whether or not the batch is provided (whether or not we are training basically)
diff --git a/nerfstudio/models/base_surface_model.py b/nerfstudio/models/base_surface_model.py
index b5e2d373a..f7af6e2c1 100644
--- a/nerfstudio/models/base_surface_model.py
+++ b/nerfstudio/models/base_surface_model.py
@@ -33,7 +33,7 @@ from nerfstudio.cameras.rays import RayBundle
from nerfstudio.field_components.encodings import NeRFEncoding
from nerfstudio.field_components.field_heads import FieldHeadNames
from nerfstudio.field_components.spatial_distortions import SceneContraction
-from nerfstudio.fields.nerfacto_field import TCNNNerfactoField
+from nerfstudio.fields.nerfacto_field import NerfactoField
from nerfstudio.fields.sdf_field import SDFFieldConfig
from nerfstudio.fields.vanilla_nerf_field import NeRFField
from nerfstudio.model_components.losses import (
@@ -124,7 +124,7 @@ class SurfaceModel(Model):
# background model
if self.config.background_model == "grid":
- self.field_background = TCNNNerfactoField(
+ self.field_background = NerfactoField(
self.scene_box.aabb,
spatial_distortion=self.scene_contraction,
num_images=self.num_train_data,
diff --git a/nerfstudio/models/instant_ngp.py b/nerfstudio/models/instant_ngp.py
index 1eff0c836..e8ac52b96 100644
--- a/nerfstudio/models/instant_ngp.py
+++ b/nerfstudio/models/instant_ngp.py
@@ -36,7 +36,7 @@ from nerfstudio.engine.callbacks import (
)
from nerfstudio.field_components.field_heads import FieldHeadNames
from nerfstudio.field_components.spatial_distortions import SceneContraction
-from nerfstudio.fields.nerfacto_field import TCNNNerfactoField
+from nerfstudio.fields.nerfacto_field import NerfactoField
from nerfstudio.model_components.losses import MSELoss
from nerfstudio.model_components.ray_samplers import VolumetricSampler
from nerfstudio.model_components.renderers import (
@@ -94,7 +94,7 @@ class NGPModel(Model):
"""
config: InstantNGPModelConfig
- field: TCNNNerfactoField
+ field: NerfactoField
def __init__(self, config: InstantNGPModelConfig, **kwargs) -> None:
super().__init__(config=config, **kwargs)
@@ -108,7 +108,7 @@ class NGPModel(Model):
else:
scene_contraction = SceneContraction(order=float("inf"))
- self.field = TCNNNerfactoField(
+ self.field = NerfactoField(
aabb=self.scene_box.aabb,
num_images=self.num_train_data,
log2_hashmap_size=self.config.log2_hashmap_size,
diff --git a/nerfstudio/models/nerfacto.py b/nerfstudio/models/nerfacto.py
index 6d46c86c3..80ead5951 100644
--- a/nerfstudio/models/nerfacto.py
+++ b/nerfstudio/models/nerfacto.py
@@ -37,7 +37,7 @@ from nerfstudio.engine.callbacks import (
from nerfstudio.field_components.field_heads import FieldHeadNames
from nerfstudio.field_components.spatial_distortions import SceneContraction
from nerfstudio.fields.density_fields import HashMLPDensityField
-from nerfstudio.fields.nerfacto_field import TCNNNerfactoField
+from nerfstudio.fields.nerfacto_field import NerfactoField
from nerfstudio.model_components.losses import (
MSELoss,
distortion_loss,
@@ -130,6 +130,8 @@ class NerfactoModelConfig(ModelConfig):
"""Whether to disable scene contraction or not."""
use_gradient_scaling: bool = False
"""Use gradient scaler where the gradients are lower for points closer to the camera."""
+ implementation: Literal["tcnn", "torch"] = "tcnn"
+ """Which implementation to use for the model."""
class NerfactoModel(Model):
@@ -151,7 +153,7 @@ class NerfactoModel(Model):
scene_contraction = SceneContraction(order=float("inf"))
# Fields
- self.field = TCNNNerfactoField(
+ self.field = NerfactoField(
self.scene_box.aabb,
hidden_dim=self.config.hidden_dim,
num_levels=self.config.num_levels,
@@ -163,6 +165,7 @@ class NerfactoModel(Model):
num_images=self.num_train_data,
use_pred_normals=self.config.predict_normals,
use_average_appearance_embedding=self.config.use_average_appearance_embedding,
+ implementation=self.config.implementation,
)
self.density_fns = []
@@ -172,7 +175,12 @@ class NerfactoModel(Model):
if self.config.use_same_proposal_network:
assert len(self.config.proposal_net_args_list) == 1, "Only one proposal network is allowed."
prop_net_args = self.config.proposal_net_args_list[0]
- network = HashMLPDensityField(self.scene_box.aabb, spatial_distortion=scene_contraction, **prop_net_args)
+ network = HashMLPDensityField(
+ self.scene_box.aabb,
+ spatial_distortion=scene_contraction,
+ **prop_net_args,
+ implementation=self.config.implementation,
+ )
self.proposal_networks.append(network)
self.density_fns.extend([network.density_fn for _ in range(num_prop_nets)])
else:
@@ -182,6 +190,7 @@ class NerfactoModel(Model):
self.scene_box.aabb,
spatial_distortion=scene_contraction,
**prop_net_args,
+ implementation=self.config.implementation,
)
self.proposal_networks.append(network)
self.density_fns.extend([network.density_fn for network in self.proposal_networks])
diff --git a/nerfstudio/models/neus_facto.py b/nerfstudio/models/neus_facto.py
index 1f7104620..5c1a3ec9d 100644
--- a/nerfstudio/models/neus_facto.py
+++ b/nerfstudio/models/neus_facto.py
@@ -48,7 +48,7 @@ class NeuSFactoModelConfig(NeuSModelConfig):
"""NeusFacto Model Config"""
_target: Type = field(default_factory=lambda: NeuSFactoModel)
- num_proposal_samples_per_ray: Tuple[int, int] = (256, 96)
+ num_proposal_samples_per_ray: Tuple[int, ...] = (256, 96)
"""Number of samples per ray for the proposal network."""
num_neus_samples_per_ray: int = 48
"""Number of samples per ray for the nerf network."""
diff --git a/nerfstudio/models/semantic_nerfw.py b/nerfstudio/models/semantic_nerfw.py
index a006ca3b2..c465e65b9 100644
--- a/nerfstudio/models/semantic_nerfw.py
+++ b/nerfstudio/models/semantic_nerfw.py
@@ -38,7 +38,7 @@ from nerfstudio.engine.callbacks import (
from nerfstudio.field_components.field_heads import FieldHeadNames
from nerfstudio.field_components.spatial_distortions import SceneContraction
from nerfstudio.fields.density_fields import HashMLPDensityField
-from nerfstudio.fields.nerfacto_field import TCNNNerfactoField
+from nerfstudio.fields.nerfacto_field import NerfactoField
from nerfstudio.model_components.losses import MSELoss, distortion_loss, interlevel_loss
from nerfstudio.model_components.ray_samplers import ProposalNetworkSampler
from nerfstudio.model_components.renderers import (
@@ -90,7 +90,7 @@ class SemanticNerfWModel(Model):
raise ValueError("Transient embedding is not fully working for semantic nerf-w.")
# Fields
- self.field = TCNNNerfactoField(
+ self.field = NerfactoField(
self.scene_box.aabb,
num_levels=self.config.num_levels,
max_res=self.config.max_res,
diff --git a/nerfstudio/scripts/render.py b/nerfstudio/scripts/render.py
index 0fffd00e8..aef5d4909 100644
--- a/nerfstudio/scripts/render.py
+++ b/nerfstudio/scripts/render.py
@@ -21,6 +21,7 @@ from __future__ import annotations
import json
import os
import struct
+import shutil
import sys
from contextlib import ExitStack
from dataclasses import dataclass, field
@@ -59,6 +60,7 @@ from nerfstudio.pipelines.base_pipeline import Pipeline
from nerfstudio.utils import colormaps, install_checks
from nerfstudio.utils.eval_utils import eval_setup
from nerfstudio.utils.rich_utils import CONSOLE, ItersPerSecColumn
+from nerfstudio.utils.scripts import run_command
def _render_trajectory_video(
@@ -342,6 +344,22 @@ class RenderCameraPath(BaseRender):
crop_data = get_crop_from_json(camera_path)
camera_path = get_path_from_json(camera_path)
+ if camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value:
+ # temp folder for writing left and right view renders
+ temp_folder_path = self.output_path.parent / (self.output_path.stem + "_temp")
+
+ Path(temp_folder_path).mkdir(parents=True, exist_ok=True)
+ left_eye_path = temp_folder_path / "ods_render_Left.mp4"
+
+ self.output_path = left_eye_path
+
+ CONSOLE.print("[bold green]:goggles: Omni-directional Stereo VR :goggles:")
+ CONSOLE.print("Rendering left eye view")
+
+ # add mp4 suffix to video output if none is specified
+ if self.output_format == "video" and str(self.output_path.suffix) == "":
+ self.output_path = self.output_path.with_suffix(".mp4")
+
_render_trajectory_video(
pipeline,
camera_path,
@@ -356,6 +374,51 @@ class RenderCameraPath(BaseRender):
colormap_options=self.colormap_options,
)
+ if camera_path.camera_type[0] == CameraType.OMNIDIRECTIONALSTEREO_L.value:
+ # declare paths for left and right renders
+
+ left_eye_path = self.output_path
+ right_eye_path = left_eye_path.parent / "ods_render_Right.mp4"
+
+ self.output_path = right_eye_path
+ camera_path.camera_type[0] = CameraType.OMNIDIRECTIONALSTEREO_R.value
+
+ CONSOLE.print("Rendering right eye view")
+ _render_trajectory_video(
+ pipeline,
+ camera_path,
+ output_filename=self.output_path,
+ rendered_output_names=self.rendered_output_names,
+ rendered_resolution_scaling_factor=1.0 / self.downscale_factor,
+ crop_data=crop_data,
+ seconds=seconds,
+ output_format=self.output_format,
+ image_format=self.image_format,
+ jpeg_quality=self.jpeg_quality,
+ colormap_options=self.colormap_options,
+ )
+
+ # stack the left and right eye renders for final output
+ self.output_path = Path(str(left_eye_path.parent)[:-5] + ".mp4")
+ ffmpeg_ods_command = ""
+ if self.output_format == "video":
+ ffmpeg_ods_command = f'ffmpeg -y -i "{left_eye_path}" -i "{right_eye_path}" -filter_complex "[0:v]pad=iw:2*ih[int];[int][1:v]overlay=0:h" -c:v libx264 -crf 23 -preset veryfast "{self.output_path}"'
+ run_command(ffmpeg_ods_command, verbose=False)
+ if self.output_format == "images":
+ # create a folder for the stacked renders
+ self.output_path = Path(str(left_eye_path.parent)[:-5])
+ self.output_path.mkdir(parents=True, exist_ok=True)
+ if self.image_format == "png":
+ ffmpeg_ods_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.png")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.png")}" -filter_complex vstack -start_number 0 "{str(self.output_path)+"//%05d.png"}"'
+ elif self.image_format == "jpeg":
+ ffmpeg_ods_command = f'ffmpeg -y -pattern_type glob -i "{str(left_eye_path.with_suffix("") / "*.jpg")}" -pattern_type glob -i "{str(right_eye_path.with_suffix("") / "*.jpg")}" -filter_complex vstack -start_number 0 "{str(self.output_path)+"//%05d.jpg"}"'
+ run_command(ffmpeg_ods_command, verbose=False)
+
+ # remove the temp files directory
+ if str(left_eye_path.parent)[-5:] == "_temp":
+ shutil.rmtree(left_eye_path.parent, ignore_errors=True)
+ CONSOLE.print("[bold green]Final ODS Render Complete")
+
@dataclass
class RenderInterpolated(BaseRender):
diff --git a/nerfstudio/scripts/train.py b/nerfstudio/scripts/train.py
index bc6617212..9ca18c71a 100644
--- a/nerfstudio/scripts/train.py
+++ b/nerfstudio/scripts/train.py
@@ -49,7 +49,7 @@ import random
import socket
import traceback
from datetime import timedelta
-from typing import Any, Callable, Optional
+from typing import Any, Callable, Literal, Optional
import numpy as np
import torch
@@ -104,11 +104,12 @@ def _distributed_worker(
local_rank: int,
main_func: Callable,
world_size: int,
- num_gpus_per_machine: int,
+ num_devices_per_machine: int,
machine_rank: int,
dist_url: str,
config: TrainerConfig,
timeout: timedelta = DEFAULT_TIMEOUT,
+ device_type: Literal["cpu", "cuda", "mps"] = "cuda",
) -> Any:
"""Spawned distributed worker that handles the initialization of process group and handles the
training process on multiple processes.
@@ -117,7 +118,7 @@ def _distributed_worker(
local_rank: Current rank of process.
main_func: Function that will be called by the distributed workers.
world_size: Total number of gpus available.
- num_gpus_per_machine: Number of GPUs per machine.
+ num_devices_per_machine: Number of GPUs per machine.
machine_rank: Rank of this machine.
dist_url: URL to connect to for distributed jobs, including protocol
E.g., "tcp://127.0.0.1:8686".
@@ -132,24 +133,24 @@ def _distributed_worker(
Any: TODO: determine the return type
"""
assert torch.cuda.is_available(), "cuda is not available. Please check your installation."
- global_rank = machine_rank * num_gpus_per_machine + local_rank
+ global_rank = machine_rank * num_devices_per_machine + local_rank
dist.init_process_group(
- backend="nccl",
+ backend="nccl" if device_type == "cuda" else "gloo",
init_method=dist_url,
world_size=world_size,
rank=global_rank,
timeout=timeout,
)
assert comms.LOCAL_PROCESS_GROUP is None
- num_machines = world_size // num_gpus_per_machine
+ num_machines = world_size // num_devices_per_machine
for i in range(num_machines):
- ranks_on_i = list(range(i * num_gpus_per_machine, (i + 1) * num_gpus_per_machine))
+ ranks_on_i = list(range(i * num_devices_per_machine, (i + 1) * num_devices_per_machine))
pg = dist.new_group(ranks_on_i)
if i == machine_rank:
comms.LOCAL_PROCESS_GROUP = pg
- assert num_gpus_per_machine <= torch.cuda.device_count()
+ assert num_devices_per_machine <= torch.cuda.device_count()
output = main_func(local_rank, world_size, config, global_rank)
comms.synchronize()
dist.destroy_process_group()
@@ -158,29 +159,32 @@ def _distributed_worker(
def launch(
main_func: Callable,
- num_gpus_per_machine: int,
+ num_devices_per_machine: int,
num_machines: int = 1,
machine_rank: int = 0,
dist_url: str = "auto",
config: Optional[TrainerConfig] = None,
timeout: timedelta = DEFAULT_TIMEOUT,
+ device_type: Literal["cpu", "cuda", "mps"] = "cuda",
) -> None:
"""Function that spawns multiple processes to call on main_func
Args:
main_func (Callable): function that will be called by the distributed workers
- num_gpus_per_machine (int): number of GPUs per machine
+ num_devices_per_machine (int): number of GPUs per machine
num_machines (int, optional): total number of machines
machine_rank (int, optional): rank of this machine.
dist_url (str, optional): url to connect to for distributed jobs.
config (TrainerConfig, optional): config file specifying training regimen.
timeout (timedelta, optional): timeout of the distributed workers.
+ device_type: type of device to use for training.
"""
assert config is not None
- world_size = num_machines * num_gpus_per_machine
- if world_size <= 1:
- # world_size=0 uses one CPU in one process.
- # world_size=1 uses one GPU in one process.
+ world_size = num_machines * num_devices_per_machine
+ if world_size == 0:
+ raise ValueError("world_size cannot be 0")
+ elif world_size == 1:
+ # uses one process
try:
main_func(local_rank=0, world_size=world_size, config=config)
except KeyboardInterrupt:
@@ -199,17 +203,9 @@ def launch(
process_context = mp.spawn(
_distributed_worker,
- nprocs=num_gpus_per_machine,
+ nprocs=num_devices_per_machine,
join=False,
- args=(
- main_func,
- world_size,
- num_gpus_per_machine,
- machine_rank,
- dist_url,
- config,
- timeout,
- ),
+ args=(main_func, world_size, num_devices_per_machine, machine_rank, dist_url, config, timeout, device_type),
)
# process_context won't be None because join=False, so it's okay to assert this
# for Pylance reasons
@@ -249,7 +245,8 @@ def main(config: TrainerConfig) -> None:
launch(
main_func=train_loop,
- num_gpus_per_machine=config.machine.num_gpus,
+ num_devices_per_machine=config.machine.num_devices,
+ device_type=config.machine.device_type,
num_machines=config.machine.num_machines,
machine_rank=config.machine.machine_rank,
dist_url=config.machine.dist_url,
diff --git a/nerfstudio/utils/printing.py b/nerfstudio/utils/printing.py
index 859a3dc1b..1fc4e99a8 100644
--- a/nerfstudio/utils/printing.py
+++ b/nerfstudio/utils/printing.py
@@ -19,10 +19,10 @@ from math import floor, log
from nerfstudio.utils.rich_utils import CONSOLE
-def print_tcnn_speed_warning(method_name: str):
+def print_tcnn_speed_warning(module_name: str):
"""Prints a warning about the speed of the TCNN."""
CONSOLE.line()
- CONSOLE.print(f"[bold yellow]WARNING: Using a slow implementation of {method_name}. ")
+ CONSOLE.print(f"[bold yellow]WARNING: Using a slow implementation for the {module_name} module. ")
CONSOLE.print(
"[bold yellow]:person_running: :person_running: "
+ "Install tcnn for speedups :person_running: :person_running:"
diff --git a/nerfstudio/utils/writer.py b/nerfstudio/utils/writer.py
index cc12c9efc..8d3b07b1a 100644
--- a/nerfstudio/utils/writer.py
+++ b/nerfstudio/utils/writer.py
@@ -320,7 +320,7 @@ class WandbWriter(Writer):
Args:
config: config dictionary to write out
"""
- wandb.config.update(config_dict)
+ wandb.config.update(config_dict, allow_val_change=True)
@decorate_all([check_main_thread])
diff --git a/nerfstudio/viewer_beta/control_panel.py b/nerfstudio/viewer_beta/control_panel.py
new file mode 100644
index 000000000..ea0492eb2
--- /dev/null
+++ b/nerfstudio/viewer_beta/control_panel.py
@@ -0,0 +1,369 @@
+# Copyright 2022 the Regents of the University of California, Nerfstudio Team and contributors. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+""" Control panel for the viewer """
+from collections import defaultdict
+from typing import Callable, DefaultDict, List, Tuple, get_args
+
+import torch
+from viser import ViserServer
+
+from nerfstudio.utils.colormaps import ColormapOptions, Colormaps
+from nerfstudio.viewer_beta.viewer_elements import ( # ViewerButtonGroup,
+ ViewerButtonGroup,
+ ViewerCheckbox,
+ ViewerDropdown,
+ ViewerElement,
+ ViewerNumber,
+ ViewerRGB,
+ ViewerSlider,
+ ViewerVec3,
+)
+
+
+class ControlPanel:
+ """
+ Initializes the control panel with all the elements
+ Args:
+ time_enabled: whether or not the time slider should be enabled
+ rerender_cb: a callback that will be called when the user changes a parameter that requires a rerender
+ (eg train speed, max res, etc)
+ crop_update_cb: a callback that will be called when the user changes the crop parameters
+ update_output_cb: a callback that will be called when the user changes the output render
+ """
+
+ def __init__(
+ self,
+ viser_server: ViserServer,
+ time_enabled: bool,
+ rerender_cb: Callable,
+ crop_update_cb: Callable,
+ update_output_cb: Callable,
+ update_split_output_cb: Callable,
+ ):
+ # elements holds a mapping from tag: [elements]
+ self.viser_server = viser_server
+ self._elements_by_tag: DefaultDict[str, List[ViewerElement]] = defaultdict(lambda: [])
+
+ self._train_speed = ViewerButtonGroup(
+ name="Train Speed ",
+ default_value="Balanced",
+ options=["Slow", "Balanced", "Fast"],
+ cb_hook=lambda han: self._train_speed_cb(),
+ )
+ self._output_render = ViewerDropdown(
+ "Output Render",
+ "not set",
+ ["not set"],
+ cb_hook=lambda han: [self.update_control_panel(), update_output_cb(han), rerender_cb(han)],
+ hint="The output to render",
+ )
+ self._colormap = ViewerDropdown[Colormaps](
+ "Colormap", "default", ["default"], cb_hook=rerender_cb, hint="The colormap to use"
+ )
+ self._invert = ViewerCheckbox("Invert", False, cb_hook=rerender_cb, hint="Invert the colormap")
+ self._normalize = ViewerCheckbox("Normalize", True, cb_hook=rerender_cb, hint="Normalize the colormap")
+ self._min = ViewerNumber("Min", 0.0, cb_hook=rerender_cb, hint="Min value of the colormap")
+ self._max = ViewerNumber("Max", 1.0, cb_hook=rerender_cb, hint="Max value of the colormap")
+
+ self._split = ViewerCheckbox(
+ "Enable",
+ False,
+ cb_hook=lambda han: [self.update_control_panel(), rerender_cb(han)],
+ hint="Render two outputs",
+ )
+ self._split_percentage = ViewerSlider(
+ "Split Percentage", 0.5, 0.0, 1.0, 0.01, cb_hook=rerender_cb, hint="Where to split"
+ )
+ self._split_output_render = ViewerDropdown(
+ "Output Render Split",
+ "not set",
+ ["not set"],
+ cb_hook=lambda han: [self.update_control_panel(), update_split_output_cb(han), rerender_cb(han)],
+ hint="The second output",
+ )
+ # Hack: spaces are after at the end of the names to make them unique
+ self._split_colormap = ViewerDropdown[Colormaps](
+ "Colormap ", "default", ["default"], cb_hook=rerender_cb, hint="Colormap of the second output"
+ )
+ self._split_invert = ViewerCheckbox(
+ "Invert ", False, cb_hook=rerender_cb, hint="Invert the colormap of the second output"
+ )
+ self._split_normalize = ViewerCheckbox(
+ "Normalize ", True, cb_hook=rerender_cb, hint="Normalize the colormap of the second output"
+ )
+ self._split_min = ViewerNumber(
+ "Min ", 0.0, cb_hook=rerender_cb, hint="Min value of the colormap of the second output"
+ )
+ self._split_max = ViewerNumber(
+ "Max ", 1.0, cb_hook=rerender_cb, hint="Max value of the colormap of the second output"
+ )
+
+ self._train_util = ViewerSlider(
+ "Train Util",
+ default_value=0.85,
+ min_value=0.0,
+ max_value=1,
+ step=0.05,
+ hint="Target training utilization, 0.0 is slow, 1.0 is fast. Doesn't affect final render quality",
+ )
+ self._max_res = ViewerSlider(
+ "Max Res", 512, 64, 2048, 100, cb_hook=rerender_cb, hint="Maximum resolution to render in viewport"
+ )
+ self._crop_viewport = ViewerCheckbox(
+ "Enable ",
+ False,
+ cb_hook=lambda han: [self.update_control_panel(), crop_update_cb(han), rerender_cb(han)],
+ hint="Crop the scene to a specified box",
+ )
+ self._background_color = ViewerRGB(
+ "Background color", (38, 42, 55), cb_hook=crop_update_cb, hint="Color of the background"
+ )
+ self._crop_min = ViewerVec3(
+ "Crop Min", (-1, -1, -1), 0.05, cb_hook=crop_update_cb, hint="Minimum value of the crop"
+ )
+ self._crop_max = ViewerVec3(
+ "Crop Max", (1, 1, 1), 0.05, cb_hook=crop_update_cb, hint="Maximum value of the crop"
+ )
+ self._time = ViewerSlider("Time", 0.0, 0.0, 1.0, 0.01, cb_hook=rerender_cb, hint="Time to render")
+ self._time_enabled = time_enabled
+
+ self.add_element(self._train_speed)
+ self.add_element(self._train_util)
+ with self.viser_server.gui_folder("Render Options"):
+ self.add_element(self._max_res)
+ self.add_element(self._output_render)
+ self.add_element(self._colormap)
+ # colormap options
+ with self.viser_server.gui_folder(" "):
+ self.add_element(self._invert, additional_tags=("colormap",))
+ self.add_element(self._normalize, additional_tags=("colormap",))
+ self.add_element(self._min, additional_tags=("colormap",))
+ self.add_element(self._max, additional_tags=("colormap",))
+
+ # split options
+ with self.viser_server.gui_folder("Split Screen"):
+ self.add_element(self._split)
+
+ self.add_element(self._split_percentage, additional_tags=("split",))
+ self.add_element(self._split_output_render, additional_tags=("split",))
+ self.add_element(self._split_colormap, additional_tags=("split",))
+ with self.viser_server.gui_folder(" "):
+ self.add_element(self._split_invert, additional_tags=("split_colormap",))
+ self.add_element(self._split_normalize, additional_tags=("split_colormap",))
+ self.add_element(self._split_min, additional_tags=("split_colormap",))
+ self.add_element(self._split_max, additional_tags=("split_colormap",))
+
+ with self.viser_server.gui_folder("Crop Viewport"):
+ self.add_element(self._crop_viewport)
+
+ # Crop options
+ self.add_element(self._background_color, additional_tags=("crop",))
+ self.add_element(self._crop_min, additional_tags=("crop",))
+ self.add_element(self._crop_max, additional_tags=("crop",))
+
+ self.add_element(self._time, additional_tags=("time",))
+
+ def _train_speed_cb(self) -> None:
+ pass
+
+ """Callback for when the train speed is changed"""
+ if self._train_speed.value == "Fast":
+ self._train_util.value = 0.95
+ self._max_res.value = 256
+ elif self._train_speed.value == "Balanced":
+ self._train_util.value = 0.85
+ self._max_res.value = 512
+ elif self._train_speed.value == "Slow":
+ self._train_util.value = 0.5
+ self._max_res.value = 1024
+
+ def update_output_options(self, new_options: List[str]):
+ """
+ Args:
+ new_options: a list of new output options
+ """
+ self._output_render.set_options(new_options)
+ self._split_output_render.set_options(new_options)
+ self._split_output_render.value = new_options[-1]
+
+ def add_element(self, e: ViewerElement, additional_tags: Tuple[str] = tuple()) -> None:
+ """Adds an element to the control panel
+
+ Args:
+ e: the element to add
+ additional_tags: additional tags to add to the element for selection
+ """
+ self._elements_by_tag["all"].append(e)
+ for t in additional_tags:
+ self._elements_by_tag[t].append(e)
+ e.install(self.viser_server)
+
+ def update_control_panel(self) -> None:
+ """
+ Sets elements to be hidden or not based on the current state of the control panel
+ """
+ self._colormap.set_disabled(self.output_render == "rgb")
+ for e in self._elements_by_tag["colormap"]:
+ e.set_hidden(self.output_render == "rgb")
+ for e in self._elements_by_tag["split_colormap"]:
+ e.set_hidden(not self._split.value or self.split_output_render == "rgb")
+ for e in self._elements_by_tag["crop"]:
+ e.set_hidden(not self.crop_viewport)
+ self._time.set_hidden(not self._time_enabled)
+ self._split_percentage.set_hidden(not self._split.value)
+ self._split_output_render.set_hidden(not self._split.value)
+ self._split_colormap.set_hidden(not self._split.value)
+ self._split_colormap.set_disabled(self.split_output_render == "rgb")
+
+ def update_colormap_options(self, dimensions: int, dtype: type) -> None:
+ """update the colormap options based on the current render
+
+ Args:
+ dimensions: the number of dimensions of the render
+ dtype: the data type of the render
+ """
+ self._colormap.set_options(_get_colormap_options(dimensions, dtype))
+
+ def update_split_colormap_options(self, dimensions: int, dtype: type) -> None:
+ """update the split colormap options based on the current render
+
+ Args:
+ dimensions: the number of dimensions of the render
+ dtype: the data type of the render
+ """
+ self._split_colormap.set_options(_get_colormap_options(dimensions, dtype))
+
+ @property
+ def output_render(self) -> str:
+ """Returns the current output render"""
+ return self._output_render.value
+
+ @property
+ def split_output_render(self) -> str:
+ """Returns the current output for the split render"""
+ return self._split_output_render.value
+
+ @property
+ def split(self) -> bool:
+ """Returns whether the split is enabled"""
+ return self._split.value
+
+ @property
+ def split_percentage(self) -> float:
+ """Returns the percentage of the screen to split"""
+ return self._split_percentage.value
+
+ @property
+ def train_util(self) -> float:
+ """Returns the current train util setting"""
+ return self._train_util.value
+
+ @property
+ def max_res(self) -> int:
+ """Returns the current max res setting"""
+ return self._max_res.value
+
+ @property
+ def crop_viewport(self) -> bool:
+ """Returns the current crop viewport setting"""
+ return self._crop_viewport.value
+
+ @crop_viewport.setter
+ def crop_viewport(self, value: bool):
+ """Sets the crop viewport setting"""
+ self._crop_viewport.value = value
+
+ @property
+ def crop_min(self) -> Tuple[float, float, float]:
+ """Returns the current crop min setting"""
+ return self._crop_min.value
+
+ @crop_min.setter
+ def crop_min(self, value: Tuple[float, float, float]):
+ """Sets the crop min setting"""
+ self._crop_min.value = value
+
+ @property
+ def crop_max(self) -> Tuple[float, float, float]:
+ """Returns the current crop max setting"""
+ return self._crop_max.value
+
+ @crop_max.setter
+ def crop_max(self, value: Tuple[float, float, float]):
+ """Sets the crop max setting"""
+ self._crop_max.value = value
+
+ @property
+ def background_color(self) -> Tuple[int, int, int]:
+ """Returns the current background color"""
+ return self._background_color.value
+
+ @background_color.setter
+ def background_color(self, value: Tuple[int, int, int]):
+ """Sets the background color"""
+ self._background_color.value = value
+
+ @property
+ def time(self) -> float:
+ """Returns the current background color"""
+ return self._time.value
+
+ @time.setter
+ def time(self, value: float):
+ """Sets the background color"""
+ self._time.value = value
+
+ @property
+ def colormap_options(self) -> ColormapOptions:
+ """Returns the current colormap options"""
+ return ColormapOptions(
+ colormap=self._colormap.value,
+ normalize=self._normalize.value,
+ colormap_min=self._min.value,
+ colormap_max=self._max.value,
+ invert=self._invert.value,
+ )
+
+ @property
+ def split_colormap_options(self) -> ColormapOptions:
+ """Returns the current colormap options"""
+ return ColormapOptions(
+ colormap=self._split_colormap.value,
+ normalize=self._split_normalize.value,
+ colormap_min=self._split_min.value,
+ colormap_max=self._split_max.value,
+ invert=self._split_invert.value,
+ )
+
+
+def _get_colormap_options(dimensions: int, dtype: type) -> List[Colormaps]:
+ """
+ Given the number of dimensions and data type, returns a list of available colormap options
+ to use with the visualize() function.
+
+ Args:
+ dimensions: the number of dimensions of the render
+ dtype: the data type of the render
+ Returns:
+ a list of available colormap options
+ """
+ colormap_options: List[Colormaps] = []
+ if dimensions == 3:
+ colormap_options = ["default"]
+ if dimensions == 1 and dtype in [torch.float64, torch.float32, torch.float16, torch.bfloat16]:
+ colormap_options = [c for c in list(get_args(Colormaps)) if c != "default"]
+ if dimensions > 3:
+ colormap_options = ["pca"]
+ return colormap_options
diff --git a/nerfstudio/viewer_beta/render_state_machine.py b/nerfstudio/viewer_beta/render_state_machine.py
index f2323b1d8..d18200761 100644
--- a/nerfstudio/viewer_beta/render_state_machine.py
+++ b/nerfstudio/viewer_beta/render_state_machine.py
@@ -22,13 +22,15 @@ from typing import TYPE_CHECKING, Any, Dict, Literal, Optional, Tuple, get_args
import torch
-from nerfstudio.utils import writer
+from nerfstudio.model_components.renderers import background_color_override_context
+from nerfstudio.utils import colormaps, writer
from nerfstudio.utils.writer import GLOBAL_BUFFER, EventName, TimeWriter
from nerfstudio.viewer.server import viewer_utils
+from nerfstudio.viewer_beta import utils
from nerfstudio.viewer_beta.utils import CameraState, get_camera
if TYPE_CHECKING:
- from nerfstudio.viewer_beta.viewer_state import ViewerState
+ from nerfstudio.viewer_beta.viewer import Viewer
RenderStates = Literal["low_move", "low_static", "high"]
RenderActions = Literal["rerender", "move", "static", "step"]
@@ -52,7 +54,7 @@ class RenderStateMachine(threading.Thread):
viewer: the viewer state
"""
- def __init__(self, viewer: ViewerState):
+ def __init__(self, viewer: Viewer):
threading.Thread.__init__(self)
self.transitions: Dict[RenderStates, Dict[RenderActions, RenderStates]] = {
s: {} for s in get_args(RenderStates)
@@ -111,6 +113,14 @@ class RenderStateMachine(threading.Thread):
camera_state: the current camera state
"""
+ # initialize the camera ray bundle
+ utils.update_render_aabb(
+ crop_viewport=self.viewer.control_panel.crop_viewport,
+ crop_min=self.viewer.control_panel.crop_min,
+ crop_max=self.viewer.control_panel.crop_max,
+ model=self.viewer.get_model(),
+ )
+
image_height, image_width = self._calculate_image_res(camera_state.aspect)
camera = get_camera(camera_state, image_height, image_width)
@@ -123,8 +133,20 @@ class RenderStateMachine(threading.Thread):
with TimeWriter(None, None, write=False) as vis_t:
self.viewer.get_model().eval()
step = self.viewer.step
- with torch.no_grad():
- outputs = self.viewer.get_model().get_outputs_for_camera_ray_bundle(camera_ray_bundle)
+ if self.viewer.control_panel.crop_viewport:
+ color = self.viewer.control_panel.background_color
+ if color is None:
+ background_color = torch.tensor([0.0, 0.0, 0.0], device=self.viewer.pipeline.model.device)
+ else:
+ background_color = torch.tensor(
+ [color[0] / 255.0, color[1] / 255.0, color[2] / 255.0],
+ device=self.viewer.get_model().device,
+ )
+ with background_color_override_context(background_color), torch.no_grad():
+ outputs = self.viewer.get_model().get_outputs_for_camera_ray_bundle(camera_ray_bundle)
+ else:
+ with torch.no_grad():
+ outputs = self.viewer.get_model().get_outputs_for_camera_ray_bundle(camera_ray_bundle)
self.viewer.get_model().train()
num_rays = len(camera_ray_bundle)
render_time = vis_t.duration
@@ -173,7 +195,37 @@ class RenderStateMachine(threading.Thread):
Args:
outputs: the dictionary of outputs to choose from, from the model
"""
- selected_output = (outputs["rgb"] * 255).type(torch.uint8)
+ output_keys = set(outputs.keys())
+ if self.output_keys != output_keys:
+ self.output_keys = output_keys
+ self.viewer.control_panel.update_output_options(list(outputs.keys()))
+
+ output_render = self.viewer.control_panel.output_render
+ self.viewer.update_colormap_options(
+ dimensions=outputs[output_render].shape[-1], dtype=outputs[output_render].dtype
+ )
+ selected_output = colormaps.apply_colormap(
+ image=outputs[self.viewer.control_panel.output_render],
+ colormap_options=self.viewer.control_panel.colormap_options,
+ )
+
+ if self.viewer.control_panel.split:
+ split_output_render = self.viewer.control_panel.split_output_render
+ self.viewer.update_split_colormap_options(
+ dimensions=outputs[split_output_render].shape[-1], dtype=outputs[split_output_render].dtype
+ )
+ split_output = colormaps.apply_colormap(
+ image=outputs[self.viewer.control_panel.split_output_render],
+ colormap_options=self.viewer.control_panel.split_colormap_options,
+ )
+ split_index = min(
+ int(self.viewer.control_panel.split_percentage * selected_output.shape[1]),
+ selected_output.shape[1] - 1,
+ )
+ selected_output = torch.cat([selected_output[:, :split_index], split_output[:, split_index:]], dim=1)
+ selected_output[:, split_index] = torch.tensor([0.133, 0.157, 0.192], device=selected_output.device)
+
+ selected_output = (selected_output * 255).type(torch.uint8)
self.viewer.viser_server.set_background_image(
selected_output.cpu().numpy(),
@@ -190,7 +242,7 @@ class RenderStateMachine(threading.Thread):
image_height: the maximum image height that can be rendered in the time budget
image_width: the maximum image width that can be rendered in the time budget
"""
- max_res = self.viewer.max_res
+ max_res = self.viewer.control_panel.max_res
if self.state == "high":
# high res is always static
image_height = max_res
diff --git a/nerfstudio/viewer_beta/utils.py b/nerfstudio/viewer_beta/utils.py
index 77f4e198f..0dd435b88 100644
--- a/nerfstudio/viewer_beta/utils.py
+++ b/nerfstudio/viewer_beta/utils.py
@@ -13,13 +13,15 @@
# limitations under the License.
from dataclasses import dataclass
-from typing import Optional, Union
+from typing import Optional, Tuple, Union
import numpy as np
import torch
from jaxtyping import Float
from nerfstudio.cameras.cameras import Cameras, CameraType
+from nerfstudio.data.scene_box import SceneBox
+from nerfstudio.models.base_model import Model
@dataclass
@@ -65,3 +67,29 @@ def get_camera(
times=torch.tensor([0.0], dtype=torch.float32),
)
return camera
+
+
+def update_render_aabb(
+ crop_viewport: bool, crop_min: Tuple[float, float, float], crop_max: Tuple[float, float, float], model: Model
+):
+ """
+ update the render aabb box for the viewer:
+
+ Args:
+ crop_viewport: whether to crop the viewport
+ crop_min: min of the crop box
+ crop_max: max of the crop box
+ model: the model to render
+ """
+
+ if crop_viewport:
+ crop_min_tensor = torch.tensor(crop_min, dtype=torch.float32)
+ crop_max_tensor = torch.tensor(crop_max, dtype=torch.float32)
+
+ if isinstance(model.render_aabb, SceneBox):
+ model.render_aabb.aabb[0] = crop_min_tensor
+ model.render_aabb.aabb[1] = crop_max_tensor
+ else:
+ model.render_aabb = SceneBox(aabb=torch.stack([crop_min_tensor, crop_max_tensor], dim=0))
+ else:
+ model.render_aabb = None
diff --git a/nerfstudio/viewer_beta/viewer_state.py b/nerfstudio/viewer_beta/viewer.py
similarity index 73%
rename from nerfstudio/viewer_beta/viewer_state.py
rename to nerfstudio/viewer_beta/viewer.py
index 115ff6f9a..f4e8d3429 100644
--- a/nerfstudio/viewer_beta/viewer_state.py
+++ b/nerfstudio/viewer_beta/viewer.py
@@ -32,6 +32,7 @@ from nerfstudio.pipelines.base_pipeline import Pipeline
from nerfstudio.utils.decorators import check_main_thread, decorate_all
from nerfstudio.utils.writer import GLOBAL_BUFFER, EventName
from nerfstudio.viewer.server import viewer_utils
+from nerfstudio.viewer_beta.control_panel import ControlPanel
from nerfstudio.viewer_beta.render_state_machine import RenderAction, RenderStateMachine
from nerfstudio.viewer_beta.utils import CameraState
@@ -42,7 +43,7 @@ VISER_NERFSTUDIO_SCALE_RATIO: int = 10
@decorate_all([check_main_thread])
-class ViewerState:
+class Viewer:
"""Class to hold state for viewer variables
Args:
@@ -54,9 +55,12 @@ class ViewerState:
Attributes:
viewer_url: url to open viewer
+ viser_server: the viser server
"""
viewer_url: str
+ viser_server: viser.ViserServer
+ camera_state: Optional[CameraState] = None
def __init__(
self,
@@ -74,6 +78,7 @@ class ViewerState:
self.pipeline = pipeline
self.log_filename = log_filename
self.datapath = datapath.parent if datapath.is_file() else datapath
+ self.include_time = self.pipeline.datamanager.includes_time
if self.config.websocket_port is None:
websocket_port = viewer_utils.get_free_port(default_port=self.config.websocket_port_default)
@@ -94,12 +99,19 @@ class ViewerState:
self.viser_server = viser.ViserServer(host=config.websocket_host, port=websocket_port)
- self.render_statemachine = RenderStateMachine(self)
- self.render_statemachine.start()
-
self.viser_server.on_client_connect(self.handle_new_client)
- self.camera_state: Optional[CameraState] = None
+ self.control_panel = ControlPanel(
+ self.viser_server,
+ self.include_time,
+ self._interrupt_render,
+ self._crop_params_update,
+ self._output_type_change,
+ self._output_split_type_change,
+ )
+
+ self.render_statemachine = RenderStateMachine(self)
+ self.render_statemachine.start()
def handle_new_client(self, client: viser.ClientHandle) -> None:
@client.camera.on_update
@@ -112,6 +124,35 @@ class ViewerState:
self.camera_state = CameraState(fov=client.camera.fov, aspect=client.camera.aspect, c2w=c2w)
self.render_statemachine.action(RenderAction("move", self.camera_state))
+ def _interrupt_render(self, _) -> None:
+ """Interrupt current render."""
+ if self.camera_message is not None:
+ self.render_statemachine.action(RenderAction("rerender", self.camera_message))
+
+ def _crop_params_update(self, _) -> None:
+ """Update crop parameters"""
+ print("Crop params not set up")
+ # crop_min = torch.tensor(self.control_panel.crop_min, dtype=torch.float32)
+ # crop_max = torch.tensor(self.control_panel.crop_max, dtype=torch.float32)
+ # scene_box = SceneBox(aabb=torch.stack([crop_min, crop_max], dim=0))
+ # self.viser_server.update_scene_box(scene_box)
+ # crop_scale = crop_max - crop_min
+ # crop_center = (crop_max + crop_min) / 2.0
+ # self.viser_server.send_crop_params(
+ # crop_enabled=self.control_panel.crop_viewport,
+ # crop_bg_color=self.control_panel.background_color,
+ # crop_scale=tuple(crop_scale.tolist()),
+ # crop_center=tuple(crop_center.tolist()),
+ # )
+ # if self.camera_message is not None:
+ # self.render_statemachine.action(RenderAction("rerender", self.camera_message))
+
+ def _output_type_change(self, _):
+ self.output_type_changed = True
+
+ def _output_split_type_change(self, _):
+ self.output_split_type_changed = True
+
def _pick_drawn_image_idxs(self, total_num: int) -> list[int]:
"""Determine indicies of images to display in viewer.
@@ -161,7 +202,6 @@ class ViewerState:
self.train_state = train_state
self.train_util = 0.9
- self.max_res = 512
def update_scene(self, step: int, num_rays_per_batch: Optional[int] = None) -> None:
"""updates the scene based on the graph weights
@@ -183,7 +223,7 @@ class ViewerState:
train_s = GLOBAL_BUFFER["events"][EventName.TRAIN_RAYS_PER_SEC.value]["avg"]
vis_s = GLOBAL_BUFFER["events"][EventName.VIS_RAYS_PER_SEC.value]["avg"]
train_util = self.train_util
- vis_n = self.max_res**2
+ vis_n = self.control_panel.max_res**2
train_n = num_rays_per_batch
train_time = train_n / train_s
vis_time = vis_n / vis_s
@@ -195,6 +235,28 @@ class ViewerState:
self.last_step = step
self.render_statemachine.action(RenderAction("step", self.camera_state))
+ def update_colormap_options(self, dimensions: int, dtype: type) -> None:
+ """update the colormap options based on the current render
+
+ Args:
+ dimensions: the number of dimensions of the render
+ dtype: the data type of the render
+ """
+ if self.output_type_changed:
+ self.control_panel.update_colormap_options(dimensions, dtype)
+ self.output_type_changed = False
+
+ def update_split_colormap_options(self, dimensions: int, dtype: type) -> None:
+ """update the colormap options based on the current render
+
+ Args:
+ dimensions: the number of dimensions of the render
+ dtype: the data type of the render
+ """
+ if self.output_split_type_changed:
+ self.control_panel.update_split_colormap_options(dimensions, dtype)
+ self.output_split_type_changed = False
+
def get_model(self) -> Model:
"""Returns the model."""
return self.pipeline.model
diff --git a/nerfstudio/viewer_beta/viewer_elements.py b/nerfstudio/viewer_beta/viewer_elements.py
new file mode 100644
index 000000000..5fbfc8598
--- /dev/null
+++ b/nerfstudio/viewer_beta/viewer_elements.py
@@ -0,0 +1,440 @@
+# Copyright 2022 the Regents of the University of California, Nerfstudio Team and contributors. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+""" Viewer GUI elements for the nerfstudio viewer """
+
+
+from __future__ import annotations
+
+from abc import abstractmethod
+from typing import Any, Callable, Generic, List, Optional, Tuple, Union
+
+from typing_extensions import LiteralString, TypeVar
+from viser import (
+ GuiButtonGroupHandle,
+ GuiButtonHandle,
+ GuiDropdownHandle,
+ GuiHandle,
+ ViserServer,
+)
+
+TValue = TypeVar("TValue")
+TString = TypeVar("TString", default=str, bound=str)
+
+
+class ViewerElement(Generic[TValue]):
+ """Base class for all viewer elements
+
+ Args:
+ name: The name of the element
+ disabled: If the element is disabled
+ """
+
+ def __init__(
+ self,
+ name: str,
+ disabled: bool = False,
+ cb_hook: Callable = lambda element: None,
+ ) -> None:
+ self.name = name
+ self.gui_handle: Optional[Union[GuiHandle[TValue], GuiButtonHandle, GuiButtonGroupHandle]] = None
+ self.disabled = disabled
+ self.cb_hook = cb_hook
+
+ @abstractmethod
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ """
+ Returns the GuiHandle object which actually controls the parameter in the gui.
+
+ Args:
+ viser_server: The server to install the gui element into.
+ """
+ ...
+
+ def remove(self) -> None:
+ """Removes the gui element from the viewer"""
+ if self.gui_handle is not None:
+ self.gui_handle.remove()
+ self.gui_handle = None
+
+ def set_hidden(self, hidden: bool) -> None:
+ """Sets the hidden state of the gui element"""
+ assert self.gui_handle is not None
+ self.gui_handle.visible = not hidden
+
+ def set_disabled(self, disabled: bool) -> None:
+ """Sets the disabled state of the gui element"""
+ assert self.gui_handle is not None
+ self.gui_handle.disabled = disabled
+
+ @abstractmethod
+ def install(self, viser_server: ViserServer) -> None:
+ """Installs the gui element into the given viser_server"""
+ ...
+
+
+class ViewerButton(ViewerElement[bool]):
+ """A button in the viewer
+
+ Args:
+ name: The name of the button
+ cb_hook: The function to call when the button is pressed
+ disabled: If the button is disabled
+ """
+
+ gui_handle: GuiButtonHandle
+
+ def __init__(self, name: str, cb_hook: Callable[[ViewerButton], Any], disabled: bool = False):
+ super().__init__(name, disabled=disabled, cb_hook=cb_hook)
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ self.gui_handle = viser_server.add_gui_button(name=self.name, disabled=self.disabled)
+
+ def install(self, viser_server: ViserServer) -> None:
+ self._create_gui_handle(viser_server)
+
+ assert self.gui_handle is not None
+ self.gui_handle.on_click(lambda _: self.cb_hook(self))
+
+
+class ViewerParameter(ViewerElement[TValue], Generic[TValue]):
+ """A viewer element with state
+
+ Args:
+ name: The name of the element
+ default_value: The default value of the element
+ disabled: If the element is disabled
+ cb_hook: Callback to call on update
+ """
+
+ gui_handle: GuiHandle
+
+ def __init__(
+ self,
+ name: str,
+ default_value: TValue,
+ disabled: bool = False,
+ cb_hook: Callable = lambda element: None,
+ ) -> None:
+ super().__init__(name, disabled=disabled, cb_hook=cb_hook)
+ self.default_value = default_value
+
+ def install(self, viser_server: ViserServer) -> None:
+ """
+ Based on the type provided by default_value, installs a gui element inside the given viser_server
+
+ Args:
+ viser_server: The server to install the gui element into.
+ """
+ self._create_gui_handle(viser_server)
+
+ assert self.gui_handle is not None
+ self.gui_handle.on_update(lambda _: self.cb_hook(self))
+
+ @abstractmethod
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ ...
+
+ @property
+ def value(self) -> TValue:
+ """Returns the current value of the viewer element"""
+ if self.gui_handle is None:
+ return self.default_value
+ return self.gui_handle.value
+
+ @value.setter
+ def value(self, value: TValue) -> None:
+ if self.gui_handle is not None:
+ self.gui_handle.value = value
+ else:
+ self.default_value = value
+
+
+IntOrFloat = TypeVar("IntOrFloat", int, float)
+
+
+class ViewerSlider(ViewerParameter[IntOrFloat], Generic[IntOrFloat]):
+ """A slider in the viewer
+
+ Args:
+ name: The name of the slider
+ default_value: The default value of the slider
+ min_value: The minimum value of the slider
+ max_value: The maximum value of the slider
+ step: The step size of the slider
+ disabled: If the slider is disabled
+ cb_hook: Callback to call on update
+ hint: The hint text
+ """
+
+ def __init__(
+ self,
+ name: str,
+ default_value: IntOrFloat,
+ min_value: IntOrFloat,
+ max_value: IntOrFloat,
+ step: IntOrFloat = 0.1,
+ disabled: bool = False,
+ cb_hook: Callable[[ViewerSlider], Any] = lambda element: None,
+ hint: Optional[str] = None,
+ ):
+ assert isinstance(default_value, (float, int))
+ super().__init__(name, default_value, disabled=disabled, cb_hook=cb_hook)
+ self.min = min_value
+ self.max = max_value
+ self.step = step
+ self.hint = hint
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ assert self.gui_handle is None, "gui_handle should be initialized once"
+ self.gui_handle = viser_server.add_gui_slider(
+ self.name, self.min, self.max, self.step, self.default_value, disabled=self.disabled, hint=self.hint
+ )
+
+
+class ViewerText(ViewerParameter[str]):
+ """A text field in the viewer
+
+ Args:
+ name: The name of the text field
+ default_value: The default value of the text field
+ disabled: If the text field is disabled
+ cb_hook: Callback to call on update
+ hint: The hint text
+ """
+
+ def __init__(
+ self,
+ name: str,
+ default_value: str,
+ disabled: bool = False,
+ cb_hook: Callable[[ViewerText], Any] = lambda element: None,
+ hint: Optional[str] = None,
+ ):
+ assert isinstance(default_value, str)
+ super().__init__(name, default_value, disabled=disabled, cb_hook=cb_hook)
+ self.hint = hint
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ assert self.gui_handle is None, "gui_handle should be initialized once"
+ self.gui_handle = viser_server.add_gui_text(
+ self.name, self.default_value, disabled=self.disabled, hint=self.hint
+ )
+
+
+class ViewerNumber(ViewerParameter[IntOrFloat], Generic[IntOrFloat]):
+ """A number field in the viewer
+
+ Args:
+ name: The name of the number field
+ default_value: The default value of the number field
+ disabled: If the number field is disabled
+ cb_hook: Callback to call on update
+ hint: The hint text
+ """
+
+ default_value: IntOrFloat
+
+ def __init__(
+ self,
+ name: str,
+ default_value: IntOrFloat,
+ disabled: bool = False,
+ cb_hook: Callable[[ViewerNumber], Any] = lambda element: None,
+ hint: Optional[str] = None,
+ ):
+ assert isinstance(default_value, (float, int))
+ super().__init__(name, default_value, disabled=disabled, cb_hook=cb_hook)
+ self.hint = hint
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ assert self.gui_handle is None, "gui_handle should be initialized once"
+ self.gui_handle = viser_server.add_gui_number(
+ self.name, self.default_value, disabled=self.disabled, hint=self.hint
+ )
+
+
+class ViewerCheckbox(ViewerParameter[bool]):
+ """A checkbox in the viewer
+
+ Args:
+ name: The name of the checkbox
+ default_value: The default value of the checkbox
+ disabled: If the checkbox is disabled
+ cb_hook: Callback to call on update
+ hint: The hint text
+ """
+
+ def __init__(
+ self,
+ name: str,
+ default_value: bool,
+ disabled: bool = False,
+ cb_hook: Callable[[ViewerCheckbox], Any] = lambda element: None,
+ hint: Optional[str] = None,
+ ):
+ assert isinstance(default_value, bool)
+ super().__init__(name, default_value, disabled=disabled, cb_hook=cb_hook)
+ self.hint = hint
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ assert self.gui_handle is None, "gui_handle should be initialized once"
+ self.gui_handle = viser_server.add_gui_checkbox(
+ self.name, self.default_value, disabled=self.disabled, hint=self.hint
+ )
+
+
+TLiteralString = TypeVar("TLiteralString", bound=LiteralString)
+
+
+class ViewerDropdown(ViewerParameter[TString], Generic[TString]):
+ """A dropdown in the viewer
+
+ Args:
+ name: The name of the dropdown
+ default_value: The default value of the dropdown
+ options: The options of the dropdown
+ disabled: If the dropdown is disabled
+ cb_hook: Callback to call on update
+ hint: The hint text
+ """
+
+ gui_handle: Optional[GuiDropdownHandle[TString]]
+
+ def __init__(
+ self,
+ name: str,
+ default_value: TString,
+ options: List[TString],
+ disabled: bool = False,
+ cb_hook: Callable[[ViewerDropdown], Any] = lambda element: None,
+ hint: Optional[str] = None,
+ ):
+ assert default_value in options
+ super().__init__(name, default_value, disabled=disabled, cb_hook=cb_hook)
+ self.options = options
+ self.hint = hint
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ assert self.gui_handle is None, "gui_handle should be initialized once"
+ self.gui_handle = viser_server.add_gui_dropdown(
+ self.name, self.options, self.default_value, disabled=self.disabled, hint=self.hint # type: ignore
+ )
+
+ def set_options(self, new_options: List[TString]) -> None:
+ """
+ Sets the options of the dropdown,
+
+ Args:
+ new_options: The new options. If the current option isn't in the new options, the first option is selected.
+ """
+ self.options = new_options
+ if self.gui_handle is not None:
+ self.gui_handle.options = new_options
+
+
+class ViewerButtonGroup(ViewerParameter[TString], Generic[TString]):
+ """A button group in the viewer. Unlike other fields, cannot be disabled.
+
+ Args:
+ name: The name of the button group
+ options: The options of the button group
+ cb_hook: Callback to call on update
+ """
+
+ gui_handle: GuiButtonGroupHandle
+
+ def __init__(
+ self,
+ name: str,
+ default_value: TString,
+ options: List[TString],
+ cb_hook: Callable[[ViewerDropdown], Any] = lambda element: None,
+ ):
+ super().__init__(name, disabled=False, default_value=default_value, cb_hook=cb_hook)
+ self.options = options
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ assert self.gui_handle is None, "gui_handle should be initialized once"
+ self.gui_handle = viser_server.add_gui_button_group(self.name, self.options)
+
+ def install(self, viser_server: ViserServer) -> None:
+ self._create_gui_handle(viser_server)
+
+ assert self.gui_handle is not None
+ self.gui_handle.on_click(lambda _: self.cb_hook(self))
+
+
+class ViewerRGB(ViewerParameter[Tuple[int, int, int]]):
+ """
+ An RGB color picker for the viewer
+
+ Args:
+ name: The name of the color picker
+ default_value: The default value of the color picker
+ disabled: If the color picker is disabled
+ cb_hook: Callback to call on update
+ hint: The hint text
+ """
+
+ def __init__(
+ self,
+ name,
+ default_value: Tuple[int, int, int],
+ disabled=False,
+ cb_hook: Callable[[ViewerRGB], Any] = lambda element: None,
+ hint: Optional[str] = None,
+ ):
+ assert len(default_value) == 3
+ super().__init__(name, default_value, disabled=disabled, cb_hook=cb_hook)
+ self.hint = hint
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ self.gui_handle = viser_server.add_gui_rgb(
+ self.name, self.default_value, disabled=self.disabled, hint=self.hint
+ )
+
+
+class ViewerVec3(ViewerParameter[Tuple[float, float, float]]):
+ """
+ 3 number boxes in a row to input a vector
+
+ Args:
+ name: The name of the vector
+ default_value: The default value of the vector
+ step: The step of the vector
+ disabled: If the vector is disabled
+ cb_hook: Callback to call on update
+ hint: The hint text
+ """
+
+ def __init__(
+ self,
+ name,
+ default_value: Tuple[float, float, float],
+ step=0.1,
+ disabled=False,
+ cb_hook: Callable[[ViewerVec3], Any] = lambda element: None,
+ hint: Optional[str] = None,
+ ):
+ assert len(default_value) == 3
+ super().__init__(name, default_value, disabled=disabled, cb_hook=cb_hook)
+ self.step = step
+ self.hint = hint
+
+ def _create_gui_handle(self, viser_server: ViserServer) -> None:
+ self.gui_handle = viser_server.add_gui_vector3(
+ self.name, self.default_value, self.step, disabled=self.disabled, hint=self.hint
+ )
diff --git a/pyproject.toml b/pyproject.toml
index c66c34b04..02972b0e9 100644
--- a/pyproject.toml
+++ b/pyproject.toml
@@ -17,7 +17,7 @@ dependencies = [
"appdirs>=1.4",
"av>=9.2.0",
"cryptography>=38",
- "tyro>=0.3.31",
+ "tyro>=0.5.3",
"gdown>=4.6.0",
"ninja>=1.10",
"h5py>=2.9.0",
@@ -51,7 +51,7 @@ dependencies = [
"torchvision>=0.14.1",
"torchmetrics[image]>=0.9.3",
"typing_extensions>=4.4.0",
- "viser>=0.0.10",
+ "viser>=0.0.12",
"nuscenes-devkit>=1.1.1",
"wandb>=0.13.3",
"xatlas",
diff --git a/tests/field_components/test_encodings.py b/tests/field_components/test_encodings.py
index dc59b79ff..a7dbb7f2c 100644
--- a/tests/field_components/test_encodings.py
+++ b/tests/field_components/test_encodings.py
@@ -154,10 +154,9 @@ def test_tensor_hash_encoder():
)
assert encoder.get_out_dim() == out_dim
- in_tensor = torch.zeros((10, 3))
- in_tensor[..., 1] = 1
- encoded = encoder(in_tensor)
- assert encoded.shape == (10, out_dim)
+ in_tensor = torch.rand((10, 3))
+ encoded_torch = encoder(in_tensor)
+ assert encoded_torch.shape == (10, out_dim)
encoder = encodings.HashEncoding(
num_levels=num_levels,
@@ -165,10 +164,8 @@ def test_tensor_hash_encoder():
log2_hashmap_size=5,
implementation="tcnn",
)
- in_tensor = torch.zeros((10, 3))
- in_tensor[..., 1] = 1
- encoded = encoder(in_tensor)
- assert encoded.shape == (10, out_dim)
+ encoded_tcnn = encoder(in_tensor).float().cpu()
+ assert encoded_tcnn.shape == (10, out_dim)
def test_kplane_encoder():
diff --git a/tests/test_train.py b/tests/test_train.py
index 88d8ba683..0034dedd0 100644
--- a/tests/test_train.py
+++ b/tests/test_train.py
@@ -20,7 +20,6 @@ BLACKLIST = [
"semantic-nerfw",
"instant-ngp",
"instant-ngp-bounded",
- "nerfacto",
"nerfacto-big",
"volinga",
"phototourism",
@@ -35,7 +34,11 @@ BLACKLIST = [
def set_reduced_config(config: TrainerConfig):
"""Reducing the config settings to speedup test"""
- config.machine.num_gpus = 0
+ config.machine.device_type = "cpu"
+ if hasattr(config.pipeline.model, "implementation"):
+ setattr(config.pipeline.model, "implementation", "torch")
+ config.mixed_precision = False
+ config.use_grad_scaler = False
config.max_num_iterations = 2
# reduce dataset factors; set dataset to test
config.pipeline.datamanager.dataparser = BlenderDataParserConfig(data=Path("tests/data/lego_test"))