 +
+
+
 +
+
 +
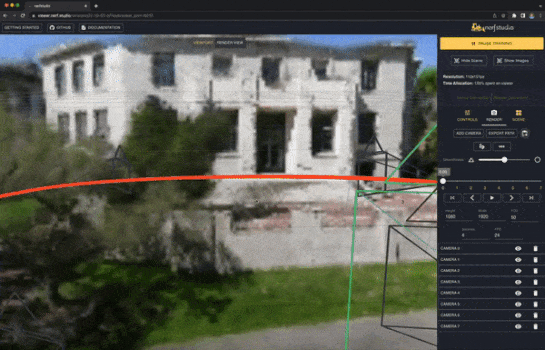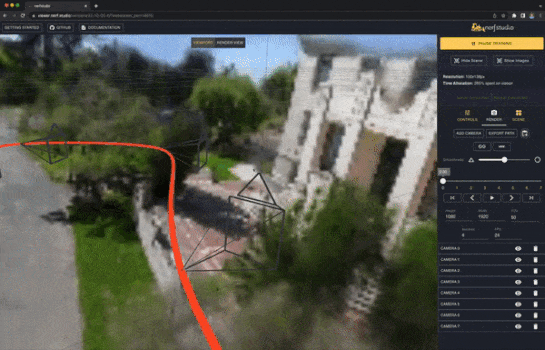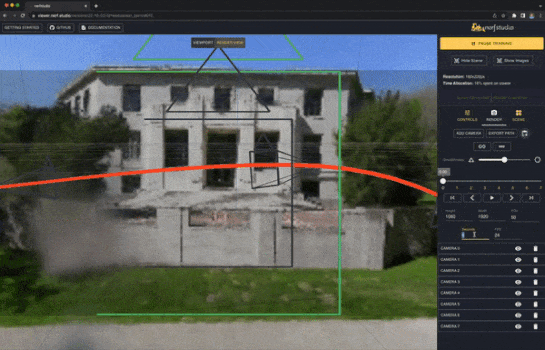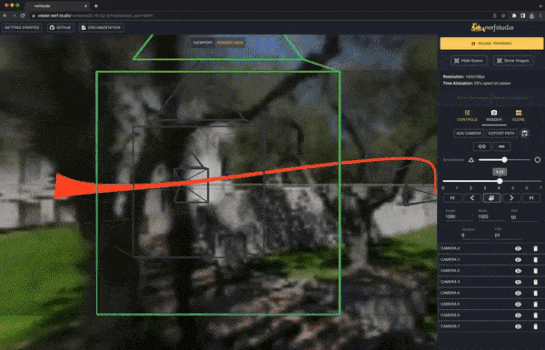 @@ -103,7 +110,7 @@ Easy option:
pip install nerfstudio
```
-If you would want the latest and greatest:
+If you want the latest and greatest:
```bash
git clone https://github.com/nerfstudio-project/nerfstudio.git
@@ -128,9 +135,9 @@ If you have custom data in the form of a video or folder of images, we've provid
After installing both software, you can process your data via:
```bash
-ns-process-data {video,images,insta360} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR}
+ns-process-data {video,images,polycam,insta360,record3d} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR}
# Or if you're on a system without an attached display (i.e. colab):
-ns-process-data {video,images,insta360} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR} --no-gpu
+ns-process-data {video,images,poylcam,insta360,record3d} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR} --no-gpu
```
## 3. Training a model
@@ -198,6 +205,7 @@ If you're interested in learning more on how to create your own pipelines, devel
| 🏃 **Tutorials** |
| [Getting Started](https://docs.nerf.studio/en/latest/quickstart/installation.html) | A more in-depth guide on how to get started with nerfstudio from installation to contributing. |
| [Using the Viewer](https://docs.nerf.studio/en/latest/quickstart/viewer_quickstart.html) | A quick demo video on how to navigate the viewer. |
+| [Using Record3D](https://www.youtube.com/watch?v=XwKq7qDQCQk) | Demo video on how to run nerfstudio without using COLMAP. |
| 💻 **For Developers** |
| [Creating pipelines](https://docs.nerf.studio/en/latest/developer_guides/pipelines/index.html) | Learn how to easily build new neural rendering pipelines by using and/or implementing new modules. |
| [Creating datasets](https://docs.nerf.studio/en/latest/quickstart/custom_dataset.html) | Have a new dataset? Learn how to run it with nerfstudio. |
@@ -220,16 +228,34 @@ We provide the following support structures to make life easier for getting star
- And more!
- :pencil2: Support for multiple logging interfaces (Tensorboard, Wandb), code profiling, and other built-in debugging tools
- :chart_with_upwards_trend: Easy-to-use benchmarking scripts on the Blender dataset
-- :iphone: Full pipeline support (w/ Colmap or Record3D) for going from a video on your phone to a full 3D render.
+- :iphone: Full pipeline support (w/ Colmap, Polycam, or Record3D) for going from a video on your phone to a full 3D render.
# Built On
-#### [tyro](https://github.com/brentyi/tyro)
+
+
+
 +
+
 +
+
 "
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {
+ "id": "SiiXJ7K_fePG"
+ },
+ "source": [
+ "
\n",
+ "  \n",
+ "
'))\n", + " display(HTML('
Note: This may take time, especially on hires inputs, so we recommend to download dataset after creation.'))\n",
+ " !mkdir -p /content/data/nerfstudio/custom_data\n",
+ " if scene == 'upload your images':\n",
+ " !mkdir -p /content/data/nerfstudio/custom_data/raw_images\n",
+ " %cd /content/data/nerfstudio/custom_data/raw_images\n",
+ " uploaded = files.upload()\n",
+ " dir = os.getcwd()\n",
+ " else:\n",
+ " %cd /content/data/nerfstudio/custom_data/\n",
+ " uploaded = files.upload()\n",
+ " dir = os.getcwd()\n",
+ " preupload_datasets = [os.path.join(dir, f) for f in uploaded.keys()]\n",
+ " del uploaded\n",
+ " %cd /content/\n",
+ "\n",
+ " if scene == 'upload your images':\n",
+ " !ns-process-data images --data /content/data/nerfstudio/custom_data/raw_images --output-dir /content/data/nerfstudio/custom_data/\n",
+ " else:\n",
+ " video_path = preupload_datasets[0]\n",
+ " !ns-process-data video --data $video_path --output-dir /content/data/nerfstudio/custom_data/\n",
+ "\n",
+ " scene = \"custom_data\"\n",
+ "else:\n",
+ " %cd /content/\n",
+ " !ns-download-data --dataset=nerfstudio --capture=$scene\n",
+ "\n",
+ "print(\"Data Processing Succeeded!\")"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 2,
+ "metadata": {
+ "colab": {
+ "base_uri": "https://localhost:8080/",
+ "height": 928
+ },
+ "id": "VoKDxqEcjmfC",
+ "outputId": "d2919aa4-96dd-4e50-829f-289e4208882b",
+ "cellView": "form"
+ },
+ "outputs": [
+ {
+ "output_type": "stream",
+ "name": "stdout",
+ "text": [
+ "/content\n",
+ "\u001b[K\u001b[?25h/tools/node/bin/lt -> /tools/node/lib/node_modules/localtunnel/bin/lt.js\n",
+ "\u001b[K\u001b[?25h+ localtunnel@2.0.2\n",
+ "added 22 packages from 22 contributors in 2.07s\n",
+ "https://viewer.nerf.studio/?websocket_url=wss://cyan-facts-matter-34-91-1-218.loca.lt\n",
+ "You may need to click Refresh Page after you start training!\n"
+ ]
+ },
+ {
+ "output_type": "execute_result",
+ "data": {
+ "text/plain": [
+ "
-
+ {text_intro}
+
+ Animated camera properties will show up here!
+ Set up and Start Viewer
\n",
+ "\n",
+ "%cd /content\n",
+ "\n",
+ "# Install localtunnel\n",
+ "# We are using localtunnel https://github.com/localtunnel/localtunnel but ngrok could also be used\n",
+ "!npm install -g localtunnel\n",
+ "\n",
+ "# Tunnel port 7007, the default for\n",
+ "!rm url.txt 2> /dev/null\n",
+ "get_ipython().system_raw('lt --port 7007 >> url.txt 2>&1 &')\n",
+ "\n",
+ "import time\n",
+ "time.sleep(3) # the previous command needs time to write to url.txt\n",
+ "\n",
+ "\n",
+ "with open('url.txt') as f:\n",
+ " lines = f.readlines()\n",
+ "websocket_url = lines[0].split(\": \")[1].strip().replace(\"https\", \"wss\")\n",
+ "# from nerfstudio.utils.io import load_from_json\n",
+ "# from pathlib import Path\n",
+ "# json_filename = \"nerfstudio/nerfstudio/viewer/app/package.json\"\n",
+ "# version = load_from_json(Path(json_filename))[\"version\"]\n",
+ "url = f\"https://viewer.nerf.studio/?websocket_url={websocket_url}\"\n",
+ "print(url)\n",
+ "print(\"You may need to click Refresh Page after you start training!\")\n",
+ "from IPython import display\n",
+ "display.IFrame(src=url, height=800, width=\"100%\")"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "id": "m_N8_cLfjoXD",
+ "cellView": "form"
+ },
+ "outputs": [],
+ "source": [
+ "#@markdown Start Training
\n",
+ "\n",
+ "%cd /content\n",
+ "if os.path.exists(f\"data/nerfstudio/{scene}/transforms.json\"):\n",
+ " !ns-train nerfacto --viewer.websocket-port 7007 nerfstudio-data --data data/nerfstudio/$scene --downscale-factor 4\n",
+ "else:\n",
+ " display(HTML('Error: Data processing did not complete
'))\n",
+ " display(HTML('Please re-run `Downloading and Processing Data`, or view the FAQ for more info.
'))"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {
+ "cellView": "form",
+ "colab": {
+ "base_uri": "https://localhost:8080/"
+ },
+ "id": "WGt8ukG6Htg3",
+ "outputId": "fa946890-c7d8-4e46-a54e-7231bc5a2059"
+ },
+ "outputs": [
+ {
+ "name": "stdout",
+ "output_type": "stream",
+ "text": [
+ "\u001b[2;36m[19:48:48]\u001b[0m\u001b[2;36m \u001b[0mSkipping \u001b[1;36m0\u001b[0m files in dataset split train. \u001b]8;id=527413;file:///content/nerfstudio/nerfstudio/data/dataparsers/nerfstudio_dataparser.py\u001b\\\u001b[2mnerfstudio_dataparser.py\u001b[0m\u001b]8;;\u001b\\\u001b[2m:\u001b[0m\u001b]8;id=243595;file:///content/nerfstudio/nerfstudio/data/dataparsers/nerfstudio_dataparser.py#91\u001b\\\u001b[2m91\u001b[0m\u001b]8;;\u001b\\\n",
+ "\u001b[2;36m \u001b[0m\u001b[2;36m \u001b[0mSkipping \u001b[1;36m0\u001b[0m files in dataset split test. \u001b]8;id=109270;file:///content/nerfstudio/nerfstudio/data/dataparsers/nerfstudio_dataparser.py\u001b\\\u001b[2mnerfstudio_dataparser.py\u001b[0m\u001b]8;;\u001b\\\u001b[2m:\u001b[0m\u001b]8;id=464675;file:///content/nerfstudio/nerfstudio/data/dataparsers/nerfstudio_dataparser.py#91\u001b\\\u001b[2m91\u001b[0m\u001b]8;;\u001b\\\n",
+ "\u001b[2KLoading data batch \u001b[90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\u001b[0m \u001b[35m100%\u001b[0m \u001b[36m0:00:00\u001b[0m\n",
+ "\u001b[?25h/usr/local/lib/python3.7/site-packages/torch/utils/data/dataloader.py:566: UserWarning: This DataLoader will create 4 worker processes in total. Our suggested max number of worker in current system is 2, which is smaller than what this DataLoader is going to create. Please be aware that excessive worker creation might get DataLoader running slow or even freeze, lower the worker number to avoid potential slowness/freeze if necessary.\n",
+ " cpuset_checked))\n",
+ "\u001b[2KLoading data batch \u001b[90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\u001b[0m \u001b[35m100%\u001b[0m \u001b[36m0:00:00\u001b[0m\n",
+ "\u001b[?25h/usr/local/lib/python3.7/site-packages/torchvision/models/_utils.py:209: UserWarning: The parameter 'pretrained' is deprecated since 0.13 and will be removed in 0.15, please use 'weights' instead.\n",
+ " f\"The parameter '{pretrained_param}' is deprecated since 0.13 and will be removed in 0.15, \"\n",
+ "/usr/local/lib/python3.7/site-packages/torchvision/models/_utils.py:223: UserWarning: Arguments other than a weight enum or `None` for 'weights' are deprecated since 0.13 and will be removed in 0.15. The current behavior is equivalent to passing `weights=AlexNet_Weights.IMAGENET1K_V1`. You can also use `weights=AlexNet_Weights.DEFAULT` to get the most up-to-date weights.\n",
+ " warnings.warn(msg)\n",
+ "Loading latest checkpoint from load_dir\n",
+ "✅ Done loading checkpoint from \n",
+ "outputs/data-nerfstudio-poster/nerfacto/\u001b[1;36m2022\u001b[0m-\u001b[1;36m10\u001b[0m-29_192844/nerfstudio_models/step-\u001b[1;36m000014000.\u001b[0mckpt\n",
+ "\u001b[1;32mCreating trajectory video\u001b[0m\n",
+ "\u001b[2K🎥 Rendering 🎥 \u001b[90m━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\u001b[0m \u001b[35m100%\u001b[0m \u001b[31m0.14 fps\u001b[0m \u001b[33m11:47\u001b[0m\n",
+ "\u001b[2K\u001b[32m( ● )\u001b[0m \u001b[33mSaving video\u001b[0m\n",
+ "\u001b[1A\u001b[2K\u001b[92m────────────────────────────────────────────── \u001b[0m\u001b[32m 🎉 🎉 🎉 Success 🎉 🎉 🎉\u001b[0m\u001b[92m ──────────────────────────────────────────────\u001b[0m\n",
+ " \u001b[32mSaved video to renders/output.mp4\u001b[0m \n",
+ "\u001b[0m"
+ ]
+ }
+ ],
+ "source": [
+ "#@title # Render Video { vertical-output: true }\n",
+ "#@markdown Export the camera path from within the viewer, then run this cell.
\n",
+ "#@markdown The rendered video should be at renders/output.mp4!
\n",
+ "\n",
+ "\n",
+ "base_dir = \"/content/outputs/data-nerfstudio-\" + scene + \"/nerfacto/\"\n",
+ "training_run_dir = base_dir + os.listdir(base_dir)[0]\n",
+ "\n",
+ "from IPython.core.display import display, HTML\n",
+ "display(HTML('Upload the camera path JSON.
'))\n",
+ "%cd $training_run_dir\n",
+ "uploaded = files.upload()\n",
+ "uploaded_camera_path_filename = list(uploaded.keys())[0]\n",
+ "\n",
+ "config_filename = training_run_dir + \"/config.yml\"\n",
+ "camera_path_filename = training_run_dir + \"/\" + uploaded_camera_path_filename\n",
+ "camera_path_filename = camera_path_filename.replace(\" \", \"\\\\ \").replace(\"(\", \"\\\\(\").replace(\")\", \"\\\\)\")\n",
+ "\n",
+ "%cd /content/\n",
+ "!ns-render --load-config $config_filename --traj filename --camera-path-filename $camera_path_filename --output-path renders/output.mp4"
+ ]
+ }
+ ],
+ "metadata": {
+ "accelerator": "GPU",
+ "colab": {
+ "collapsed_sections": [],
+ "provenance": [],
+ "include_colab_link": true
+ },
+ "gpuClass": "standard",
+ "kernelspec": {
+ "display_name": "Python 3.8.12 ('nerfactory')",
+ "language": "python",
+ "name": "python3"
+ },
+ "language_info": {
+ "name": "python",
+ "version": "3.8.12"
+ },
+ "vscode": {
+ "interpreter": {
+ "hash": "34c28001ff35fb390494047002768a8182dcf55b1b11415165e62ea61557ab83"
+ }
+ }
+ },
+ "nbformat": 4,
+ "nbformat_minor": 0
+}
diff --git a/docs/_static/imgs/readme_colab.png b/docs/_static/imgs/readme_colab.png
new file mode 100644
index 000000000..2ba11d768
Binary files /dev/null and b/docs/_static/imgs/readme_colab.png differ
diff --git a/docs/_templates/sidebar/brand.html b/docs/_templates/sidebar/brand.html
index 14772296b..7a0140a98 100644
--- a/docs/_templates/sidebar/brand.html
+++ b/docs/_templates/sidebar/brand.html
@@ -44,4 +44,59 @@ going well. :) -#}
>
Github
+
+
+
+ colab
diff --git a/docs/developer_guides/pipelines/fields.md b/docs/developer_guides/pipelines/fields.md
index 8c6c6005f..f4c9c6d2e 100644
--- a/docs/developer_guides/pipelines/fields.md
+++ b/docs/developer_guides/pipelines/fields.md
@@ -69,8 +69,6 @@ class FieldHeadNames(Enum):
TRANSIENT_RGB = "transient_rgb"
TRANSIENT_DENSITY = "transient_density"
SEMANTICS = "semantics"
- SEMANTICS_STUFF = "semantics_stuff"
- SEMANTICS_THING = "semantics_thing"
```
```{button-link} https://github.com/nerfstudio-project/nerfstudio/blob/master/nerfstudio/field_components/field_heads.py
diff --git a/docs/developer_guides/pipelines/index.rst b/docs/developer_guides/pipelines/index.rst
index b90954525..7255af29a 100644
--- a/docs/developer_guides/pipelines/index.rst
+++ b/docs/developer_guides/pipelines/index.rst
@@ -26,9 +26,9 @@ Why Pipelines?
Our goal is for any NeRF paper to be implemented as a Pipeline.
-The Pipeline is composed of two major components, namely the DataManager and the Model. The DataManager is responsible for loading data and generating RayBundle and RayGT objects. RayBundles are the input to the forward pass of the Model. These are needed for at both train and inference time. RayGT objects, however, are needed only during training to calculate the losses in the Loss Dict.
+The Pipeline is composed of two major components, namely the DataManager and the Model. The DataManager is responsible for loading data and generating RayBundle and RayGT objects. RayBundles are the input to the forward pass of the Model. These are needed for both training and inference time. RayGT objects, however, are needed only during training to calculate the losses in the Loss Dict.
-RayBundle objects describe origins and viewing directions. The model will take these rays and render them into quanties as RayOutputs. RayGT contains the necessary ground truth (GT) information needed to compute losses. For example, the GT pixel values can be used to supervise the rendered rays with an L2 loss.
+RayBundle objects describe origins and viewing directions. The model will take these rays and render them into quantities as RayOutputs. RayGT contains the necessary ground truth (GT) information needed to compute losses. For example, the GT pixel values can be used to supervise the rendered rays with an L2 loss.
In the following sections, we describe the Pipeline components and look at their code.
@@ -44,6 +44,6 @@ In the following sections, we describe the Pipeline components and look at their
Implementing NeRF Papers
==========================
-Let's say you want to create a custom Pipeline that has a custom DataManager and a custom Model. Perhaps you care about dynmically adding cameras to the DataManager during training or you want to importance sample and generate rays from pixels where the loss is high. This can be accomplished by mixing and matching components into a Pipeline. The following guide will take you through an example of this.
+Let's say you want to create a custom Pipeline that has a custom DataManager and a custom Model. Perhaps you care about dynamically adding cameras to the DataManager during training or you want to importance sample and generate rays from pixels where the loss is high. This can be accomplished by mixing and matching components into a Pipeline. The following guide will take you through an example of this.
-This guide is coming soon!
\ No newline at end of file
+This guide is coming soon!
diff --git a/docs/developer_guides/viewer/viewer_overview.md b/docs/developer_guides/viewer/viewer_overview.md
index bd2d33e4d..b80463e75 100644
--- a/docs/developer_guides/viewer/viewer_overview.md
+++ b/docs/developer_guides/viewer/viewer_overview.md
@@ -22,14 +22,6 @@ The connection between the Bridge Server and the Client App works with WebSocket
## Installing and running locally
-#### Running the Bridge Server
-
-The viewer bridge server runs on the same machine that you use for training. The training code will connect to this server with a lightweight TCP connection using ZMQ. The training job will launch the viewer bridge server is you specify `--viewer.launch-bridge-server` in the terminal. Otherwise, you can launch the bridge server manually with the following script.
-
-```python
-python scripts/viewer/run_bridge_server.py --help
-```
-
#### Running the Client App
```shell
@@ -58,6 +50,14 @@ yarn install
yarn start
```
+#### Running the Bridge Server Manually
+
+The viewer bridge server runs on the same machine that you use for training. The training code will connect to this server with a lightweight TCP connection using ZMQ. The training job will launch the viewer bridge server is you specify `--viewer.launch-bridge-server` in the terminal. Otherwise, you can launch the bridge server manually with the following script.
+
+```python
+ns-bridge-server --help
+```
+
## Acknowledgements and references
We thank the authors and contributors to the following repos, which we've started, used, and modified for our use-cases.
diff --git a/docs/index.md b/docs/index.md
index c6bbb80c8..69b149711 100644
--- a/docs/index.md
+++ b/docs/index.md
@@ -50,7 +50,7 @@ quickstart/installation
quickstart/first_nerf
quickstart/custom_dataset
quickstart/viewer_quickstart
-quickstart/google_colab
+quickstart/data_conventions
ContributingOur *defacto* method.
-
+
### Running the Method
-
+
```bash
ns-train nerfacto --help
```
-
+
## Method
-
+
### Overview
-
-```{admonition} Coming Soon
-This guide is coming soon. This is our flagship method that we encourage creators to use when making videos. It uses techniques from [Mip-NeRF 360](https://jonbarron.info/mipnerf360/) and [Instant-NGP](https://nvlabs.github.io/instant-ngp/).
+
+We created the nerfacto model to act as our default for real data captures of static scenes. The model is not existing published work, but rather a combination of many published methods that we have found work well for real data. This guide discusses the details of the model, understanding the [NeRF model](./nerf.md) is a prerequisite.
+
+```{admonition} TLDR
+We combine the following techniques in this model:
+* Camera pose refinement
+* Per image appearance conditioning
+* Proposal sampling
+* Scene contraction
+* Hash encoding
```
-
-Most of the code for this method takes place in the `NerfactoModel` class.
-
+
+```{warning}
+🏗️ This guide is under construction 🏗️
+```
+
+## Pipeline
+
+```{image} imgs/nerfacto/models_nerfacto_pipeline-light.png
+:align: center
+:class: only-light
+```
+
+```{image} imgs/nerfacto/models_nerfacto_pipeline-dark.png
+:align: center
+:class: only-dark
+```
+
+Here is an overview pipeline for nerfacto, we will walk through each component in this guide.
+
+### Pose Refinement
+
+It is not uncommon to have errors in the predicted camera poses. This is even more of a factor when using poses acquired from devices such as phones (ie. if you use the Record3D IOS app to capture data). Misaligned poses result in both cloudy artifacts in the scene and a reduction of sharpness and details. The NeRF framework allows us to backpropagate loss gradients to the input pose calculations. We can use this information to optimize and refine the poses.
+
+### Piecewise Sampler
+
+We use a Piecewise sampler to produce the initial set of samples of the scene. This sampler allocates half of the samples uniformly up to a distance of 1 from the camera. The remaining samples are distributed such that the step size increases with each sample. The step size is chosen such that the [frustums](../model_components/visualize_samples.ipynb) are scaled versions of themselves. By increasing the step sizes, we are able to sample distant objects will still having a dense set of samples for nearby objects.
+
+### Proposal Sampler
+
+The proposal sampler consolidates the sample locations to the regions of the scene that contribute most to the final render (typically the first surface intersection). This greatly improves reconstruction quality. The proposal network sampler requires a density function for the scene. The density function can be implemented in a variety of ways, we find that using a small fused-mlp with a hash encoding has sufficient accuracy and is fast. The proposal network sampler can be chained together with multiple density functions to further consolidate the sampling. We have found that two density functions are better than one. Larger than 2 leads to diminishing returns.
+
+#### Density Field
+
+The density field only needs to represent a coarse density representation of the scene to guide sampling. Combining a hash encoding with a small fused MLP (from [tiny-cuda-nn](https://github.com/NVlabs/tiny-cuda-nn)) provides a fast way to query the scene. We can make it more efficient by decreasing the encoding dictionary size and number of feature levels. These simplifications have little impact on the reconstruction quality because the density function does not need to learn high frequency details during the initial passes.
+
+### Nerfacto Field
+
+```{image} imgs/nerfacto/models_nerfacto_field-light.png
+:align: center
+:class: only-light
+:width: 600
+```
+
+```{image} imgs/nerfacto/models_nerfacto_field-dark.png
+:align: center
+:class: only-dark
+:width: 600
+```
+
```{button-link} https://github.com/nerfstudio-project/nerfstudio/blob/main/nerfstudio/models/nerfacto.py
:color: primary
:outline:
diff --git a/docs/quickstart/custom_dataset.md b/docs/quickstart/custom_dataset.md
index f0a170280..1c4f05722 100644
--- a/docs/quickstart/custom_dataset.md
+++ b/docs/quickstart/custom_dataset.md
@@ -1,31 +1,46 @@
# Using custom data
-Training model on existing datasets is only so fun. If you would like to train on self captured data you will need to process the data into an existing format. Specifically we need to know the camera poses for each image. [COLMAP](https://github.com/colmap/colmap) is a standard tool for extracting poses. It is possible to use other methods like [SLAM](https://en.wikipedia.org/wiki/Simultaneous_localization_and_mapping) or hardware recorded poses. We intend to add documentation for these other methods in the future.
+Training model on existing datasets is only so fun. If you would like to train on self captured data you will need to process the data into the nerfstudio format. Specifically we need to know the camera poses for each image.
-## Nerfstudio dataset
-
-To assist running on custom data we have a script that will process a video or folder of images into a format that is compatible with nerfstudio. We use [COLMAP](https://colmap.github.io) and [FFmpeg](https://ffmpeg.org/download.html) in our data processing script, please have these installed. We have provided a quickstart to installing COLMAP below, FFmpeg can be downloaded from [here](https://ffmpeg.org/download.html)
-
-To process your data run:
+To process your own data run:
```bash
-ns-process-data {video,images,insta360} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR}
+ns-process-data {video,images,polycam,insta360,record3d} --data {DATA_PATH} --output-dir {PROCESSED_DATA_DIR}
```
A full set of arguments can be found {doc}`here
+
+## Dataset format
+
+Our explanation here is for the nerfstudio data format. The `transforms.json` has a similar format to [Instant NGP](https://github.com/NVlabs/instant-ngp).
+
+**Camera intrinsics**
+
+At the top of the file, we specify the camera intrinsics. We assume that all the intrinsics parameters are the same for every camera in the dataset. The following is an example
+
+```json
+{
+ "fl_x": 1072.281897246229, // focal length x
+ "fl_y": 1068.6906965388932, // focal length y
+ "cx": 1504.0, // principal point x
+ "cy": 1000.0, // principal point y
+ "w": 3008, // image width
+ "h": 2000, // image height
+ "camera_model": "OPENCV_FISHEYE", // camera model type
+ "k1": 0.03126218448029553, // first radial distorial parameter
+ "k2": 0.005177020067511987, // second radial distorial parameter
+ "k3": 0.0006640977794272005, // third radial distorial parameter
+ "k4": 0.00010067035656515042, // fourth radial distorial parameter
+ "p1": -6.472477652140879e-5, // first tangential distortion parameter
+ "p2": -1.374647851912992e-7, // second tangential distortion parameter
+ "frames": // ... extrinsics parameters explained below
+}
+```
+
+The valid `camera_model` strings are currently "OPENCV" and "OPENCV_FISHEYE". "OPENCV" (i.e., perspective) uses k1-2 and p1-2. "OPENCV_FISHEYE" uses k1-4.
+
+**Camera extrinsics**
+
+For a transform matrix, the first 3 columns are the +X, +Y, and +Z defining the camera orientation, and the X, Y, Z values define the origin. The last row is to be compatible with homogeneous coordinates.
+
+```json
+{
+ // ... intrinsics parameters
+ "frames": [
+ {
+ "file_path": "images/frame_00001.jpeg",
+ "transform_matrix": [
+ // [+X0 +Y0 +Z0 X]
+ // [+X1 +Y1 +Z1 Y]
+ // [+X2 +Y2 +Z2 Z]
+ // [0.0 0.0 0.0 1]
+ [1.0, 0.0, 0.0, 0.0],
+ [0.0, 1.0, 0.0, 0.0],
+ [0.0, 0.0, 1.0, 0.0],
+ [0.0, 0.0, 0.0, 1.0]
+ ]
+ }
+ ]
+}
+```
diff --git a/docs/quickstart/google_colab.md b/docs/quickstart/google_colab.md
deleted file mode 100644
index b086e5e59..000000000
--- a/docs/quickstart/google_colab.md
+++ /dev/null
@@ -1,3 +0,0 @@
-# Google Colab
-
-Nerfstudio works in Google Colab using their hosted GPUs! Here is [the link](https://colab.research.google.com/drive/1l-QDYEcv759kUNJQrJ8z1CI8o1iIiU-l?usp=sharing). Make a copy of this file and go from there!
diff --git a/docs/quickstart/imgs/polycam_export.png b/docs/quickstart/imgs/polycam_export.png
new file mode 100644
index 000000000..4d4997169
Binary files /dev/null and b/docs/quickstart/imgs/polycam_export.png differ
diff --git a/docs/quickstart/imgs/polycam_settings.png b/docs/quickstart/imgs/polycam_settings.png
new file mode 100644
index 000000000..04702c144
Binary files /dev/null and b/docs/quickstart/imgs/polycam_settings.png differ
diff --git a/docs/reference/api/data.rst b/docs/reference/api/data.rst
index a0ac5a2b2..de7b57abe 100644
--- a/docs/reference/api/data.rst
+++ b/docs/reference/api/data.rst
@@ -13,7 +13,7 @@ Data Parsers
Datasets
----------------
-.. automodule:: nerfstudio.data.utils.datasets
+.. automodule:: nerfstudio.data.datasets
:members:
:show-inheritance:
diff --git a/docs/reference/cli/index.md b/docs/reference/cli/index.md
index af333742a..797f0d9eb 100644
--- a/docs/reference/cli/index.md
+++ b/docs/reference/cli/index.md
@@ -14,6 +14,7 @@ Here are the popular commands that we offer. If you've cloned the repo, you can
| ns-train | Generate a NeRF | scripts/train.py |
| ns-eval | Run evaluation metrics for your Model | scripts/eval.py |
| ns-render | Render out a video of your NeRF | scripts/render.py |
+| ns-export | Export a NeRF into other formats | scripts/exporter.py |
```{toctree}
:maxdepth: 1
@@ -23,5 +24,6 @@ ns_process_data
ns_download_data
ns_train
ns_render
+ns_export
ns_eval
```
diff --git a/docs/reference/cli/ns_export.md b/docs/reference/cli/ns_export.md
new file mode 100644
index 000000000..cdfc54f2f
--- /dev/null
+++ b/docs/reference/cli/ns_export.md
@@ -0,0 +1,9 @@
+# ns-export
+
+```{eval-rst}
+.. argparse::
+ :module: scripts.exporter
+ :func: get_parser_fn
+ :prog: ns-export
+ :nodefault:
+```
diff --git a/nerfstudio/cameras/camera_utils.py b/nerfstudio/cameras/camera_utils.py
index b0de30a9b..30d755596 100644
--- a/nerfstudio/cameras/camera_utils.py
+++ b/nerfstudio/cameras/camera_utils.py
@@ -342,7 +342,7 @@ def _compute_residual_and_jacobian(
def radial_and_tangential_undistort(
coords: torch.Tensor,
distortion_params: torch.Tensor,
- eps: float = 1e-9,
+ eps: float = 1e-3,
max_iterations: int = 10,
) -> torch.Tensor:
"""Computes undistorted coords given opencv distortion parameters.
diff --git a/nerfstudio/cameras/cameras.py b/nerfstudio/cameras/cameras.py
index bd5b4e13b..d039ee9b0 100644
--- a/nerfstudio/cameras/cameras.py
+++ b/nerfstudio/cameras/cameras.py
@@ -83,6 +83,7 @@ class Cameras:
camera_type: Optional[
Union[TensorType["num_cameras"], int, List[CameraType], CameraType]
] = CameraType.PERSPECTIVE,
+ times: Optional[TensorType["num_cameras"]] = None,
):
self._num_cameras = camera_to_worlds.shape[0]
self.camera_to_worlds = camera_to_worlds # This comes first since it determines @property self.device
@@ -123,6 +124,8 @@ class Cameras:
self.camera_type = self._init_get_camera_type(camera_type)
+ self.times = times
+
def _init_get_camera_type(
self, camera_type: Union[TensorType["num_cameras"], int, List[CameraType], CameraType]
) -> TensorType["num_cameras"]:
@@ -225,6 +228,7 @@ class Cameras:
height=self.image_height.to(device),
distortion_params=distortion_params.to(device) if distortion_params is not None else None,
camera_type=self.camera_type.to(device),
+ times=self.times.to(device) if self.times is not None else None,
)
def get_image_coords(self, pixel_offset: float = 0.5) -> TensorType["height", "width", 2]:
@@ -307,11 +311,7 @@ class Cameras:
sin_theta = torch.sin(theta)
directions_stack = torch.stack(
- [
- coord_stack[..., 0] * sin_theta / theta,
- coord_stack[..., 1] * sin_theta / theta,
- -torch.cos(theta),
- ],
+ [coord_stack[..., 0] * sin_theta / theta, coord_stack[..., 1] * sin_theta / theta, -torch.cos(theta)],
dim=-1,
)
elif self.camera_type[0] == CameraType.EQUIRECTANGULAR.value:
@@ -349,18 +349,18 @@ class Cameras:
else:
ray_bundle_camera_indices = camera_indices.view(pixel_area.shape)
+ times = self.times[camera_indices, None] if self.times is not None else None
+
return RayBundle(
origins=origins,
directions=directions,
pixel_area=pixel_area,
camera_indices=ray_bundle_camera_indices,
+ times=times,
)
def to_json(
- self,
- camera_idx: int,
- image: Optional[TensorType["height", "width", 2]] = None,
- max_size: Optional[int] = None,
+ self, camera_idx: int, image: Optional[TensorType["height", "width", 2]] = None, max_size: Optional[int] = None
) -> Dict:
"""Convert a camera to a json dictionary.
@@ -380,6 +380,7 @@ class Cameras:
"fy": self.fy[camera_idx].tolist(),
"camera_to_world": self.camera_to_worlds[camera_idx].tolist(),
"camera_index": camera_idx,
+ "times": self.times[camera_idx].item() if self.times is not None else None,
}
if image is not None:
image_uint8 = (image * 255).detach().type(torch.uint8)
@@ -432,8 +433,9 @@ class Cameras:
self.cy[indices],
height=self._image_heights[indices],
width=self._image_widths[indices],
- distortion_params=self.distortion_params[indices] if self.distortion_params else None,
+ distortion_params=self.distortion_params[indices] if self.distortion_params is not None else None,
camera_type=self.camera_type[indices],
+ times=self.times[indices] if self.times is not None else None,
)
if isinstance(indices, (int, slice)):
indices = (indices,)
@@ -445,6 +447,9 @@ class Cameras:
self.cy[indices + (slice(None),)],
height=self._image_heights[indices + (slice(None),)],
width=self._image_widths[indices + (slice(None),)],
- distortion_params=self.distortion_params[indices + (slice(None),)] if self.distortion_params else None,
+ distortion_params=self.distortion_params[indices + (slice(None),)]
+ if self.distortion_params is not None
+ else None,
camera_type=self.camera_type[indices + (slice(None),)],
+ times=self.times[indices + (slice(None),)] if self.times is not None else None,
)
diff --git a/nerfstudio/cameras/rays.py b/nerfstudio/cameras/rays.py
index 16b28eae8..d9dbaba0b 100644
--- a/nerfstudio/cameras/rays.py
+++ b/nerfstudio/cameras/rays.py
@@ -40,6 +40,8 @@ class Frustums(TensorDataclass):
"""Where the frustum ends along a ray."""
pixel_area: TensorType["bs":..., 1]
"""Projected area of pixel a distance 1 away from origin."""
+ offsets: Optional[TensorType["bs":..., 3]] = None
+ """Offsets for each sample position"""
def get_positions(self) -> TensorType[..., 3]:
"""Calulates "center" position of frustum. Not weighted by mass.
@@ -47,7 +49,14 @@ class Frustums(TensorDataclass):
Returns:
xyz positions.
"""
- return self.origins + self.directions * (self.starts + self.ends) / 2
+ pos = self.origins + self.directions * (self.starts + self.ends) / 2
+ if self.offsets is not None:
+ pos = pos + self.offsets
+ return pos
+
+ def set_offsets(self, offsets):
+ """Sets offsets for this frustum for computing positions"""
+ self.offsets = offsets
def get_gaussian_blob(self) -> Gaussians:
"""Calculates guassian approximation of conical frustum.
@@ -57,6 +66,8 @@ class Frustums(TensorDataclass):
"""
# Cone radius is set such that the square pixel_area matches the cone area.
cone_radius = torch.sqrt(self.pixel_area) / 1.7724538509055159 # r = sqrt(pixel_area / pi)
+ if self.offsets is not None:
+ raise NotImplementedError()
return conical_frustum_to_gaussian(
origins=self.origins,
directions=self.directions,
@@ -100,6 +111,9 @@ class RaySamples(TensorDataclass):
metadata: Optional[Dict[str, TensorType["bs":..., "latent_dims"]]] = None
"""addtional information relevant to generating ray samples"""
+ times: Optional[TensorType[..., 1]] = None
+ """Times at which rays are sampled"""
+
def get_weights(self, densities: TensorType[..., "num_samples", 1]) -> TensorType[..., "num_samples", 1]:
"""Return weights based on predicted densities
@@ -143,6 +157,8 @@ class RayBundle(TensorDataclass):
"""Rays Distance along ray to stop sampling"""
metadata: Optional[Dict[str, TensorType["num_rays", "latent_dims"]]] = None
"""Additional metadata or data needed for interpolation, will mimic shape of rays"""
+ times: Optional[TensorType[..., 1]] = None
+ """Times at which rays are sampled"""
def set_camera_indices(self, camera_index: int) -> None:
"""Sets all of the the camera indices to a specific camera index.
@@ -223,6 +239,7 @@ class RayBundle(TensorDataclass):
spacing_ends=spacing_ends, # [..., num_samples, 1]
spacing_to_euclidean_fn=spacing_to_euclidean_fn,
metadata=shaped_raybundle_fields.metadata,
+ times=None if self.times is None else self.times[..., None], # [..., 1, 1]
)
return ray_samples
diff --git a/nerfstudio/configs/base_config.py b/nerfstudio/configs/base_config.py
index 340806577..2e67c64f0 100644
--- a/nerfstudio/configs/base_config.py
+++ b/nerfstudio/configs/base_config.py
@@ -18,6 +18,7 @@
from __future__ import annotations
+import warnings
from dataclasses import dataclass
from datetime import datetime
from pathlib import Path
@@ -32,6 +33,8 @@ from nerfstudio.configs.config_utils import to_immutable_dict
# model instances
from nerfstudio.utils import writer
+warnings.filterwarnings("ignore", module="torchvision")
+
CONSOLE = Console(width=120)
# Pretty printing class
@@ -178,6 +181,8 @@ class ViewerConfig(PrintableConfig):
max_num_display_images: int = 512
"""Maximum number of training images to display in the viewer, to avoid lag. This does not change which images are
actually used in training/evaluation. If -1, display all."""
+ quit_on_train_completion: bool = False
+ """Whether to kill the training job when it has completed. Note this will stop rendering in the viewer."""
from nerfstudio.engine.optimizers import OptimizerConfig
@@ -241,7 +246,7 @@ class Config(PrintableConfig):
def set_experiment_name(self) -> None:
"""Dynamically set the experiment name"""
if self.experiment_name is None:
- self.experiment_name = str(self.pipeline.datamanager.dataparser.data).replace("/", "-")
+ self.experiment_name = str(self.pipeline.datamanager.dataparser.data).replace("../", "").replace("/", "-")
def get_base_dir(self) -> Path:
"""Retrieve the base directory to set relative paths"""
diff --git a/nerfstudio/configs/method_configs.py b/nerfstudio/configs/method_configs.py
index f4a95f027..2c829e092 100644
--- a/nerfstudio/configs/method_configs.py
+++ b/nerfstudio/configs/method_configs.py
@@ -23,18 +23,26 @@ from typing import Dict
import tyro
from nerfstudio.cameras.camera_optimizers import CameraOptimizerConfig
-from nerfstudio.configs.base_config import Config, TrainerConfig, ViewerConfig
-from nerfstudio.data.datamanagers import VanillaDataManagerConfig
+from nerfstudio.configs.base_config import (
+ Config,
+ SchedulerConfig,
+ TrainerConfig,
+ ViewerConfig,
+)
+from nerfstudio.data.datamanagers.base_datamanager import VanillaDataManagerConfig
+from nerfstudio.data.datamanagers.semantic_datamanager import SemanticDataManagerConfig
from nerfstudio.data.dataparsers.blender_dataparser import BlenderDataParserConfig
+from nerfstudio.data.dataparsers.dnerf_dataparser import DNeRFDataParserConfig
from nerfstudio.data.dataparsers.friends_dataparser import FriendsDataParserConfig
from nerfstudio.data.dataparsers.nerfstudio_dataparser import NerfstudioDataParserConfig
from nerfstudio.engine.optimizers import AdamOptimizerConfig, RAdamOptimizerConfig
-from nerfstudio.models.base_model import VanillaModelConfig
+from nerfstudio.field_components.temporal_distortions import TemporalDistortionKind
from nerfstudio.models.instant_ngp import InstantNGPModelConfig
from nerfstudio.models.mipnerf import MipNerfModel
from nerfstudio.models.nerfacto import NerfactoModelConfig
from nerfstudio.models.semantic_nerfw import SemanticNerfWModelConfig
-from nerfstudio.models.vanilla_nerf import NeRFModel
+from nerfstudio.models.tensorf import TensoRFModelConfig
+from nerfstudio.models.vanilla_nerf import NeRFModel, VanillaModelConfig
from nerfstudio.pipelines.base_pipeline import VanillaPipelineConfig
from nerfstudio.pipelines.dynamic_batch import DynamicBatchPipelineConfig
@@ -45,6 +53,8 @@ descriptions = {
"mipnerf": "High quality model for bounded scenes. (slow)",
"semantic-nerfw": "Predicts semantic segmentations and filters out transient objects.",
"vanilla-nerf": "Original NeRF model. (slow)",
+ "tensorf": "tensorf",
+ "dnerf": "Dynamic-NeRF model. (slow)",
}
method_configs["nerfacto"] = Config(
@@ -120,7 +130,7 @@ method_configs["semantic-nerfw"] = Config(
method_name="semantic-nerfw",
trainer=TrainerConfig(steps_per_eval_batch=500, steps_per_save=2000, mixed_precision=True),
pipeline=VanillaPipelineConfig(
- datamanager=VanillaDataManagerConfig(
+ datamanager=SemanticDataManagerConfig(
dataparser=FriendsDataParserConfig(), train_num_rays_per_batch=4096, eval_num_rays_per_batch=8192
),
model=SemanticNerfWModelConfig(eval_num_rays_per_chunk=1 << 16),
@@ -151,13 +161,61 @@ method_configs["vanilla-nerf"] = Config(
"fields": {
"optimizer": RAdamOptimizerConfig(lr=5e-4, eps=1e-08),
"scheduler": None,
- }
+ },
+ "temporal_distortion": {
+ "optimizer": RAdamOptimizerConfig(lr=5e-4, eps=1e-08),
+ "scheduler": None,
+ },
},
)
+method_configs["tensorf"] = Config(
+ method_name="tensorf",
+ trainer=TrainerConfig(mixed_precision=False),
+ pipeline=VanillaPipelineConfig(
+ datamanager=VanillaDataManagerConfig(
+ dataparser=BlenderDataParserConfig(),
+ ),
+ model=TensoRFModelConfig(),
+ ),
+ optimizers={
+ "fields": {
+ "optimizer": AdamOptimizerConfig(lr=0.001),
+ "scheduler": SchedulerConfig(lr_final=0.0001, max_steps=30000),
+ },
+ "encodings": {
+ "optimizer": AdamOptimizerConfig(lr=0.02),
+ "scheduler": SchedulerConfig(lr_final=0.002, max_steps=30000),
+ },
+ },
+)
+
+method_configs["dnerf"] = Config(
+ method_name="dnerf",
+ pipeline=VanillaPipelineConfig(
+ datamanager=VanillaDataManagerConfig(dataparser=DNeRFDataParserConfig()),
+ model=VanillaModelConfig(
+ _target=NeRFModel,
+ enable_temporal_distortion=True,
+ temporal_distortion_params={"kind": TemporalDistortionKind.DNERF},
+ ),
+ ),
+ optimizers={
+ "fields": {
+ "optimizer": RAdamOptimizerConfig(lr=5e-4, eps=1e-08),
+ "scheduler": None,
+ },
+ "temporal_distortion": {
+ "optimizer": RAdamOptimizerConfig(lr=5e-4, eps=1e-08),
+ "scheduler": None,
+ },
+ },
+)
AnnotatedBaseConfigUnion = tyro.conf.SuppressFixed[ # Don't show unparseable (fixed) arguments in helptext.
- tyro.extras.subcommand_type_from_defaults(defaults=method_configs, descriptions=descriptions)
+ tyro.conf.FlagConversionOff[
+ tyro.extras.subcommand_type_from_defaults(defaults=method_configs, descriptions=descriptions)
+ ]
]
"""Union[] type over config types, annotated with default instances for use with
tyro.cli(). Allows the user to pick between one of several base configurations, and
diff --git a/nerfstudio/data/datamanagers/__init__.py b/nerfstudio/data/datamanagers/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/data/datamanagers/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/nerfstudio/data/datamanagers.py b/nerfstudio/data/datamanagers/base_datamanager.py
similarity index 89%
rename from nerfstudio/data/datamanagers.py
rename to nerfstudio/data/datamanagers/base_datamanager.py
index c3cf367c3..a895fb7b8 100644
--- a/nerfstudio/data/datamanagers.py
+++ b/nerfstudio/data/datamanagers/base_datamanager.py
@@ -13,8 +13,9 @@
# limitations under the License.
"""
-Data loader.
+Datamanager.
"""
+
from __future__ import annotations
from abc import abstractmethod
@@ -23,32 +24,38 @@ from typing import Dict, List, Optional, Tuple, Type, Union
import torch
import tyro
+from rich.progress import Console
from torch import nn
from torch.nn import Parameter
from torch.utils.data import Dataset
from torch.utils.data.distributed import DistributedSampler
+from typing_extensions import Literal
from nerfstudio.cameras.camera_optimizers import CameraOptimizerConfig
from nerfstudio.cameras.rays import RayBundle
from nerfstudio.configs.base_config import InstantiateConfig
from nerfstudio.data.dataparsers.blender_dataparser import BlenderDataParserConfig
+from nerfstudio.data.dataparsers.dnerf_dataparser import DNeRFDataParserConfig
from nerfstudio.data.dataparsers.friends_dataparser import FriendsDataParserConfig
from nerfstudio.data.dataparsers.instant_ngp_dataparser import (
InstantNGPDataParserConfig,
)
from nerfstudio.data.dataparsers.nerfstudio_dataparser import NerfstudioDataParserConfig
+from nerfstudio.data.dataparsers.nuscenes_dataparser import NuScenesDataParserConfig
from nerfstudio.data.dataparsers.record3d_dataparser import Record3DDataParserConfig
+from nerfstudio.data.datasets.base_dataset import InputDataset
from nerfstudio.data.pixel_samplers import PixelSampler
from nerfstudio.data.utils.dataloaders import (
CacheDataloader,
FixedIndicesEvalDataloader,
RandIndicesEvalDataloader,
)
-from nerfstudio.data.utils.datasets import InputDataset
from nerfstudio.engine.callbacks import TrainingCallback, TrainingCallbackAttributes
from nerfstudio.model_components.ray_generators import RayGenerator
from nerfstudio.utils.misc import IterableWrapper
+CONSOLE = Console(width=120)
+
AnnotatedDataParserUnion = tyro.conf.OmitSubcommandPrefixes[ # Omit prefixes of flags in subcommands.
tyro.extras.subcommand_type_from_defaults(
{
@@ -56,7 +63,9 @@ AnnotatedDataParserUnion = tyro.conf.OmitSubcommandPrefixes[ # Omit prefixes of
"blender-data": BlenderDataParserConfig(),
"friends-data": FriendsDataParserConfig(),
"instant-ngp-data": InstantNGPDataParserConfig(),
+ "nuscenes-data": NuScenesDataParserConfig(),
"record3d-data": Record3DDataParserConfig(),
+ "dnerf-data": DNeRFDataParserConfig(),
},
prefix_names=False, # Omit prefixes in subcommands themselves.
)
@@ -128,9 +137,9 @@ class DataManager(nn.Module):
super().__init__()
self.train_count = 0
self.eval_count = 0
- if self.train_dataset:
+ if self.train_dataset and self.test_mode != "inference":
self.setup_train()
- if self.eval_dataset:
+ if self.eval_dataset and self.test_mode != "inference":
self.setup_eval()
def forward(self):
@@ -242,10 +251,16 @@ class VanillaDataManagerConfig(InstantiateConfig):
"""Number of rays per batch to use per training iteration."""
train_num_images_to_sample_from: int = -1
"""Number of images to sample during training iteration."""
+ train_num_times_to_repeat_images: int = -1
+ """When not training on all images, number of iterations before picking new
+ images. If -1, never pick new images."""
eval_num_rays_per_batch: int = 1024
"""Number of rays per batch to use per eval iteration."""
eval_num_images_to_sample_from: int = -1
"""Number of images to sample during eval iteration."""
+ eval_num_times_to_repeat_images: int = -1
+ """When not evaluating on all images, number of iterations before picking
+ new images. If -1, never pick new images."""
eval_image_indices: Optional[Tuple[int, ...]] = (0,)
"""Specifies the image indices to use during eval; if None, uses all."""
camera_optimizer: CameraOptimizerConfig = CameraOptimizerConfig()
@@ -274,7 +289,7 @@ class VanillaDataManager(DataManager): # pylint: disable=abstract-method
self,
config: VanillaDataManagerConfig,
device: Union[torch.device, str] = "cpu",
- test_mode: bool = False,
+ test_mode: Literal["test", "val", "inference"] = "val",
world_size: int = 1,
local_rank: int = 0,
**kwargs, # pylint: disable=unused-argument
@@ -284,19 +299,29 @@ class VanillaDataManager(DataManager): # pylint: disable=abstract-method
self.world_size = world_size
self.local_rank = local_rank
self.sampler = None
+ self.test_mode = test_mode
+ self.test_split = "test" if test_mode in ["test", "inference"] else "val"
- self.train_dataset = InputDataset(config.dataparser.setup().get_dataparser_outputs(split="train"))
- self.eval_dataset = InputDataset(
- config.dataparser.setup().get_dataparser_outputs(split="val" if not test_mode else "test")
- )
+ self.train_dataset = self.create_train_dataset()
+ self.eval_dataset = self.create_eval_dataset()
super().__init__()
+ def create_train_dataset(self) -> InputDataset:
+ """Sets up the data loaders for training"""
+ return InputDataset(self.config.dataparser.setup().get_dataparser_outputs(split="train"))
+
+ def create_eval_dataset(self) -> InputDataset:
+ """Sets up the data loaders for evaluation"""
+ return InputDataset(self.config.dataparser.setup().get_dataparser_outputs(split=self.test_split))
+
def setup_train(self):
"""Sets up the data loaders for training"""
assert self.train_dataset is not None
+ CONSOLE.print("Setting up training dataset...")
self.train_image_dataloader = CacheDataloader(
self.train_dataset,
num_images_to_sample_from=self.config.train_num_images_to_sample_from,
+ num_times_to_repeat_images=self.config.train_num_times_to_repeat_images,
device=self.device,
num_workers=self.world_size * 4,
pin_memory=True,
@@ -314,9 +339,11 @@ class VanillaDataManager(DataManager): # pylint: disable=abstract-method
def setup_eval(self):
"""Sets up the data loader for evaluation"""
assert self.eval_dataset is not None
+ CONSOLE.print("Setting up evaluation dataset...")
self.eval_image_dataloader = CacheDataloader(
self.eval_dataset,
num_images_to_sample_from=self.config.eval_num_images_to_sample_from,
+ num_times_to_repeat_images=self.config.eval_num_times_to_repeat_images,
device=self.device,
num_workers=self.world_size * 4,
pin_memory=True,
@@ -340,9 +367,6 @@ class VanillaDataManager(DataManager): # pylint: disable=abstract-method
num_workers=self.world_size * 4,
)
- # TODO: eval dataloader should be separate from train
- self.iter_eval_dataloader = iter(self.eval_image_dataloader)
-
def next_train(self, step: int) -> Tuple[RayBundle, Dict]:
"""Returns the next batch of data from the train dataloader."""
self.train_count += 1
diff --git a/nerfstudio/data/datamanagers/semantic_datamanager.py b/nerfstudio/data/datamanagers/semantic_datamanager.py
new file mode 100644
index 000000000..d19769308
--- /dev/null
+++ b/nerfstudio/data/datamanagers/semantic_datamanager.py
@@ -0,0 +1,47 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Semantic datamanager.
+"""
+
+from dataclasses import dataclass, field
+from typing import Type
+
+from nerfstudio.data.datamanagers.base_datamanager import (
+ VanillaDataManager,
+ VanillaDataManagerConfig,
+)
+from nerfstudio.data.datasets.semantic_dataset import SemanticDataset
+
+
+@dataclass
+class SemanticDataManagerConfig(VanillaDataManagerConfig):
+ """A semantic datamanager - required to use with .setup()"""
+
+ _target: Type = field(default_factory=lambda: SemanticDataManager)
+
+
+class SemanticDataManager(VanillaDataManager): # pylint: disable=abstract-method
+ """Data manager implementation for data that also requires processing semantic data.
+
+ Args:
+ config: the DataManagerConfig used to instantiate class
+ """
+
+ def create_train_dataset(self) -> SemanticDataset:
+ return SemanticDataset(self.config.dataparser.setup().get_dataparser_outputs(split="train"))
+
+ def create_eval_dataset(self) -> SemanticDataset:
+ return SemanticDataset(self.config.dataparser.setup().get_dataparser_outputs(split=self.test_split))
diff --git a/nerfstudio/data/dataparsers/base_dataparser.py b/nerfstudio/data/dataparsers/base_dataparser.py
index f671f17ea..3b99f274e 100644
--- a/nerfstudio/data/dataparsers/base_dataparser.py
+++ b/nerfstudio/data/dataparsers/base_dataparser.py
@@ -34,18 +34,14 @@ from nerfstudio.data.scene_box import SceneBox
class Semantics:
"""Dataclass for semantic labels."""
- stuff_filenames: List[Path]
- """filenames to load "stuff"/background data"""
- stuff_classes: List[str]
- """class labels for "stuff" data"""
- stuff_colors: torch.Tensor
- """color mapping for "stuff" classes"""
- thing_filenames: List[Path]
- """filenames to load "thing"/foreground data"""
- thing_classes: List[str]
- """class labels for "thing" data"""
- thing_colors: torch.Tensor
- """color mapping for "thing" classes"""
+ filenames: List[Path]
+ """filenames to load semantic data"""
+ classes: List[str]
+ """class labels for data"""
+ colors: torch.Tensor
+ """color mapping for classes"""
+ mask_classes: List[str] = field(default_factory=lambda: [])
+ """classes to mask out from training for all modalities"""
@dataclass
@@ -61,14 +57,11 @@ class DataparserOutputs:
"""Color of dataset background."""
scene_box: SceneBox = SceneBox()
"""Scene box of dataset. Used to bound the scene or provide the scene scale depending on model."""
- semantics: Optional[Semantics] = None
- """Semantics information."""
- additional_inputs: Dict[str, Any] = to_immutable_dict({})
- """Dictionary of additional dataset information (e.g. semantics/point clouds/masks).
- {input_name:
- ... {"func": function to process additional dataparser outputs,
- ... "kwargs": dictionary of data to pass into "func"}
- }
+ mask_filenames: Optional[List[Path]] = None
+ """Filenames for any masks that are required"""
+ metadata: Dict[str, Any] = to_immutable_dict({})
+ """Dictionary of any metadata that be required for the given experiment.
+ Will be processed by the InputDataset to create any additional tensors that may be required.
"""
def as_dict(self) -> dict:
diff --git a/nerfstudio/data/dataparsers/dnerf_dataparser.py b/nerfstudio/data/dataparsers/dnerf_dataparser.py
new file mode 100644
index 000000000..56a9f232b
--- /dev/null
+++ b/nerfstudio/data/dataparsers/dnerf_dataparser.py
@@ -0,0 +1,108 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Data parser for blender dataset"""
+from __future__ import annotations
+
+from dataclasses import dataclass, field
+from pathlib import Path
+from typing import Type
+
+import imageio
+import numpy as np
+import torch
+
+from nerfstudio.cameras.cameras import Cameras, CameraType
+from nerfstudio.data.dataparsers.base_dataparser import (
+ DataParser,
+ DataParserConfig,
+ DataparserOutputs,
+)
+from nerfstudio.data.scene_box import SceneBox
+from nerfstudio.utils.colors import get_color
+from nerfstudio.utils.io import load_from_json
+
+
+@dataclass
+class DNeRFDataParserConfig(DataParserConfig):
+ """D-NeRF dataset parser config"""
+
+ _target: Type = field(default_factory=lambda: DNeRF)
+ """target class to instantiate"""
+ data: Path = Path("data/dnerf/lego")
+ """Directory specifying location of data."""
+ scale_factor: float = 1.0
+ """How much to scale the camera origins by."""
+ alpha_color: str = "white"
+ """alpha color of background"""
+
+
+@dataclass
+class DNeRF(DataParser):
+ """DNeRF Dataset"""
+
+ config: DNeRFDataParserConfig
+
+ def __init__(self, config: DNeRFDataParserConfig):
+ super().__init__(config=config)
+ self.data: Path = config.data
+ self.scale_factor: float = config.scale_factor
+ self.alpha_color = config.alpha_color
+
+ def _generate_dataparser_outputs(self, split="train"):
+ if self.alpha_color is not None:
+ alpha_color_tensor = get_color(self.alpha_color)
+ else:
+ alpha_color_tensor = None
+
+ meta = load_from_json(self.data / f"transforms_{split}.json")
+ image_filenames = []
+ poses = []
+ times = []
+ for frame in meta["frames"]:
+ fname = self.data / Path(frame["file_path"].replace("./", "") + ".png")
+ image_filenames.append(fname)
+ poses.append(np.array(frame["transform_matrix"]))
+ times.append(frame["time"])
+ poses = np.array(poses).astype(np.float32)
+ times = torch.tensor(times, dtype=torch.float32)
+
+ img_0 = imageio.imread(image_filenames[0])
+ image_height, image_width = img_0.shape[:2]
+ camera_angle_x = float(meta["camera_angle_x"])
+ focal_length = 0.5 * image_width / np.tan(0.5 * camera_angle_x)
+
+ cx = image_width / 2.0
+ cy = image_height / 2.0
+ camera_to_world = torch.from_numpy(poses[:, :3]) # camera to world transform
+
+ # in x,y,z order
+ camera_to_world[..., 3] *= self.scale_factor
+ scene_box = SceneBox(aabb=torch.tensor([[-1.5, -1.5, -1.5], [1.5, 1.5, 1.5]], dtype=torch.float32))
+
+ cameras = Cameras(
+ camera_to_worlds=camera_to_world,
+ fx=focal_length,
+ fy=focal_length,
+ cx=cx,
+ cy=cy,
+ camera_type=CameraType.PERSPECTIVE,
+ times=times,
+ )
+
+ dataparser_outputs = DataparserOutputs(
+ image_filenames=image_filenames, cameras=cameras, alpha_color=alpha_color_tensor, scene_box=scene_box
+ )
+
+ return dataparser_outputs
diff --git a/nerfstudio/data/dataparsers/friends_dataparser.py b/nerfstudio/data/dataparsers/friends_dataparser.py
index 7a1afa69e..cd60e9951 100644
--- a/nerfstudio/data/dataparsers/friends_dataparser.py
+++ b/nerfstudio/data/dataparsers/friends_dataparser.py
@@ -19,9 +19,7 @@ from dataclasses import dataclass, field
from pathlib import Path
from typing import Type
-import numpy as np
import torch
-from PIL import Image
from rich.console import Console
from nerfstudio.cameras.cameras import Cameras, CameraType
@@ -37,31 +35,6 @@ from nerfstudio.utils.io import load_from_json
CONSOLE = Console()
-def get_semantics_and_masks(image_idx: int, semantics: Semantics):
- """function to process additional semantics and mask information
-
- Args:
- image_idx: specific image index to work with
- semantics: semantics data
- """
- # handle mask
- person_index = semantics.thing_classes.index("person")
- thing_image_filename = semantics.thing_filenames[image_idx]
- pil_image = Image.open(thing_image_filename)
- thing_semantics = torch.from_numpy(np.array(pil_image, dtype="int32"))[..., None]
- mask = (thing_semantics != person_index).to(torch.float32) # 1 where valid
- # handle semantics
- # stuff
- stuff_image_filename = semantics.stuff_filenames[image_idx]
- pil_image = Image.open(stuff_image_filename)
- stuff_semantics = torch.from_numpy(np.array(pil_image, dtype="int32"))[..., None]
- # thing
- thing_image_filename = semantics.thing_filenames[image_idx]
- pil_image = Image.open(thing_image_filename)
- thing_semantics = torch.from_numpy(np.array(pil_image, dtype="int32"))[..., None]
- return {"mask": mask, "semantics_stuff": stuff_semantics, "semantics_thing": thing_semantics}
-
-
@dataclass
class FriendsDataParserConfig(DataParserConfig):
"""Friends dataset parser config"""
@@ -142,9 +115,8 @@ class Friends(DataParser):
camera_to_worlds[..., 3] *= scale # cameras
# --- semantics ---
- semantics = None
if self.config.include_semantics:
- thing_filenames = [
+ filenames = [
Path(
str(image_filename)
.replace(f"/{images_folder}/", f"/{segmentations_folder}/thing/")
@@ -152,27 +124,10 @@ class Friends(DataParser):
)
for image_filename in image_filenames
]
- stuff_filenames = [
- Path(
- str(image_filename)
- .replace(f"/{images_folder}/", f"/{segmentations_folder}/stuff/")
- .replace(".jpg", ".png")
- )
- for image_filename in image_filenames
- ]
panoptic_classes = load_from_json(self.config.data / "panoptic_classes.json")
- stuff_classes = panoptic_classes["stuff"]
- stuff_colors = torch.tensor(panoptic_classes["stuff_colors"], dtype=torch.float32) / 255.0
- thing_classes = panoptic_classes["thing"]
- thing_colors = torch.tensor(panoptic_classes["thing_colors"], dtype=torch.float32) / 255.0
- semantics = Semantics(
- stuff_classes=stuff_classes,
- stuff_colors=stuff_colors,
- stuff_filenames=stuff_filenames,
- thing_classes=thing_classes,
- thing_colors=thing_colors,
- thing_filenames=thing_filenames,
- )
+ classes = panoptic_classes["thing"]
+ colors = torch.tensor(panoptic_classes["thing_colors"], dtype=torch.float32) / 255.0
+ semantics = Semantics(filenames=filenames, classes=classes, colors=colors, mask_classes=["person"])
assert torch.all(cx[0] == cx), "Not all cameras have the same cx. Our Cameras class does not support this."
assert torch.all(cy[0] == cy), "Not all cameras have the same cy. Our Cameras class does not support this."
@@ -191,7 +146,6 @@ class Friends(DataParser):
image_filenames=image_filenames,
cameras=cameras,
scene_box=scene_box,
- additional_inputs={"semantics": {"func": get_semantics_and_masks, "kwargs": {"semantics": semantics}}},
- semantics=semantics,
+ metadata={"semantics": semantics} if self.config.include_semantics else {},
)
return dataparser_outputs
diff --git a/nerfstudio/data/dataparsers/instant_ngp_dataparser.py b/nerfstudio/data/dataparsers/instant_ngp_dataparser.py
index 1641ad43d..1e5a69b99 100644
--- a/nerfstudio/data/dataparsers/instant_ngp_dataparser.py
+++ b/nerfstudio/data/dataparsers/instant_ngp_dataparser.py
@@ -130,7 +130,7 @@ class InstantNGP(DataParser):
fl_x, fl_y = 0, 0
def fov_to_focal_length(rad, res):
- return 0.5 * res / np.tanh(0.5 * rad)
+ return 0.5 * res / np.tan(0.5 * rad)
if "fl_x" in meta:
fl_x = meta["fl_x"]
diff --git a/nerfstudio/data/dataparsers/nerfstudio_dataparser.py b/nerfstudio/data/dataparsers/nerfstudio_dataparser.py
index afb66c657..c1eb62715 100644
--- a/nerfstudio/data/dataparsers/nerfstudio_dataparser.py
+++ b/nerfstudio/data/dataparsers/nerfstudio_dataparser.py
@@ -113,9 +113,17 @@ class Nerfstudio(DataParser):
else:
raise ValueError(f"Unknown dataparser split {split}")
+ if "orientation_override" in meta:
+ orientation_method = meta["orientation_override"]
+ CONSOLE.log(f"[yellow] Dataset is overriding orientation method to {orientation_method}")
+ else:
+ orientation_method = self.config.orientation_method
+
poses = torch.from_numpy(np.array(poses).astype(np.float32))
poses = camera_utils.auto_orient_and_center_poses(
- poses, method=self.config.orientation_method, center_poses=self.config.center_poses
+ poses,
+ method=orientation_method,
+ center_poses=self.config.center_poses,
)
# Scale poses
diff --git a/nerfstudio/data/dataparsers/nuscenes_dataparser.py b/nerfstudio/data/dataparsers/nuscenes_dataparser.py
new file mode 100644
index 000000000..88e215611
--- /dev/null
+++ b/nerfstudio/data/dataparsers/nuscenes_dataparser.py
@@ -0,0 +1,212 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Data parser for NuScenes dataset"""
+import math
+import os
+from dataclasses import dataclass, field
+from pathlib import Path
+from typing import Optional, Tuple, Type
+
+import numpy as np
+import torch
+from nuscenes.nuscenes import NuScenes as NuScenesDatabase
+from typing_extensions import Literal
+
+from nerfstudio.cameras.cameras import Cameras, CameraType
+from nerfstudio.data.dataparsers.base_dataparser import (
+ DataParser,
+ DataParserConfig,
+ DataparserOutputs,
+)
+from nerfstudio.data.scene_box import SceneBox
+from nerfstudio.utils.colmap_utils import qvec2rotmat
+
+
+def rotation_translation_to_pose(r_vec, t_vec):
+ """Convert quaternion rotation and translation vectors to 4x4 matrix"""
+
+ pose = np.eye(4)
+ pose[:3, :3] = qvec2rotmat(r_vec)
+ pose[:3, 3] = t_vec
+ return pose
+
+
+@dataclass
+class NuScenesDataParserConfig(DataParserConfig):
+ """NuScenes dataset config.
+ NuScenes (https://www.nuscenes.org/nuscenes) is an autonomous driving dataset containing 1000 20s clips.
+ Each clip was recorded with a suite of sensors including 6 souround cameras.
+ It also includes 3D cuboid annotations around obects.
+ We optionally use these cuboids to mask dynamic objects by specifying the mask_dir flag.
+ To create these masks use scripts/datasets/process_nuscenes_masks.py.
+ """
+
+ _target: Type = field(default_factory=lambda: NuScenes)
+ """target class to instantiate"""
+ data: Path = Path("scene-0103") # TODO: rename to scene but keep checkpoint saving name?
+ """Name of the scene."""
+ data_dir: Path = Path("/mnt/local/NuScenes")
+ """Path to NuScenes dataset."""
+ version: Literal["v1.0-mini", "v1.0-trainval"] = "v1.0-mini"
+ """Dataset version."""
+ cameras: Tuple[Literal["FRONT", "FRONT_LEFT", "FRONT_RIGHT", "BACK", "BACK_LEFT", "BACK_RIGHT"], ...] = ("FRONT",)
+ """Which cameras to use."""
+ mask_dir: Optional[Path] = None
+ """Path to masks of dynamic objects."""
+
+ train_split_percentage: float = 0.9
+ """The percent of images to use for training. The remaining images are for eval."""
+
+ verbose: bool = False
+ """Load dataset with verbose messaging"""
+
+
+@dataclass
+class NuScenes(DataParser):
+ """NuScenes DatasetParser"""
+
+ config: NuScenesDataParserConfig
+
+ def _generate_dataparser_outputs(self, split="train"):
+ # pylint: disable=too-many-statements
+
+ nusc = NuScenesDatabase(version=self.config.version, dataroot=self.config.data_dir, verbose=self.config.verbose)
+ cameras = ["CAM_" + camera for camera in self.config.cameras]
+
+ assert (
+ len(cameras) == 1
+ ), "waiting on multiple camera support" # TODO: remove once multiple cameras are supported
+
+ # get samples for scene
+ samples = [
+ samp for samp in nusc.sample if nusc.get("scene", samp["scene_token"])["name"] == str(self.config.data)
+ ]
+
+ # sort by timestamp (only to make chronological viz easier)
+ samples.sort(key=lambda x: (x["scene_token"], x["timestamp"]))
+
+ transform1 = np.array(
+ [
+ [0, -1, 0, 0],
+ [0, 0, -1, 0],
+ [1, 0, 0, 0],
+ [0, 0, 0, 1],
+ ]
+ )
+ transform2 = np.array(
+ [
+ [0, 0, 1, 0],
+ [0, 1, 0, 0],
+ [-1, 0, 0, 0],
+ [0, 0, 0, 1],
+ ]
+ )
+
+ # get image filenames and camera data
+ image_filenames = []
+ mask_filenames = []
+ mask_dir = self.config.mask_dir if self.config.mask_dir is not None else Path("")
+ intrinsics = []
+ poses = []
+ for sample in samples:
+ for camera in cameras:
+ camera_data = nusc.get("sample_data", sample["data"][camera])
+ calibrated_sensor_data = nusc.get("calibrated_sensor", camera_data["calibrated_sensor_token"])
+ ego_pose_data = nusc.get("ego_pose", camera_data["ego_pose_token"])
+
+ ego_pose = rotation_translation_to_pose(ego_pose_data["rotation"], ego_pose_data["translation"])
+ cam_pose = rotation_translation_to_pose(
+ calibrated_sensor_data["rotation"], calibrated_sensor_data["translation"]
+ )
+ pose = ego_pose @ cam_pose
+
+ # rotate to opencv frame
+ pose = transform1 @ pose
+
+ # convert from opencv camera to nerfstudio camera
+ pose[0:3, 1:3] *= -1
+ pose = pose[np.array([1, 0, 2, 3]), :]
+ pose[2, :] *= -1
+
+ # rotate to z-up in viewer
+ pose = transform2 @ pose
+
+ image_filenames.append(self.config.data_dir / camera_data["filename"])
+ mask_filenames.append(
+ mask_dir / "masks" / camera / os.path.split(camera_data["filename"])[1].replace("jpg", "png")
+ )
+ intrinsics.append(calibrated_sensor_data["camera_intrinsic"])
+ poses.append(pose)
+ poses = torch.from_numpy(np.stack(poses).astype(np.float32))
+ intrinsics = torch.from_numpy(np.array(intrinsics).astype(np.float32))
+
+ # center poses
+ poses[:, :3, 3] -= poses[:, :3, 3].mean(dim=0)
+
+ # scale poses
+ poses[:, :3, 3] /= poses[:, :3, 3].abs().max()
+
+ # filter image_filenames and poses based on train/eval split percentage
+ num_snapshots = len(samples)
+ num_train_snapshots = math.ceil(num_snapshots * self.config.train_split_percentage)
+ num_eval_snapshots = num_snapshots - num_train_snapshots
+ i_all = np.arange(num_snapshots)
+ i_train = np.linspace(
+ 0, num_snapshots - 1, num_train_snapshots, dtype=int
+ ) # equally spaced training snapshots starting and ending at 0 and num_images-1
+ i_eval = np.setdiff1d(i_all, i_train) # eval images are the remaining images
+ assert len(i_eval) == num_eval_snapshots
+ i_train = (i_train[None, :] * len(cameras) + np.arange(len(cameras))[:, None]).ravel()
+ i_eval = (i_eval[None, :] * len(cameras) + np.arange(len(cameras))[:, None]).ravel()
+ if split == "train":
+ indices = i_train
+ elif split in ["val", "test"]:
+ indices = i_eval
+ else:
+ raise ValueError(f"Unknown dataparser split {split}")
+
+ # Choose image_filenames and poses based on split, but after auto orient and scaling the poses.
+ image_filenames = [image_filenames[i] for i in indices]
+ mask_filenames = [mask_filenames[i] for i in indices]
+ intrinsics = intrinsics[indices]
+ poses = poses[indices]
+
+ # in x,y,z order
+ # assumes that the scene is centered at the origin
+ aabb_scale = 1.0
+ scene_box = SceneBox(
+ aabb=torch.tensor(
+ [[-aabb_scale, -aabb_scale, -aabb_scale], [aabb_scale, aabb_scale, aabb_scale]], dtype=torch.float32
+ )
+ )
+
+ cameras = Cameras(
+ fx=intrinsics[:, 0, 0],
+ fy=intrinsics[:, 1, 1],
+ cx=intrinsics[:, 0, 2],
+ cy=intrinsics[:, 1, 2],
+ height=900,
+ width=1600,
+ camera_to_worlds=poses[:, :3, :4],
+ camera_type=CameraType.PERSPECTIVE,
+ )
+
+ dataparser_outputs = DataparserOutputs(
+ image_filenames=image_filenames,
+ cameras=cameras,
+ scene_box=scene_box,
+ mask_filenames=mask_filenames if self.config.mask_dir is not None else None,
+ )
+ return dataparser_outputs
diff --git a/nerfstudio/data/dataparsers/record3d_dataparser.py b/nerfstudio/data/dataparsers/record3d_dataparser.py
index 513f9b4c6..099470d01 100644
--- a/nerfstudio/data/dataparsers/record3d_dataparser.py
+++ b/nerfstudio/data/dataparsers/record3d_dataparser.py
@@ -21,6 +21,7 @@ from typing import Type
import numpy as np
import torch
+from rich.console import Console
from scipy.spatial.transform import Rotation
from typing_extensions import Literal
@@ -35,6 +36,8 @@ from nerfstudio.data.scene_box import SceneBox
from nerfstudio.utils import poses as pose_utils
from nerfstudio.utils.io import load_from_json
+CONSOLE = Console(width=120)
+
@dataclass
class Record3DDataParserConfig(DataParserConfig):
@@ -51,8 +54,8 @@ class Record3DDataParserConfig(DataParserConfig):
orientation_method: Literal["pca", "up"] = "up"
"""The method to use for orientation"""
max_dataset_size: int = 300
- """Max number of images to train on. If the dataset has
- more, images will be sampled approximately evenly."""
+ """Max number of images to train on. If the dataset has more, images will be sampled approximately evenly. If -1,
+ use all images."""
@dataclass
@@ -62,6 +65,12 @@ class Record3D(DataParser):
config: Record3DDataParserConfig
def _generate_dataparser_outputs(self, split: str = "train") -> DataparserOutputs:
+
+ CONSOLE.print(
+ "[bold red]DEPRECATION WARNING: The Record3D dataparser will be deprecated in future versions. "
+ "Use `ns-data-process record3d` to convert the data into the nerfstudio format instead."
+ )
+
image_dir = self.config.data / "rgb"
if not image_dir.exists():
@@ -86,7 +95,7 @@ class Record3D(DataParser):
axis=-1,
).astype(np.float32)
- if num_images > self.config.max_dataset_size:
+ if self.config.max_dataset_size != -1 and num_images > self.config.max_dataset_size:
# Evenly select max_dataset_size images from dataset, including first
# and last indices.
idx = np.round(np.linspace(0, num_images - 1, self.config.max_dataset_size)).astype(int)
diff --git a/nerfstudio/data/datasets/__init__.py b/nerfstudio/data/datasets/__init__.py
new file mode 100644
index 000000000..d926cf95c
--- /dev/null
+++ b/nerfstudio/data/datasets/__init__.py
@@ -0,0 +1,13 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
diff --git a/nerfstudio/data/utils/datasets.py b/nerfstudio/data/datasets/base_dataset.py
similarity index 77%
rename from nerfstudio/data/utils/datasets.py
rename to nerfstudio/data/datasets/base_dataset.py
index b192a39c7..15d4296d0 100644
--- a/nerfstudio/data/utils/datasets.py
+++ b/nerfstudio/data/datasets/base_dataset.py
@@ -13,7 +13,7 @@
# limitations under the License.
"""
-Some dataset code.
+Dataset.
"""
from __future__ import annotations
@@ -27,6 +27,7 @@ from torch.utils.data import Dataset
from torchtyping import TensorType
from nerfstudio.data.dataparsers.base_dataparser import DataparserOutputs
+from nerfstudio.data.utils.data_utils import get_image_mask_tensor_from_path
class InputDataset(Dataset):
@@ -39,6 +40,7 @@ class InputDataset(Dataset):
def __init__(self, dataparser_outputs: DataparserOutputs):
super().__init__()
self.dataparser_outputs = dataparser_outputs
+ self.has_masks = self.dataparser_outputs.mask_filenames is not None
def __len__(self):
return len(self.dataparser_outputs.image_filenames)
@@ -71,7 +73,7 @@ class InputDataset(Dataset):
image = image[:, :, :3]
return image
- def get_data(self, image_idx) -> Dict:
+ def get_data(self, image_idx: int) -> Dict:
"""Returns the ImageDataset data as a dictionary.
Args:
@@ -80,13 +82,23 @@ class InputDataset(Dataset):
image = self.get_image(image_idx)
data = {"image_idx": image_idx}
data["image"] = image
- for _, data_func_dict in self.dataparser_outputs.additional_inputs.items():
- assert "func" in data_func_dict, "Missing function to process data: specify `func` in `additional_inputs`"
- func = data_func_dict["func"]
- assert "kwargs" in data_func_dict, "No data to process: specify `kwargs` in `additional_inputs`"
- data.update(func(image_idx, **data_func_dict["kwargs"]))
+ if self.has_masks:
+ mask_filepath = self.dataparser_outputs.mask_filenames[image_idx]
+ data["mask"] = get_image_mask_tensor_from_path(filepath=mask_filepath)
+ metadata = self.get_metadata(data)
+ data.update(metadata)
return data
- def __getitem__(self, image_idx):
+ # pylint: disable=no-self-use
+ def get_metadata(self, data: Dict) -> Dict:
+ """Method that can be used to process any additional metadata that may be part of the model inputs.
+
+ Args:
+ image_idx: The image index in the dataset.
+ """
+ del data
+ return {}
+
+ def __getitem__(self, image_idx: int) -> Dict:
data = self.get_data(image_idx)
return data
diff --git a/nerfstudio/data/datasets/semantic_dataset.py b/nerfstudio/data/datasets/semantic_dataset.py
new file mode 100644
index 000000000..f2c2a0910
--- /dev/null
+++ b/nerfstudio/data/datasets/semantic_dataset.py
@@ -0,0 +1,53 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+Semantic dataset.
+"""
+
+from typing import Dict
+
+import torch
+
+from nerfstudio.data.dataparsers.base_dataparser import DataparserOutputs, Semantics
+from nerfstudio.data.datasets.base_dataset import InputDataset
+from nerfstudio.data.utils.data_utils import get_semantics_and_mask_tensors_from_path
+
+
+class SemanticDataset(InputDataset):
+ """Dataset that returns images and semantics and masks.
+
+ Args:
+ dataparser_outputs: description of where and how to read input images.
+ """
+
+ def __init__(self, dataparser_outputs: DataparserOutputs):
+ super().__init__(dataparser_outputs)
+ assert "semantics" in dataparser_outputs.metadata.keys() and isinstance(
+ dataparser_outputs.metadata["semantics"], Semantics
+ )
+ self.semantics = dataparser_outputs.metadata["semantics"]
+ self.mask_indices = torch.tensor(
+ [self.semantics.classes.index(mask_class) for mask_class in self.semantics.mask_classes]
+ ).view(1, 1, -1)
+
+ def get_metadata(self, data: Dict) -> Dict:
+ # handle mask
+ filepath = self.semantics.filenames[data["image_idx"]]
+ semantic_label, mask = get_semantics_and_mask_tensors_from_path(
+ filepath=filepath, mask_indices=self.mask_indices
+ )
+ if "mask" in data.keys():
+ mask = mask & data["mask"]
+ return {"mask": mask, "semantics": semantic_label}
diff --git a/nerfstudio/data/pixel_samplers.py b/nerfstudio/data/pixel_samplers.py
index 432a8210f..cec02176a 100644
--- a/nerfstudio/data/pixel_samplers.py
+++ b/nerfstudio/data/pixel_samplers.py
@@ -48,30 +48,13 @@ def collate_image_dataset_batch(batch: Dict, num_rays_per_batch: int, keep_full_
).long()
c, y, x = (i.flatten() for i in torch.split(indices, 1, dim=-1))
- image = batch["image"][c, y, x]
- mask, semantics_stuff, semantics_thing = None, None, None
- if "mask" in batch:
- mask = batch["mask"][c, y, x]
- if "semantics_stuff" in batch:
- semantics_stuff = batch["semantics_stuff"][c, y, x]
- if "semantics_thing" in batch:
- semantics_thing = batch["semantics_thing"][c, y, x]
- assert image.shape == (num_rays_per_batch, 3), image.shape
+ collated_batch = {key: value[c, y, x] for key, value in batch.items() if key != "image_idx" and value is not None}
+
+ assert collated_batch["image"].shape == (num_rays_per_batch, 3), collated_batch["image"].shape
# Needed to correct the random indices to their actual camera idx locations.
- local_indices = indices.clone()
indices[:, 0] = batch["image_idx"][c]
- collated_batch = {
- "local_indices": local_indices, # local to the batch returned
- "indices": indices, # with the abs camera indices
- "image": image,
- }
- if mask is not None:
- collated_batch["mask"] = mask
- if semantics_stuff is not None:
- collated_batch["semantics_stuff"] = semantics_stuff
- if semantics_thing is not None:
- collated_batch["semantics_thing"] = semantics_thing
+ collated_batch["indices"] = indices # with the abs camera indices
if keep_full_image:
collated_batch["full_image"] = batch["image"]
diff --git a/nerfstudio/data/utils/data_utils.py b/nerfstudio/data/utils/data_utils.py
new file mode 100644
index 000000000..953e7951b
--- /dev/null
+++ b/nerfstudio/data/utils/data_utils.py
@@ -0,0 +1,45 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Utility functions to allow easy re-use of common operations across dataloaders"""
+from pathlib import Path
+from typing import List, Tuple, Union
+
+import numpy as np
+import torch
+from PIL import Image
+
+
+def get_image_mask_tensor_from_path(filepath: Path) -> torch.Tensor:
+ """
+ Utility function to read a mask image from the given path and return a boolean tensor
+ """
+ pil_mask = Image.open(filepath)
+ mask_tensor = torch.from_numpy(np.array(pil_mask)).unsqueeze(-1).bool()
+ return mask_tensor
+
+
+def get_semantics_and_mask_tensors_from_path(
+ filepath: Path, mask_indices: Union[List, torch.Tensor]
+) -> Tuple[torch.Tensor, torch.Tensor]:
+ """
+ Utility function to read segmentation from the given filepath
+ If no mask is required - use mask_indices = []
+ """
+ if isinstance(mask_indices, List):
+ mask_indices = torch.tensor(mask_indices, dtype="int64").view(1, 1, -1)
+ pil_image = Image.open(filepath)
+ semantics = torch.from_numpy(np.array(pil_image, dtype="int64"))[..., None]
+ mask = torch.sum(semantics == mask_indices, dim=-1, keepdim=True) == 0
+ return semantics, mask
diff --git a/nerfstudio/data/utils/dataloaders.py b/nerfstudio/data/utils/dataloaders.py
index fab0db183..5eec5e530 100644
--- a/nerfstudio/data/utils/dataloaders.py
+++ b/nerfstudio/data/utils/dataloaders.py
@@ -21,15 +21,17 @@ from abc import abstractmethod
from typing import Dict, Optional, Tuple, Union
import torch
-from rich.progress import track
+from rich.progress import Console, track
from torch.utils.data import Dataset, default_collate
from torch.utils.data.dataloader import DataLoader
from nerfstudio.cameras.cameras import Cameras
from nerfstudio.cameras.rays import RayBundle
-from nerfstudio.data.utils.datasets import InputDataset
+from nerfstudio.data.datasets.base_dataset import InputDataset
from nerfstudio.utils.misc import get_dict_to_torch
+CONSOLE = Console(width=120)
+
class CacheDataloader(DataLoader):
"""Collated image dataset that implements caching of default-pytorch-collatable data.
@@ -38,7 +40,7 @@ class CacheDataloader(DataLoader):
Args:
dataset: Dataset to sample from.
num_samples_to_collate: How many images to sample rays for each batch. -1 for all images.
- num_times_to_repeat_images: How often to collate new images.
+ num_times_to_repeat_images: How often to collate new images. -1 to never pick new images.
device: Device to perform computation.
"""
@@ -46,13 +48,13 @@ class CacheDataloader(DataLoader):
self,
dataset: Dataset,
num_images_to_sample_from: int = -1,
- num_times_to_repeat_images: int = 0,
+ num_times_to_repeat_images: int = -1,
device: Union[torch.device, str] = "cpu",
**kwargs,
):
self.dataset = dataset
self.num_times_to_repeat_images = num_times_to_repeat_images
- self.cache_all_images = num_images_to_sample_from == -1
+ self.cache_all_images = (num_images_to_sample_from == -1) or (num_images_to_sample_from >= len(self.dataset))
self.num_images_to_sample_from = len(self.dataset) if self.cache_all_images else num_images_to_sample_from
self.device = device
@@ -61,7 +63,21 @@ class CacheDataloader(DataLoader):
self.cached_collated_batch = None
if self.cache_all_images:
+ CONSOLE.print(f"Caching all {len(self.dataset)} images.")
+ if len(self.dataset) > 500:
+ CONSOLE.print(
+ "[bold yellow]Warning: If you run out of memory, try reducing the number of images to sample from."
+ )
self.cached_collated_batch = self._get_collated_batch()
+ elif self.num_times_to_repeat_images == -1:
+ CONSOLE.print(
+ f"Caching {self.num_images_to_sample_from} out of {len(self.dataset)} images, without resampling."
+ )
+ else:
+ CONSOLE.print(
+ f"Caching {self.num_images_to_sample_from} out of {len(self.dataset)} images, "
+ f"resampling every {self.num_times_to_repeat_images} iters."
+ )
super().__init__(dataset=dataset, **kwargs)
def __getitem__(self, idx):
@@ -150,6 +166,7 @@ class EvalDataloader(DataLoader):
camera_to_worlds=self.cameras.camera_to_worlds[image_idx : image_idx + 1],
distortion_params=distortion_params,
camera_type=self.cameras.camera_type[image_idx : image_idx + 1],
+ times=self.cameras.times[image_idx : image_idx + 1] if self.cameras.time else None,
)
return camera
diff --git a/nerfstudio/engine/trainer.py b/nerfstudio/engine/trainer.py
index 5b9b60c73..d35ebfeee 100644
--- a/nerfstudio/engine/trainer.py
+++ b/nerfstudio/engine/trainer.py
@@ -26,6 +26,7 @@ from typing import Dict, List, Tuple
import torch
from rich.console import Console
from torch.cuda.amp.grad_scaler import GradScaler
+from typing_extensions import Literal
from nerfstudio.configs import base_config as cfg
from nerfstudio.engine.callbacks import (
@@ -90,7 +91,7 @@ class Trainer:
# set up viewer if enabled
viewer_log_path = self.base_dir / config.viewer.relative_log_filename
self.viewer_state, banner_messages = None, None
- if self.config.is_viewer_enabled():
+ if self.config.is_viewer_enabled() and local_rank == 0:
self.viewer_state, banner_messages = viewer_utils.setup_viewer(config.viewer, log_filename=viewer_log_path)
self._check_viewer_warnings()
# set up writers/profilers if enabled
@@ -102,11 +103,14 @@ class Trainer:
writer.put_config(name="config", config_dict=dataclasses.asdict(config), step=0)
profiler.setup_profiler(config.logging)
- def setup(self, test_mode=False):
+ def setup(self, test_mode: Literal["test", "val", "inference"] = "val"):
"""Setup the Trainer by calling other setup functions.
Args:
- test_mode: Whether to setup for testing. Defaults to False.
+ test_mode:
+ 'val': loads train/val datasets into memory
+ 'test': loads train/test datset into memory
+ 'inference': does not load any dataset into memory
"""
self.pipeline = self.config.pipeline.setup(
device=self.device, test_mode=test_mode, world_size=self.world_size, local_rank=self.local_rank
@@ -131,6 +135,7 @@ class Trainer:
self._init_viewer_state()
with TimeWriter(writer, EventName.TOTAL_TRAIN_TIME):
num_iterations = self.config.trainer.max_num_iterations
+ step = 0
for step in range(self._start_step, self._start_step + num_iterations):
with TimeWriter(writer, EventName.ITER_TRAIN_TIME, step=step) as train_t:
@@ -149,12 +154,14 @@ class Trainer:
for callback in self.callbacks:
callback.run_callback_at_location(step, location=TrainingCallbackLocation.AFTER_TRAIN_ITERATION)
- writer.put_time(
- name=EventName.TRAIN_RAYS_PER_SEC,
- duration=self.config.pipeline.datamanager.train_num_rays_per_batch / train_t.duration,
- step=step,
- avg_over_steps=True,
- )
+ # Skip the first two steps to avoid skewed timings that break the viewer rendering speed estimate.
+ if step > 1:
+ writer.put_time(
+ name=EventName.TRAIN_RAYS_PER_SEC,
+ duration=self.config.pipeline.datamanager.train_num_rays_per_batch / train_t.duration,
+ step=step,
+ avg_over_steps=True,
+ )
self._update_viewer_state(step)
@@ -172,14 +179,21 @@ class Trainer:
writer.write_out_storage()
# save checkpoint at the end of training
self.save_checkpoint(step)
- self._always_render(step)
+ CONSOLE.rule()
+ CONSOLE.print("[bold green]:tada: :tada: :tada: Training Finished :tada: :tada: :tada:", justify="center")
+ if not self.config.viewer.quit_on_train_completion:
+ CONSOLE.print("Use ctrl+c to quit", justify="center")
+ self._always_render(step)
+
+ @check_main_thread
def _always_render(self, step):
if self.config.is_viewer_enabled():
while True:
self.viewer_state.vis["renderingState/isTraining"].write(False)
self._update_viewer_state(step)
+ @check_main_thread
def _check_viewer_warnings(self) -> None:
"""Helper to print out any warnings regarding the way the viewer/loggers are enabled"""
if self.config.is_viewer_enabled():
diff --git a/nerfstudio/field_components/encodings.py b/nerfstudio/field_components/encodings.py
index 7e149e531..65bff8244 100644
--- a/nerfstudio/field_components/encodings.py
+++ b/nerfstudio/field_components/encodings.py
@@ -416,7 +416,6 @@ class TensorVMEncoding(Encoding):
self.resolution = resolution
self.num_components = num_components
- # TODO(terrance): Learning rates should be different for these
self.plane_coef = nn.Parameter(init_scale * torch.randn((3, num_components, resolution, resolution)))
self.line_coef = nn.Parameter(init_scale * torch.randn((3, num_components, resolution, 1)))
@@ -424,7 +423,6 @@ class TensorVMEncoding(Encoding):
return self.num_components * 3
def forward(self, in_tensor: TensorType["bs":..., "input_dim"]) -> TensorType["bs":..., "output_dim"]:
- in_tensor = in_tensor / 4.0 + 0.5
plane_coord = torch.stack([in_tensor[..., [0, 1]], in_tensor[..., [0, 2]], in_tensor[..., [1, 2]]]) # [3,...,2]
line_coord = torch.stack([in_tensor[..., 2], in_tensor[..., 1], in_tensor[..., 0]]) # [3, ...]
line_coord = torch.stack([torch.zeros_like(line_coord), line_coord], dim=-1) # [3, ...., 2]
@@ -452,6 +450,7 @@ class TensorVMEncoding(Encoding):
self.plane_coef.data, size=(resolution, resolution), mode="bilinear", align_corners=True
)
line_coef = F.interpolate(self.line_coef.data, size=(resolution, 1), mode="bilinear", align_corners=True)
+
# TODO(ethan): are these torch.nn.Parameters needed?
self.plane_coef, self.line_coef = torch.nn.Parameter(plane_coef), torch.nn.Parameter(line_coef)
self.resolution = resolution
diff --git a/nerfstudio/field_components/field_heads.py b/nerfstudio/field_components/field_heads.py
index c11a827d1..702cafd81 100644
--- a/nerfstudio/field_components/field_heads.py
+++ b/nerfstudio/field_components/field_heads.py
@@ -181,33 +181,3 @@ class SemanticFieldHead(FieldHead):
def __init__(self, num_classes: int, in_dim: Optional[int] = None) -> None:
super().__init__(in_dim=in_dim, out_dim=num_classes, field_head_name=FieldHeadNames.SEMANTICS, activation=None)
-
-
-class SemanticStuffFieldHead(FieldHead):
- """Semantic stuff output
-
- Args:
- num_classes: Number of semantic classes
- in_dim: input dimension. If not defined in constructor, it must be set later.
- activation: output head activation
- """
-
- def __init__(self, num_classes: int, in_dim: Optional[int] = None) -> None:
- super().__init__(
- in_dim=in_dim, out_dim=num_classes, field_head_name=FieldHeadNames.SEMANTICS_STUFF, activation=None
- )
-
-
-class SemanticThingFieldHead(FieldHead):
- """Semantic thing output
-
- Args:
- num_classes: Number of semantic classes
- in_dim: input dimension. If not defined in constructor, it must be set later.
- activation: output head activation
- """
-
- def __init__(self, num_classes: int, in_dim: Optional[int] = None) -> None:
- super().__init__(
- in_dim=in_dim, out_dim=num_classes, field_head_name=FieldHeadNames.SEMANTICS_THING, activation=None
- )
diff --git a/nerfstudio/field_components/mlp.py b/nerfstudio/field_components/mlp.py
index 7774e043a..312714a23 100644
--- a/nerfstudio/field_components/mlp.py
+++ b/nerfstudio/field_components/mlp.py
@@ -15,7 +15,7 @@
"""
Multi Layer Perceptron
"""
-from typing import Optional, Tuple
+from typing import Optional, Set, Tuple
import torch
from torch import nn
@@ -54,6 +54,7 @@ class MLP(FieldComponent):
self.num_layers = num_layers
self.layer_width = layer_width
self.skip_connections = skip_connections
+ self._skip_connections: Set[int] = set(skip_connections) if skip_connections else set()
self.activation = activation
self.out_activation = out_activation
self.net = None
@@ -67,10 +68,9 @@ class MLP(FieldComponent):
else:
for i in range(self.num_layers - 1):
if i == 0:
- if self.skip_connections is not None:
- assert i not in list(self.skip_connections), "Skip connection at layer 0 doesn't make sense."
+ assert i not in self._skip_connections, "Skip connection at layer 0 doesn't make sense."
layers.append(nn.Linear(self.in_dim, self.layer_width))
- elif self.skip_connections is not None and i in self.skip_connections:
+ elif i in self._skip_connections:
layers.append(nn.Linear(self.layer_width + self.in_dim, self.layer_width))
else:
layers.append(nn.Linear(self.layer_width, self.layer_width))
@@ -88,9 +88,12 @@ class MLP(FieldComponent):
"""
x = in_tensor
for i, layer in enumerate(self.layers):
- if self.skip_connections is not None and i in self.skip_connections:
+ # as checked in `build_nn_modules`, 0 should not be in `_skip_connections`
+ if i in self._skip_connections:
x = torch.cat([in_tensor, x], -1)
x = layer(x)
- if self.activation:
+ if self.activation is not None and i < len(self.layers) - 1:
x = self.activation(x)
+ if self.out_activation is not None:
+ x = self.out_activation(x)
return x
diff --git a/nerfstudio/field_components/temporal_distortions.py b/nerfstudio/field_components/temporal_distortions.py
new file mode 100644
index 000000000..cd50893e4
--- /dev/null
+++ b/nerfstudio/field_components/temporal_distortions.py
@@ -0,0 +1,92 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Space distortions which occur as a function of time."""
+
+from enum import Enum
+from typing import Any, Dict, Optional, Tuple
+
+import torch
+from torch import nn
+from torchtyping import TensorType
+
+from nerfstudio.field_components.encodings import Encoding, NeRFEncoding
+from nerfstudio.field_components.mlp import MLP
+
+
+class TemporalDistortion(nn.Module):
+ """Apply spatial distortions as a function of time"""
+
+ def forward(self, positions: TensorType["bs":..., 3], times: Optional[TensorType[1]]) -> TensorType["bs":..., 3]:
+ """
+ Args:
+ positions: Samples to translate as a function of time
+ times: times for each sample
+
+ Returns:
+ Translated positions.
+ """
+
+
+class TemporalDistortionKind(Enum):
+ """Possible temporal distortion names"""
+
+ DNERF = "dnerf"
+
+ def to_temporal_distortion(self, config: Dict[str, Any]) -> TemporalDistortion:
+ """Converts this kind to a temporal distortion"""
+ if self == TemporalDistortionKind.DNERF:
+ return DNeRFDistortion(**config)
+ raise NotImplementedError(f"Unknown temporal distortion kind {self}")
+
+
+class DNeRFDistortion(TemporalDistortion):
+ """Optimizable temporal deformation using an MLP.
+ Args:
+ position_encoding: An encoding for the XYZ of distortion
+ temporal_encoding: An encoding for the time of distortion
+ mlp_num_layers: Number of layers in distortion MLP
+ mlp_layer_width: Size of hidden layer for the MLP
+ skip_connections: Number of layers for skip connections in the MLP
+ """
+
+ def __init__(
+ self,
+ position_encoding: Encoding = NeRFEncoding(
+ in_dim=3, num_frequencies=10, min_freq_exp=0.0, max_freq_exp=8.0, include_input=True
+ ),
+ temporal_encoding: Encoding = NeRFEncoding(
+ in_dim=1, num_frequencies=10, min_freq_exp=0.0, max_freq_exp=8.0, include_input=True
+ ),
+ mlp_num_layers: int = 4,
+ mlp_layer_width: int = 256,
+ skip_connections: Tuple[int] = (4,),
+ ) -> None:
+ super().__init__()
+ self.position_encoding = position_encoding
+ self.temporal_encoding = temporal_encoding
+ self.mlp_deform = MLP(
+ in_dim=self.position_encoding.get_out_dim() + self.temporal_encoding.get_out_dim(),
+ out_dim=3,
+ num_layers=mlp_num_layers,
+ layer_width=mlp_layer_width,
+ skip_connections=skip_connections,
+ )
+
+ def forward(self, positions, times=None):
+ if times is None:
+ return None
+ p = self.position_encoding(positions)
+ t = self.temporal_encoding(times)
+ return self.mlp_deform(torch.cat([p, t], dim=-1))
diff --git a/nerfstudio/fields/nerfacto_field.py b/nerfstudio/fields/nerfacto_field.py
index 2634547b9..70d196b20 100644
--- a/nerfstudio/fields/nerfacto_field.py
+++ b/nerfstudio/fields/nerfacto_field.py
@@ -35,8 +35,7 @@ from nerfstudio.field_components.field_heads import (
FieldHead,
FieldHeadNames,
RGBFieldHead,
- SemanticStuffFieldHead,
- SemanticThingFieldHead,
+ SemanticFieldHead,
TransientDensityFieldHead,
TransientRGBFieldHead,
UncertaintyFieldHead,
@@ -95,8 +94,7 @@ class TCNNNerfactoField(Field):
transient_embedding_dim: int = 16,
use_transient_embedding: bool = False,
use_semantics: bool = False,
- num_semantics_thing_classes: int = 100,
- num_semantics_stuff_classes: int = 100,
+ num_semantic_classes: int = 100,
use_average_appearance_embedding: bool = False,
spatial_distortion: Optional[SpatialDistortion] = None,
) -> None:
@@ -180,11 +178,8 @@ class TCNNNerfactoField(Field):
"n_hidden_layers": 1,
},
)
- self.field_head_semantics_stuff = SemanticStuffFieldHead(
- in_dim=self.mlp_semantics.n_output_dims, num_classes=num_semantics_stuff_classes
- )
- self.field_head_semantics_thing = SemanticThingFieldHead(
- in_dim=self.mlp_semantics.n_output_dims, num_classes=num_semantics_thing_classes
+ self.field_head_semantics = SemanticFieldHead(
+ in_dim=self.mlp_semantics.n_output_dims, num_classes=num_semantic_classes
)
self.mlp_head = tcnn.Network(
@@ -266,8 +261,7 @@ class TCNNNerfactoField(Field):
)
# print(semantics_input)
x = self.mlp_semantics(semantics_input).view(*ray_samples.frustums.directions.shape[:-1], -1).to(directions)
- outputs[FieldHeadNames.SEMANTICS_STUFF] = self.field_head_semantics_stuff(x)
- outputs[FieldHeadNames.SEMANTICS_THING] = self.field_head_semantics_thing(x)
+ outputs[FieldHeadNames.SEMANTICS] = self.field_head_semantics(x)
h = torch.cat(
[
@@ -318,12 +312,14 @@ class TorchNerfactoField(Field):
num_layers=base_mlp_num_layers,
layer_width=base_mlp_layer_width,
skip_connections=skip_connections,
+ out_activation=nn.ReLU(),
)
self.mlp_head = MLP(
in_dim=self.mlp_base.get_out_dim() + self.direction_encoding.get_out_dim() + self.appearance_embedding_dim,
num_layers=head_mlp_num_layers,
layer_width=head_mlp_layer_width,
+ out_activation=nn.ReLU(),
)
self.field_output_density = DensityFieldHead(in_dim=self.mlp_base.get_out_dim())
diff --git a/nerfstudio/fields/nerfw_field.py b/nerfstudio/fields/nerfw_field.py
index fb1a25242..b2916fef4 100644
--- a/nerfstudio/fields/nerfw_field.py
+++ b/nerfstudio/fields/nerfw_field.py
@@ -83,6 +83,7 @@ class VanillaNerfWField(Field):
num_layers=base_mlp_num_layers,
layer_width=base_mlp_layer_width,
skip_connections=skip_connections,
+ out_activation=nn.ReLU(),
)
self.mlp_transient = MLP(
in_dim=self.mlp_base.get_out_dim() + self.embedding_transient.get_out_dim(),
@@ -90,6 +91,7 @@ class VanillaNerfWField(Field):
num_layers=4,
layer_width=base_mlp_layer_width,
activation=nn.ReLU(),
+ out_activation=nn.ReLU(),
)
self.mlp_head = MLP(
in_dim=self.mlp_base.get_out_dim()
@@ -97,6 +99,7 @@ class VanillaNerfWField(Field):
+ self.embedding_appearance.get_out_dim(),
num_layers=head_mlp_num_layers,
layer_width=head_mlp_layer_width,
+ out_activation=nn.ReLU(),
)
self.field_head_density = DensityFieldHead(in_dim=self.mlp_base.get_out_dim())
diff --git a/nerfstudio/fields/semantic_nerf_field.py b/nerfstudio/fields/semantic_nerf_field.py
index dcf07ae6a..fa53a9313 100644
--- a/nerfstudio/fields/semantic_nerf_field.py
+++ b/nerfstudio/fields/semantic_nerf_field.py
@@ -67,17 +67,20 @@ class SemanticNerfField(Field):
num_layers=base_mlp_num_layers,
layer_width=base_mlp_layer_width,
skip_connections=skip_connections,
+ out_activation=nn.ReLU(),
)
self.mlp_head = MLP(
in_dim=self.mlp_base.get_out_dim() + self.direction_encoding.get_out_dim(),
num_layers=head_mlp_num_layers,
layer_width=head_mlp_layer_width,
+ out_activation=nn.ReLU(),
)
self.mlp_semantic = MLP(
in_dim=self.mlp_head.get_out_dim(),
layer_width=self.mlp_head.layer_width // 2,
num_layers=1,
activation=nn.ReLU(),
+ out_activation=nn.ReLU(),
)
self.field_head_density = DensityFieldHead(in_dim=self.mlp_base.get_out_dim())
self.field_head_rgb = RGBFieldHead(in_dim=self.mlp_head.get_out_dim())
diff --git a/nerfstudio/fields/tensorf_field.py b/nerfstudio/fields/tensorf_field.py
new file mode 100644
index 000000000..4972fa1df
--- /dev/null
+++ b/nerfstudio/fields/tensorf_field.py
@@ -0,0 +1,136 @@
+# Copyright 2022 The Plenoptix Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""TensoRF Field"""
+
+
+from typing import Optional
+
+import torch
+from torch import nn
+from torch.nn.parameter import Parameter
+from torchtyping import TensorType
+
+from nerfstudio.cameras.rays import RaySamples
+from nerfstudio.data.scene_box import SceneBox
+from nerfstudio.field_components.encodings import Encoding, Identity, SHEncoding
+from nerfstudio.field_components.field_heads import FieldHeadNames, RGBFieldHead
+from nerfstudio.field_components.mlp import MLP
+from nerfstudio.fields.base_field import Field
+
+
+class TensoRFField(Field):
+ """TensoRF Field"""
+
+ def __init__(
+ self,
+ aabb,
+ # the aabb bounding box of the dataset
+ feature_encoding: Encoding = Identity(in_dim=3),
+ # the encoding method used for appearance encoding outputs
+ direction_encoding: Encoding = Identity(in_dim=3),
+ # the encoding method used for ray direction
+ density_encoding: Encoding = Identity(in_dim=3),
+ # the tensor encoding method used for scene density
+ color_encoding: Encoding = Identity(in_dim=3),
+ # the tensor encoding method used for scene color
+ appearance_dim: int = 27,
+ # the number of dimensions for the appearance embedding
+ head_mlp_num_layers: int = 2,
+ # number of layers for the MLP
+ head_mlp_layer_width: int = 128,
+ # layer width for the MLP
+ use_sh: bool = False,
+ # whether to use spherical harmonics as the feature decoding function
+ sh_levels: int = 2,
+ # number of levels to use for spherical harmonics
+ ) -> None:
+ super().__init__()
+ self.aabb = Parameter(aabb, requires_grad=False)
+ self.feature_encoding = feature_encoding
+ self.direction_encoding = direction_encoding
+ self.density_encoding = density_encoding
+ self.color_encoding = color_encoding
+
+ self.mlp_head = MLP(
+ in_dim=appearance_dim + 3 + self.direction_encoding.get_out_dim() + self.feature_encoding.get_out_dim(),
+ num_layers=head_mlp_num_layers,
+ layer_width=head_mlp_layer_width,
+ activation=nn.ReLU(),
+ out_activation=nn.ReLU(),
+ )
+
+ self.use_sh = use_sh
+
+ if self.use_sh:
+ self.sh = SHEncoding(sh_levels)
+ self.B = nn.Linear(
+ in_features=self.color_encoding.get_out_dim(), out_features=3 * self.sh.get_out_dim(), bias=False
+ )
+ else:
+ self.B = nn.Linear(in_features=self.color_encoding.get_out_dim(), out_features=appearance_dim, bias=False)
+
+ self.field_output_rgb = RGBFieldHead(in_dim=self.mlp_head.get_out_dim(), activation=nn.Sigmoid())
+
+ def get_density(self, ray_samples: RaySamples):
+ positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
+ density = self.density_encoding(positions)
+ density_enc = torch.sum(density, dim=-1)[:, :, None]
+ relu = torch.nn.ReLU()
+ density_enc = relu(density_enc)
+ return density_enc
+
+ def get_outputs(self, ray_samples: RaySamples, density_embedding: Optional[TensorType] = None) -> TensorType:
+ d = ray_samples.frustums.directions
+ positions = SceneBox.get_normalized_positions(ray_samples.frustums.get_positions(), self.aabb)
+ rgb_features = self.color_encoding(positions)
+ rgb_features = self.B(rgb_features)
+
+ d_encoded = self.direction_encoding(d)
+ rgb_features_encoded = self.feature_encoding(rgb_features)
+
+ if self.use_sh:
+ sh_mult = self.sh(d)[:, :, None]
+ rgb_sh = rgb_features.view(sh_mult.shape[0], sh_mult.shape[1], 3, sh_mult.shape[-1])
+ rgb = torch.relu(torch.sum(sh_mult * rgb_sh, dim=-1) + 0.5)
+ else:
+ out = self.mlp_head(torch.cat([rgb_features, d, rgb_features_encoded, d_encoded], dim=-1)) # type: ignore
+ rgb = self.field_output_rgb(out)
+
+ return rgb
+
+ def forward(
+ self, ray_samples: RaySamples, mask: Optional[TensorType] = None, bg_color: Optional[TensorType] = None
+ ):
+ if mask is not None and bg_color is not None:
+ base_density = torch.zeros(ray_samples.shape)[:, :, None].to(mask.device)
+ base_rgb = bg_color.repeat(ray_samples[:, :, None].shape)
+ if mask.any():
+ input_rays = ray_samples[mask, :]
+ density = self.get_density(input_rays)
+ rgb = self.get_outputs(input_rays, None)
+
+ base_density[mask] = density
+ base_rgb[mask] = rgb
+
+ base_density.requires_grad_()
+ base_rgb.requires_grad_()
+
+ density = base_density
+ rgb = base_rgb
+ else:
+ density = self.get_density(ray_samples)
+ rgb = self.get_outputs(ray_samples, None)
+
+ return {FieldHeadNames.DENSITY: density, FieldHeadNames.RGB: rgb}
diff --git a/nerfstudio/fields/vanilla_nerf_field.py b/nerfstudio/fields/vanilla_nerf_field.py
index c7c40b850..a30582d14 100644
--- a/nerfstudio/fields/vanilla_nerf_field.py
+++ b/nerfstudio/fields/vanilla_nerf_field.py
@@ -73,12 +73,14 @@ class NeRFField(Field):
num_layers=base_mlp_num_layers,
layer_width=base_mlp_layer_width,
skip_connections=skip_connections,
+ out_activation=nn.ReLU(),
)
self.mlp_head = MLP(
in_dim=self.mlp_base.get_out_dim() + self.direction_encoding.get_out_dim(),
num_layers=head_mlp_num_layers,
layer_width=head_mlp_layer_width,
+ out_activation=nn.ReLU(),
)
self.field_output_density = DensityFieldHead(in_dim=self.mlp_base.get_out_dim())
diff --git a/nerfstudio/model_components/exporters.py b/nerfstudio/model_components/exporters.py
new file mode 100644
index 000000000..947254500
--- /dev/null
+++ b/nerfstudio/model_components/exporters.py
@@ -0,0 +1,128 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+
+"""Algorithms for exporting data."""
+
+from __future__ import annotations
+
+import sys
+from typing import Tuple
+
+import open3d as o3d
+import torch
+from rich.console import Console
+from rich.progress import (
+ BarColumn,
+ Progress,
+ TaskProgressColumn,
+ TextColumn,
+ TimeRemainingColumn,
+)
+
+from nerfstudio.configs.base_config import Config # pylint: disable=unused-import
+from nerfstudio.pipelines.base_pipeline import Pipeline
+
+CONSOLE = Console(width=120)
+
+
+def generate_point_cloud(
+ pipeline: Pipeline,
+ num_points: int = 1000000,
+ remove_outliers: bool = True,
+ estimate_normals: bool = False,
+ rgb_output_name: str = "rgb",
+ depth_output_name: str = "depth",
+ use_bounding_box: bool = True,
+ bounding_box_min: Tuple[float, float, float] = (-1.0, -1.0, -1.0),
+ bounding_box_max: Tuple[float, float, float] = (1.0, 1.0, 1.0),
+) -> o3d.geometry.PointCloud:
+ """Generate a point cloud from a nerf.
+
+ Args:
+ pipeline: Pipeline to evaluate with.
+ num_points: Number of points to generate. May result in less if outlier removal is used.
+ remove_outliers: Whether to remove outliers.
+ estimate_normals: Whether to estimate normals.
+ rgb_output_name: Name of the RGB output.
+ depth_output_name: Name of the depth output.
+ use_bounding_box: Whether to use a bounding box to sample points.
+ bounding_box_min: Minimum of the bounding box.
+ bounding_box_max: Maximum of the bounding box.
+
+ Returns:
+ Point cloud.
+ """
+
+ progress = Progress(
+ TextColumn(":cloud: Computing Point Cloud :cloud:"),
+ BarColumn(),
+ TaskProgressColumn(show_speed=True),
+ TimeRemainingColumn(elapsed_when_finished=True, compact=True),
+ )
+ points = []
+ rgbs = []
+ with progress as progress_bar:
+ task = progress_bar.add_task("Generating Point Cloud", total=num_points)
+ while not progress_bar.finished:
+ with torch.no_grad():
+ ray_bundle, _ = pipeline.datamanager.next_train(0)
+ outputs = pipeline.model(ray_bundle)
+ if rgb_output_name not in outputs:
+ CONSOLE.rule("Error", style="red")
+ CONSOLE.print(f"Could not find {rgb_output_name} in the model outputs", justify="center")
+ CONSOLE.print(f"Please set --rgb_output_name to one of: {outputs.keys()}", justify="center")
+ sys.exit(1)
+ if depth_output_name not in outputs:
+ CONSOLE.rule("Error", style="red")
+ CONSOLE.print(f"Could not find {depth_output_name} in the model outputs", justify="center")
+ CONSOLE.print(f"Please set --depth_output_name to one of: {outputs.keys()}", justify="center")
+ sys.exit(1)
+ rgb = outputs[rgb_output_name]
+ depth = outputs[depth_output_name]
+ point = ray_bundle.origins + ray_bundle.directions * depth
+
+ if use_bounding_box:
+ comp_l = torch.tensor(bounding_box_min, device=point.device)
+ comp_m = torch.tensor(bounding_box_max, device=point.device)
+ assert torch.all(
+ comp_l < comp_m
+ ), f"Bounding box min {bounding_box_min} must be smaller than max {bounding_box_max}"
+ mask = torch.all(torch.concat([point > comp_l, point < comp_m], dim=-1), dim=-1)
+ point = point[mask]
+ rgb = rgb[mask]
+
+ points.append(point)
+ rgbs.append(rgb)
+ progress.advance(task, point.shape[0])
+ points = torch.cat(points, dim=0)
+ rgbs = torch.cat(rgbs, dim=0)
+
+ pcd = o3d.geometry.PointCloud()
+ pcd.points = o3d.utility.Vector3dVector(points.float().cpu().numpy())
+ pcd.colors = o3d.utility.Vector3dVector(rgbs.float().cpu().numpy())
+
+ if remove_outliers:
+ CONSOLE.print("Cleaning Point Cloud")
+ pcd, _ = pcd.remove_statistical_outlier(nb_neighbors=20, std_ratio=1.0)
+ print("\033[A\033[A")
+ CONSOLE.print("[bold green]:white_check_mark: Cleaning Point Cloud")
+
+ if estimate_normals:
+ CONSOLE.print("Estimating Point Cloud Normals")
+ pcd.estimate_normals()
+ print("\033[A\033[A")
+ CONSOLE.print("[bold green]:white_check_mark: Estimating Point Cloud Normals")
+
+ return pcd
diff --git a/nerfstudio/model_components/renderers.py b/nerfstudio/model_components/renderers.py
index 9604a1d5f..21726acc5 100644
--- a/nerfstudio/model_components/renderers.py
+++ b/nerfstudio/model_components/renderers.py
@@ -200,11 +200,15 @@ class AccumulationRenderer(nn.Module):
class DepthRenderer(nn.Module):
"""Calculate depth along ray.
+ Depth Method:
+ - median: Depth is set to the distance where the accumulated weight reaches 0.5.
+ - expected: Expected depth along ray. Same procedure as rendering rgb, but with depth.
+
Args:
- method (str, optional): Depth calculation method.
+ method: Depth calculation method.
"""
- def __init__(self, method: Literal["expected"] = "expected") -> None:
+ def __init__(self, method: Literal["median", "expected"] = "median") -> None:
super().__init__()
self.method = method
@@ -215,7 +219,7 @@ class DepthRenderer(nn.Module):
ray_indices: Optional[TensorType["num_samples"]] = None,
num_rays: Optional[int] = None,
) -> TensorType[..., 1]:
- """Composite samples along ray and calculate disparities.
+ """Composite samples along ray and calculate depths.
Args:
weights: Weights for each sample.
@@ -227,6 +231,17 @@ class DepthRenderer(nn.Module):
Outputs of depth values.
"""
+ if self.method == "median":
+ steps = (ray_samples.frustums.starts + ray_samples.frustums.ends) / 2
+
+ if ray_indices is not None and num_rays is not None:
+ raise NotImplementedError("Median depth calculation is not implemented for packed samples.")
+ cumulative_weights = torch.cumsum(weights[..., 0], dim=-1) # [..., num_samples]
+ split = torch.ones((*weights.shape[:-2], 1), device=weights.device) * 0.5 # [..., 1]
+ median_index = torch.searchsorted(cumulative_weights, split, side="left") # [..., 1]
+ median_index = torch.clamp(median_index, 0, steps.shape[-2] - 1) # [..., 1]
+ median_depth = torch.gather(steps[..., 0], dim=-1, index=median_index) # [..., 1]
+ return median_depth
if self.method == "expected":
eps = 1e-10
steps = (ray_samples.frustums.starts + ray_samples.frustums.ends) / 2
diff --git a/nerfstudio/model_components/scene_colliders.py b/nerfstudio/model_components/scene_colliders.py
index 88428f650..5cf178f99 100644
--- a/nerfstudio/model_components/scene_colliders.py
+++ b/nerfstudio/model_components/scene_colliders.py
@@ -13,7 +13,7 @@
# limitations under the License.
"""
-Ray generator.
+Scene Colliders
"""
from __future__ import annotations
@@ -84,6 +84,7 @@ class AABBBoxCollider(SceneBoxCollider):
# clamp to near plane
near_plane = self.near_plane if self.training else 0
nears = torch.clamp(nears, min=near_plane)
+ fars = torch.maximum(fars, nears + 1e-6)
return nears, fars
diff --git a/nerfstudio/models/base_model.py b/nerfstudio/models/base_model.py
index ef36f53c8..6be459343 100644
--- a/nerfstudio/models/base_model.py
+++ b/nerfstudio/models/base_model.py
@@ -77,6 +77,7 @@ class Model(nn.Module):
self.num_train_data = num_train_data
self.kwargs = kwargs
self.collider = None
+
self.populate_modules() # populate the modules
self.callbacks = None
# to keep track of which device the nn.Module is on
@@ -208,13 +209,3 @@ class Model(nn.Module):
"""
state = {key.replace("module.", ""): value for key, value in loaded_state["model"].items()}
self.load_state_dict(state) # type: ignore
-
-
-@dataclass
-class VanillaModelConfig(ModelConfig):
- """Vanilla Model Config"""
-
- num_coarse_samples: int = 64
- """Number of samples in coarse field evaluation"""
- num_importance_samples: int = 128
- """Number of samples in fine field evaluation"""
diff --git a/nerfstudio/models/instant_ngp.py b/nerfstudio/models/instant_ngp.py
index 480c52ee8..f30d2ad9a 100644
--- a/nerfstudio/models/instant_ngp.py
+++ b/nerfstudio/models/instant_ngp.py
@@ -125,7 +125,7 @@ class NGPModel(Model):
background_color = "random" if self.config.randomize_background else colors.WHITE
self.renderer_rgb = RGBRenderer(background_color=background_color)
self.renderer_accumulation = AccumulationRenderer()
- self.renderer_depth = DepthRenderer()
+ self.renderer_depth = DepthRenderer(method="expected")
# losses
self.rgb_loss = MSELoss()
diff --git a/nerfstudio/models/semantic_nerfw.py b/nerfstudio/models/semantic_nerfw.py
index c30804439..3f9dcad86 100644
--- a/nerfstudio/models/semantic_nerfw.py
+++ b/nerfstudio/models/semantic_nerfw.py
@@ -72,8 +72,9 @@ class SemanticNerfWModel(Model):
config: SemanticNerfWModelConfig
- def __init__(self, config: SemanticNerfWModelConfig, semantics: Semantics, **kwargs) -> None:
- self.semantics = semantics
+ def __init__(self, config: SemanticNerfWModelConfig, metadata: Dict, **kwargs) -> None:
+ assert "semantics" in metadata.keys() and isinstance(metadata["semantics"], Semantics)
+ self.semantics = metadata["semantics"]
super().__init__(config=config, **kwargs)
def populate_modules(self):
@@ -93,8 +94,7 @@ class SemanticNerfWModel(Model):
use_average_appearance_embedding=self.config.use_average_appearance_embedding,
use_transient_embedding=self.config.use_transient_embedding,
use_semantics=True,
- num_semantics_stuff_classes=len(self.semantics.stuff_classes),
- num_semantics_thing_classes=len(self.semantics.thing_classes),
+ num_semantic_classes=len(self.semantics.classes),
)
# Build the proposal network(s)
@@ -204,20 +204,13 @@ class SemanticNerfWModel(Model):
outputs["density_transient"] = field_outputs[FieldHeadNames.TRANSIENT_DENSITY]
# semantics
- outputs["semantics_thing"] = self.renderer_semantics(
- field_outputs[FieldHeadNames.SEMANTICS_THING], weights=weights_static.detach()
- )
- outputs["semantics_stuff"] = self.renderer_semantics(
- field_outputs[FieldHeadNames.SEMANTICS_STUFF], weights=weights_static.detach()
+ outputs["semantics"] = self.renderer_semantics(
+ field_outputs[FieldHeadNames.SEMANTICS], weights=weights_static.detach()
)
# semantics colormaps
- semantic_labels = torch.argmax(torch.nn.functional.softmax(outputs["semantics_stuff"], dim=-1), dim=-1)
- outputs["semantics_colormap_stuff"] = self.semantics.stuff_colors[semantic_labels]
- semantic_labels = torch.argmax(torch.nn.functional.softmax(outputs["semantics_thing"], dim=-1), dim=-1)
- outputs["semantics_colormap_thing"] = self.semantics.thing_colors[semantic_labels]
- # TODO: adding these together is incorrect and produces weird results
- outputs["semantics_colormap"] = outputs["semantics_colormap_stuff"] + outputs["semantics_colormap_thing"]
+ semantic_labels = torch.argmax(torch.nn.functional.softmax(outputs["semantics"], dim=-1), dim=-1)
+ outputs["semantics_colormap"] = self.semantics.colors[semantic_labels]
return outputs
@@ -247,12 +240,7 @@ class SemanticNerfWModel(Model):
loss_dict["rgb_loss"] = self.rgb_loss(image, outputs["rgb"])
# semantic loss
- loss_dict["semantics_stuff_loss"] = self.cross_entropy_loss(
- outputs["semantics_stuff"], batch["semantics_stuff"][..., 0].long()
- )
- loss_dict["semantics_thing_loss"] = self.cross_entropy_loss(
- outputs["semantics_thing"], batch["semantics_thing"][..., 0].long()
- )
+ loss_dict["semantics_loss"] = self.cross_entropy_loss(outputs["semantics"], batch["semantics"][..., 0].long())
return loss_dict
def get_image_metrics_and_images(
@@ -295,14 +283,8 @@ class SemanticNerfWModel(Model):
images_dict[key] = prop_depth_i
# semantics
- semantic_labels = torch.argmax(torch.nn.functional.softmax(outputs["semantics_stuff"], dim=-1), dim=-1)
- images_dict["semantics_colormap_stuff"] = self.semantics.stuff_colors[semantic_labels]
- semantic_labels = torch.argmax(torch.nn.functional.softmax(outputs["semantics_thing"], dim=-1), dim=-1)
- images_dict["semantics_colormap_thing"] = self.semantics.thing_colors[semantic_labels]
- # TODO: adding these together is incorrect and produces weird results
- images_dict["semantics_colormap"] = (
- images_dict["semantics_colormap_stuff"] + images_dict["semantics_colormap_thing"]
- )
+ semantic_labels = torch.argmax(torch.nn.functional.softmax(outputs["semantics"], dim=-1), dim=-1)
+ images_dict["semantics_colormap"] = self.semantics.colors[semantic_labels]
# valid mask
images_dict["mask"] = batch["mask"].repeat(1, 1, 3)
diff --git a/nerfstudio/models/tensorf.py b/nerfstudio/models/tensorf.py
new file mode 100644
index 000000000..e3fa1ee65
--- /dev/null
+++ b/nerfstudio/models/tensorf.py
@@ -0,0 +1,280 @@
+# Copyright 2022 The Nerfstudio Team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""
+TensorRF implementation.
+"""
+
+from __future__ import annotations
+
+from dataclasses import dataclass, field
+from typing import Dict, List, Tuple, Type
+
+import numpy as np
+import torch
+from torch.nn import Parameter
+from torchmetrics import PeakSignalNoiseRatio
+from torchmetrics.functional import structural_similarity_index_measure
+from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
+
+from nerfstudio.cameras.rays import RayBundle
+from nerfstudio.configs.config_utils import to_immutable_dict
+from nerfstudio.engine.callbacks import (
+ TrainingCallback,
+ TrainingCallbackAttributes,
+ TrainingCallbackLocation,
+)
+from nerfstudio.field_components.encodings import NeRFEncoding, TensorVMEncoding
+from nerfstudio.field_components.field_heads import FieldHeadNames
+from nerfstudio.fields.tensorf_field import TensoRFField
+from nerfstudio.model_components.losses import MSELoss
+from nerfstudio.model_components.ray_samplers import PDFSampler, UniformSampler
+from nerfstudio.model_components.renderers import (
+ AccumulationRenderer,
+ DepthRenderer,
+ RGBRenderer,
+)
+from nerfstudio.model_components.scene_colliders import AABBBoxCollider
+from nerfstudio.models.base_model import Model, ModelConfig
+from nerfstudio.utils import colormaps, colors, misc
+
+
+@dataclass
+class TensoRFModelConfig(ModelConfig):
+ """TensoRF model config"""
+
+ _target: Type = field(default_factory=lambda: TensoRFModel)
+ """target class to instantiate"""
+ init_resolution: int = 128
+ """initial render resolution"""
+ final_resolution: int = 300
+ """final render resolution"""
+ upsampling_iters: Tuple[int, ...] = (2000, 3000, 4000, 5500, 7000)
+ """specifies a list of iteration step numbers to perform upsampling"""
+ loss_coefficients: Dict[str, float] = to_immutable_dict({"rgb_loss": 1.0})
+ """Loss specific weights."""
+ num_samples: int = 256
+ """Number of samples in field evaluation"""
+ num_den_components: int = 16
+ """Number of components in density encoding"""
+ num_color_components: int = 48
+ """Number of components in color encoding"""
+ appearance_dim: int = 27
+ """Number of channels for color encoding"""
+
+
+class TensoRFModel(Model):
+ """TensoRF Model
+
+ Args:
+ config: TensoRF configuration to instantiate model
+ """
+
+ def __init__(
+ self,
+ config: TensoRFModelConfig,
+ **kwargs,
+ ) -> None:
+ self.init_resolution = config.init_resolution
+ self.upsampling_iters = config.upsampling_iters
+ self.num_den_components = config.num_den_components
+ self.num_color_components = config.num_color_components
+ self.appearance_dim = config.appearance_dim
+ self.upsampling_steps = (
+ np.round(
+ np.exp(
+ np.linspace(
+ np.log(config.init_resolution),
+ np.log(config.final_resolution),
+ len(config.upsampling_iters) + 1,
+ )
+ )
+ )
+ .astype("int")
+ .tolist()[1:]
+ )
+ super().__init__(config=config, **kwargs)
+
+ def get_training_callbacks(
+ self, training_callback_attributes: TrainingCallbackAttributes
+ ) -> List[TrainingCallback]:
+
+ # the callback that we want to run every X iterations after the training iteration
+ def reinitialize_optimizer(
+ self, training_callback_attributes: TrainingCallbackAttributes, step: int # pylint: disable=unused-argument
+ ):
+ resolution = self.upsampling_steps.pop(0)
+
+ # upsample the position and direction grids
+ self.field.density_encoding.upsample_grid(resolution)
+ self.field.color_encoding.upsample_grid(resolution)
+
+ # reinitialize the encodings optimizer
+ optimizers_config = training_callback_attributes.optimizers.config
+ enc = training_callback_attributes.pipeline.get_param_groups()["encodings"]
+ lr_init = optimizers_config["encodings"]["optimizer"].lr
+
+ training_callback_attributes.optimizers.optimizers["encodings"] = optimizers_config["encodings"][
+ "optimizer"
+ ].setup(params=enc)
+ if optimizers_config["encodings"]["scheduler"]:
+ training_callback_attributes.optimizers.schedulers["encodings"] = optimizers_config["encodings"][
+ "scheduler"
+ ].setup(optimizer=training_callback_attributes.optimizers.optimizers["encodings"], lr_init=lr_init)
+
+ callbacks = [
+ TrainingCallback(
+ where_to_run=[TrainingCallbackLocation.AFTER_TRAIN_ITERATION],
+ iters=self.upsampling_iters,
+ func=reinitialize_optimizer,
+ args=[self, training_callback_attributes],
+ )
+ ]
+ return callbacks
+
+ def populate_modules(self):
+ """Set the fields and modules"""
+ super().populate_modules()
+
+ # setting up fields
+ density_encoding = TensorVMEncoding(
+ resolution=self.init_resolution,
+ num_components=self.num_den_components,
+ )
+ color_encoding = TensorVMEncoding(
+ resolution=self.init_resolution,
+ num_components=self.num_color_components,
+ )
+
+ feature_encoding = NeRFEncoding(in_dim=self.appearance_dim, num_frequencies=2, min_freq_exp=0, max_freq_exp=2)
+ direction_encoding = NeRFEncoding(in_dim=3, num_frequencies=2, min_freq_exp=0, max_freq_exp=2)
+
+ self.field = TensoRFField(
+ self.scene_box.aabb,
+ feature_encoding=feature_encoding,
+ direction_encoding=direction_encoding,
+ density_encoding=density_encoding,
+ color_encoding=color_encoding,
+ appearance_dim=self.appearance_dim,
+ head_mlp_num_layers=2,
+ head_mlp_layer_width=128,
+ use_sh=False,
+ )
+
+ # samplers
+ self.sampler_uniform = UniformSampler(num_samples=self.config.num_samples, single_jitter=True)
+ self.sampler_pdf = PDFSampler(num_samples=self.config.num_samples // 2, single_jitter=True)
+
+ # renderers
+ self.renderer_rgb = RGBRenderer(background_color=colors.WHITE)
+ self.renderer_accumulation = AccumulationRenderer()
+ self.renderer_depth = DepthRenderer()
+
+ # losses
+ self.rgb_loss = MSELoss()
+
+ # metrics
+ self.psnr = PeakSignalNoiseRatio(data_range=1.0)
+ self.ssim = structural_similarity_index_measure
+ self.lpips = LearnedPerceptualImagePatchSimilarity()
+
+ # colliders
+ if self.config.enable_collider:
+ self.collider = AABBBoxCollider(scene_box=self.scene_box)
+
+ def get_param_groups(self) -> Dict[str, List[Parameter]]:
+ param_groups = {}
+
+ param_groups["fields"] = (
+ list(self.field.mlp_head.parameters())
+ + list(self.field.B.parameters())
+ + list(self.field.field_output_rgb.parameters())
+ )
+ param_groups["encodings"] = list(self.field.color_encoding.parameters()) + list(
+ self.field.density_encoding.parameters()
+ )
+
+ return param_groups
+
+ def get_outputs(self, ray_bundle: RayBundle):
+ # uniform sampling
+ ray_samples_uniform = self.sampler_uniform(ray_bundle)
+ dens = self.field.get_density(ray_samples_uniform)
+ weights = ray_samples_uniform.get_weights(dens)
+ coarse_accumulation = self.renderer_accumulation(weights)
+ acc_mask = torch.where(coarse_accumulation < 0.0001, False, True).reshape(-1)
+
+ # pdf sampling
+ ray_samples_pdf = self.sampler_pdf(ray_bundle, ray_samples_uniform, weights)
+
+ # fine field:
+ field_outputs_fine = self.field.forward(ray_samples_pdf, acc_mask, colors.WHITE.to(weights.device))
+
+ weights_fine = ray_samples_pdf.get_weights(field_outputs_fine[FieldHeadNames.DENSITY])
+
+ accumulation = self.renderer_accumulation(weights_fine)
+ depth = self.renderer_depth(weights_fine, ray_samples_pdf)
+
+ rgb = self.renderer_rgb(
+ rgb=field_outputs_fine[FieldHeadNames.RGB],
+ weights=weights_fine,
+ )
+
+ rgb = torch.where(accumulation < 0, colors.WHITE.to(rgb.device), rgb)
+ accumulation = torch.clamp(accumulation, min=0)
+
+ outputs = {"rgb": rgb, "accumulation": accumulation, "depth": depth}
+ return outputs
+
+ def get_loss_dict(self, outputs, batch, metrics_dict=None) -> Dict[str, torch.Tensor]:
+ # Scaling metrics by coefficients to create the losses.
+ device = outputs["rgb"].device
+ image = batch["image"].to(device)
+
+ rgb_loss = self.rgb_loss(image, outputs["rgb"])
+
+ loss_dict = {"rgb_loss": rgb_loss}
+ loss_dict = misc.scale_dict(loss_dict, self.config.loss_coefficients)
+ return loss_dict
+
+ def get_image_metrics_and_images(
+ self, outputs: Dict[str, torch.Tensor], batch: Dict[str, torch.Tensor]
+ ) -> Tuple[Dict[str, float], Dict[str, torch.Tensor]]:
+ image = batch["image"].to(outputs["rgb"].device)
+ rgb = outputs["rgb"]
+ acc = colormaps.apply_colormap(outputs["accumulation"])
+ depth = colormaps.apply_depth_colormap(
+ outputs["depth"],
+ accumulation=outputs["accumulation"],
+ near_plane=self.config.collider_params["near_plane"],
+ far_plane=self.config.collider_params["far_plane"],
+ )
+
+ combined_rgb = torch.cat([image, rgb], dim=1)
+
+ # Switch images from [H, W, C] to [1, C, H, W] for metrics computations
+ image = torch.moveaxis(image, -1, 0)[None, ...]
+ rgb = torch.moveaxis(rgb, -1, 0)[None, ...]
+
+ psnr = self.psnr(image, rgb)
+ ssim = self.ssim(image, rgb)
+ lpips = self.lpips(image, rgb)
+
+ metrics_dict = {
+ "psnr": float(psnr.item()),
+ "ssim": float(ssim.item()),
+ "lpips": float(lpips.item()),
+ }
+ images_dict = {"img": combined_rgb, "accumulation": acc, "depth": depth}
+ return metrics_dict, images_dict
diff --git a/nerfstudio/models/vanilla_nerf.py b/nerfstudio/models/vanilla_nerf.py
index 827bdfa26..3e731524f 100644
--- a/nerfstudio/models/vanilla_nerf.py
+++ b/nerfstudio/models/vanilla_nerf.py
@@ -18,7 +18,8 @@ Implementation of vanilla nerf.
from __future__ import annotations
-from typing import Dict, List, Tuple
+from dataclasses import dataclass, field
+from typing import Any, Dict, List, Tuple, Type
import torch
from torch.nn import Parameter
@@ -27,8 +28,10 @@ from torchmetrics.functional import structural_similarity_index_measure
from torchmetrics.image.lpip import LearnedPerceptualImagePatchSimilarity
from nerfstudio.cameras.rays import RayBundle
+from nerfstudio.configs.config_utils import to_immutable_dict
from nerfstudio.field_components.encodings import NeRFEncoding
from nerfstudio.field_components.field_heads import FieldHeadNames
+from nerfstudio.field_components.temporal_distortions import TemporalDistortionKind
from nerfstudio.fields.vanilla_nerf_field import NeRFField
from nerfstudio.model_components.losses import MSELoss
from nerfstudio.model_components.ray_samplers import PDFSampler, UniformSampler
@@ -41,6 +44,22 @@ from nerfstudio.models.base_model import Model, ModelConfig
from nerfstudio.utils import colormaps, colors, misc
+@dataclass
+class VanillaModelConfig(ModelConfig):
+ """Vanilla Model Config"""
+
+ _target: Type = field(default_factory=lambda: NeRFModel)
+ num_coarse_samples: int = 64
+ """Number of samples in coarse field evaluation"""
+ num_importance_samples: int = 128
+ """Number of samples in fine field evaluation"""
+
+ enable_temporal_distortion: bool = False
+ """Specifies whether or not to include ray warping based on time."""
+ temporal_distortion_params: Dict[str, Any] = to_immutable_dict({"kind": TemporalDistortionKind.DNERF})
+ """Parameters to instantiate temporal distortion with"""
+
+
class NeRFModel(Model):
"""Vanilla NeRF model
@@ -50,11 +69,12 @@ class NeRFModel(Model):
def __init__(
self,
- config: ModelConfig,
+ config: VanillaModelConfig,
**kwargs,
) -> None:
self.field_coarse = None
self.field_fine = None
+ self.temporal_distortion = None
super().__init__(
config=config,
@@ -73,8 +93,15 @@ class NeRFModel(Model):
in_dim=3, num_frequencies=4, min_freq_exp=0.0, max_freq_exp=4.0, include_input=True
)
- self.field_coarse = NeRFField(position_encoding=position_encoding, direction_encoding=direction_encoding)
- self.field_fine = NeRFField(position_encoding=position_encoding, direction_encoding=direction_encoding)
+ self.field_coarse = NeRFField(
+ position_encoding=position_encoding,
+ direction_encoding=direction_encoding,
+ )
+
+ self.field_fine = NeRFField(
+ position_encoding=position_encoding,
+ direction_encoding=direction_encoding,
+ )
# samplers
self.sampler_uniform = UniformSampler(num_samples=self.config.num_coarse_samples)
@@ -93,11 +120,18 @@ class NeRFModel(Model):
self.ssim = structural_similarity_index_measure
self.lpips = LearnedPerceptualImagePatchSimilarity()
+ if getattr(self.config, "enable_temporal_distortion", False):
+ params = self.config.temporal_distortion_params
+ kind = params.pop("kind")
+ self.temporal_distortion = kind.to_temporal_distortion(params)
+
def get_param_groups(self) -> Dict[str, List[Parameter]]:
param_groups = {}
if self.field_coarse is None or self.field_fine is None:
raise ValueError("populate_fields() must be called before get_param_groups")
param_groups["fields"] = list(self.field_coarse.parameters()) + list(self.field_fine.parameters())
+ if self.temporal_distortion is not None:
+ param_groups["temporal_distortion"] = list(self.temporal_distortion.parameters())
return param_groups
def get_outputs(self, ray_bundle: RayBundle):
@@ -107,6 +141,9 @@ class NeRFModel(Model):
# uniform sampling
ray_samples_uniform = self.sampler_uniform(ray_bundle)
+ if self.temporal_distortion is not None:
+ offsets = self.temporal_distortion(ray_samples_uniform.frustums.get_positions(), ray_samples_uniform.times)
+ ray_samples_uniform.frustums.set_offsets(offsets)
# coarse field:
field_outputs_coarse = self.field_coarse.forward(ray_samples_uniform)
@@ -120,6 +157,9 @@ class NeRFModel(Model):
# pdf sampling
ray_samples_pdf = self.sampler_pdf(ray_bundle, ray_samples_uniform, weights_coarse)
+ if self.temporal_distortion is not None:
+ offsets = self.temporal_distortion(ray_samples_pdf.frustums.get_positions(), ray_samples_pdf.times)
+ ray_samples_pdf.frustums.set_offsets(offsets)
# fine field:
field_outputs_fine = self.field_fine.forward(ray_samples_pdf)
diff --git a/nerfstudio/pipelines/base_pipeline.py b/nerfstudio/pipelines/base_pipeline.py
index 7c64e268f..d5a8b1ec0 100644
--- a/nerfstudio/pipelines/base_pipeline.py
+++ b/nerfstudio/pipelines/base_pipeline.py
@@ -35,9 +35,10 @@ from rich.progress import (
from torch import nn
from torch.nn import Parameter
from torch.nn.parallel import DistributedDataParallel as DDP
+from typing_extensions import Literal
from nerfstudio.configs import base_config as cfg
-from nerfstudio.data.datamanagers import (
+from nerfstudio.data.datamanagers.base_datamanager import (
DataManager,
VanillaDataManager,
VanillaDataManagerConfig,
@@ -77,7 +78,10 @@ class Pipeline(nn.Module):
Args:
config: configuration to instantiate pipeline
device: location to place model and data
- test_mode: if True, loads test datset. if False, loads train/eval datasets
+ test_mode:
+ 'train': loads train/eval datasets into memory
+ 'test': loads train/test datset into memory
+ 'inference': does not load any dataset into memory
world_size: total number of machines available
local_rank: rank of current machine
@@ -191,7 +195,10 @@ class VanillaPipeline(Pipeline):
config: configuration to instantiate pipeline
device: location to place model and data
- test_mode: if True, loads test datset. if False, loads train/eval datasets
+ test_mode:
+ 'val': loads train/val datasets into memory
+ 'test': loads train/test datset into memory
+ 'inference': does not load any dataset into memory
world_size: total number of machines available
local_rank: rank of current machine
@@ -204,12 +211,13 @@ class VanillaPipeline(Pipeline):
self,
config: VanillaPipelineConfig,
device: str,
- test_mode: bool = False,
+ test_mode: Literal["test", "val", "inference"] = "val",
world_size: int = 1,
local_rank: int = 0,
):
super().__init__()
self.config = config
+ self.test_mode = test_mode
self.datamanager: VanillaDataManager = config.datamanager.setup(
device=device, test_mode=test_mode, world_size=world_size, local_rank=local_rank
)
@@ -220,8 +228,7 @@ class VanillaPipeline(Pipeline):
self._model = config.model.setup(
scene_box=self.datamanager.train_dataset.dataparser_outputs.scene_box,
num_train_data=len(self.datamanager.train_dataset),
- semantics=self.datamanager.train_dataset.dataparser_outputs.semantics,
- device=device,
+ metadata=self.datamanager.train_dataset.dataparser_outputs.metadata,
)
self.model.to(device)
@@ -352,6 +359,12 @@ class VanillaPipeline(Pipeline):
loaded_state: pre-trained model state dict
"""
state = {key.replace("module.", ""): value for key, value in loaded_state.items()}
+ if self.test_mode == "inference":
+ state.pop("datamanager.train_camera_optimizer.pose_adjustment", None)
+ state.pop("datamanager.train_ray_generator.image_coords", None)
+ state.pop("datamanager.train_ray_generator.pose_optimizer.pose_adjustment", None)
+ state.pop("datamanager.eval_ray_generator.image_coords", None)
+ state.pop("datamanager.eval_ray_generator.pose_optimizer.pose_adjustment", None)
self.load_state_dict(state) # type: ignore
def get_training_callbacks(
diff --git a/nerfstudio/pipelines/dynamic_batch.py b/nerfstudio/pipelines/dynamic_batch.py
index b2e18ef62..788f68e82 100644
--- a/nerfstudio/pipelines/dynamic_batch.py
+++ b/nerfstudio/pipelines/dynamic_batch.py
@@ -20,8 +20,9 @@ from dataclasses import dataclass, field
from typing import Type
import torch
+from typing_extensions import Literal
-from nerfstudio.data.datamanagers import VanillaDataManager
+from nerfstudio.data.datamanagers.base_datamanager import VanillaDataManager
from nerfstudio.pipelines.base_pipeline import VanillaPipeline, VanillaPipelineConfig
@@ -49,7 +50,7 @@ class DynamicBatchPipeline(VanillaPipeline):
self,
config: DynamicBatchPipelineConfig,
device: str,
- test_mode: bool = False,
+ test_mode: Literal["test", "val", "inference"] = "val",
world_size: int = 1,
local_rank: int = 0,
):
diff --git a/nerfstudio/utils/eval_utils.py b/nerfstudio/utils/eval_utils.py
index 2f1ee4673..7401a916c 100644
--- a/nerfstudio/utils/eval_utils.py
+++ b/nerfstudio/utils/eval_utils.py
@@ -25,6 +25,7 @@ from typing import Optional, Tuple
import torch
import yaml
from rich.console import Console
+from typing_extensions import Literal
from nerfstudio.configs import base_config as cfg
from nerfstudio.pipelines.base_pipeline import Pipeline
@@ -63,11 +64,21 @@ def eval_load_checkpoint(config: cfg.TrainerConfig, pipeline: Pipeline) -> Path:
return load_path
-def eval_setup(config_path: Path, eval_num_rays_per_chunk: Optional[int] = None) -> Tuple[cfg.Config, Pipeline, Path]:
+def eval_setup(
+ config_path: Path,
+ eval_num_rays_per_chunk: Optional[int] = None,
+ test_mode: Literal["test", "val", "inference"] = "test",
+) -> Tuple[cfg.Config, Pipeline, Path]:
"""Shared setup for loading a saved pipeline for evaluation.
Args:
config_path: Path to config YAML file.
+ eval_num_rays_per_chunk: Number of rays per forward pass
+ test_mode:
+ 'val': loads train/val datasets into memory
+ 'test': loads train/test datset into memory
+ 'inference': does not load any dataset into memory
+
Returns:
Loaded config, pipeline module, and corresponding checkpoint.
@@ -86,7 +97,7 @@ def eval_setup(config_path: Path, eval_num_rays_per_chunk: Optional[int] = None)
# setup pipeline (which includes the DataManager)
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
- pipeline = config.pipeline.setup(device=device, test_mode=True)
+ pipeline = config.pipeline.setup(device=device, test_mode=test_mode)
assert isinstance(pipeline, Pipeline)
pipeline.eval()
diff --git a/nerfstudio/viewer/app/package.json b/nerfstudio/viewer/app/package.json
index b0768523b..6e2f1269f 100644
--- a/nerfstudio/viewer/app/package.json
+++ b/nerfstudio/viewer/app/package.json
@@ -1,7 +1,7 @@
{
"name": "viewer",
"homepage": ".",
- "version": "22-10-13-0",
+ "version": "22-11-10-0",
"private": true,
"dependencies": {
"@emotion/react": "^11.10.4",
diff --git a/nerfstudio/viewer/app/src/SceneNode.js b/nerfstudio/viewer/app/src/SceneNode.js
index a35d23065..6cd10721c 100644
--- a/nerfstudio/viewer/app/src/SceneNode.js
+++ b/nerfstudio/viewer/app/src/SceneNode.js
@@ -27,15 +27,20 @@ function dispose(object) {
}
export default class SceneNode {
- constructor(object) {
+ constructor(object, scene_state) {
this.metadata = {}; // relevant metadata for the object
this.object = object; // three.js objects
this.children = {};
+ this.scene_state = scene_state;
for (const c of this.object.children) {
this.add_child(c);
}
}
+ get_scene_state() {
+ return this.scene_state;
+ }
+
add_child(object) {
const node = new SceneNode(object);
this.children[object.name] = node;
diff --git a/nerfstudio/viewer/app/src/index.jsx b/nerfstudio/viewer/app/src/index.jsx
index 855be0964..966e50e43 100644
--- a/nerfstudio/viewer/app/src/index.jsx
+++ b/nerfstudio/viewer/app/src/index.jsx
@@ -1,6 +1,6 @@
import './index.scss';
import React from 'react';
-import ReactDOM from 'react-dom/client';
+import ReactDOM from 'react-dom';
import { Provider } from 'react-redux';
import App from './App';
import WebSocketProvider from './modules/WebSocket/WebSocket';
diff --git a/nerfstudio/viewer/app/src/index.scss b/nerfstudio/viewer/app/src/index.scss
index c39522b58..194c5ac2e 100644
--- a/nerfstudio/viewer/app/src/index.scss
+++ b/nerfstudio/viewer/app/src/index.scss
@@ -96,6 +96,29 @@ $sidebar-color: $accent-color3 !default;
$sidebar-width: 100% !default;
@import '~react-pro-sidebar/dist/scss/styles.scss';
+// Scrollbar
+
+/* width */
+::-webkit-scrollbar {
+ width: 8px;
+ height: 6px;
+}
+
+/* Track */
+::-webkit-scrollbar-track {
+ background: #454651;
+}
+
+/* Handle */
+::-webkit-scrollbar-thumb {
+ background: $accent-color3;
+}
+
+/* Handle on hover */
+::-webkit-scrollbar-thumb:hover {
+ background: $highlight-color2;
+}
+
// ------------------------------------
// Status Panel styling
.StatusPanel {
@@ -151,6 +174,9 @@ $sidebar-width: 100% !default;
border: 2px solid #000;
// box-shadow: 24px 24px;
padding: 32px;
+ overflow-y: auto;
+ height: auto;
+ max-height: 90%;
}
.LandingModal-box .WebSocketUrlField {
@@ -161,6 +187,58 @@ $sidebar-width: 100% !default;
margin: 3px;
}
+// ------------------------------------
+// Viewport Controls Modal styling
+
+.ViewportConstrolsModal-box {
+ position: absolute;
+ top: 50%;
+ left: 50%;
+ transform: translate(-50%, -50%);
+ width: 800px; // 400
+ background-color: $base-color2;
+ border: 2px solid #000;
+ // box-shadow: 24px 24px;
+ padding: 32px;
+ overflow-y: auto;
+ height: auto;
+}
+
+// ------------------------------------
+// Render Modal styling
+
+.RenderModal-box {
+ position: absolute;
+ top: 50%;
+ left: 50%;
+ transform: translate(-50%, -50%);
+ width: 600px; // 400
+ background-color: $base-color2;
+ border: 2px solid #000;
+ // box-shadow: 24px 24px;
+ padding: 32px;
+}
+
+.RenderModal-code {
+ padding: 10px;
+ background-color: $base-color3;
+ overflow-x: scroll;
+ font-family: monospace;
+ white-space: pre;
+ margin-top: 16px;
+}
+
+.RenderModal-inline-code {
+ font-size: 0.9rem;
+ color: $accent-color3;
+}
+
+.RenderModal-box .RenderModal-button {
+ width: 50%;
+ padding: 5px;
+ margin-top: 20px;
+}
+
// ------------------------------------
// Camera Pane
@@ -173,8 +251,14 @@ $sidebar-width: 100% !default;
margin-top: 8px;
}
+.CameraPanel-render-button {
+ display: inline-block;
+ width: 70%;
+ margin: 4px;
+ margin-top: 8px;
+}
+
.CameraPanel-slider-container {
- margin-top: 40px;
margin-left: auto;
margin-right: auto;
width: 70%;
@@ -194,6 +278,7 @@ $sidebar-width: 100% !default;
}
.CameraList-row {
+ background: $base-color1;
padding: 4px;
border: solid 1px $highlight-color1;
text-align: left;
@@ -211,6 +296,13 @@ $sidebar-width: 100% !default;
width: 100px;
}
+.CameraList-row-animation-properties > div {
+ display: inline-block;
+ text-align: center;
+ margin: 10px;
+ width: 100px;
+}
+
// ------------------------------------
// Viewer Window
@@ -277,3 +369,27 @@ $viewer_button_size: 50px;
.ViewerWindow-iconbutton {
margin-top: 5px;
}
+
+// ------------------------------------
+// Export panel styling
+
+.ExportModal-code {
+ padding: 10px;
+ background-color: $base-color3;
+ overflow-x: scroll;
+ font-family: monospace;
+ white-space: pre;
+ margin-top: 16px;
+ font-size: 0.9em;
+}
+
+.ExportModal-text {
+ text-align: left;
+ margin-top: 20px;
+ font-size: 0.9em;
+}
+
+.ExportModal-button {
+ // margin: 15px;
+ padding: 20px;
+}
diff --git a/nerfstudio/viewer/app/src/modules/Banner/Banner.jsx b/nerfstudio/viewer/app/src/modules/Banner/Banner.jsx
index 0ab082edd..baedf714d 100644
--- a/nerfstudio/viewer/app/src/modules/Banner/Banner.jsx
+++ b/nerfstudio/viewer/app/src/modules/Banner/Banner.jsx
@@ -5,6 +5,7 @@ import Button from '@mui/material/Button';
import GitHubIcon from '@mui/icons-material/GitHub';
import DescriptionRoundedIcon from '@mui/icons-material/DescriptionRounded';
import LandingModal from '../LandingModal';
+import ViewportControlsModal from '../ViewportControlsModal';
function getParam(param_name) {
// https://stackoverflow.com/questions/831030/how-to-get-get-request-parameters-in-javascript
@@ -56,6 +57,7 @@ export default function Banner() {
>
Documentation
+
diff --git a/nerfstudio/viewer/app/src/modules/RenderModal/RenderModal.jsx b/nerfstudio/viewer/app/src/modules/RenderModal/RenderModal.jsx
new file mode 100644
index 000000000..6305d4043
--- /dev/null
+++ b/nerfstudio/viewer/app/src/modules/RenderModal/RenderModal.jsx
@@ -0,0 +1,93 @@
+/* eslint-disable react/jsx-props-no-spreading */
+import * as React from 'react';
+
+import { Box, Button, Modal, TextField, Typography } from '@mui/material';
+import { useSelector } from 'react-redux';
+import ContentCopyRoundedIcon from '@mui/icons-material/ContentCopyRounded';
+
+interface RenderModalProps {
+ open: object;
+ setOpen: object;
+}
+
+export default function RenderModal(props: RenderModalProps) {
+ const open = props.open;
+ const setOpen = props.setOpen;
+
+ // redux store state
+ const config_base_dir = useSelector(
+ (state) => state.renderingState.config_base_dir,
+ );
+
+ // react state
+ const [filename, setFilename] = React.useState('render_output');
+
+ const handleClose = () => setOpen(false);
+
+ // Copy the text inside the text field
+ const config_filename = `${config_base_dir}/config.yml`;
+ const camera_path_filename = `${config_base_dir}/camera_path.json`;
+ const cmd = `ns-render --load-config ${config_filename} --traj filename --camera-path-filename ${camera_path_filename} --output-path renders/${filename}.mp4`;
+
+ const text_intro = `To render a full resolution video, run the following command in a terminal.`;
+
+ const handleCopy = () => {
+ navigator.clipboard.writeText(cmd);
+ };
+
+ return (
+
-
Camera Keyboard Controls
-
- WASD - horizontal camera translation, QE - vertical camera
- translation
-
- Arrow Keys - camera rotation
-
- Spacebar - reset camera orbit point and view direction to
- origin
-
-
+
+ );
+}
diff --git a/nerfstudio/viewer/app/src/modules/RenderModal/index.jsx b/nerfstudio/viewer/app/src/modules/RenderModal/index.jsx
new file mode 100644
index 000000000..347dbeb7a
--- /dev/null
+++ b/nerfstudio/viewer/app/src/modules/RenderModal/index.jsx
@@ -0,0 +1,3 @@
+import RenderModal from './RenderModal';
+
+export default RenderModal;
diff --git a/nerfstudio/viewer/app/src/modules/Scene/Scene.jsx b/nerfstudio/viewer/app/src/modules/Scene/Scene.jsx
index dd0d36fc6..f0d0c2523 100644
--- a/nerfstudio/viewer/app/src/modules/Scene/Scene.jsx
+++ b/nerfstudio/viewer/app/src/modules/Scene/Scene.jsx
@@ -22,16 +22,36 @@ const CAMERAS_NAME = 'Training Cameras';
export function get_scene_tree() {
const scene = new THREE.Scene();
- const sceneTree = new SceneNode(scene);
+
+ const scene_state = {
+ value: new Map(),
+ callbacks: [],
+ addCallback(callback, key) {
+ this.callbacks.push([callback, key]);
+ },
+ setValue(key, value) {
+ this.value.set(key, value);
+ this.callbacks.forEach((cbk) => {
+ const i = cbk[1];
+ const callback = cbk[0];
+ return callback(this.value.get(i));
+ });
+ },
+ };
+
+ const sceneTree = new SceneNode(scene, scene_state);
const dispatch = useDispatch();
const BANNER_HEIGHT = 50;
// Main camera
const main_camera = new THREE.PerspectiveCamera(75, 1, 0.1, 1000);
- main_camera.position.x = 0.7;
- main_camera.position.y = -0.7;
- main_camera.position.z = 0.3;
+ const start_position = new THREE.Vector3(0.7, -0.7, 0.3);
+ main_camera.position.set(
+ start_position.x,
+ start_position.y,
+ start_position.z,
+ );
main_camera.up = new THREE.Vector3(0, 0, 1);
sceneTree.set_object_from_path(['Cameras', 'Main Camera'], main_camera);
@@ -68,28 +88,47 @@ export function get_scene_tree() {
const camera_controls = new CameraControls(main_camera, renderer.domElement);
camera_controls.azimuthRotateSpeed = 0.3;
camera_controls.polarRotateSpeed = 0.3;
- camera_controls.minDistance = 0.3;
- camera_controls.maxDistance = 20;
-
camera_controls.dollySpeed = 0.1;
+ camera_controls.infinityDolly = true;
camera_controls.saveState();
const keyMap = [];
const moveSpeed = 0.02;
+ const rotSpeed = 0.015;
+ const EPS = 0.01;
- function moveCamera() {
- if (keyMap.ArrowLeft === true) {
- camera_controls.rotate(-0.02, 0, true);
- }
- if (keyMap.ArrowRight === true) {
- camera_controls.rotate(0.02, 0, true);
- }
- if (keyMap.ArrowUp === true) {
- camera_controls.rotate(0, -0.01, true);
- }
- if (keyMap.ArrowDown === true) {
- camera_controls.rotate(0, 0.01, true);
+ function rotate() {
+ if (
+ keyMap.ArrowLeft ||
+ keyMap.ArrowRight ||
+ keyMap.ArrowUp ||
+ keyMap.ArrowDown
+ ) {
+ const curTar = camera_controls.getTarget();
+ const curPos = camera_controls.getPosition();
+ const diff = curTar.sub(curPos).clampLength(0, EPS);
+ camera_controls.setTarget(
+ curPos.x + diff.x,
+ curPos.y + diff.y,
+ curPos.z + diff.z,
+ );
+
+ if (keyMap.ArrowLeft === true) {
+ camera_controls.rotate(rotSpeed, 0, true);
+ }
+ if (keyMap.ArrowRight === true) {
+ camera_controls.rotate(-rotSpeed, 0, true);
+ }
+ if (keyMap.ArrowUp === true) {
+ camera_controls.rotate(0, rotSpeed / 1.5, true);
+ }
+ if (keyMap.ArrowDown === true) {
+ camera_controls.rotate(0, -rotSpeed / 1.5, true);
+ }
}
+ }
+
+ function translate() {
if (keyMap.KeyD === true) {
camera_controls.truck(moveSpeed, 0, true);
}
@@ -97,10 +136,21 @@ export function get_scene_tree() {
camera_controls.truck(-moveSpeed, 0, true);
}
if (keyMap.KeyW === true) {
- camera_controls.forward(moveSpeed, true);
+ const curPos = camera_controls.getPosition();
+ const newTar = camera_controls.getTarget();
+ const newDiff = newTar
+ .sub(curPos)
+ .normalize()
+ .multiplyScalar(curPos.length());
+ camera_controls.setTarget(
+ curPos.x + newDiff.x,
+ curPos.y + newDiff.y,
+ curPos.z + newDiff.z,
+ );
+ camera_controls.dolly(moveSpeed, true);
}
if (keyMap.KeyS === true) {
- camera_controls.forward(-moveSpeed, true);
+ camera_controls.dolly(-moveSpeed, true);
}
if (keyMap.KeyQ === true) {
camera_controls.truck(0, moveSpeed, true);
@@ -110,6 +160,14 @@ export function get_scene_tree() {
}
}
+ function moveCamera() {
+ if (!scene_state.value.get('mouse_in_scene')) {
+ return;
+ }
+ translate();
+ rotate();
+ }
+
function onKeyUp(event) {
const keyCode = event.code;
keyMap[keyCode] = false;
@@ -240,19 +298,45 @@ export function get_scene_tree() {
let drag = false;
const onMouseDown = () => {
drag = false;
+ const curPos = camera_controls.getPosition();
+ const newTar = camera_controls.getTarget();
+ const newDiff = newTar
+ .sub(curPos)
+ .normalize()
+ .multiplyScalar(curPos.length());
+ camera_controls.setTarget(
+ curPos.x + newDiff.x,
+ curPos.y + newDiff.y,
+ curPos.z + newDiff.z,
+ );
};
const onMouseMove = (e) => {
drag = true;
- const cameras = Object.values(
- sceneTree.find_no_create([CAMERAS_NAME]).children,
- ).map((obj) => obj.object.children[0].children[1]);
-
sceneTree.metadata.renderer.getSize(size);
mouseVector.x = 2 * (e.clientX / size.x) - 1;
mouseVector.y = 1 - 2 * ((e.clientY - BANNER_HEIGHT) / size.y);
+ const mouse_in_scene = !(
+ mouseVector.x > 1 ||
+ mouseVector.x < -1 ||
+ mouseVector.y > 1 ||
+ mouseVector.y < -1
+ );
+
+ scene_state.setValue('mouse_x', mouseVector.x);
+ scene_state.setValue('mouse_y', mouseVector.y);
+ scene_state.setValue('mouse_in_scene', mouse_in_scene);
+
+ const camerasParent = sceneTree.find_no_create([CAMERAS_NAME]);
+ if (camerasParent === null) {
+ return;
+ }
+ const cameras = Object.values(camerasParent.children).map(
+ (obj) => obj.object.children[0].children[1],
+ );
+
if (
mouseVector.x > 1 ||
mouseVector.x < -1 ||
@@ -283,7 +367,7 @@ export function get_scene_tree() {
};
const onMouseUp = () => {
- if (drag === true) {
+ if (drag === true || !scene_state.value.get('mouse_in_scene')) {
return;
}
if (selectedCam !== null) {
diff --git a/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/CameraPanel.jsx b/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/CameraPanel.jsx
index 9f1cf207d..dbabf0f3d 100644
--- a/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/CameraPanel.jsx
+++ b/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/CameraPanel.jsx
@@ -2,56 +2,222 @@ import * as React from 'react';
import * as THREE from 'three';
import {
+ ArrowBackIosNew,
+ ArrowForwardIos,
AllInclusiveOutlined,
ChangeHistory,
+ ClearAll,
+ Delete,
+ ExpandMore,
+ FirstPage,
GestureOutlined,
- LinearScaleOutlined,
+ KeyboardArrowUp,
+ KeyboardArrowDown,
+ LastPage,
+ Pause,
+ PlayArrow,
RadioButtonUnchecked,
Replay,
- Timeline,
+ Visibility,
+ Edit,
+ Animation,
} from '@mui/icons-material';
-import { Button, Slider } from '@mui/material';
+import {
+ Accordion,
+ AccordionDetails,
+ AccordionSummary,
+ Button,
+ InputAdornment,
+ Slider,
+} from '@mui/material';
import { MeshLine, MeshLineMaterial } from 'meshline';
import { useContext, useEffect } from 'react';
import { useDispatch, useSelector } from 'react-redux';
-import AddAPhotoIcon from '@mui/icons-material/AddAPhoto';
-import ArrowBackIosNewIcon from '@mui/icons-material/ArrowBackIosNew';
-import ArrowForwardIosIcon from '@mui/icons-material/ArrowForwardIos';
import { CSS2DObject } from 'three/examples/jsm/renderers/CSS2DRenderer';
-import ContentPasteGoIcon from '@mui/icons-material/ContentPasteGo';
-import DeleteIcon from '@mui/icons-material/Delete';
-import FirstPageIcon from '@mui/icons-material/FirstPage';
+import AddAPhotoIcon from '@mui/icons-material/AddAPhoto';
import FileDownloadOutlinedIcon from '@mui/icons-material/FileDownloadOutlined';
import FileUploadOutlinedIcon from '@mui/icons-material/FileUploadOutlined';
-import IconButton from '@mui/material/IconButton';
-import LastPageIcon from '@mui/icons-material/LastPage';
-import PauseIcon from '@mui/icons-material/Pause';
-import PlayArrowIcon from '@mui/icons-material/PlayArrow';
import { Stack } from '@mui/system';
import TextField from '@mui/material/TextField';
import Tooltip from '@mui/material/Tooltip';
-import VisibilityIcon from '@mui/icons-material/Visibility';
+import VideoCameraBackIcon from '@mui/icons-material/VideoCameraBack';
import { CameraHelper } from './CameraHelper';
import { get_curve_object_from_cameras, get_transform_matrix } from './curve';
import { WebSocketContext } from '../../WebSocket/WebSocket';
+import RenderModal from '../../RenderModal';
const msgpack = require('msgpack-lite');
+const FOV_LABELS = {
+ FOV: '°',
+ MM: 'mm',
+};
+
function set_camera_position(camera, matrix) {
const mat = new THREE.Matrix4();
mat.fromArray(matrix.elements);
mat.decompose(camera.position, camera.quaternion, camera.scale);
}
+function FovSelector(props) {
+ const fovLabel = props.fovLabel;
+ const setFovLabel = props.setFovLabel;
+ const camera = props.camera;
+ const dispatch = props.dispatch;
+ const changeMain = props.changeMain;
+ const disabled = props.disabled;
+ const applyAll = props.applyAll;
+ const setAllCameraFOV = props.setAllCameraFOV;
+ const isGlobal = props.isGlobal;
+ const globalFov = props.globalFov;
+ const setGlobalFov = props.setGlobalFov;
+
+ const getFovLabel = () => {
+ if (!isGlobal) {
+ const label = Math.round(
+ fovLabel === FOV_LABELS.FOV
+ ? camera.getEffectiveFOV()
+ : camera.getFocalLength() * camera.aspect,
+ );
+ return label;
+ }
+ const old_fov = camera.fov;
+ camera.fov = globalFov;
+ const new_focal_len = camera.getFocalLength();
+ camera.fov = old_fov;
+ const label = Math.round(
+ fovLabel === FOV_LABELS.FOV ? globalFov : new_focal_len * camera.aspect,
+ );
+ return label;
+ };
+
+ const [UIFieldOfView, setUIFieldOfView] = React.useState(
+ isGlobal ? globalFov : getFovLabel(),
+ );
+
+ useEffect(
+ () => setUIFieldOfView(getFovLabel()),
+ [camera, fovLabel, globalFov],
+ );
+
+ const setFOV = (val) => {
+ if (!isGlobal) {
+ if (fovLabel === FOV_LABELS.FOV) {
+ camera.fov = val;
+ } else {
+ camera.setFocalLength(val / camera.aspect);
+ }
+ } else if (fovLabel === FOV_LABELS.FOV) {
+ setGlobalFov(val);
+ } else {
+ const old_fov = camera.fov;
+ camera.setFocalLength(val / camera.aspect);
+ const new_fov = camera.getEffectiveFOV();
+ camera.fov = old_fov;
+ setGlobalFov(new_fov);
+ }
+
+ if (applyAll) {
+ setAllCameraFOV(val);
+ }
+
+ if (changeMain) {
+ dispatch({
+ type: 'write',
+ path: 'renderingState/field_of_view',
+ data: camera.getEffectiveFOV(),
+ });
+ }
+ };
+
+ const toggleFovLabel = () => {
+ if (fovLabel === FOV_LABELS.FOV) {
+ setFovLabel(FOV_LABELS.MM);
+ } else {
+ setFovLabel(FOV_LABELS.FOV);
+ }
+ };
+
+ return (
+
+
+ Rendering
+
+ The video will be saved to{' '}
+
+                  ./renders/{filename}.mp4
+
+ .
+ {cmd}
+
+ }
+ onClick={handleCopy}
+ >
+ Copy Command
+
+
+
-
-
+
+
- {cameraList};
@@ -188,16 +444,33 @@ export default function CameraPanel(props) {
(state) => state.renderingState.config_base_dir,
);
const websocket = useContext(WebSocketContext).socket;
+ const DEFAULT_FOV = 50;
// react state
const [cameras, setCameras] = React.useState([]);
+ // Mapping of camera id to each camera's properties
+ const [cameraProperties, setCameraProperties] = React.useState(new Map());
const [slider_value, set_slider_value] = React.useState(0);
const [smoothness_value, set_smoothness_value] = React.useState(0.5);
const [is_playing, setIsPlaying] = React.useState(false);
const [is_cycle, setIsCycle] = React.useState(false);
- const [is_linear, setIsLinear] = React.useState(false);
const [seconds, setSeconds] = React.useState(4);
const [fps, setFps] = React.useState(24);
+ const [render_modal_open, setRenderModalOpen] = React.useState(false);
+ const [animate, setAnimate] = React.useState(new Set());
+ const [globalFov, setGlobalFov] = React.useState(DEFAULT_FOV);
+
+ const scene_state = sceneTree.get_scene_state();
+
+ // Template for sharing state between Vanilla JS Three.js and React components
+ // eslint-disable-next-line no-unused-vars
+ const [mouseInScene, setMouseInScene] = React.useState(false);
+ React.useEffect(() => {
+ scene_state.addCallback(
+ (value) => setMouseInScene(value),
+ 'mouse_in_scene',
+ );
+ }, []);
const dispatch = useDispatch();
const render_height = useSelector(
@@ -207,10 +480,6 @@ export default function CameraPanel(props) {
(state) => state.renderingState.render_width,
);
- const field_of_view = useSelector(
- (state) => state.renderingState.field_of_view,
- );
-
const setRenderHeight = (value) => {
dispatch({
type: 'write',
@@ -229,13 +498,13 @@ export default function CameraPanel(props) {
// ui state
const [ui_render_height, setUIRenderHeight] = React.useState(render_height);
const [ui_render_width, setUIRenderWidth] = React.useState(render_width);
- const [ui_field_of_view, setUIFieldOfView] = React.useState(field_of_view);
const [ui_seconds, setUISeconds] = React.useState(seconds);
const [ui_fps, setUIfps] = React.useState(fps);
+ const [fovLabel, setFovLabel] = React.useState(FOV_LABELS.FOV);
// nonlinear render option
const slider_min = 0;
- const slider_max = Math.max(0, cameras.length - 1);
+ const slider_max = 1;
// animation constants
const total_num_steps = seconds * fps;
@@ -245,6 +514,7 @@ export default function CameraPanel(props) {
// set slider and render camera back to 0
if (new_camera_list.length >= 1) {
set_camera_position(camera_render, new_camera_list[0].matrix);
+ camera_render.fov = new_camera_list[0].fov;
set_slider_value(slider_min);
}
};
@@ -252,11 +522,66 @@ export default function CameraPanel(props) {
const add_camera = () => {
const camera_main_copy = camera_main.clone();
camera_main_copy.aspect = 1.0;
+ camera_main_copy.fov = globalFov;
+ const new_camera_properties = new Map();
+ camera_main_copy.properties = new_camera_properties;
+ new_camera_properties.set('FOV', globalFov);
+ new_camera_properties.set('NAME', `Camera ${cameras.length}`);
+ // TIME VALUES ARE 0-1
+ if (cameras.length === 0) {
+ new_camera_properties.set('TIME', 0.0);
+ } else {
+ new_camera_properties.set('TIME', 1.0);
+ }
+
+ const ratio = (cameras.length - 1) / cameras.length;
+
+ const new_properties = new Map(cameraProperties);
+ new_properties.forEach((properties) => {
+ properties.set('TIME', properties.get('TIME') * ratio);
+ });
+ new_properties.set(camera_main_copy.uuid, new_camera_properties);
+ setCameraProperties(new_properties);
+
const new_camera_list = cameras.concat(camera_main_copy);
setCameras(new_camera_list);
reset_slider_render_on_add(new_camera_list);
};
+ const setCameraProperty = (property, value, index) => {
+ const activeCamera = cameras[index];
+ const activeProperties = new Map(activeCamera.properties);
+ activeProperties.set(property, value);
+ const newProperties = new Map(cameraProperties);
+ newProperties.set(activeCamera.uuid, activeProperties);
+ activeCamera.properties = activeProperties;
+ setCameraProperties(newProperties);
+ };
+
+ const swapCameras = (index, new_index) => {
+ if (
+ Math.min(index, new_index) < 0 ||
+ Math.max(index, new_index) >= cameras.length
+ )
+ return;
+
+ const swapCameraTime = cameras[index].properties.get('TIME');
+ setCameraProperty('TIME', cameras[new_index].properties.get('TIME'), index);
+ setCameraProperty('TIME', swapCameraTime, new_index);
+
+ const new_cameras = [
+ ...cameras.slice(0, index),
+ ...cameras.slice(index + 1),
+ ];
+ setCameras([
+ ...new_cameras.slice(0, new_index),
+ cameras[index],
+ ...new_cameras.slice(new_index),
+ ]);
+
+ // reset_slider_render_on_change();
+ };
+
// force a rerender if the cameras are dragged around
let update_cameras_interval = null;
// eslint-disable-next-line no-unused-vars
@@ -298,8 +623,12 @@ export default function CameraPanel(props) {
const labelDiv = document.createElement('div');
labelDiv.className = 'label';
- labelDiv.textContent = i;
+ labelDiv.textContent = camera.properties.get('NAME');
labelDiv.style.color = 'black';
+ labelDiv.style.backgroundColor = "rgba(255, 255, 255, 0.61)";
+ labelDiv.style.backdropFilter = 'blur(5px)';
+ labelDiv.style.padding = '6px';
+ labelDiv.style.borderRadius = '6px';
labelDiv.style.visibility = 'visible';
const camera_label = new CSS2DObject(labelDiv);
camera_label.position.set(0, -0.1, -0.1);
@@ -317,7 +646,7 @@ export default function CameraPanel(props) {
camera_helper,
);
}
- }, [cameras, render_width, render_height]);
+ }, [cameras, cameraProperties, render_width, render_height]);
// update the camera curve
const curve_object = get_curve_object_from_cameras(
@@ -326,6 +655,37 @@ export default function CameraPanel(props) {
smoothness_value,
);
+ const getKeyframePoint = (progress: Number) => {
+ const times = [];
+ const ratio = (cameras.length - 1) / cameras.length;
+ cameras.forEach((camera) => {
+ const time = camera.properties.get('TIME');
+ times.push(is_cycle ? time * ratio : time);
+ });
+
+ if (is_cycle) {
+ times.push(1.0);
+ }
+
+ let new_point = 0.0;
+ if (progress <= times[0]) {
+ new_point = 0.0;
+ } else if (progress >= times[times.length - 1]) {
+ new_point = 1.0;
+ } else {
+ let i = 0;
+ while (
+ i < times.length - 1 &&
+ !(progress >= times[i] && progress < times[i + 1])
+ ) {
+ i += 1;
+ }
+ const percentage = (progress - times[i]) / (times[i + 1] - times[i]);
+ new_point = (i + percentage) / (times.length - 1);
+ }
+ return new_point;
+ };
+
if (cameras.length > 1) {
const num_points = fps * seconds;
const points = curve_object.curve_positions.getPoints(num_points);
@@ -337,49 +697,71 @@ export default function CameraPanel(props) {
sceneTree.set_object_from_path(['Camera Path', 'Curve'], spline_mesh);
// set the camera
- const point = Math.min(slider_value / (cameras.length - 1.0), 1);
+
+ const point = getKeyframePoint(slider_value);
let position = null;
let lookat = null;
let up = null;
- if (!is_linear) {
- position = curve_object.curve_positions.getPoint(point);
- lookat = curve_object.curve_lookats.getPoint(point);
- up = curve_object.curve_ups.getPoint(point);
- } else {
- position = curve_object.curve_positions.getPointAt(point);
- lookat = curve_object.curve_lookats.getPointAt(point);
- up = curve_object.curve_ups.getPointAt(point);
- }
+ let fov = null;
+ position = curve_object.curve_positions.getPoint(point);
+ lookat = curve_object.curve_lookats.getPoint(point);
+ up = curve_object.curve_ups.getPoint(point);
+ fov = curve_object.curve_fovs.getPoint(point).z;
+
const mat = get_transform_matrix(position, lookat, up);
set_camera_position(camera_render, mat);
+ camera_render.fov = fov;
} else {
sceneTree.delete(['Camera Path', 'Curve']);
}
const marks = [];
- for (let i = 0; i < cameras.length; i += 1) {
- marks.push({ value: i, label: i.toString() });
+ for (let i = 0; i <= 1; i += 0.25) {
+ marks.push({ value: i, label: `${(seconds * i).toFixed(1).toString()}s` });
}
+ const values = [];
+ cameras.forEach((camera) => {
+ const time = camera.properties.get('TIME');
+ const ratio = (cameras.length - 1) / cameras.length;
+ values.push(is_cycle ? time * ratio : time);
+ });
+
+ if (is_cycle && cameras.length !== 0) {
+ values.push(1.0);
+ }
+
+ const handleKeyframeSlider = (
+ event: Event,
+ newValue: number | number[],
+ activeThumb: number,
+ ) => {
+ if (activeThumb === cameras.length) return;
+ const ratio = (cameras.length - 1) / cameras.length;
+ const val = newValue[activeThumb];
+ setCameraProperty(
+ 'TIME',
+ is_cycle ? Math.min(val / ratio, 1.0) : val,
+ activeThumb,
+ );
+ };
+
// when the slider changes, update the main camera position
useEffect(() => {
if (cameras.length > 1) {
- const point = Math.min(slider_value / (cameras.length - 1.0), 1);
+ const point = getKeyframePoint(slider_value);
let position = null;
let lookat = null;
let up = null;
- if (!is_linear) {
- // interpolate to get the points
- position = curve_object.curve_positions.getPoint(point);
- lookat = curve_object.curve_lookats.getPoint(point);
- up = curve_object.curve_ups.getPoint(point);
- } else {
- position = curve_object.curve_positions.getPointAt(point);
- lookat = curve_object.curve_lookats.getPointAt(point);
- up = curve_object.curve_ups.getPointAt(point);
- }
+ let fov = null;
+ position = curve_object.curve_positions.getPoint(point);
+ lookat = curve_object.curve_lookats.getPoint(point);
+ up = curve_object.curve_ups.getPoint(point);
+ fov = curve_object.curve_fovs.getPoint(point).z;
const mat = get_transform_matrix(position, lookat, up);
set_camera_position(camera_render, mat);
+ camera_render.fov = fov;
+ setGlobalFov(fov);
}
}, [slider_value, render_height, render_width]);
@@ -405,23 +787,21 @@ export default function CameraPanel(props) {
const get_camera_path = () => {
// NOTE: currently assuming these are ints
const num_points = fps * seconds;
-
- const positions = curve_object.curve_positions.getPoints(num_points);
- const lookats = curve_object.curve_lookats.getPoints(num_points);
- const ups = curve_object.curve_ups.getPoints(num_points);
-
const camera_path = [];
for (let i = 0; i < num_points; i += 1) {
- const position = positions[i];
- const lookat = lookats[i];
- const up = ups[i];
+ const pt = getKeyframePoint(i / num_points);
+
+ const position = curve_object.curve_positions.getPoint(pt);
+ const lookat = curve_object.curve_lookats.getPoint(pt);
+ const up = curve_object.curve_ups.getPoint(pt);
+ const fov = curve_object.curve_fovs.getPoint(pt).z;
const mat = get_transform_matrix(position, lookat, up);
camera_path.push({
camera_to_world: mat.transpose().elements, // convert from col-major to row-major matrix
- fov: camera_render.fov,
+ fov,
aspect: camera_render.aspect,
});
}
@@ -433,6 +813,7 @@ export default function CameraPanel(props) {
matrix: JSON.stringify(camera.matrix.toArray()),
fov: camera.fov,
aspect: camera_render.aspect,
+ properties: JSON.stringify(Array.from(camera.properties.entries())),
});
}
@@ -446,7 +827,6 @@ export default function CameraPanel(props) {
seconds,
smoothness_value,
is_cycle,
- is_linear,
};
return camera_path_object;
};
@@ -478,9 +858,8 @@ export default function CameraPanel(props) {
};
const load_camera_path = (camera_path_object) => {
- // TODO UI for getting json
-
const new_camera_list = [];
+ const new_properties = new Map(cameraProperties);
setRenderHeight(camera_path_object.render_height);
setUIRenderHeight(camera_path_object.render_height);
@@ -495,7 +874,6 @@ export default function CameraPanel(props) {
set_smoothness_value(camera_path_object.smoothness_value);
setIsCycle(camera_path_object.is_cycle);
- setIsLinear(camera_path_object.is_linear);
for (let i = 0; i < camera_path_object.keyframes.length; i += 1) {
const keyframe = camera_path_object.keyframes[i];
@@ -506,13 +884,17 @@ export default function CameraPanel(props) {
1000,
);
+ // properties
+ camera.properties = new Map(JSON.parse(keyframe.properties));
+ new_properties.set(camera.uuid, camera.properties);
+
const mat = new THREE.Matrix4();
mat.fromArray(JSON.parse(keyframe.matrix));
- // camera.matrix = mat;
set_camera_position(camera, mat);
new_camera_list.push(camera);
}
+ setCameraProperties(new_properties);
setCameras(new_camera_list);
reset_slider_render_on_add(new_camera_list);
};
@@ -529,16 +911,11 @@ export default function CameraPanel(props) {
fr.readAsText(fileUpload);
};
- const copy_cmd_to_clipboard = () => {
- console.log('copy_cmd_to_clipboard');
+ const open_render_modal = () => {
+ setRenderModalOpen(true);
const camera_path_object = get_camera_path();
-
- // Copy the text inside the text field
- const config_filename = `${config_base_dir}/config.yml`;
const camera_path_filename = `${config_base_dir}/camera_path.json`;
- const cmd = `ns-render --load-config ${config_filename} --traj filename --camera-path-filename ${camera_path_filename} --output-path renders/output.mp4`;
- navigator.clipboard.writeText(cmd);
const camera_path_payload = {
camera_path_filename,
@@ -557,12 +934,29 @@ export default function CameraPanel(props) {
}
};
- const setFOV = (fov) => {
- dispatch({
- type: 'write',
- path: 'renderingState/field_of_view',
- data: fov,
- });
+ const isAnimated = (property) => animate.has(property);
+
+ const toggleAnimate = (property) => {
+ const new_animate = new Set(animate);
+ if (animate.has(property)) {
+ new_animate.delete(property);
+ setAnimate(new_animate);
+ } else {
+ new_animate.add(property);
+ setAnimate(new_animate);
+ }
+ };
+
+ const setAllCameraFOV = (val) => {
+ if (fovLabel === FOV_LABELS.FOV) {
+ for (let i = 0; i < cameras.length; i += 1) {
+ cameras[i].fov = val;
+ }
+ } else {
+ for (let i = 0; i < cameras.length; i += 1) {
+ cameras[i].setFocalLength(val / cameras[i].aspect);
+ }
+ }
};
return (
@@ -597,13 +991,17 @@ export default function CameraPanel(props) {
Export Path
-
-
+
+
+
+
@@ -818,11 +1235,50 @@ export default function CameraPanel(props) {
-
-
+
+ Camera Keyframes
+
+
@@ -910,6 +1366,13 @@ export default function CameraPanel(props) {
camera_main={camera_render}
cameras={cameras}
setCameras={setCameras}
+ swapCameras={swapCameras}
+ cameraProperties={cameraProperties}
+ setCameraProperties={setCameraProperties}
+ fovLabel={fovLabel}
+ setFovLabel={setFovLabel}
+ isAnimated={isAnimated}
+ dispatch={dispatch}
/>
diff --git a/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/curve.js b/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/curve.js
index 4a6fa8608..11a36f7cf 100644
--- a/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/curve.js
+++ b/nerfstudio/viewer/app/src/modules/SidePanel/CameraPanel/curve.js
@@ -2,7 +2,7 @@
import * as THREE from 'three';
-function get_curve(list_of_3d_vectors, is_cycle, smoothness_value) {
+function get_catmull_rom_curve(list_of_3d_vectors, is_cycle, smoothness_value) {
// TODO: add some hyperparameters to this function
const curve = new THREE.CatmullRomCurve3(
list_of_3d_vectors,
@@ -19,6 +19,9 @@ export function get_curve_object_from_cameras(
is_cycle,
smoothness_value,
) {
+ if (cameras.length === 0) {
+ return null;
+ }
// interpolate positions, lookat directions, and ups
// similar to
// https://github.com/google-research/multinerf/blob/1c8b1c552133cdb2de1c1f3c871b2813f6662265/internal/camera_utils.py#L281
@@ -26,6 +29,7 @@ export function get_curve_object_from_cameras(
const positions = [];
const lookats = [];
const ups = [];
+ const fovs = [];
for (let i = 0; i < cameras.length; i += 1) {
const camera = cameras[i];
@@ -39,20 +43,40 @@ export function get_curve_object_from_cameras(
positions.push(camera.position);
ups.push(up);
lookats.push(lookat);
+ // Reuse catmullromcurve3 for 1d values. TODO fix this
+ fovs.push(new THREE.Vector3(0, 0, camera.fov));
+ }
+
+ if (is_cycle) {
+ const camera = cameras[0];
+
+ const up = new THREE.Vector3(0, 1, 0);
+ const lookat = new THREE.Vector3(0, 0, 1);
+
+ up.applyQuaternion(camera.quaternion);
+ lookat.applyQuaternion(camera.quaternion);
+
+ positions.push(camera.position);
+ ups.push(up);
+ lookats.push(lookat);
+ fovs.push(new THREE.Vector3(0, 0, camera.fov));
}
let curve_positions = null;
let curve_lookats = null;
let curve_ups = null;
+ let curve_fovs = null;
- curve_positions = get_curve(positions, is_cycle, smoothness_value);
- curve_lookats = get_curve(lookats, is_cycle, smoothness_value);
- curve_ups = get_curve(ups, is_cycle, smoothness_value);
+ curve_positions = get_catmull_rom_curve(positions, false, smoothness_value);
+ curve_lookats = get_catmull_rom_curve(lookats, false, smoothness_value);
+ curve_ups = get_catmull_rom_curve(ups, false, smoothness_value);
+ curve_fovs = get_catmull_rom_curve(fovs, false, 0.05);
const curve_object = {
curve_positions,
curve_lookats,
curve_ups,
+ curve_fovs,
};
return curve_object;
}
@@ -60,6 +84,9 @@ export function get_curve_object_from_cameras(
export function get_transform_matrix(position, lookat, up) {
// normalize the vectors
lookat.normalize();
+ // make up orthogonal to lookat
+ const up_proj = lookat.clone().multiplyScalar(up.dot(lookat));
+ up.sub(up_proj);
up.normalize();
// create a copy of the vector up
diff --git a/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/ExportPanel.jsx b/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/ExportPanel.jsx
new file mode 100644
index 000000000..9703e2c14
--- /dev/null
+++ b/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/ExportPanel.jsx
@@ -0,0 +1,103 @@
+/* eslint-disable react/jsx-props-no-spreading */
+import * as React from 'react';
+
+import { Box, Typography, Tab, Tabs } from '@mui/material';
+import { LevaPanel, LevaStoreProvider, useCreateStore } from 'leva';
+import BlurOnIcon from '@mui/icons-material/BlurOn';
+import CategoryIcon from '@mui/icons-material/Category';
+import PointcloudSubPanel from './PointcloudSubPanel';
+import LevaTheme from '../../../themes/leva_theme.json';
+
+interface TabPanelProps {
+ children: React.ReactNode;
+ index: number;
+ value: number;
+}
+
+function TabPanel(props: TabPanelProps) {
+ const { children, value, index, ...other } = props;
+
+ return (
+
+ {value === index && (
+
+ );
+}
+
+function a11yProps(index: number) {
+ return {
+ id: `simple-tab-${index}`,
+ 'aria-controls': `simple-tabpanel-${index}`,
+ };
+}
+
+export default function ExportPanel(props) {
+ // unpack relevant information
+ const sceneTree = props.sceneTree;
+ const showExportBox = props.showExportBox;
+
+ const [type_value, setTypeValue] = React.useState(0);
+
+ const handleTypeChange = (event: React.SyntheticEvent, newValue: number) => {
+ setTypeValue(newValue);
+ };
+
+ const pointcloudStore = useCreateStore();
+
+ return (
+
+
+ );
+}
diff --git a/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/PointcloudSubPanel.jsx b/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/PointcloudSubPanel.jsx
new file mode 100644
index 000000000..8951c8051
--- /dev/null
+++ b/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/PointcloudSubPanel.jsx
@@ -0,0 +1,163 @@
+import * as React from 'react';
+import * as THREE from 'three';
+import { useControls, useStoreContext } from 'leva';
+import { useEffect } from 'react';
+import { useDispatch, useSelector } from 'react-redux';
+import ContentCopyRoundedIcon from '@mui/icons-material/ContentCopyRounded';
+
+import { Button } from '@mui/material';
+
+const PCD_CLIPPING_BOX_NAME = 'PCD Clipping Box';
+
+export default function PointcloudSubPanel(props) {
+ const sceneTree = props.sceneTree;
+ const showExportBox = props.showExportBox;
+ const store = useStoreContext();
+
+ const dispatch = useDispatch();
+
+ // redux store state
+ const config_base_dir = useSelector(
+ (state) => state.renderingState.config_base_dir,
+ );
+ const clippingEnabled = useSelector(
+ (state) => state.renderingState.clipping_enabled,
+ );
+ const clippingCenter = useSelector(
+ (state) => state.renderingState.clipping_center,
+ );
+ const clippingScale = useSelector(
+ (state) => state.renderingState.clipping_box_scale,
+ );
+
+ const config_filename = `${config_base_dir}/config.yml`;
+
+ const geometry = new THREE.BoxGeometry(1, 1, 1);
+ const material = new THREE.MeshBasicMaterial({
+ color: 0xffd369,
+ transparent: true,
+ opacity: 0.7,
+ side: THREE.DoubleSide,
+ });
+ const cube = new THREE.Mesh(geometry, material);
+ sceneTree.set_object_from_path([PCD_CLIPPING_BOX_NAME], cube);
+ cube.visible = showExportBox && clippingEnabled;
+
+ const update_box_center = (value) => {
+ const box = sceneTree.find_object_no_create([PCD_CLIPPING_BOX_NAME]);
+ box.position.set(value[0], value[1], value[2]);
+ };
+
+ const update_box_scale = (value) => {
+ const box = sceneTree.find_object_no_create([PCD_CLIPPING_BOX_NAME]);
+ box.scale.set(value[0], value[1], value[2]);
+ };
+
+ const controlValues = useControls(
+ {
+ numPoints: { label: 'Number of Points', value: 1000000, min: 1 },
+ removeOutliers: { label: 'Remove Outliers', value: true },
+ estimateNormals: { label: 'Estimate Normals', value: false },
+ useBoundingBox: {
+ label: 'Crop',
+ value: clippingEnabled,
+ onChange: (value) => {
+ const box = sceneTree.find_object_no_create([PCD_CLIPPING_BOX_NAME]);
+ box.visible = value;
+ dispatch({
+ type: 'write',
+ path: 'renderingState/clipping_enabled',
+ data: value,
+ });
+ },
+ },
+ center: {
+ label: '| Center',
+ value: clippingCenter,
+ render: (get) => get('useBoundingBox'),
+ onChange: (value) => {
+ update_box_center(value);
+ },
+ onEditEnd: (value) => {
+ dispatch({
+ type: 'write',
+ path: 'renderingState/clipping_center',
+ data: value,
+ });
+ },
+ },
+ scale: {
+ label: '| Scale',
+ value: clippingScale,
+ min: 0.01,
+ render: (get) => get('useBoundingBox'),
+ onChange: (value) => {
+ update_box_scale(value);
+ },
+ onEditEnd: (value) => {
+ dispatch({
+ type: 'write',
+ path: 'renderingState/clipping_box_scale',
+ data: value,
+ });
+ },
+ },
+ outputDir: { label: 'Output Directory', value: 'pcd/' },
+ },
+ { store },
+ );
+
+ const getPythonBool = (boolean) => {
+ return boolean ? 'True' : 'False';
+ };
+
+ const bbox_min = [
+ clippingCenter[0] - clippingScale[0] / 2,
+ clippingCenter[1] - clippingScale[1] / 2,
+ clippingCenter[2] - clippingScale[2] / 2,
+ ];
+ const bbox_max = [
+ clippingCenter[0] + clippingScale[0] / 2,
+ clippingCenter[1] + clippingScale[1] / 2,
+ clippingCenter[2] + clippingScale[2] / 2,
+ ];
+
+ const cmd =
+ `ns-export pointcloud` +
+ ` --load-config ${config_filename}` +
+ ` --output-dir ${controlValues.outputDir}` +
+ ` --num-points ${controlValues.numPoints}` +
+ ` --remove-outliers ${getPythonBool(controlValues.removeOutliers)}` +
+ ` --estimate-normals ${getPythonBool(controlValues.estimateNormals)}` +
+ ` --use-bounding-box ${getPythonBool(clippingEnabled)}` +
+ ` --bounding-box-min ${bbox_min[0]} ${bbox_min[1]} ${bbox_min[2]}` +
+ ` --bounding-box-max ${bbox_max[0]} ${bbox_max[1]} ${bbox_max[2]}`;
+
+ const handleCopy = () => {
+ navigator.clipboard.writeText(cmd);
+ };
+
+ useEffect(() => {
+ update_box_center(clippingCenter);
+ update_box_scale(clippingScale);
+ });
+
+ return (
+
+
+ );
+}
diff --git a/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/index.jsx b/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/index.jsx
new file mode 100644
index 000000000..41d179916
--- /dev/null
+++ b/nerfstudio/viewer/app/src/modules/SidePanel/ExportPanel/index.jsx
@@ -0,0 +1,3 @@
+import ExportPanel from './ExportPanel';
+
+export default ExportPanel;
diff --git a/nerfstudio/viewer/app/src/modules/SidePanel/ScenePanel/ScenePanel.jsx b/nerfstudio/viewer/app/src/modules/SidePanel/ScenePanel/ScenePanel.jsx
index ff70042cb..b65d4d420 100644
--- a/nerfstudio/viewer/app/src/modules/SidePanel/ScenePanel/ScenePanel.jsx
+++ b/nerfstudio/viewer/app/src/modules/SidePanel/ScenePanel/ScenePanel.jsx
@@ -17,7 +17,7 @@ import {
VisibilityOff,
} from '@mui/icons-material/';
import SceneNode from '../../../SceneNode';
-import LevaTheme from '../../ConfigPanel/leva_theme.json';
+import LevaTheme from '../../../themes/leva_theme.json';
export const snap_to_camera = (sceneTree, camera, matrix) => {
const mat = new THREE.Matrix4();
@@ -161,6 +161,7 @@ function MenuItems(props: ListItemProps) {
.map((key) => (
+ Run the following command in a terminal to export the pointcloud:
+
+ {cmd}
+
+ }
+ onClick={handleCopy}
+ >
+ Copy Command
+
+
+
+ }
+ onClick={handleOpen}
+ >
+ Viewport Controls
+
+
+ );
+}
diff --git a/nerfstudio/viewer/app/src/modules/ViewportControlsModal/index.jsx b/nerfstudio/viewer/app/src/modules/ViewportControlsModal/index.jsx
new file mode 100644
index 000000000..befc5306e
--- /dev/null
+++ b/nerfstudio/viewer/app/src/modules/ViewportControlsModal/index.jsx
@@ -0,0 +1,3 @@
+import ViewportControlsModal from './ViewportControlsModal';
+
+export default ViewportControlsModal;
diff --git a/nerfstudio/viewer/app/src/modules/WebSocket/WebSocket.jsx b/nerfstudio/viewer/app/src/modules/WebSocket/WebSocket.jsx
index 0ac088ea9..0e265ef60 100644
--- a/nerfstudio/viewer/app/src/modules/WebSocket/WebSocket.jsx
+++ b/nerfstudio/viewer/app/src/modules/WebSocket/WebSocket.jsx
@@ -23,7 +23,11 @@ export default function WebSocketContextFunction({ children }) {
const connect = () => {
// of the form wss://ip_address:port
console.log(websocket_url);
- socket = new WebSocket(websocket_url);
+ try {
+ socket = new WebSocket(websocket_url);
+ } catch (error) {
+ socket = new WebSocket('ws://localhost:7007');
+ }
socket.binaryType = 'arraybuffer';
socket.onopen = () => {
dispatch({
@@ -56,7 +60,9 @@ export default function WebSocketContextFunction({ children }) {
useEffect(() => {
// cleanup function to close the websocket on rerender
return () => {
- socket.close();
+ if (socket !== null) {
+ socket.close();
+ }
};
}, [websocket_url]);
diff --git a/nerfstudio/viewer/app/src/modules/WebSocketUrlField.jsx b/nerfstudio/viewer/app/src/modules/WebSocketUrlField.jsx
index 4dcec3376..f93b528fc 100644
--- a/nerfstudio/viewer/app/src/modules/WebSocketUrlField.jsx
+++ b/nerfstudio/viewer/app/src/modules/WebSocketUrlField.jsx
@@ -19,6 +19,16 @@ export default function WebSocketUrlField() {
});
};
+ const testWebSocket = (url) => {
+ try {
+ // eslint-disable-next-line no-new
+ new WebSocket(url);
+ return false;
+ } catch (error) {
+ return true;
+ }
+ };
+
return (
 +
 +